GPT-6 Astra enters the short-story creative writing benchmark at #3
Astra (high) scores 2.5 to 3.5 and beats GPT-5.6 Sol (high); in a separate self-judging test it picked its own story in 692 of 700 comparisons.
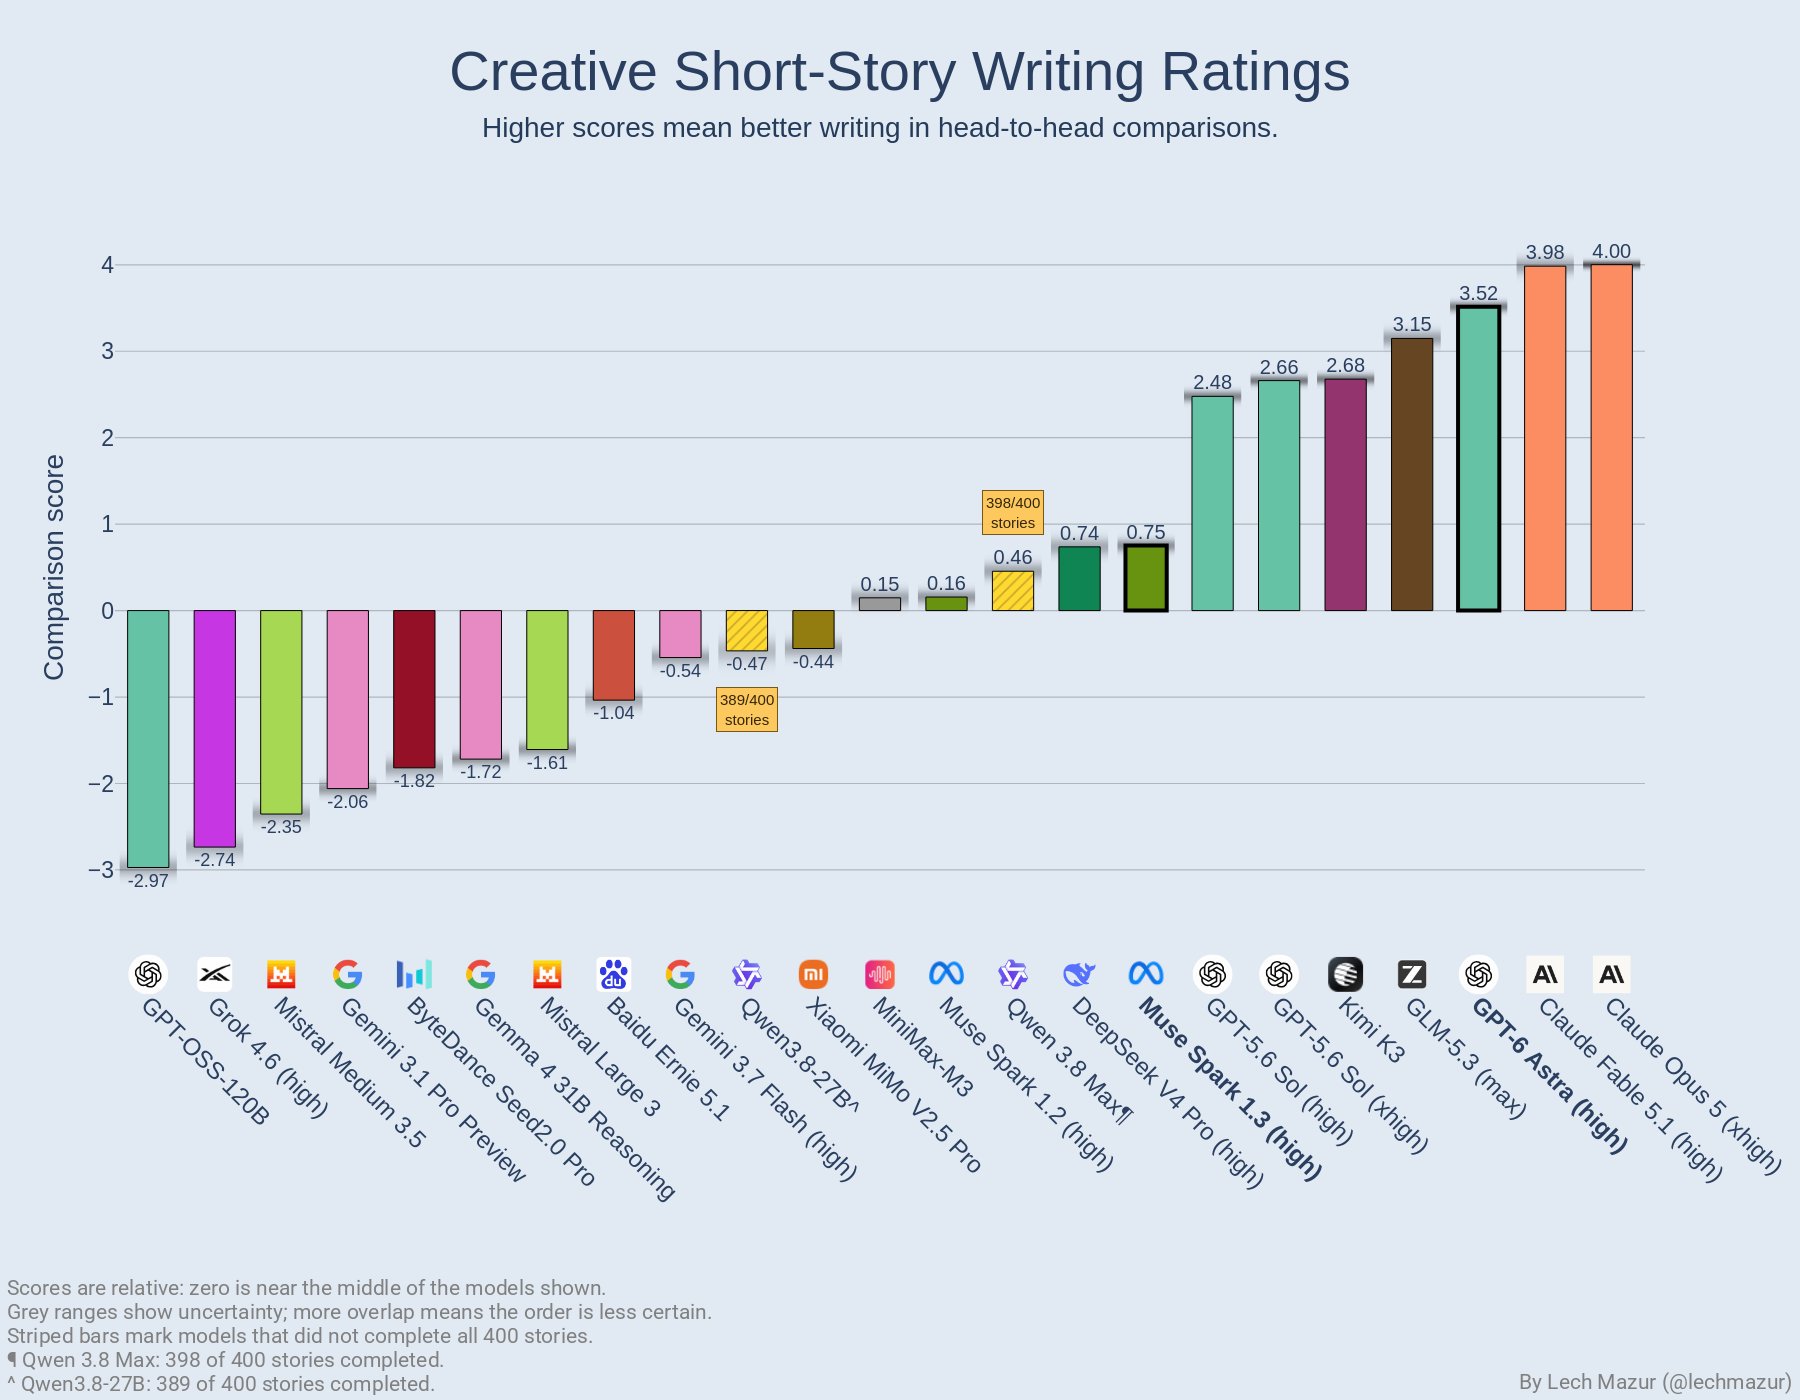
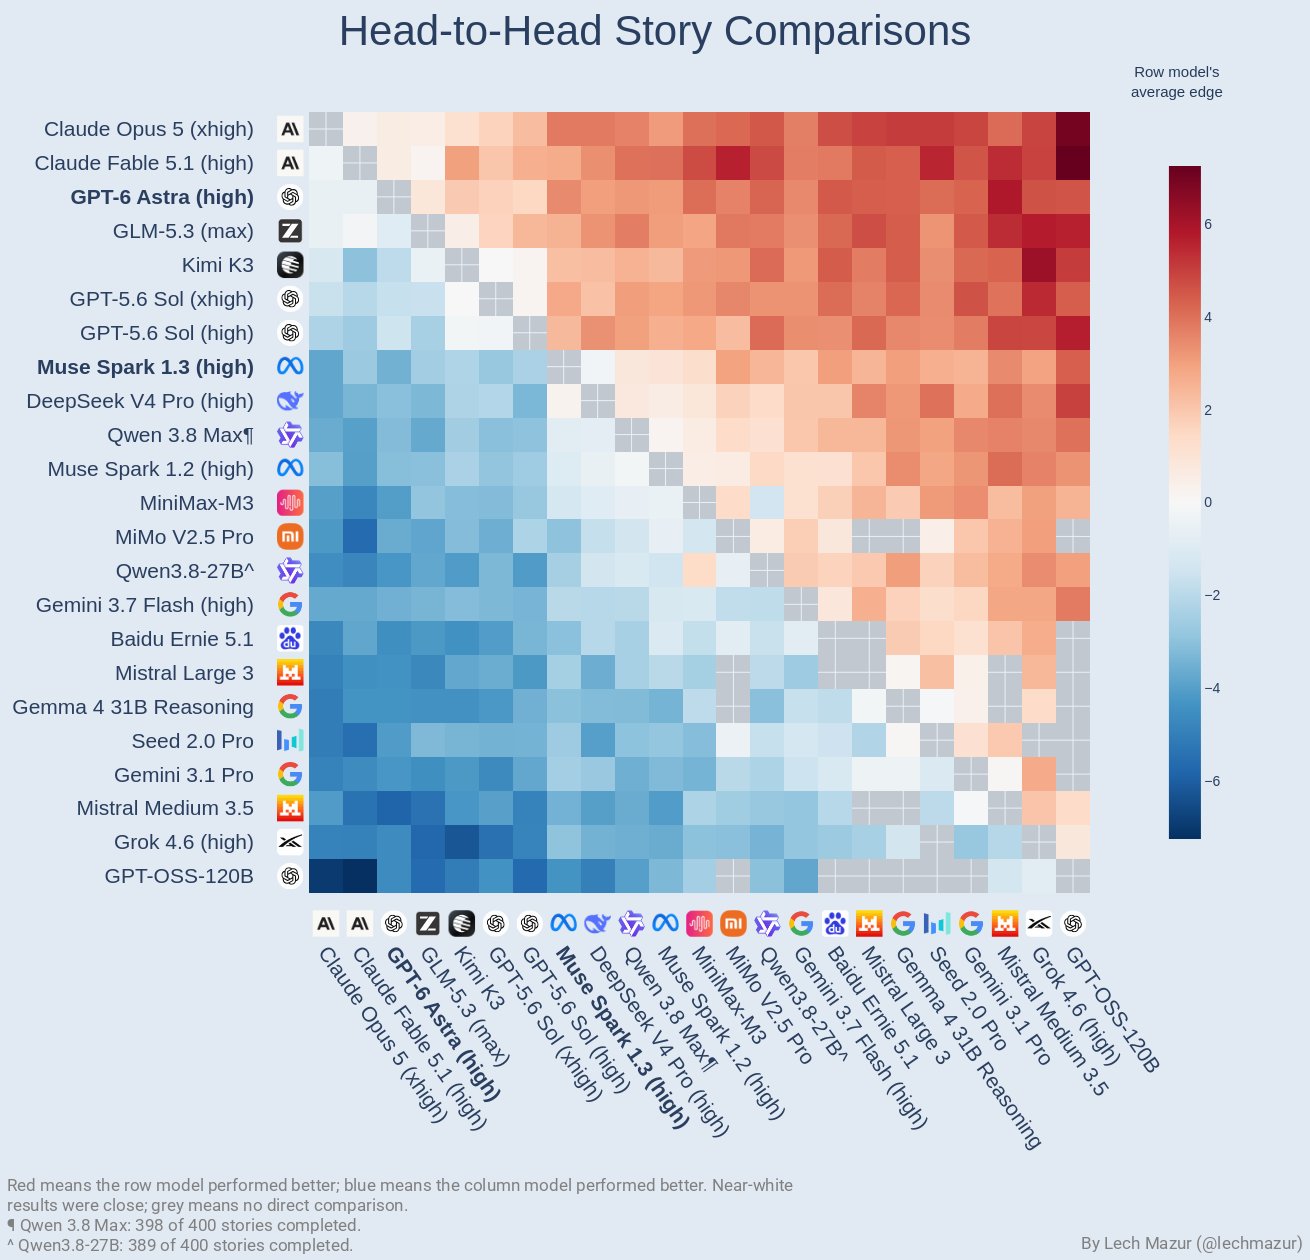
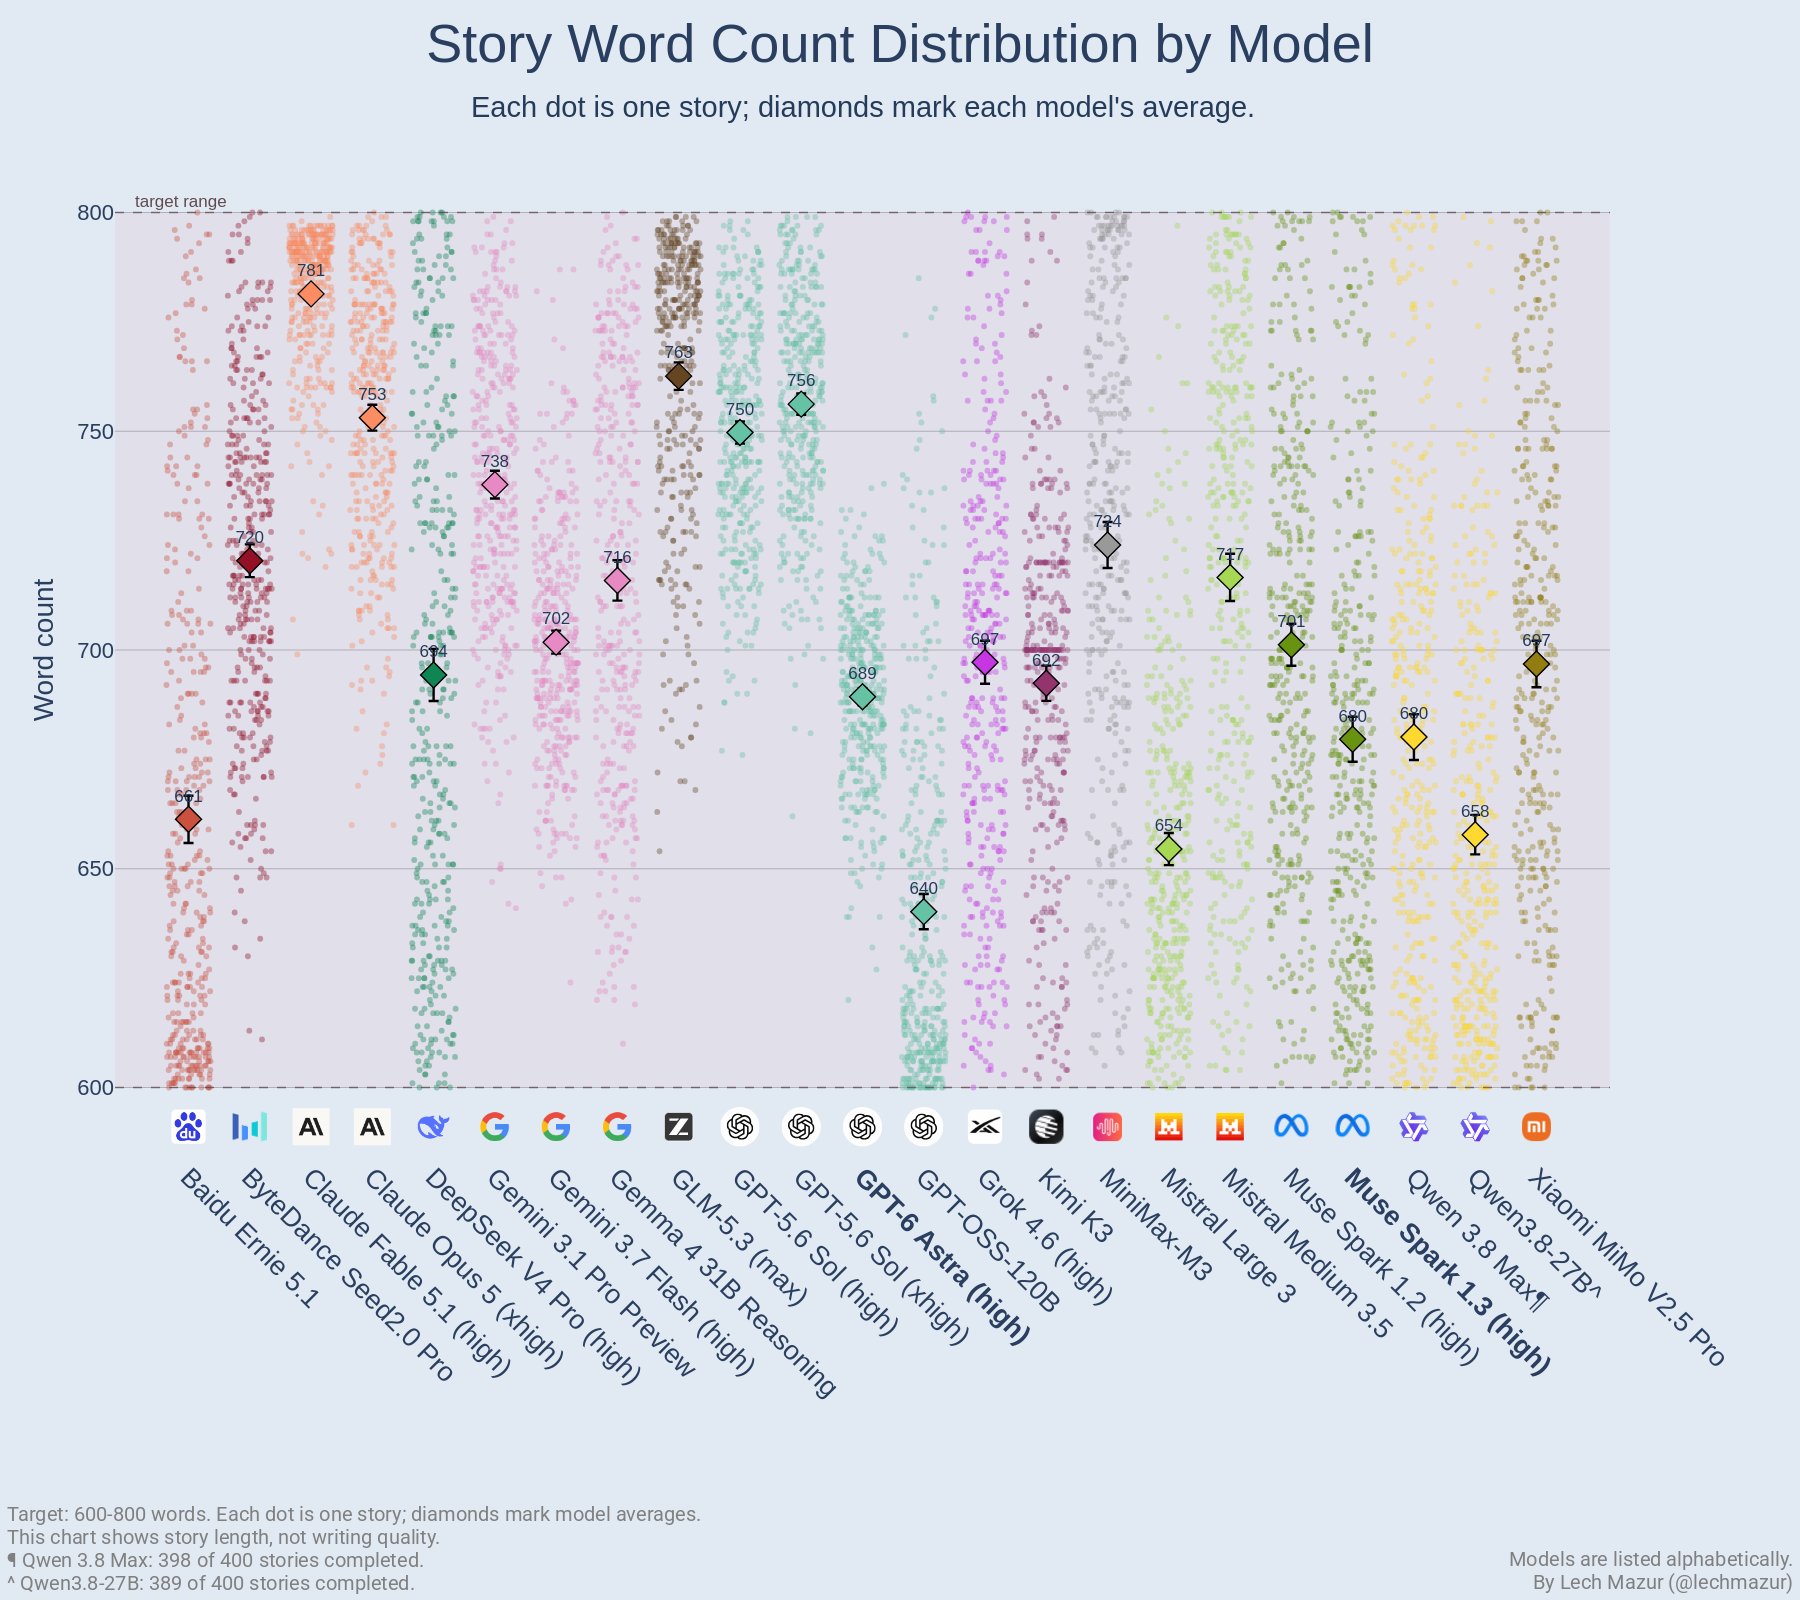
GPT-6 Astra enters the Short-Story Creative Writing Benchmark at #3! ✍️ Astra (high) decisively outperforms GPT-5.6 Sol (high): 2.5 → 3.5. Muse Spark 1.3 rebounds from 1.2: 0.2 → 0.7. The Creative Writing Benchmark tests how well models turn constrained briefs into complete 600-800-word stories. Each brief requires 10 elements, including a character, object, setting, motivation, and tone, that must meaningfully shape the story. Judges assess prose, originality, coherence, characterization, and how effectively those ingredients work together. Models write to the same prompts. Three judges from different model families compare each story pair, shown in both orders to reduce position bias. The main leaderboard now covers 50 models and 79,507 evaluator judgments. A separate self-judging experiment produced a striking result: with model names hidden, Astra chose its own story in 692 of 700 comparisons. It acknowledged just 1 of the 57 losses assigned by the regular judging panel. More info: https://github.com/lechmazur/writing/