Gemini 4 Argon scores 0.80 on short story creative writing benchmark
On Lech Mazur's short story benchmark, Gemini 4 Argon (high) scores 0.80 versus −2.17 for Gemini 3.1 Pro Preview, winning all 50 paired comparisons but still showing repetition and overly tidy endings.
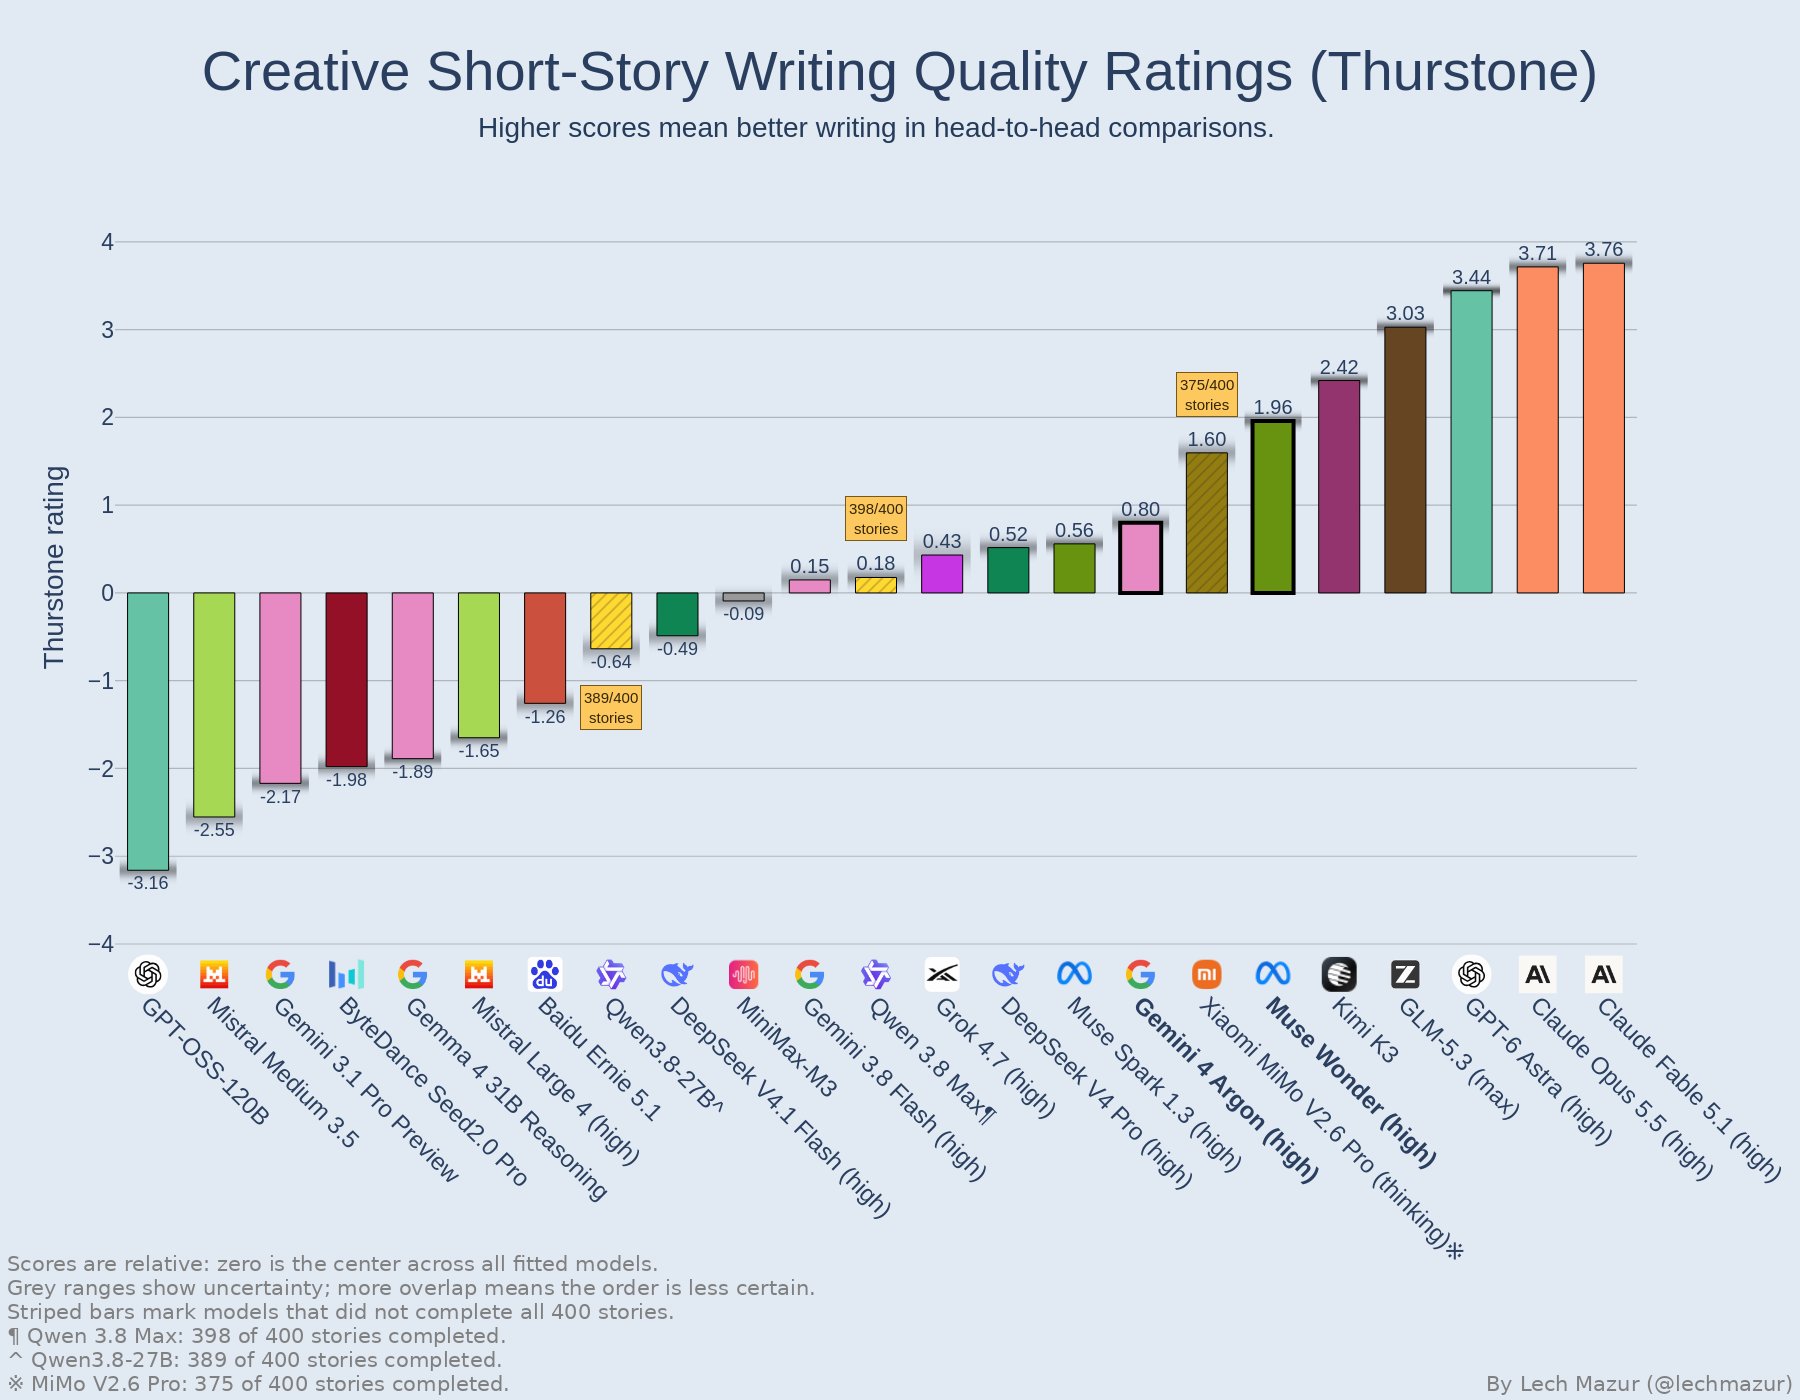
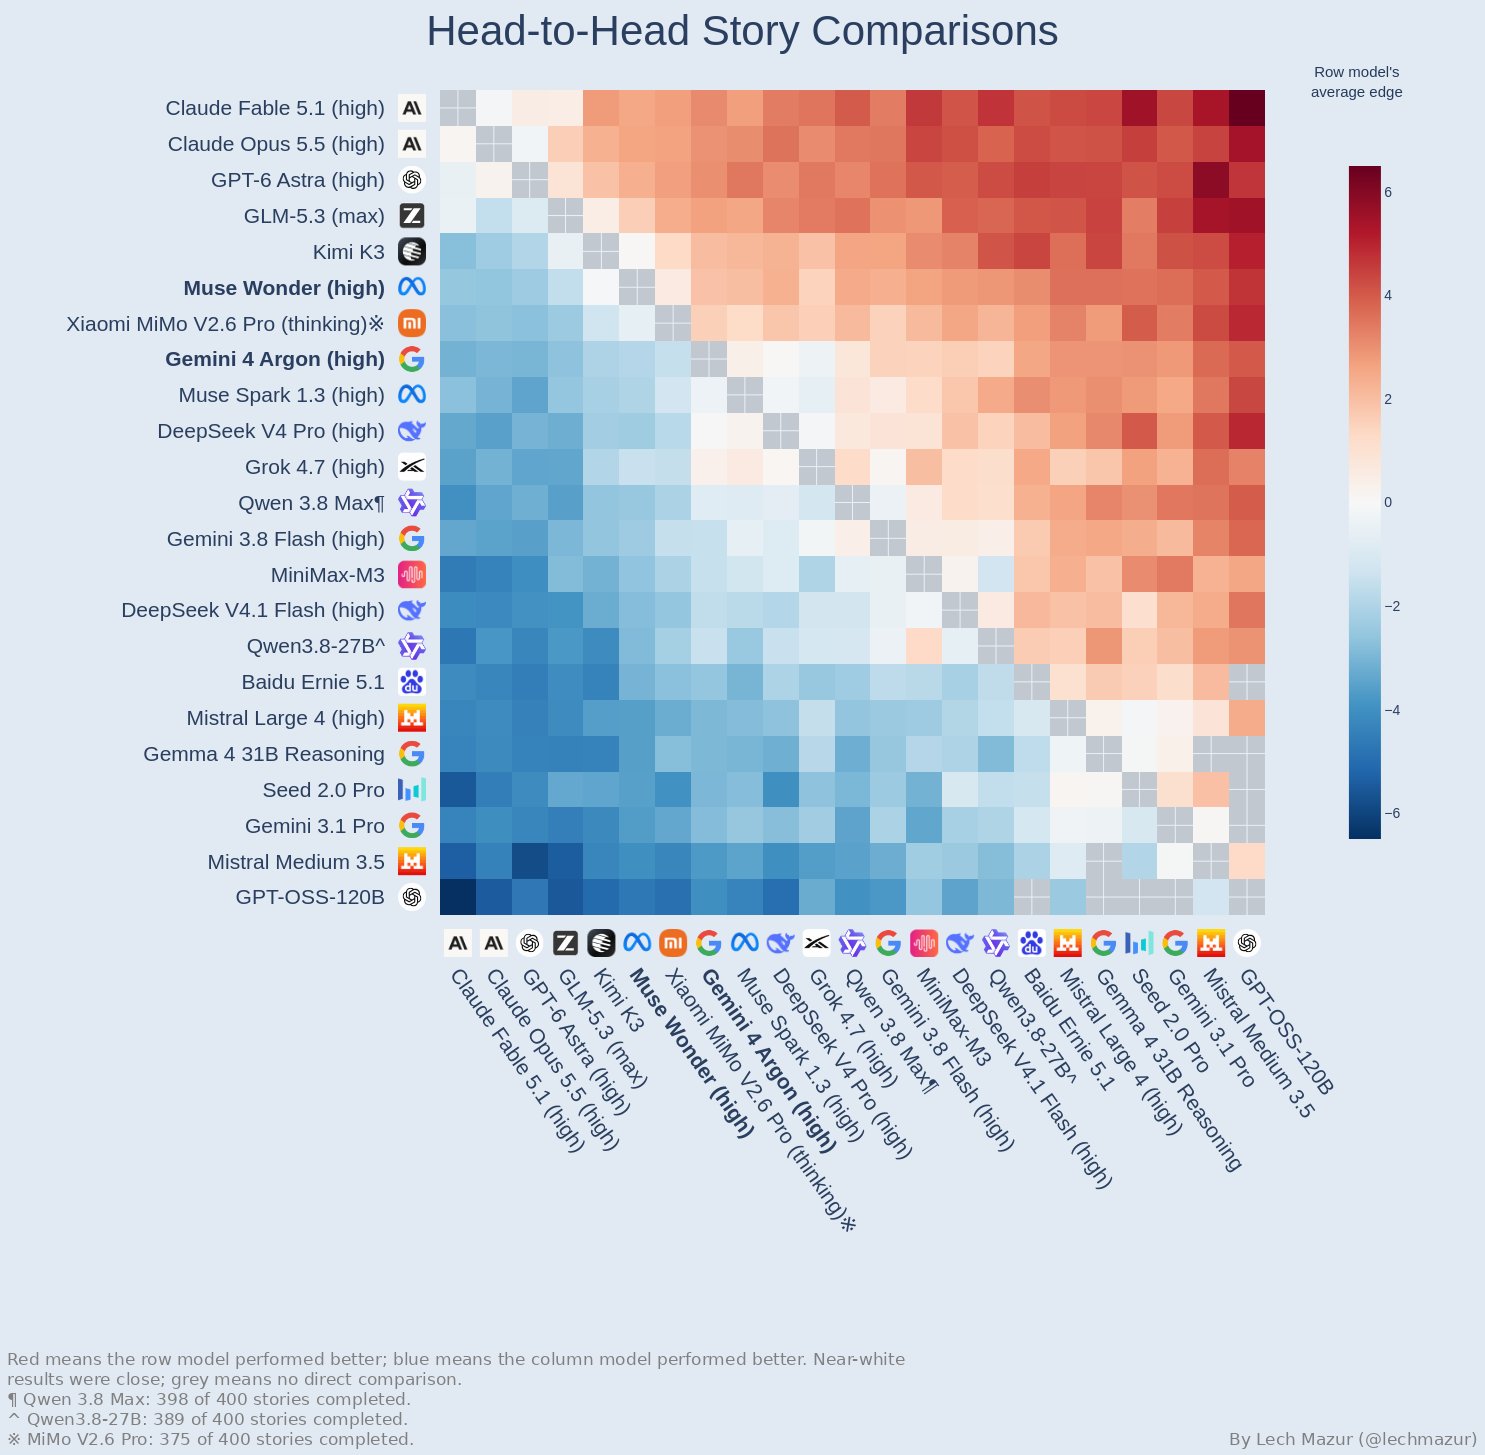
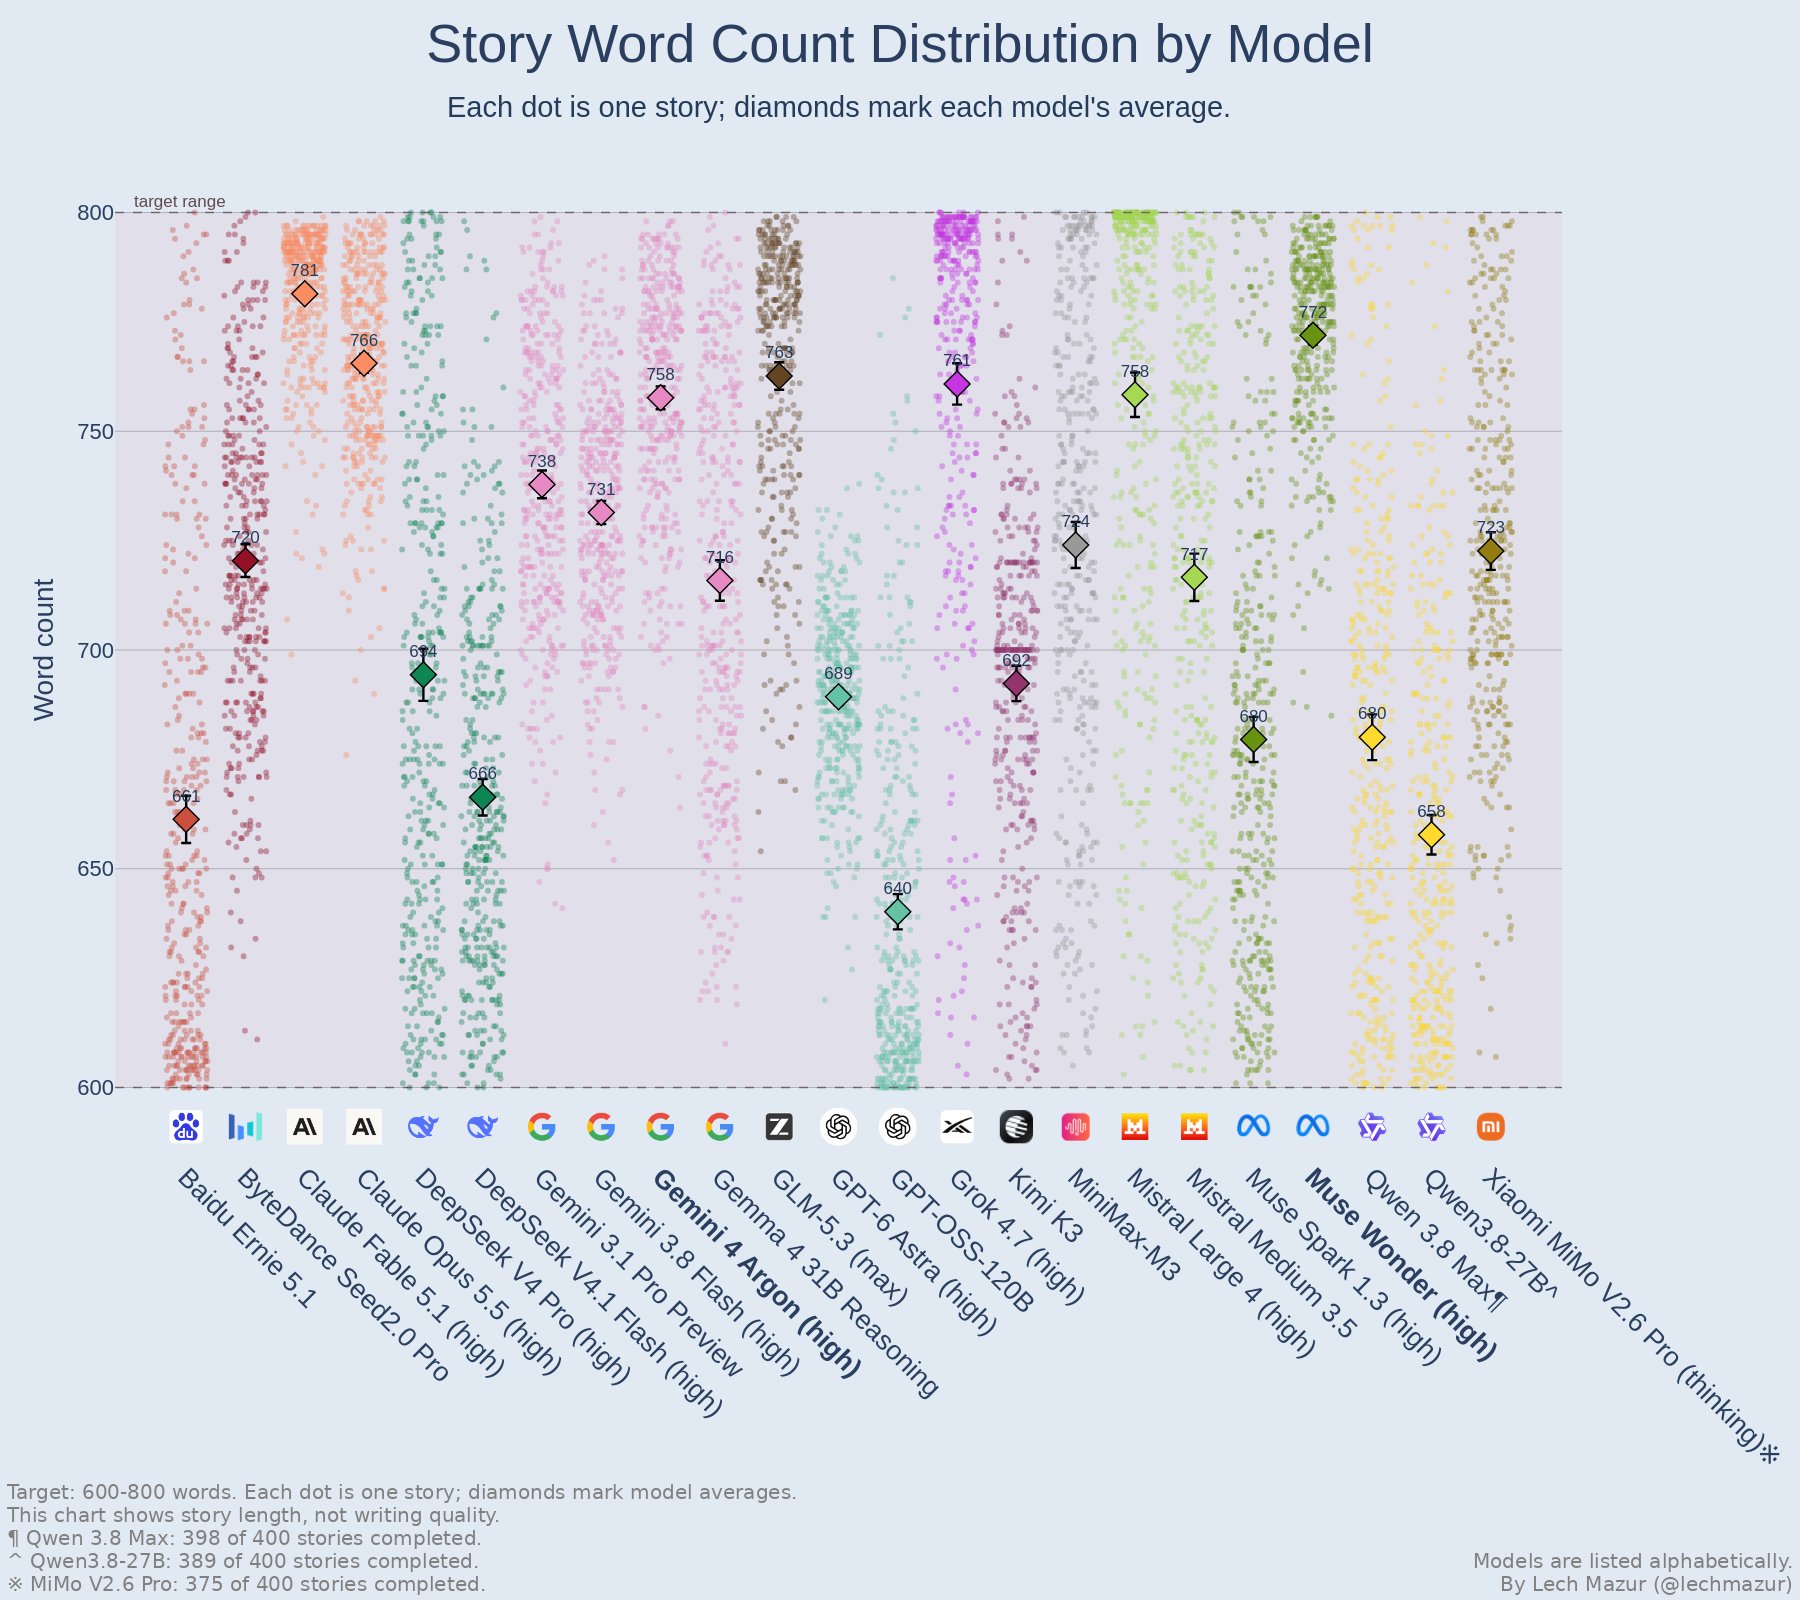
Muse Wonder (high) scores 1.96 on the Short Story Creative Writing Benchmark, compared with 0.56 for Muse Spark 1.3 (high). Gemini 4 Argon (high) scores 0.80, up from −2.17 for Gemini 3.1 Pro Preview. https://github.com/lechmazur/writing/ Argon's improvement over Gemini 3.1 Pro is large. It won all 50 matched story comparisons. Required objects, abilities, and constraints more often affect what happens in the story. Characters' solutions have clearer preparation and consequences, and relationships more often involve reciprocal needs. Gemini 3.1 Pro more frequently supplies symbolic ingredients and then explains that the problem has been solved. Argon still has recognizable habits: repeated names, explanatory narration, and endings that resolve emotional conflict too neatly. Stronger construction has not eliminated repetition or made its writing consistently subtle. The Creative Writing Benchmark tests how well models turn constrained briefs into complete 600-800-word stories. Each brief specifies 10 required elements, including a character, object, setting, motivation, and tone, that must meaningfully shape the story. Judges assess prose, originality, coherence, characterization, and how effectively the required elements work together. Models write to the same prompts. The comparisons use three judges from different model families, excluding both writers' families. Each story pair is judged in both presentation orders to reduce position bias. The leaderboard covers 59 writer models and 110,748 evaluator judgments.