Debate Benchmark: DeepSeek V4.1 Flash 1017 scores 1593 with 29% fewer reasoning tokens
On a multi-turn adversarial debate benchmark, V4.1 Flash 1017 (high) rises from 1577 to 1593 (+16) while using 29% fewer reasoning tokens on average; Kimi K3.1 Pro drops from 1691 to 1603.
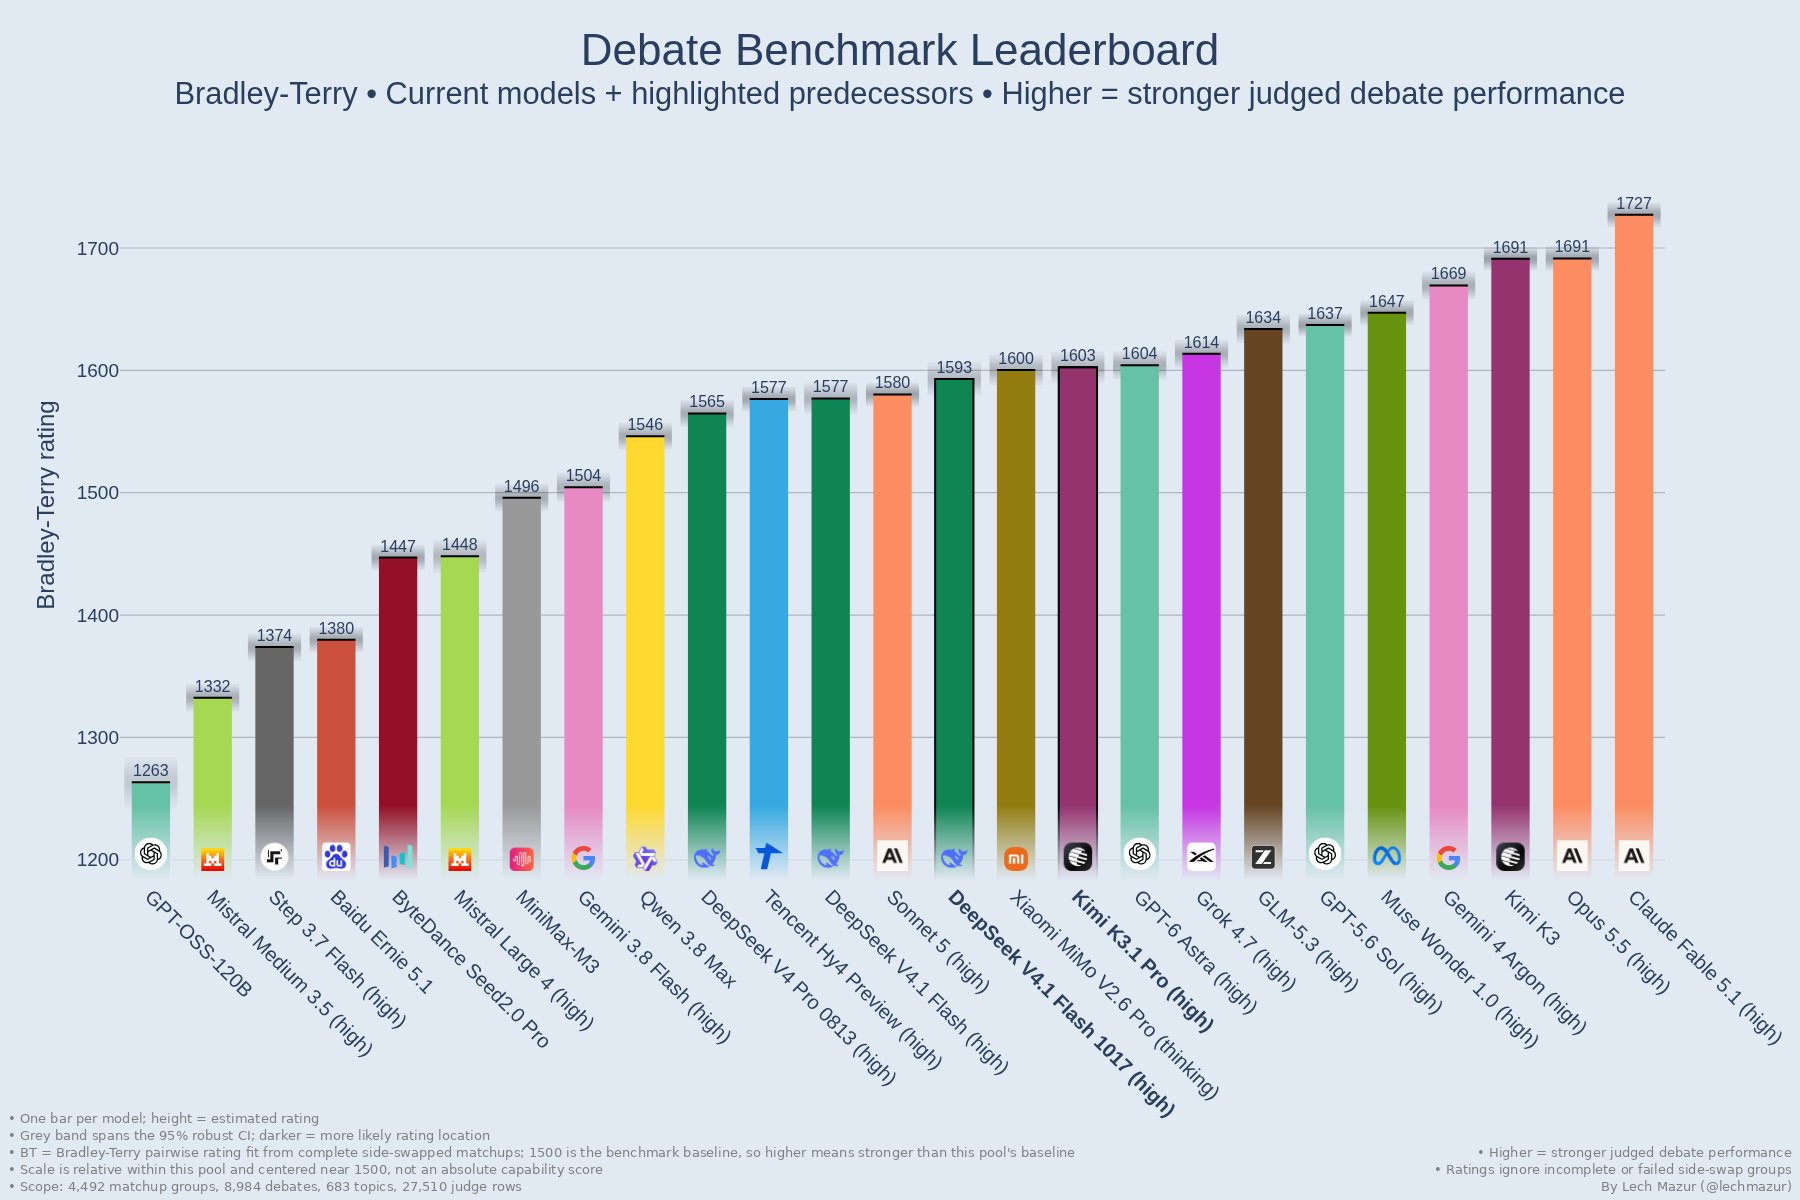
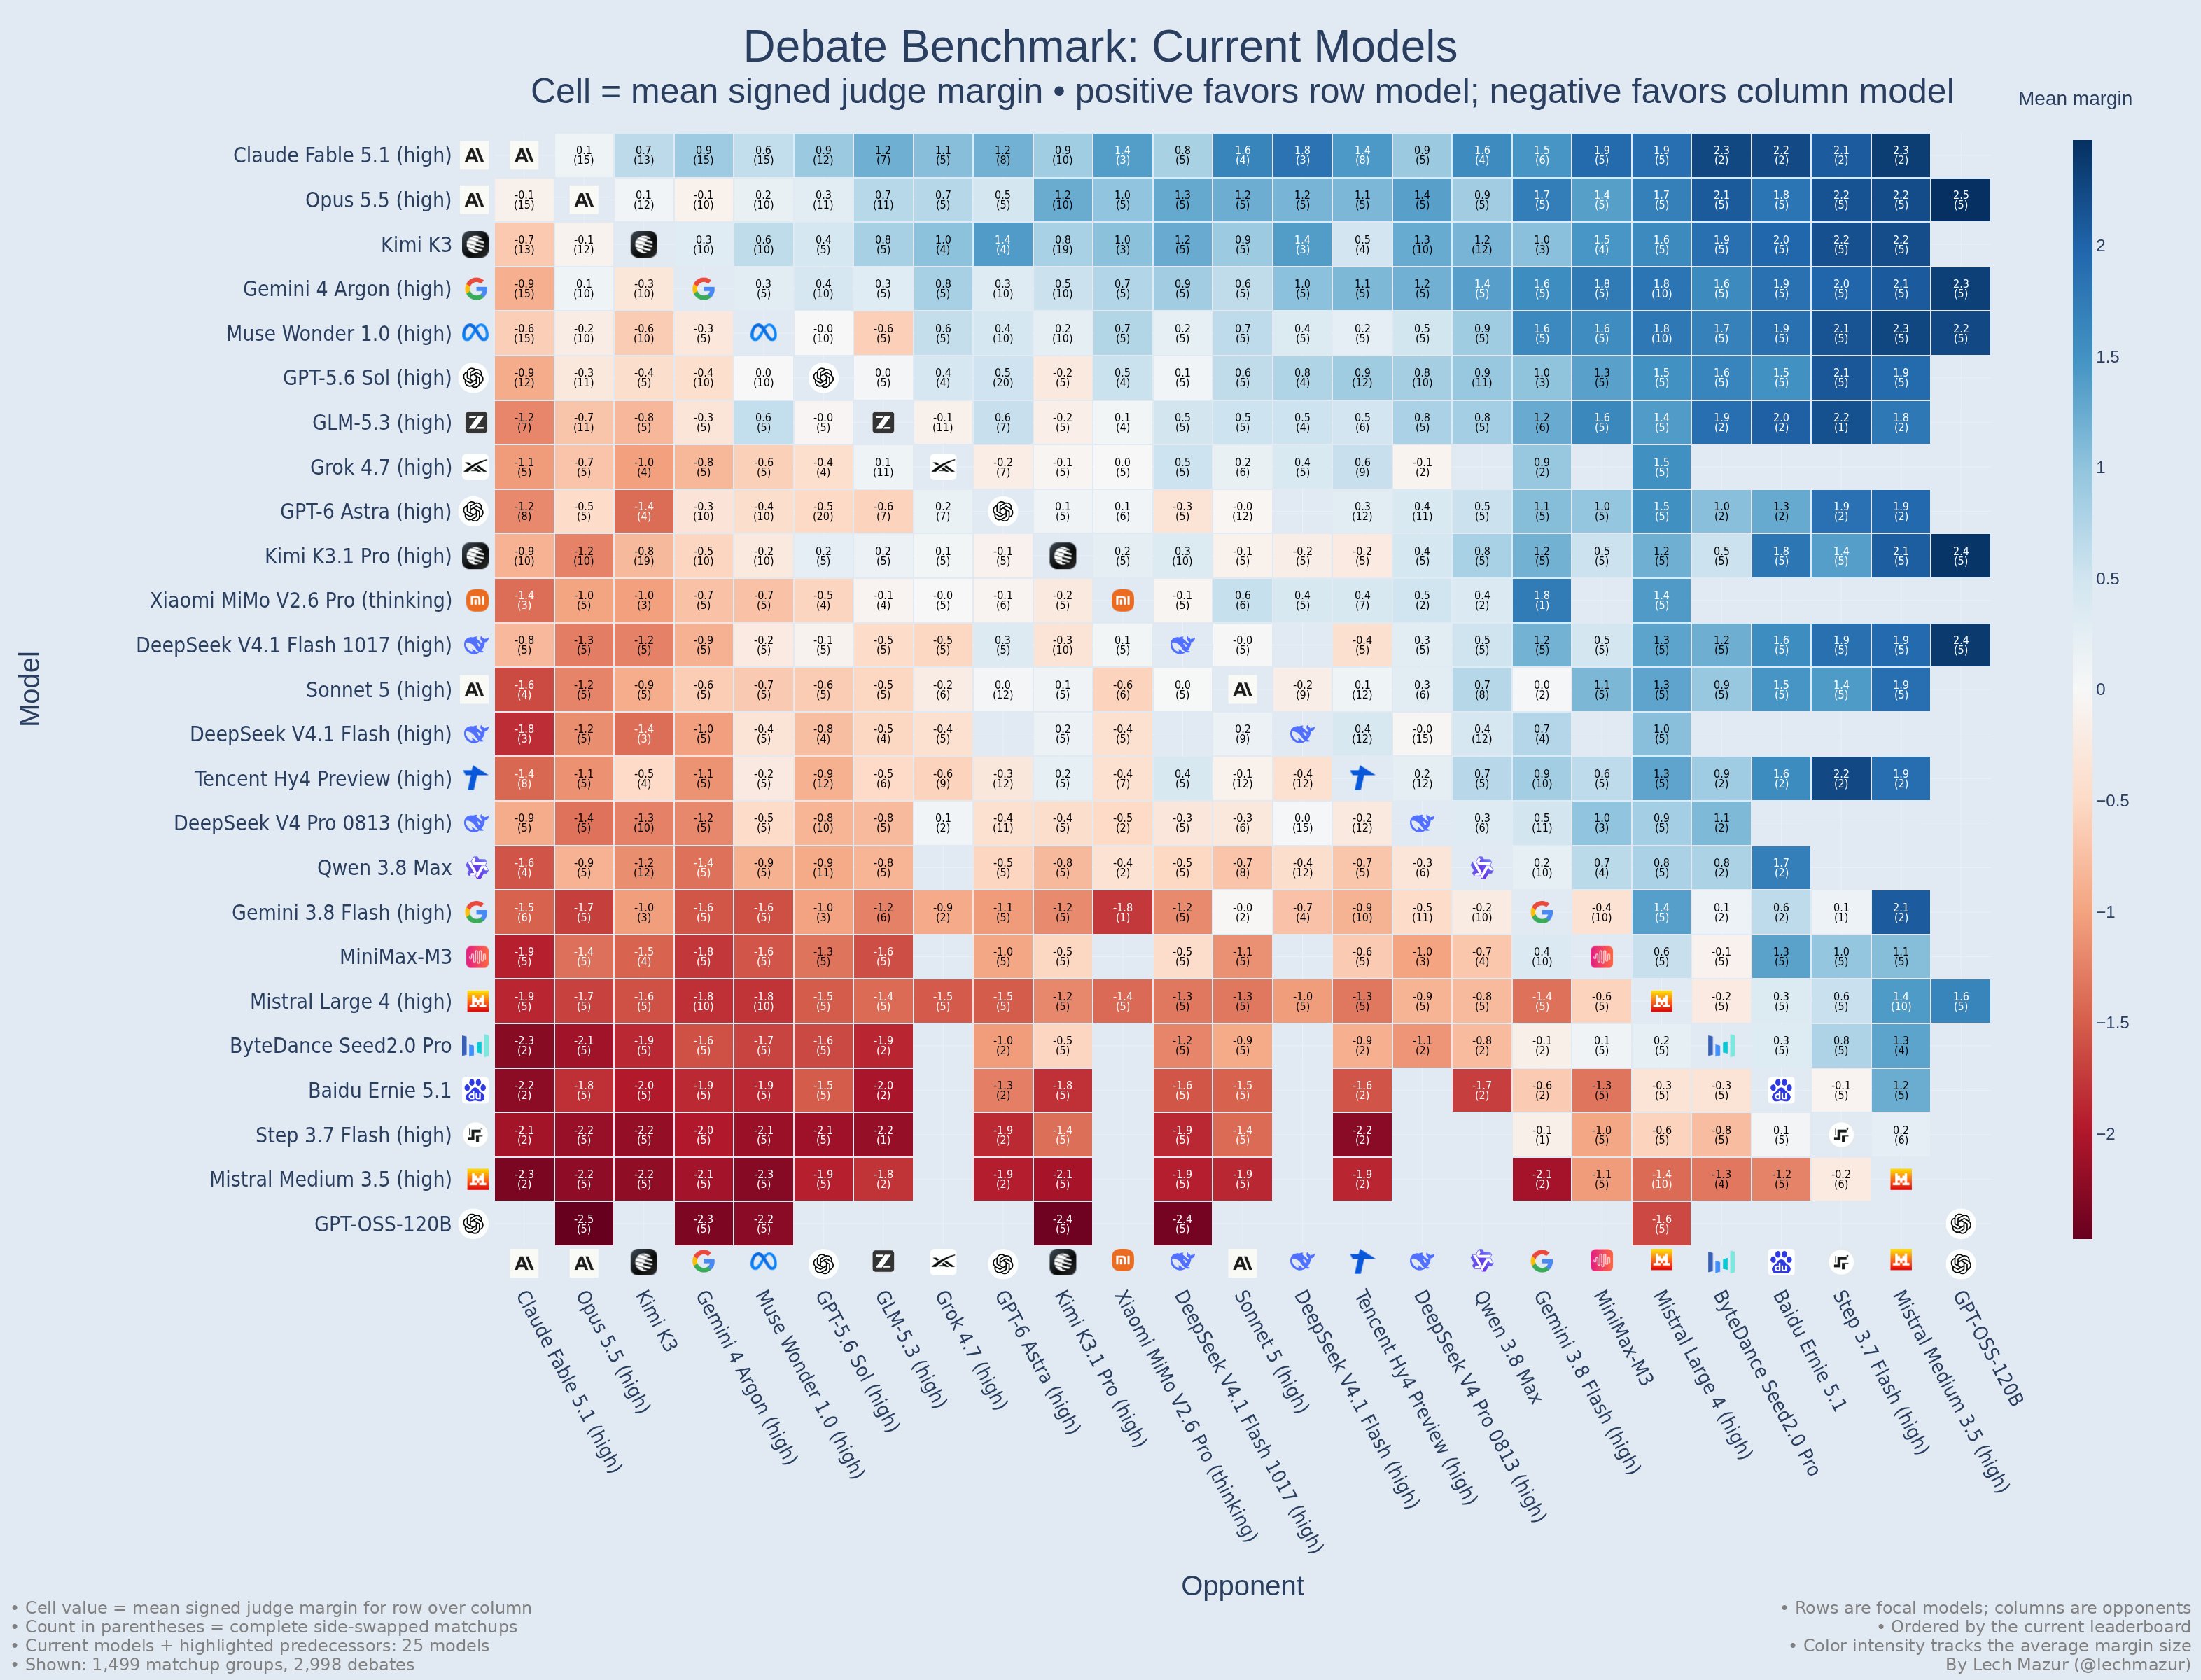
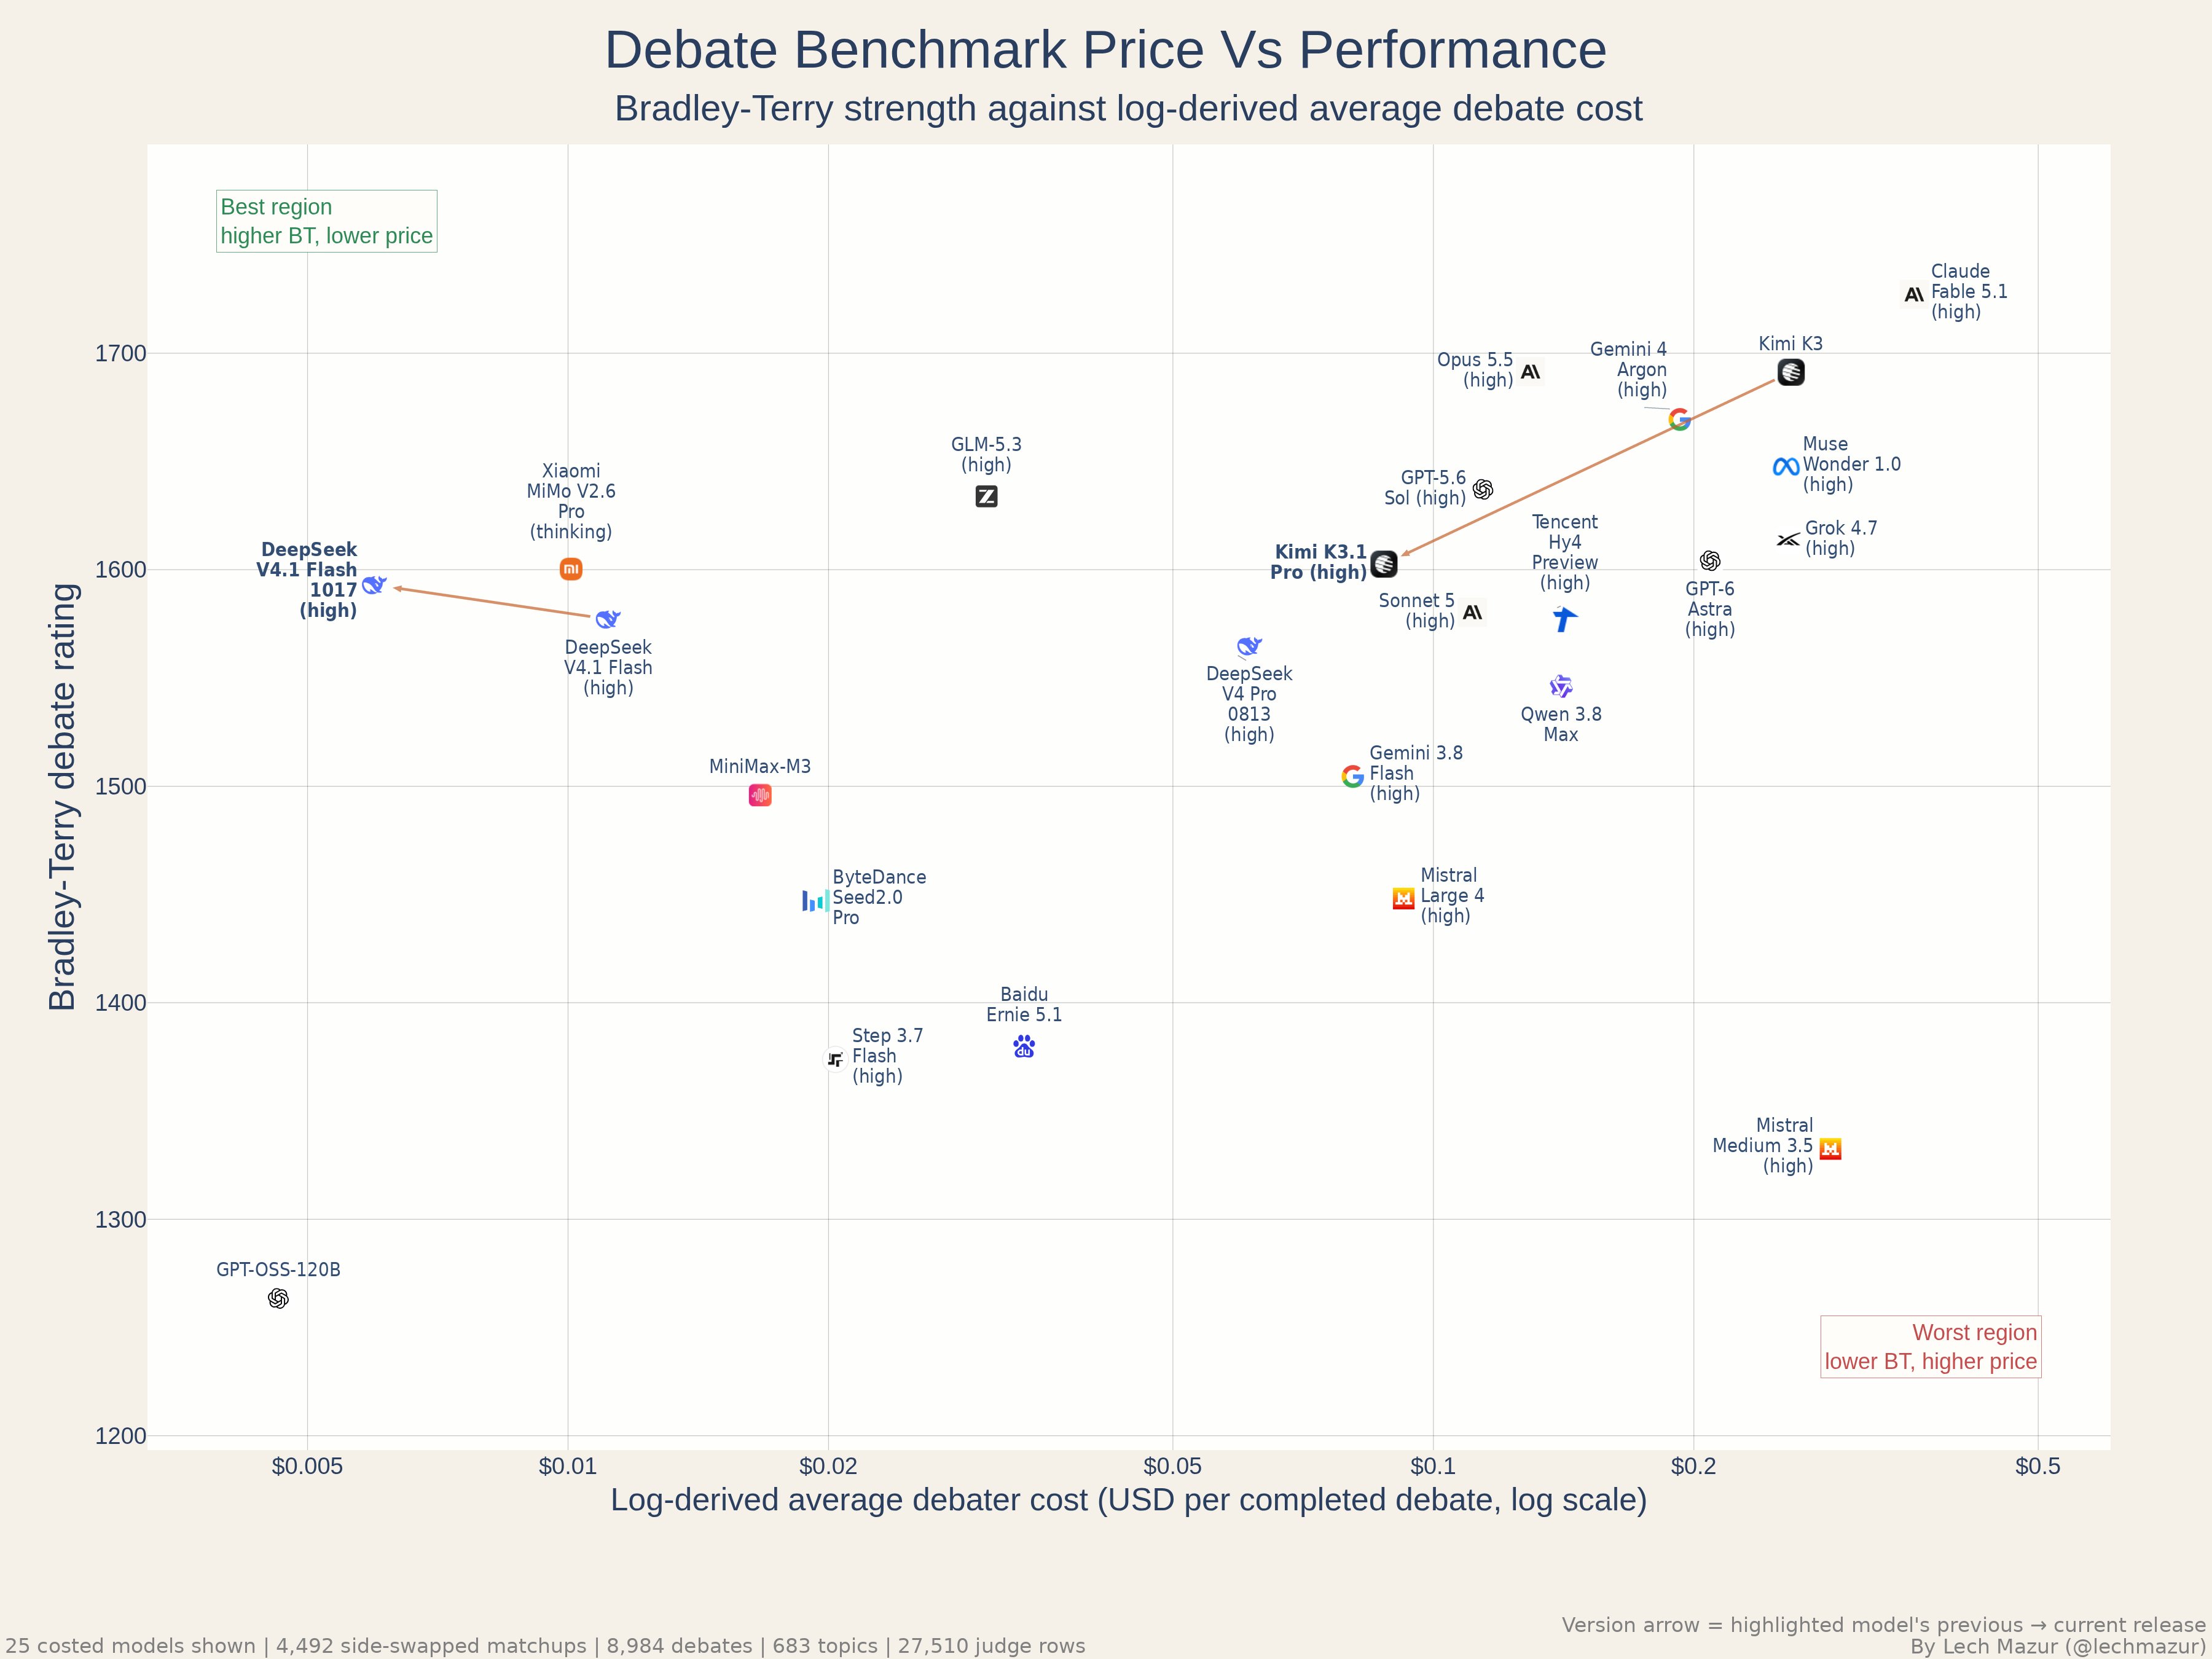
Two new models on the Debate Benchmark: Kimi K3.1 Pro (high) scores below Kimi K3 (high): 1691 → 1603, while averaging 66% fewer reasoning tokens. DeepSeek V4.1 Flash 1017 (high) scores above the earlier V4.1 Flash result: 1577 → 1593 (+16), while averaging 29% fewer reasoning tokens. https://github.com/lechmazur/debate Debate Benchmark tests how well models defend a position through sustained, adversarial, multi-turn opposition across hundreds of topics. It demands broad knowledge, factual accuracy under pressure, sharp rebuttals, and arguments that hold together round after round. Every matchup runs twice on the same motion, with PRO and CON swapped to control for side advantage. Three judges from distinct model families independently evaluate each debate's winner and margin.