Linsky tests Gemini 4 Argon: near-frontier but prone to infinite reasoning loops
Across 100 unsaturated coding and open-ended reasoning environments, Argon lands between Fable 5 and 5.1, excelling at financial simulations and circuit design but showing infinite reasoning loops and reasoning-block delineation failures.
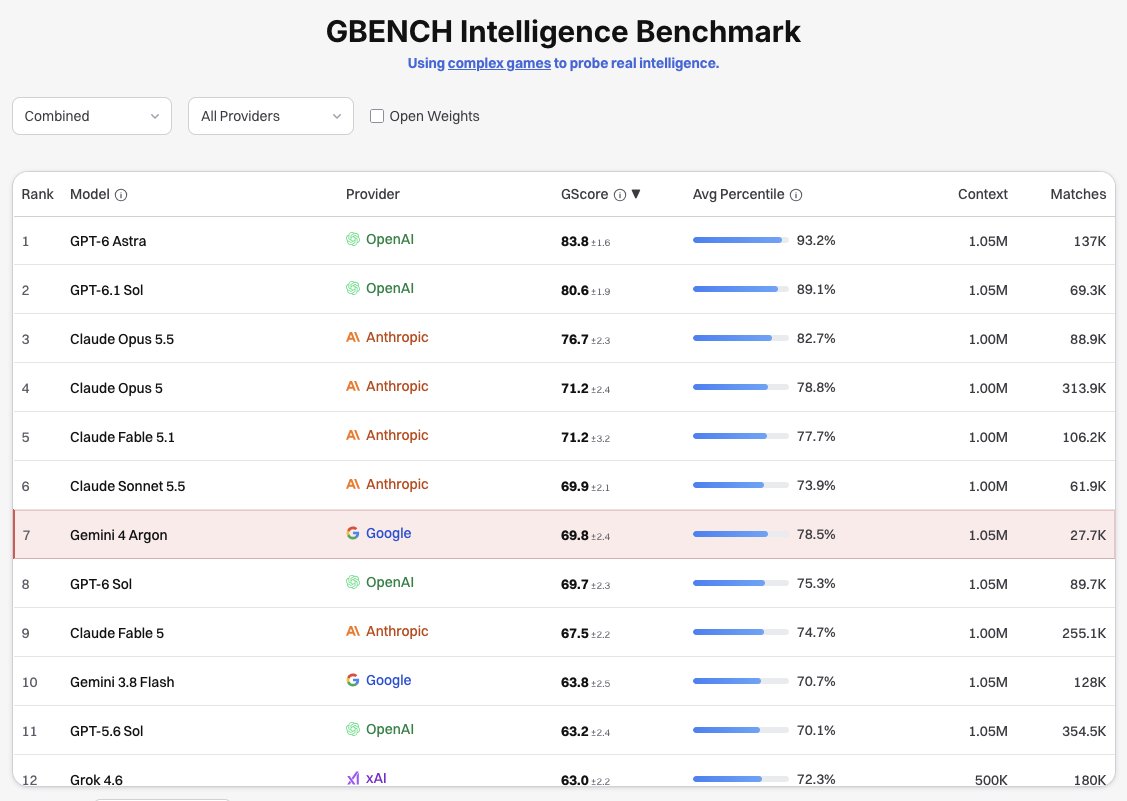
Google is so back. We tested Gemini 4 Argon across 100 unsaturated coding and open-ended reasoning environments. It's a near-frontier model, between Fable 5 and Fable 5.1. Google's major releases have usually done pretty well on our benchmarks because they're good at hard problems and open-ended decision making (with a well specified prompt), which obviously doesn't always translate to user experience (e.g. Gemini 3.x in a CLI...). In particular, older Google models struggled to work efficiently in a harness. They seem to have solved that with Argon. It's better at exploring and iterating in a harness than previous Google models, and it performed exceptionally well in financial simulations and circuit design. We did see a new problem which I hope they can fix. This is the first near-frontier model we've caught in infinite reasoning loops in a long time. We also saw a few examples of it failing to properly delineate reasoning blocks, so it has a higher failure rate than its competitors. My overall impression is that Argon is a near-frontier model for engineering design, code analysis, and chat. It definitely has the intelligence to be a competitive coding assistant product, but a good coding assistant needs to be polished, so they need to clean up the CoT bugs.