Gemini 4 Argon surprises in visual pointing test against Mistral Large 4 and Claude Haiku 5.5
A tester compared models on pointing at objects in everyday photos with some scene understanding, finding Gemini 4 Argon surprisingly strong while noting trade-offs for Mistral Large 4, Claude Haiku 5.5, GroundingPI 4B and Muse Wonder.
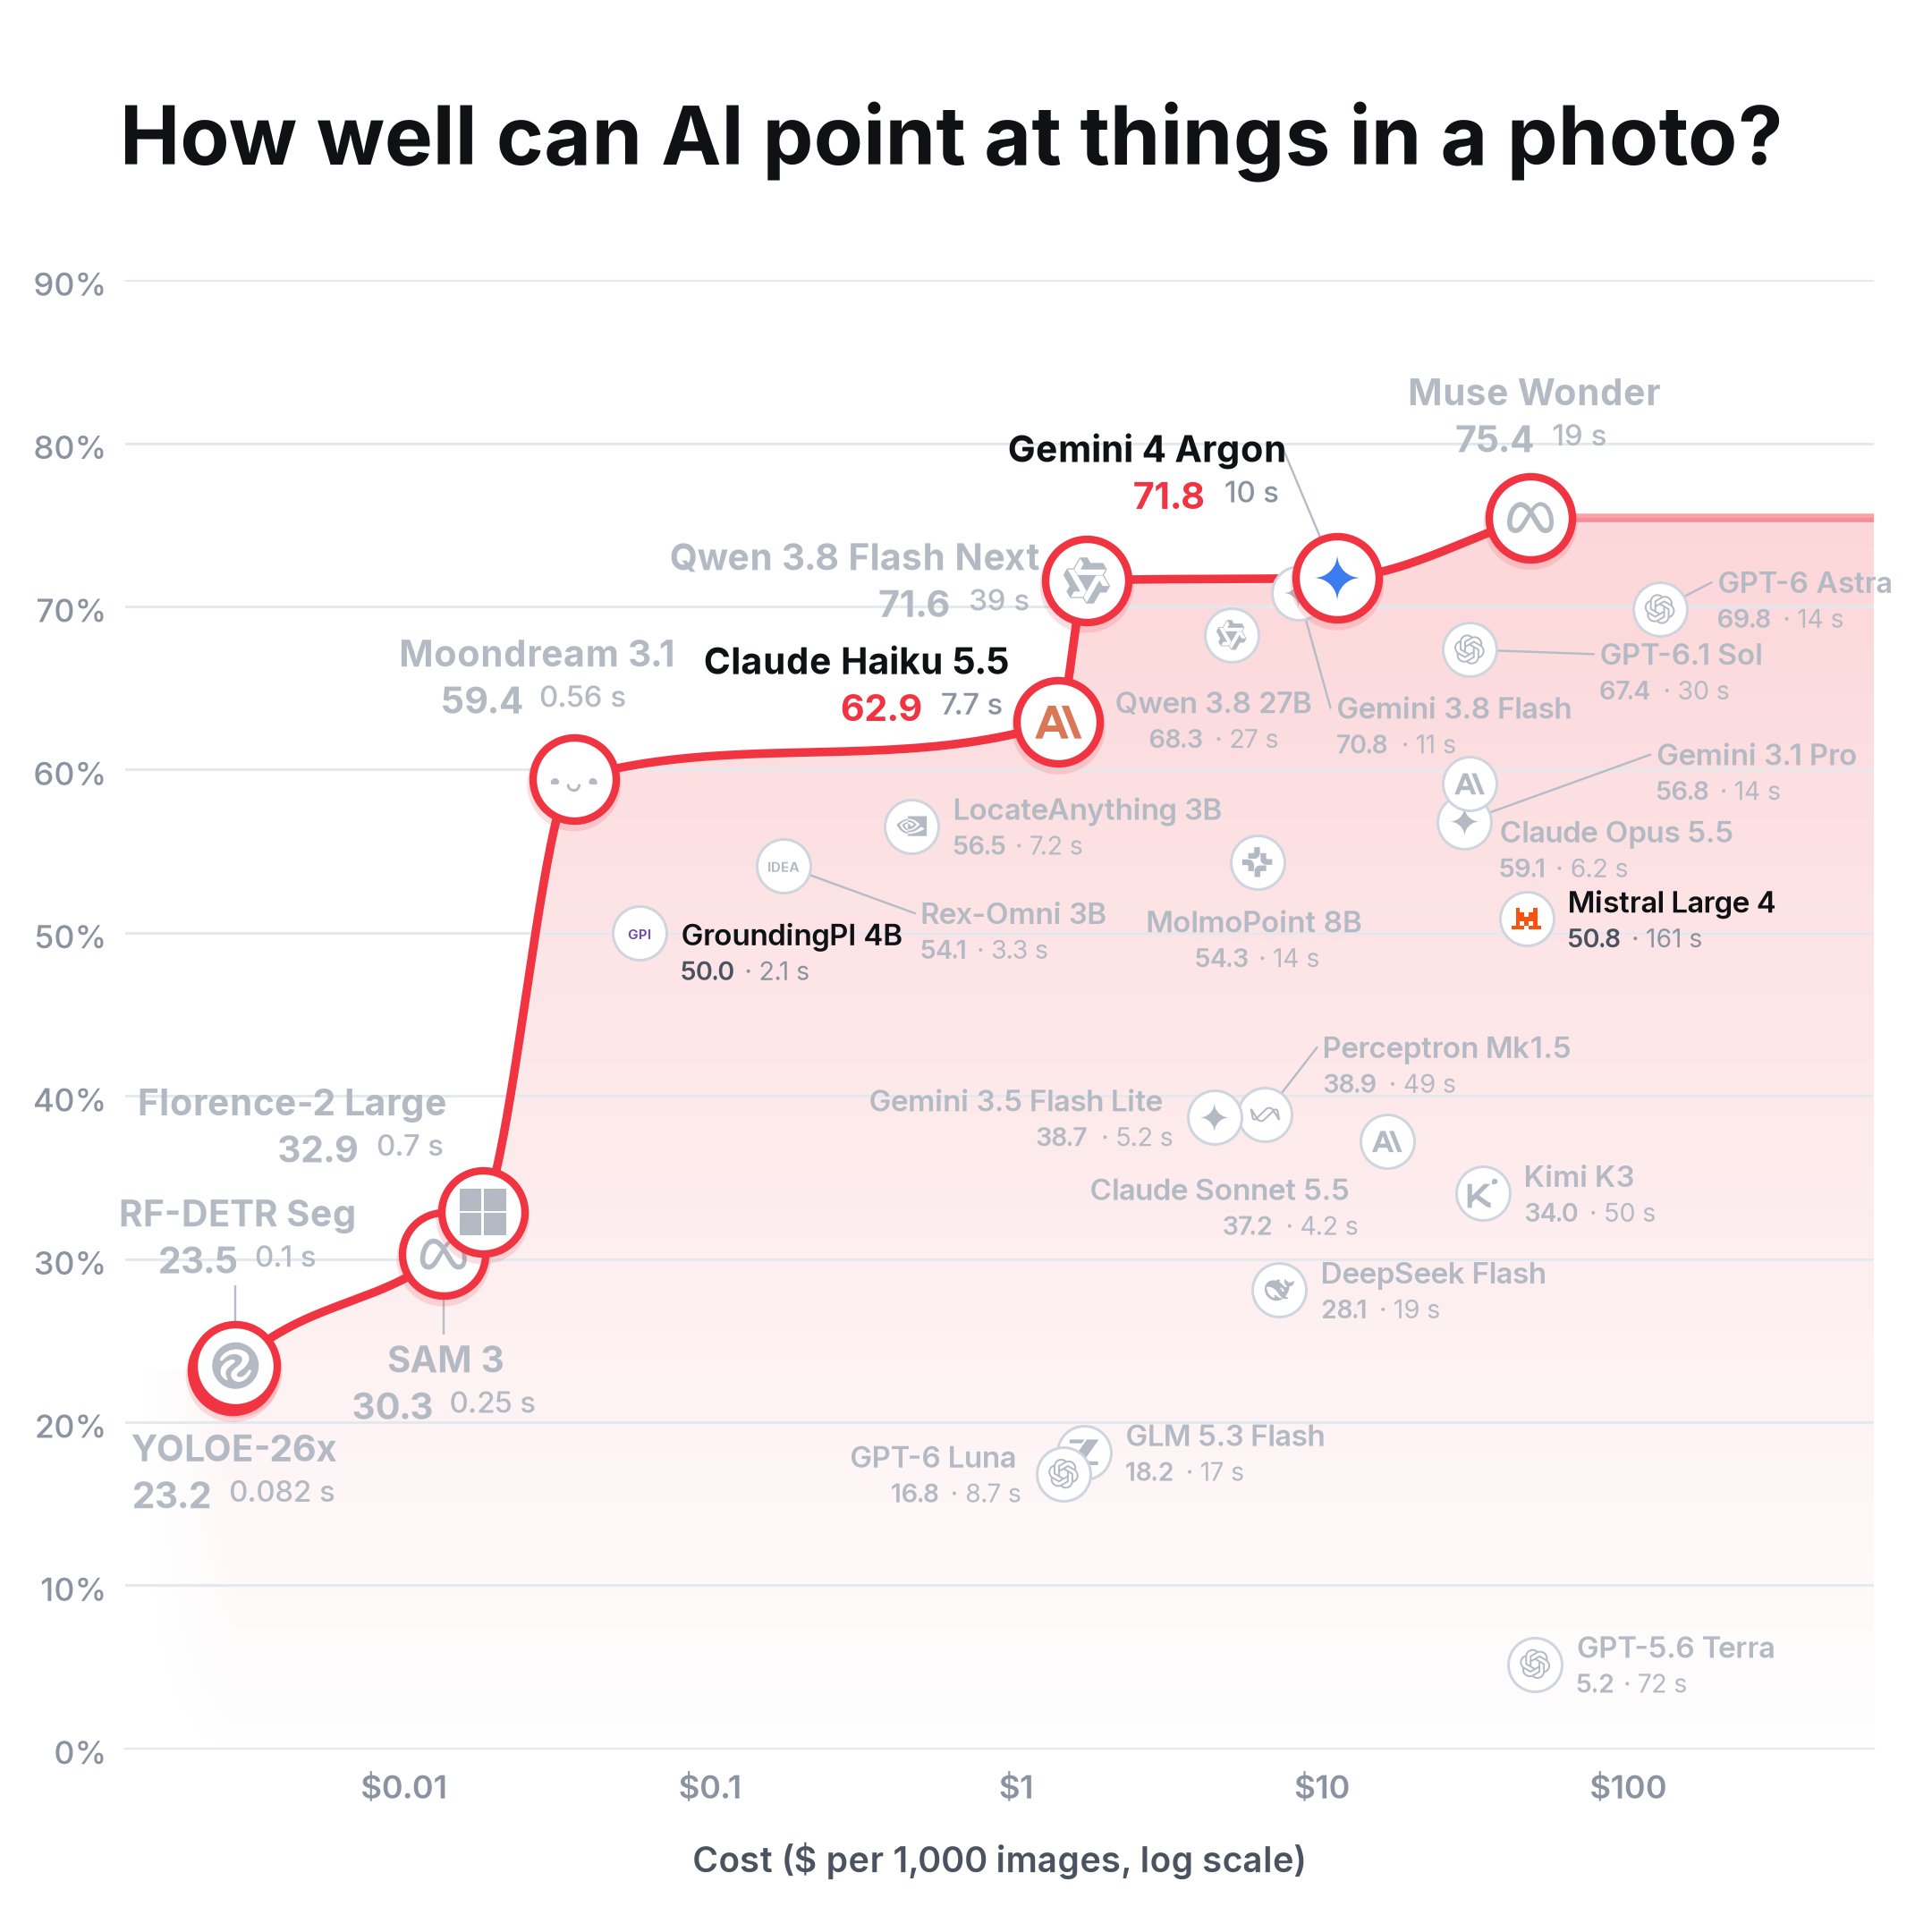
I'm very surprised by Argon's results! Gemini 4 Argon: Other benchmarks have placed Argon as top performing for vision. My task is specifically points on everyday pictures with some scene understanding (not only a direct object description). It's also only this task, not a compound, which does not mean that its performance will be similar across other vision tasks. Le Chonk, Mistral Large 4: Mistral claimed sota level vision for this model and this is not what we see here. Their demos were really impressive, but also direct object descriptions. Since my prompts require scene understanding, it is not the same task or difficulty. Claude Haiku 5.5: I'm very surprised by how well it performed compared to Sonnet. I reran Sonnet and checked the traces to be sure and the result is correct. Sonnet correctly labels what is needed, but also provides a lot of false positives which sinks the score badly. Haiku misses some instances, but overwise has correct points. Good bang for buck if you only have a Claude subscription. GroundingPI 4B: A small 4B model that claims to beat Astra (in a compound metric). The paper shows performance above Astra on a suite of tasks and below on others. It beats Astra strongly on OCR type tasks, but looses in some pointing tasks which seems to be what we see here as well. Muse Wonder: These results made me a little suspicious of Muse Wonder so I reran the tests through the API instead of the subscription. It got 0.5% more. So I think this result is valid. Muse Wonder just seems strong at scene understanding. (Tough personally I would not overindex too much on this much of a difference with the other top models.) I'm slowly building other vision tasks to see how they compare to pointing!