Liquid AI releases LFM3 on-device foundation model family
Liquid AI's LFM3 uses a tri-hybrid architecture so its 1.7B text model beats LFM2.5-2.6B with 35% fewer parameters, fits in about 1GB at 4-bit, supports 256K context, and anchors six 2B-class text, vision, audio, omni and decision models.
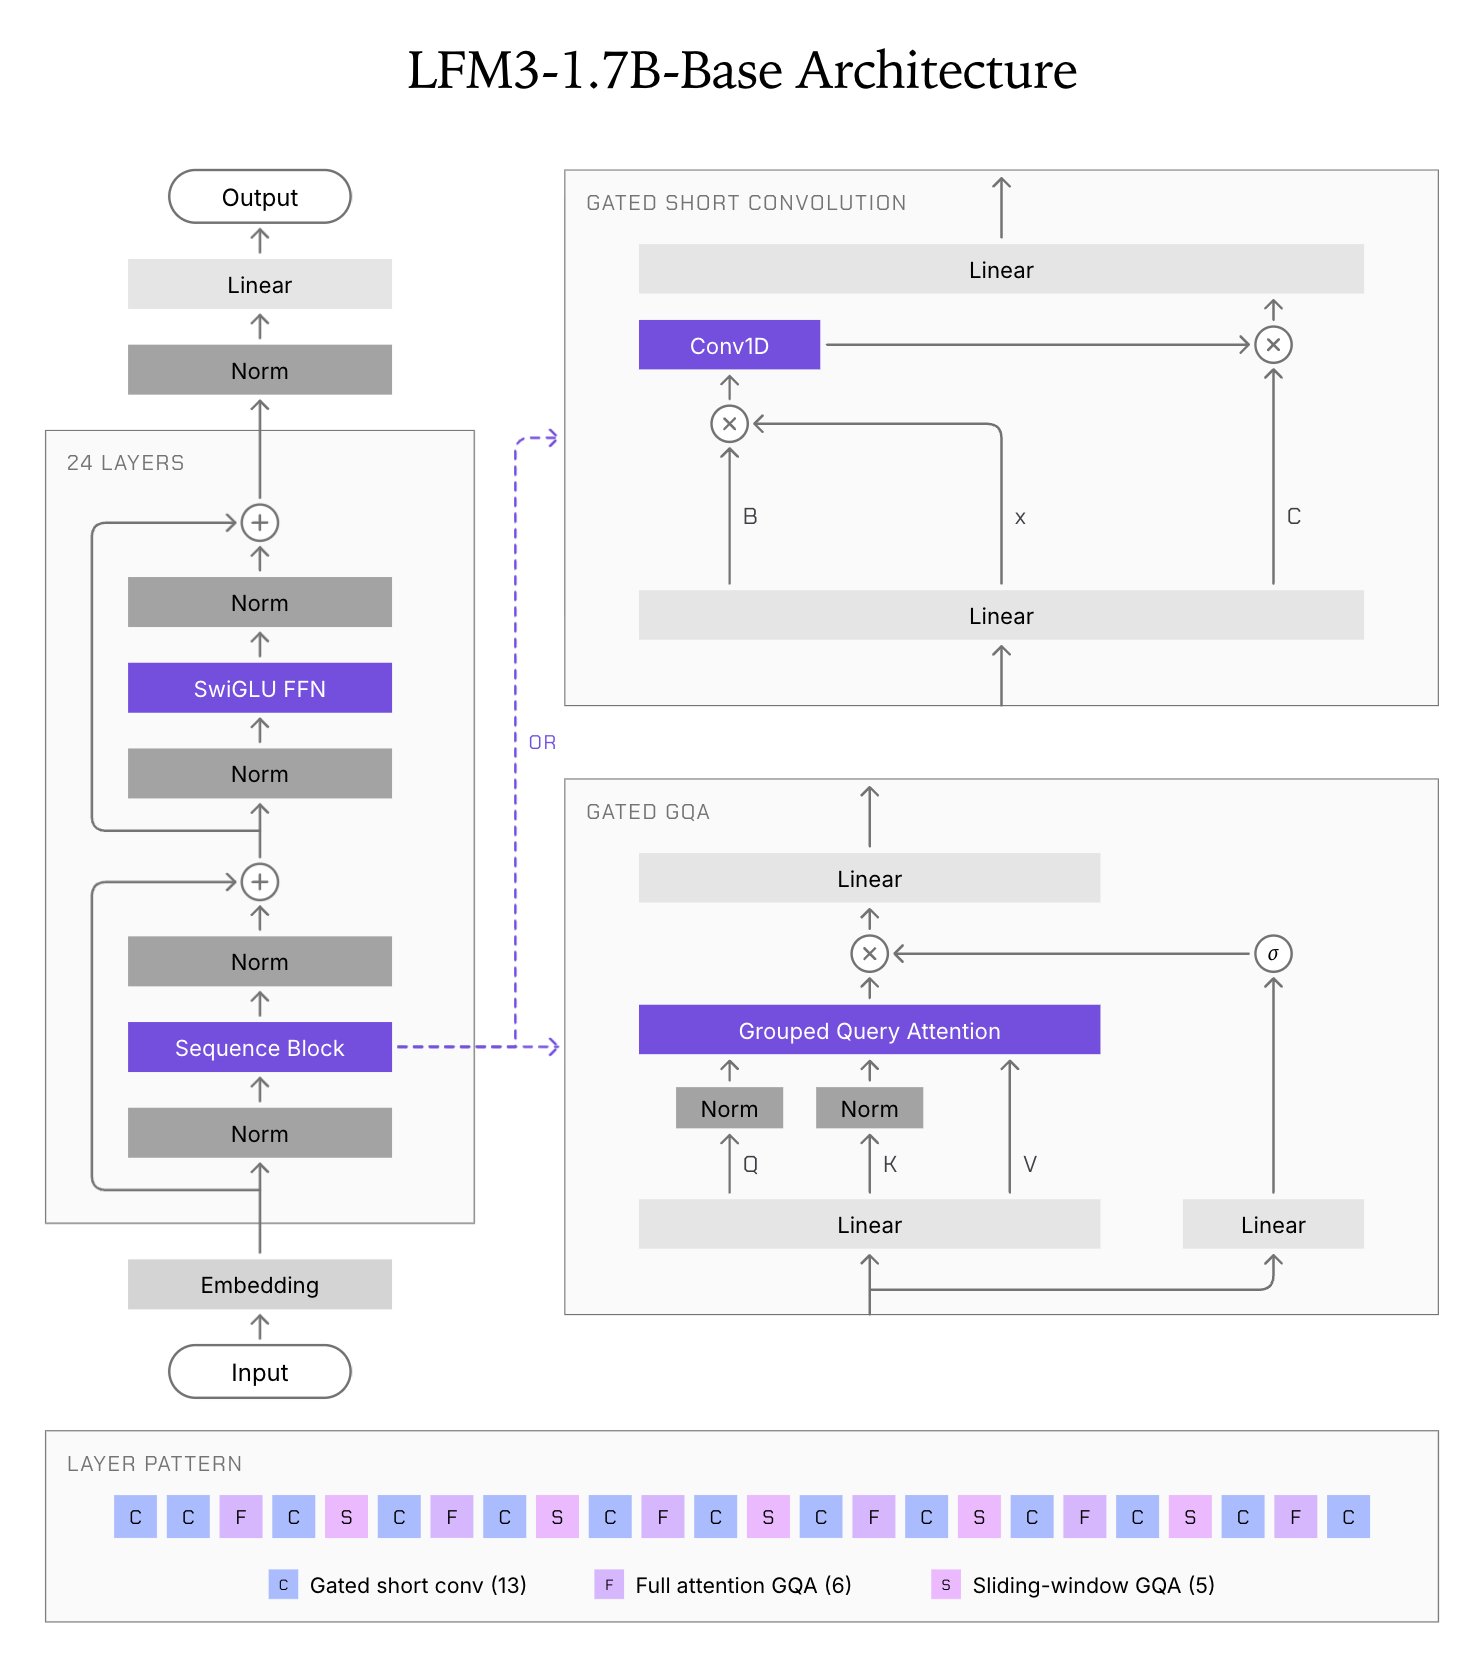
LFM3 is our most capable generation of foundation models yet, built for specialization and on-device deployment. Here’s what’s new: > More capability per parameter: a new tri-hybrid architecture combines gated short convolutions, sliding-window attention, and global attention. Together with an updated training recipe, it lets 𝙻𝙵𝙼𝟹-𝟷.𝟽𝙱 outperform LFM2.5-2.6B with 35% fewer parameters. > Every modality, one backbone: six 2B-class models for text, vision, audio, omni, and decision tasks, all built on 𝙻𝙵𝙼𝟹-𝟷.𝟽𝙱-𝙱𝚊𝚜𝚎. > Built for the edge: The text model’s weights fit in about 1GB at 4-bit precision, and it supports a 256K-token context window for longer agent workflows. > Made to be specialized: Each model can be fine-tuned on a single GPU. Adapt it to your data, terminology, and tasks. Then deploy on devices, private infrastructure, or in the cloud. 2/