Lithos engine hits 2,100+ tok/s per user on DeepSeek V4.1 Flash with eight MI355X GPUs
Lithos reports over 2,100 tokens/s per user for DeepSeek V4.1 Flash on eight AMD MI355X GPUs, up to 3.4x faster inference, with decode speed, cost per token and latency up to 1M context.
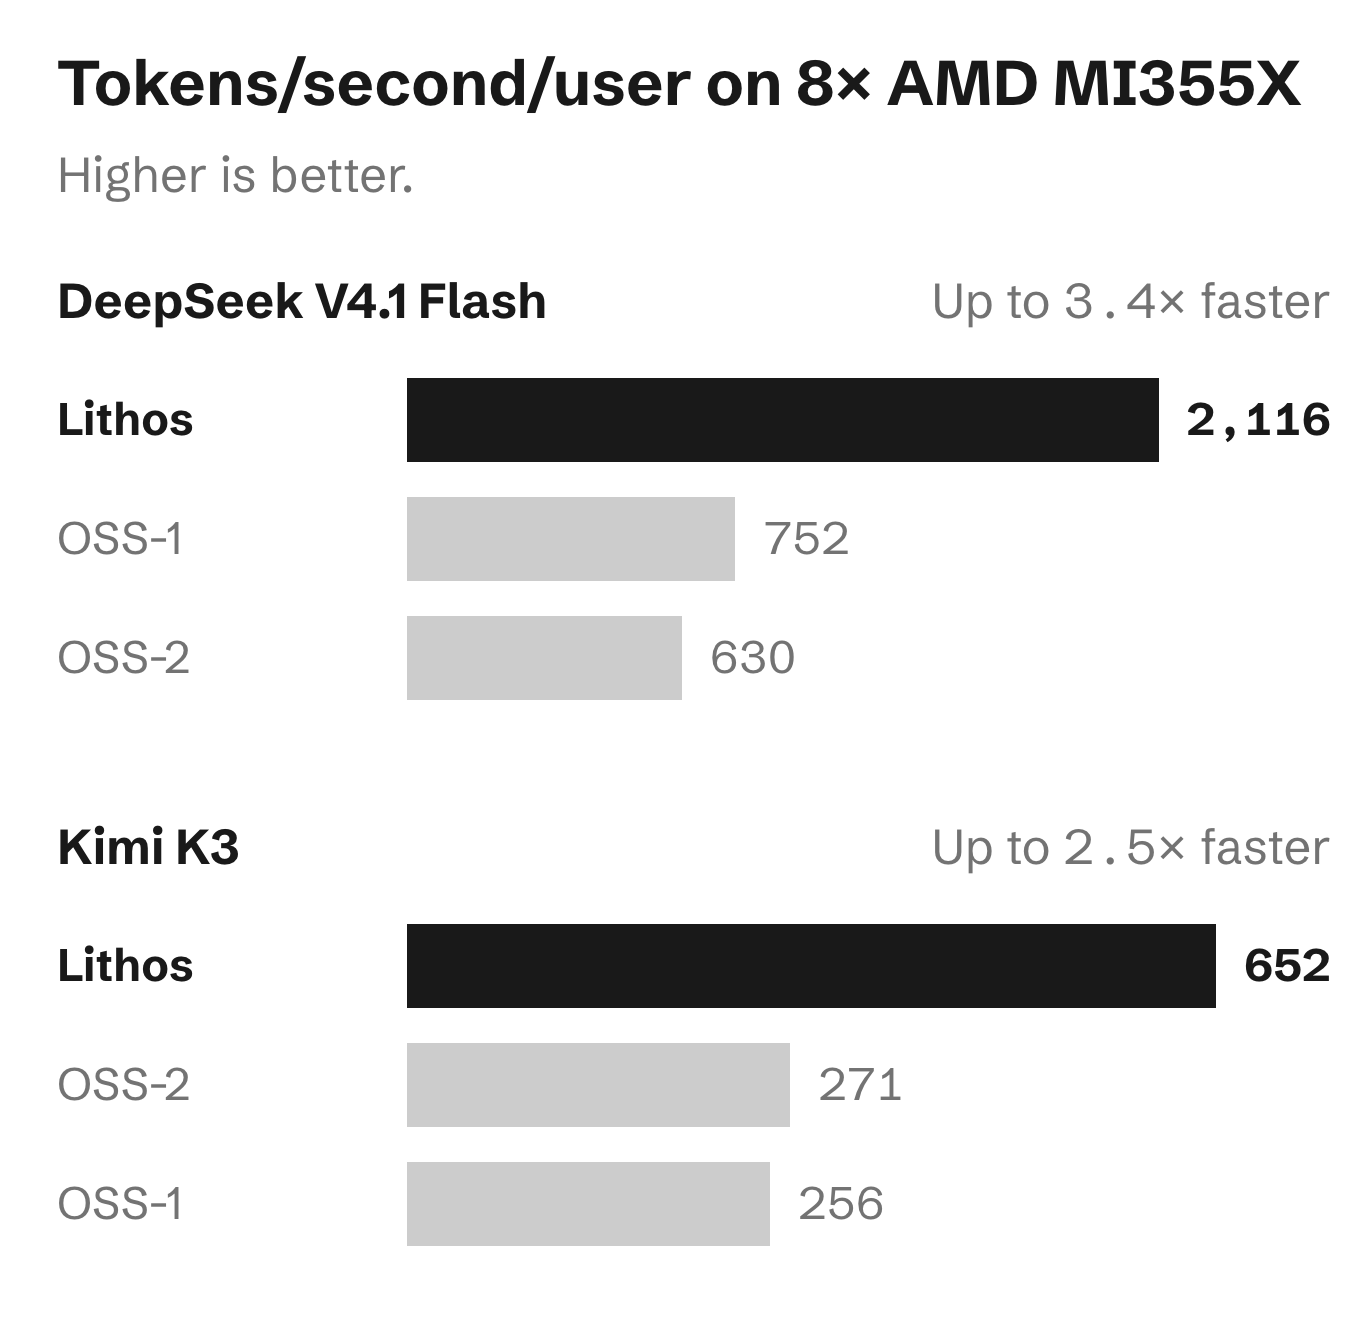
2,100+ tokens per second per user on DeepSeek V4.1 Flash, at full model quality, on eight AMD Instinct MI355X GPUs. In our benchmarks, the Lithos engine delivers: → Up to 3.4× faster inference for DeepSeek V4.1 Flash → Up to 2.5× faster inference for Kimi K3 Compared with tested open-source engines on the same eight GPUs. The key challenge is reducing the coordination tax: time spent waiting between kernels and across GPUs. Our approach combines persistent megakernels, overlapping execution, and communication inside computation. Our technical deep dive covers: - Decode speed, cost per token, and latency up to 1M context. - How Lithos engine reduces launch overhead and overlap computation with communication across GPUs. - How MI355X’s register capacity and direct instruction-level control enable hardware-specific optimizations. - What our roofline analysis reveals about opportunities for further speedups. Read the full analysis: https://www.lithosai.com/blog/ultra-fast-inference-2100-tokens-per-second-amd-mi355x