SGLang low-latency mode: DeepSeek V4.1 Flash hits 928 tok/s P90 on GB300
LMSYS with NVIDIA and AMD launched SGLang Low-Latency Mode, giving DeepSeek V4.1 Flash 1.38x P90 speedup to 928 tok/s on GB300 and 1.56x to 516 tok/s on MI355X.
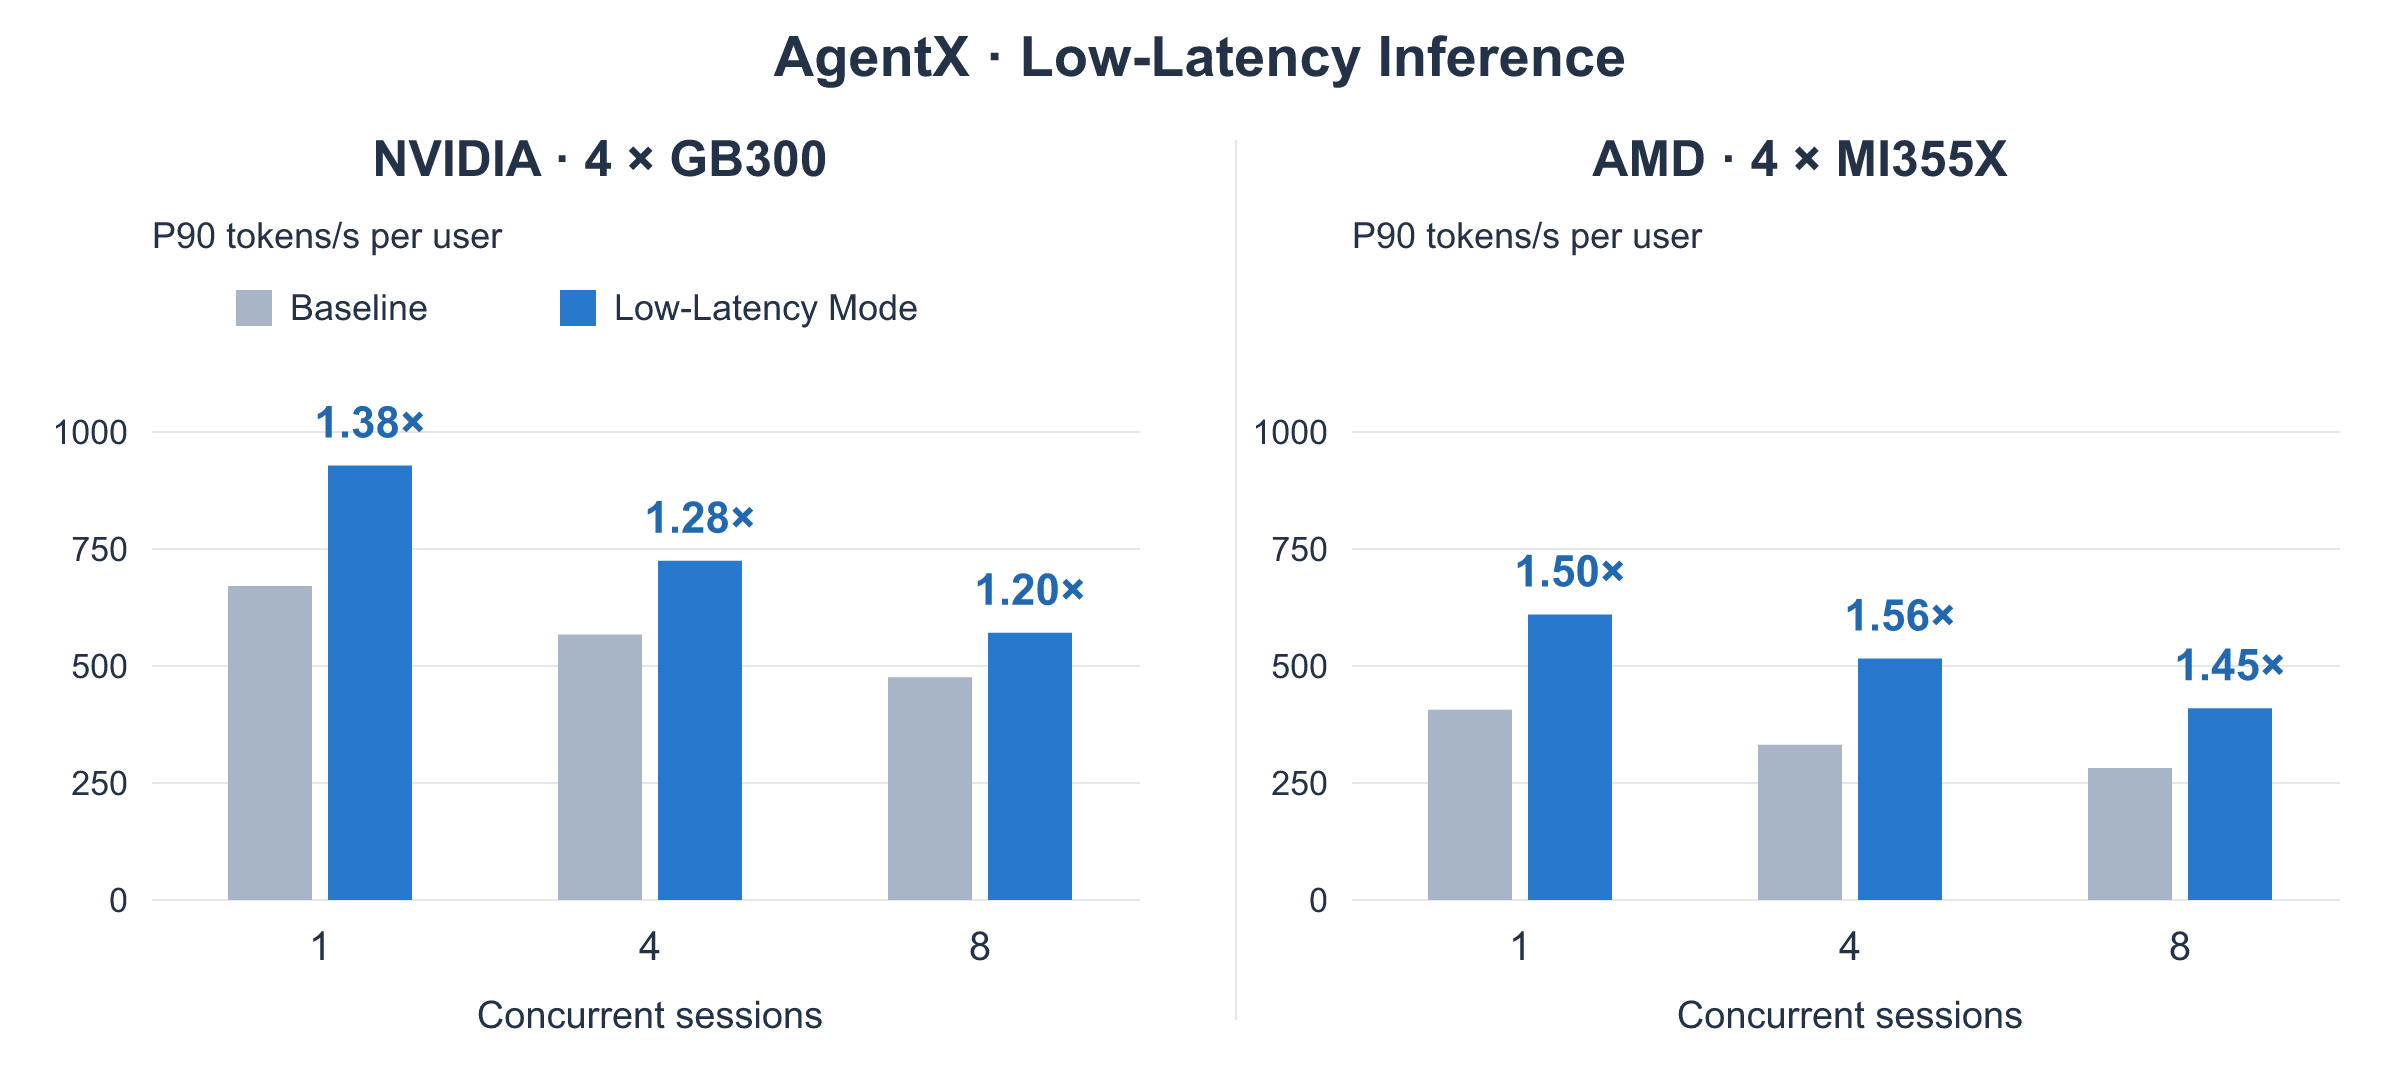
Introducing SGLang Low-Latency Mode, built with @NVIDIAAI and @AMD. On DeepSeek-V4.1-Flash with DSpark, it delivers up to 1.38× P90 per-user token speed on NVIDIA GB300 (671 to 928 tok/s) and 1.56× on AMD MI355X (332 to 516 tok/s) in @SemiAnalysis_'s AgentX trace replay. Highlights: - NVIDIA: overlapping kernels cut decoder layer time from 96.8 to 68.4 µs - AMD: 2 persistent kernels per layer replace dozens of small ones, with cross-GPU communication overlapped inside them. - New plugin system: custom kernels plug in from external libraries, with automatic fallback. - Low-latency kernels for GLM-5.3, K3, and MiniMax M3 are in progress and will plug in next.