Checking Jev's confidence threshold with a Brier score
The author shares a ten-line script that computes a Brier score from logged Jev confidence scores and actual outcomes, to test whether the 0.85 escalation threshold fits your task.
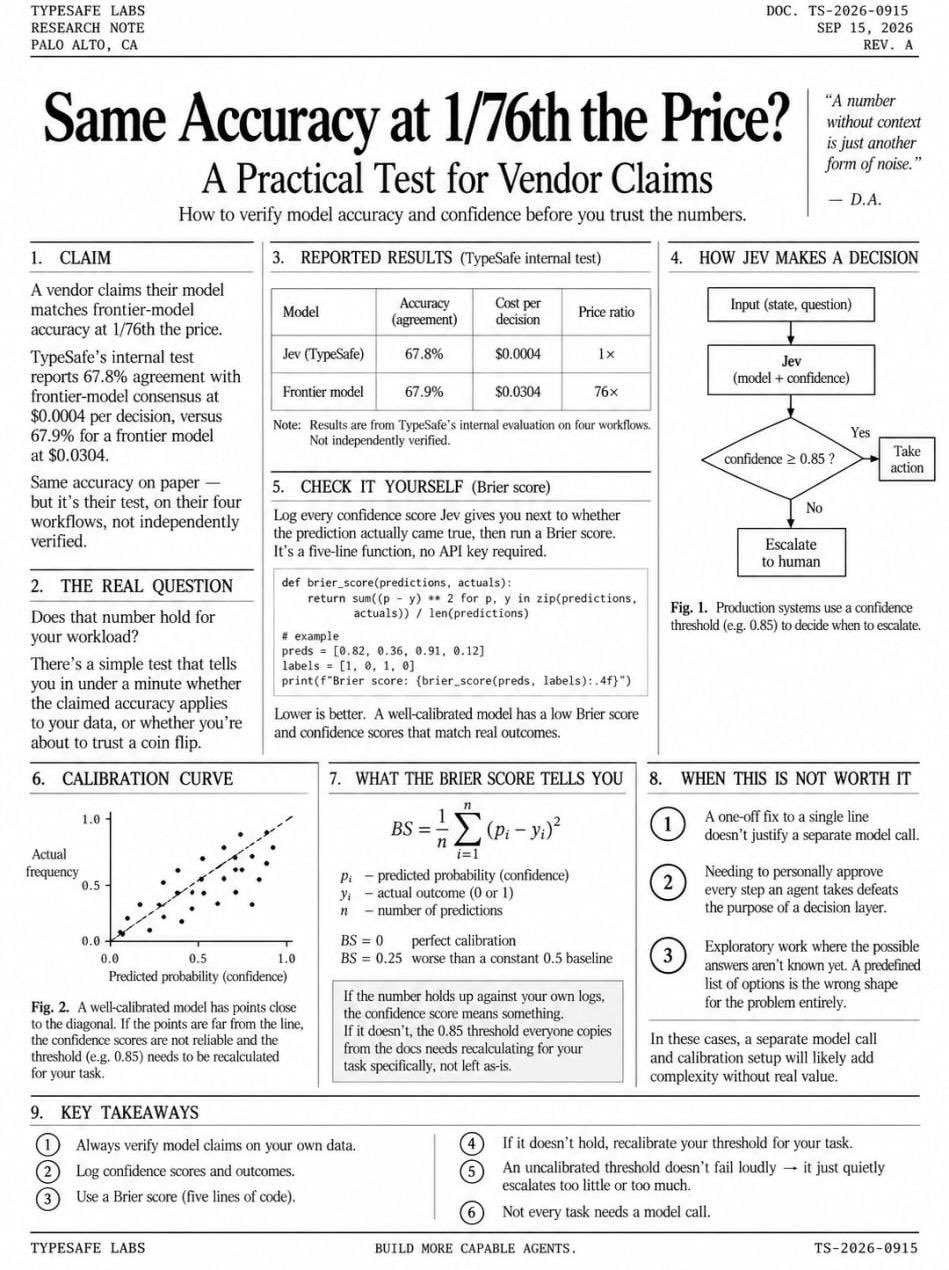
A vendor claims their model matches frontier-model accuracy at 1/76th the price there's a ten-line script that tells you in under a minute whether that number applies to your workload, or whether you're about to trust a coin flip TypeSafe's own internal test claims 67.8% agreement with frontier-model consensus at $0.0004 per decision, against 67.9% for a frontier model at $0.0304. Same accuracy on paper - but it's their test, on their four workflows, not independently verified here's the check: log every confidence score Jev gives you next to whether that prediction actually came true, then run a Brier score on the pairs. It's a five-line function, no API key required if the number holds up against your own logs, the confidence score means something. If it doesn't, the 0.85 threshold everyone copies from the docs needs recalculating for your task specifically, not left as-is that number matters because production leans on it directly: below 0.85 confidence, the system is supposed to escalate to a human instead of guessing. An uncalibrated threshold doesn't fail loudly - it just quietly escalates too little or too much, and nobody notices until the wrong ticket goes through unreviewed There are also three situations where none of this is worth setting up. A one-off fix to a single line doesn't justify a separate model call Needing to personally approve every step an agent takes defeats the purpose of a decision layer. And on exploratory work, where the possible answers aren't known yet, a predefined list of options is the wrong shape for the problem entirely The calibration script and the full breakdown are in the article below
This post quotes another post: x.com/danikkk_wqs/status/2101706326883655710