DeepSeek V4.1 Flash 1–2 bit quants: 37 tok/s on 2x3090, but more overthinking
On dual 3090s, the dsx 2-bit build hits 37 tok/s while Unsloth's 1-bit GGUF gets 12.3 tok/s; the author blames lossy quantization for thinking length rising from 10.7K to over 20K tokens.
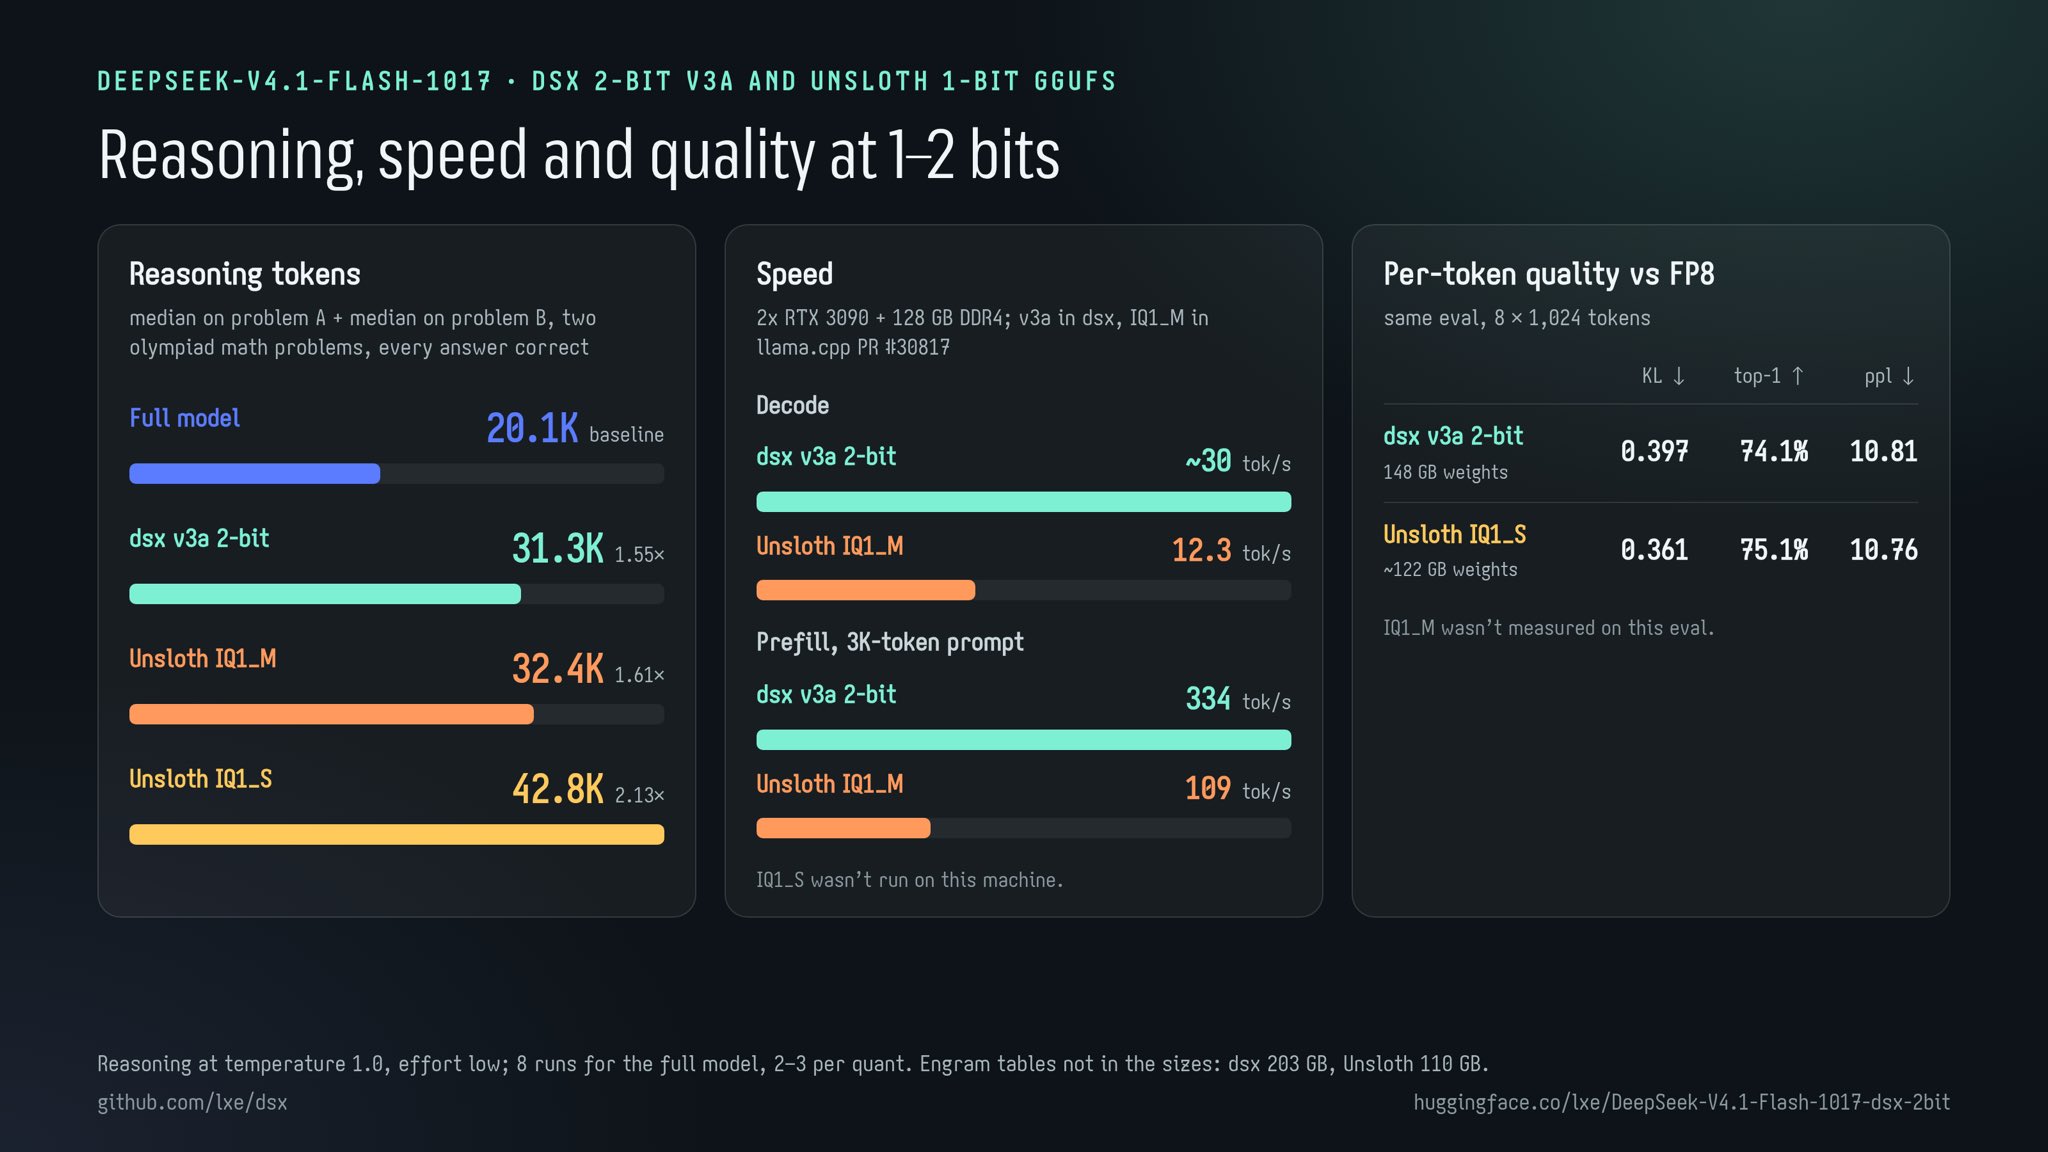
DeepSeek-V4.1-Flash-1017 at 1–2 bit quants: dsx 2-bit v3a (148 GB) and Unsloth's 1-bit GGUFs 2x3090: - dsx v3a: 37 tok/s (~500 prefill) - llama.cpp unsloth UD-IQ1_M: 12.3 tok/s (~90 tuned prefill) Per-token quality vs FP8 (same eval, 8 × 1,024 tokens): dsx v3a: - KL 0.397, top-1 74.1%, ppl 10.81 Unsloth IQ1_S: - (~122 GB): KL 0.361, top-1 75.1%, ppl 10.76 Overthinking (olympiad problem): - full model 10.7K - dsx v3a 20.8K - IQ1_M 20.3K - IQ1_S 29.8K I’m convinced that lossy precision reduction is what’s causing it to overthink in every 1-2bit quant http://github.com/lxe/dsx