Fable 5.1 has a blind spot on simple multiplication that GPT-6 Astra lacks
At low reasoning effort, Fable 5.1 drops to about 0% accuracy on multiplications like 5x6 because it skips reasoning and answers directly, while GPT-6 Astra does not show this blind spot.
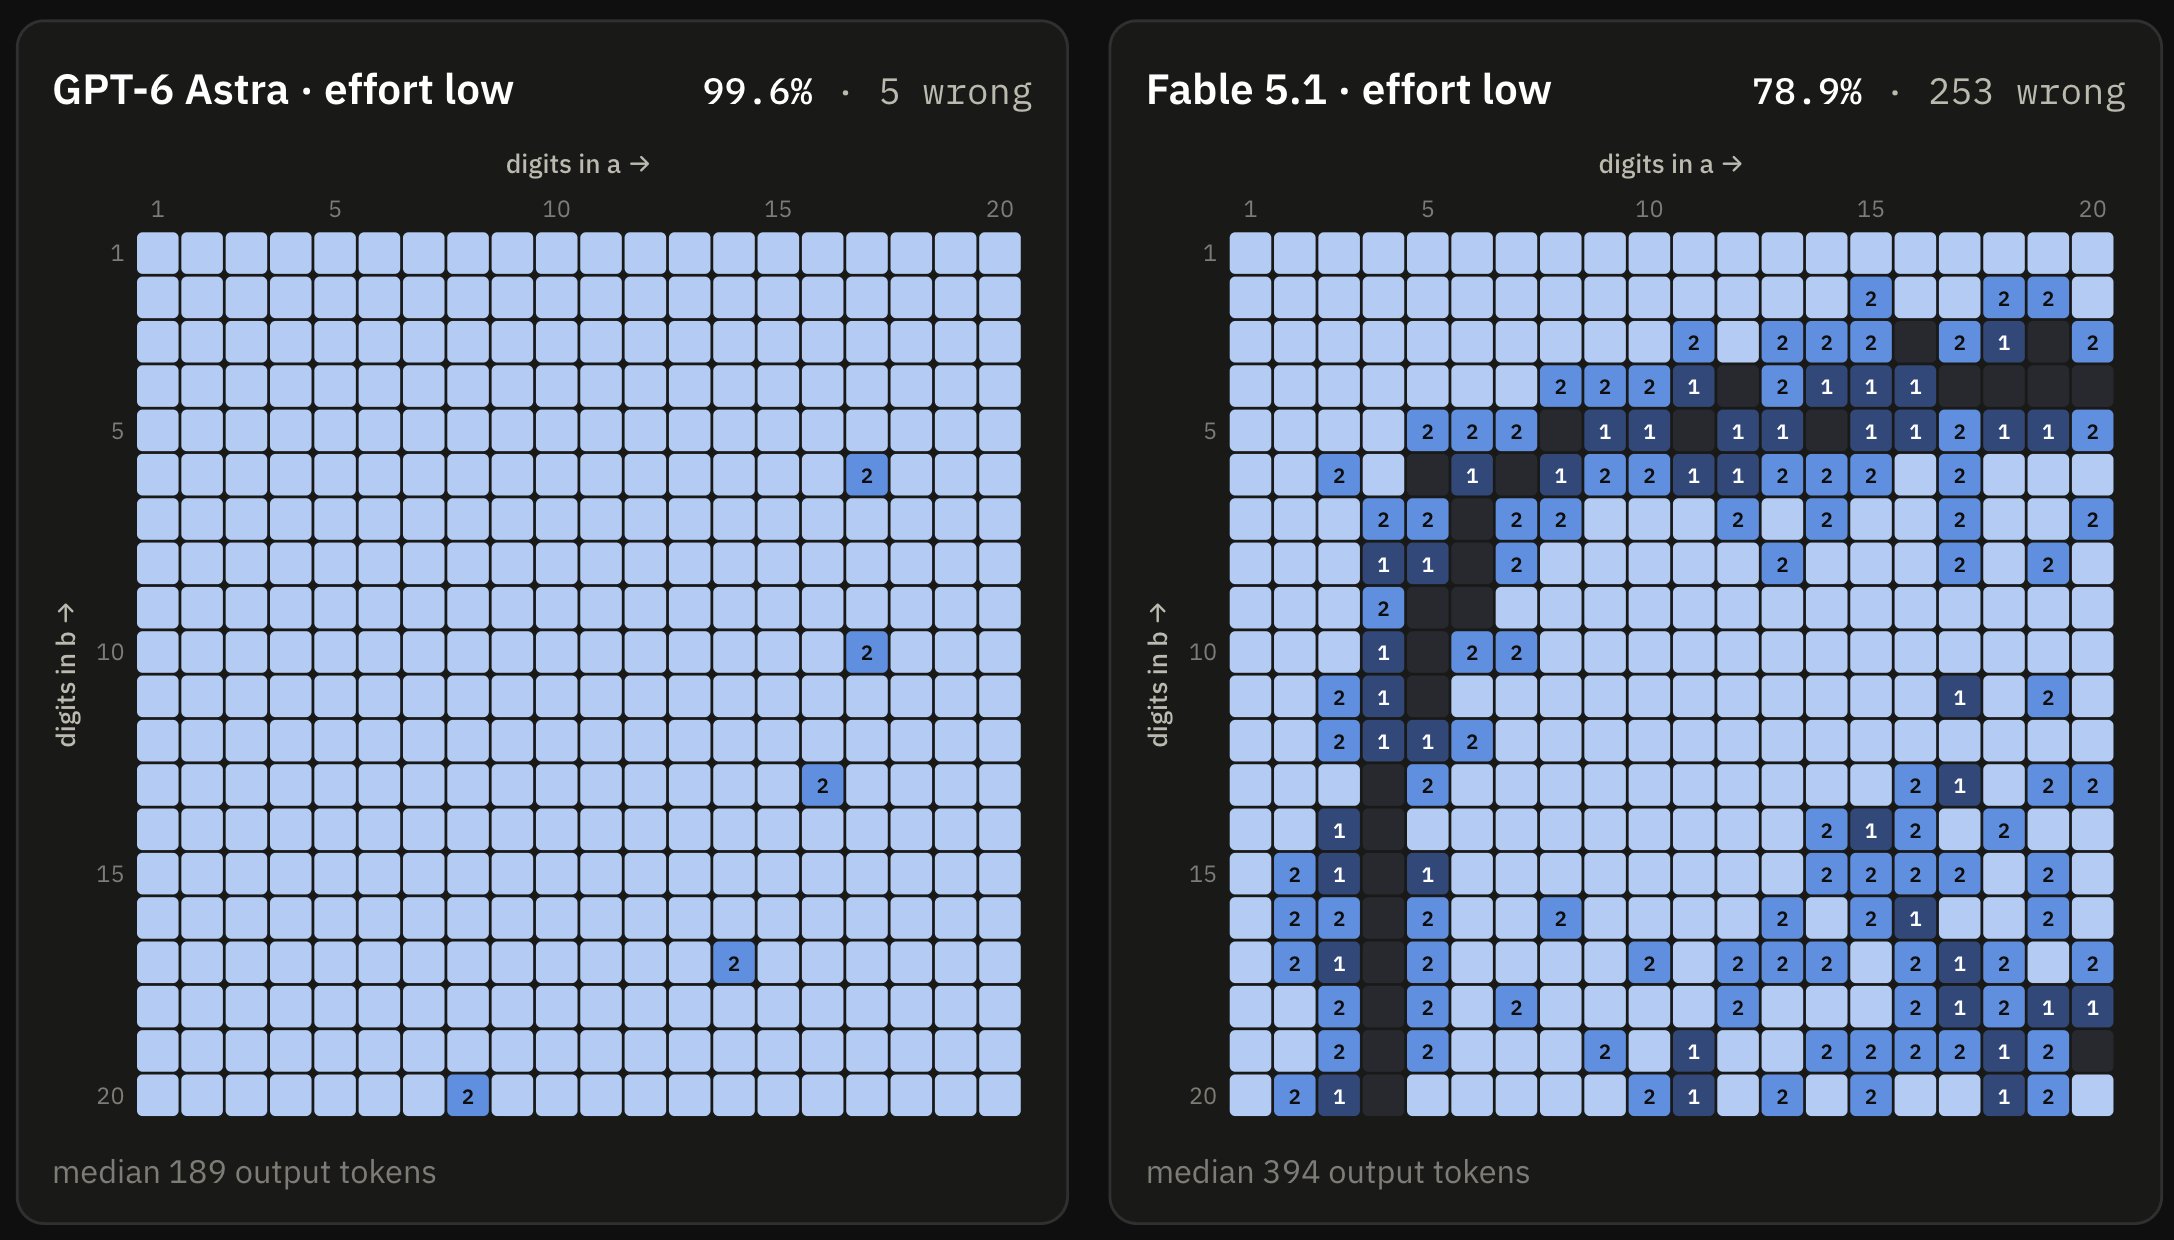
💥 The multiplication saga continues! It turns out, some frontier LLMs do struggle with simple multiplications. Unlike GPT-6-Astra, Fable 5.1 with low reasoning has a blind spot where the accuracy of, say, 5x6 multiplications drops to ~0%! The failure mode is very interesting: the 0% zone corresponds to a failure of adaptive thinking. The model decides that it shouldn't produce any reasoning and outputs the (wrong) answer directly. For larger multiplications, however, the model realizes it should produce a CoT first and then it gets the answer correctly. For very large multiplications (close to 20x20), the accuracy degrades again. How many such simple blind spots do frontier LLMs still have? This is why slowing down and carefully studying generalization and safety is the top priority... 1/2