OpenAI changed Astra benchmark results around launch, Fortune reports
During the delayed Astra launch blog, the reported hallucination rate went from 4.2% to 2% and back, and Fable 5.1's FrontierMath score also moved; OpenAI says the delay was unrelated to benchmarks.
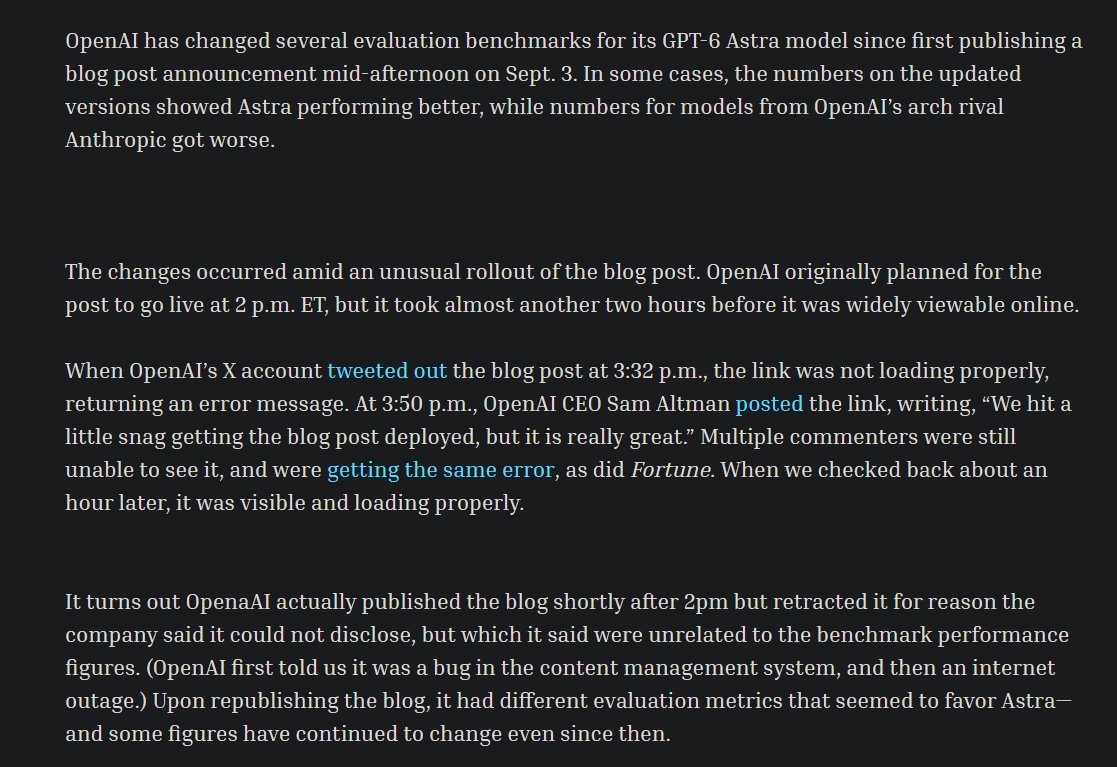
Interesting report from FORTUNE: @OpenAI quietly changed several GPT-6 Astra benchmark results around the model's launch, with some changes making Astra look better and competing models worse. One of the biggest examples: Astra's reported hallucination rate went from 4.2% to 2%, before later being changed back to 4.2%. Anthropic Fable 5.1's FrontierMath score also moved from 87.8% to 78%, then back up to 83%. This happened during the strange delay of the Astra launch blog, which was initially published, pulled, and then republished with different numbers. OpenAI says the delay was unrelated to the benchmarks and that eval results can shift depending on the exact checkpoint, harness and reasoning configuration.