Jev 1.14 adds image input, Box bounding boxes and 262k context
TypeSafe released Jev 1.14, letting images be listed once in an assets map and referenced anywhere, adding a Box type that returns a single bounding box, and supporting a 262k-token context at unchanged pricing.
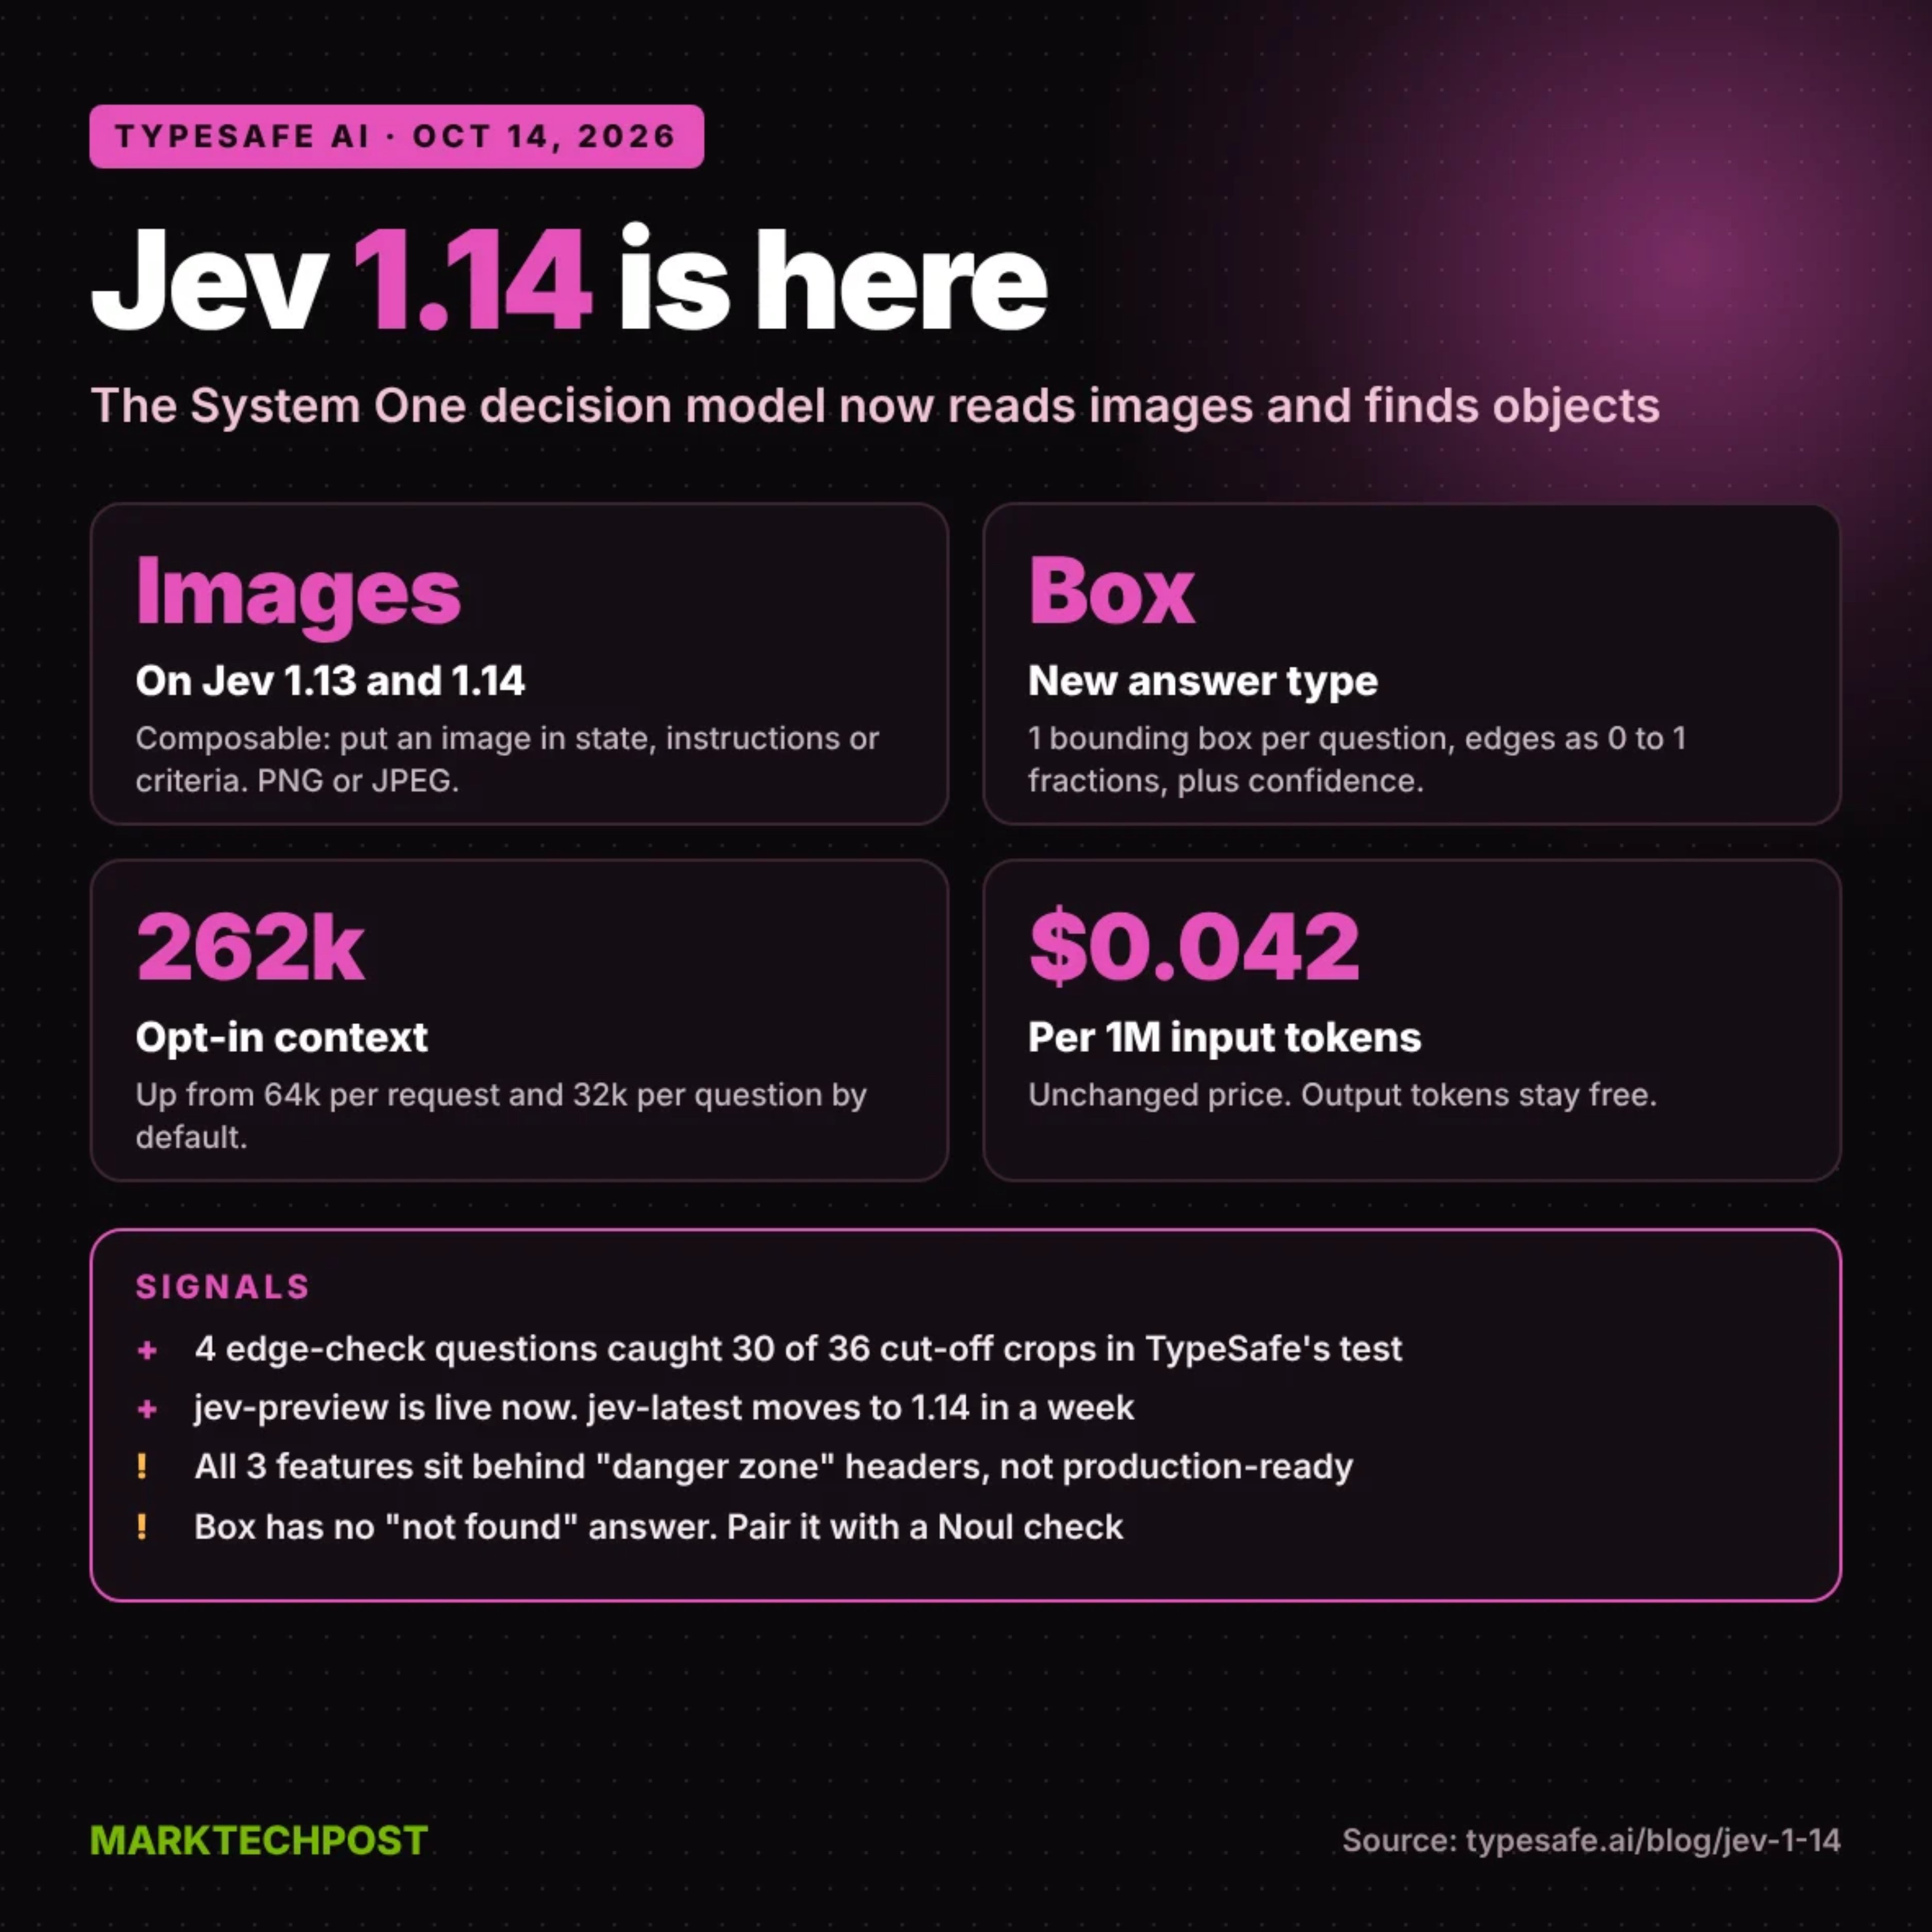
▲ TypeSafe AI just released Jev 1.14, pushing its System One decision model beyond text with image input, a new Box answer type and a 262k-token context mode. It is live now under the jev-preview alias. The core change is composable images. You list each image once in an assets map, then drop its reference anywhere in state, instructions or criteria. Surprise: Jev 1.13 was multimodal all along, and both versions now accept images. The new Box type returns a single bounding box per question, with edges as 0 to 1 fractions plus a confidence score. In TypeSafe’s own test, 4 per-edge check questions caught 30 of 36 cut-off crops. The trade-off is clear, though. All 3 features sit behind “danger zone” headers, images trail pure text on accuracy, and Box has no “not found” answer. With pricing unchanged at $0.042 per million input tokens and free output, it is built for cheap, high-volume visual decisions inside software...... Full analysis: https://www.marktechpost.com/2026/10/14/typesafe-ai-jev-1-14-images-box-long-context/ Blog: http://typesafe.ai/blog/jev-1-14 Docs: http://docs.typesafe.ai/models @typesafeai @CompleteSkeptic