Six frontier models on LIBERO-10: success rate vs API cost
Prompted by GPT-6 Astra robot demos, the authors zero-shot evaluate six GPT, Claude and Gemini models on LIBERO-10: best success rate is 44%, and more reasoning generally helps at varying cost.
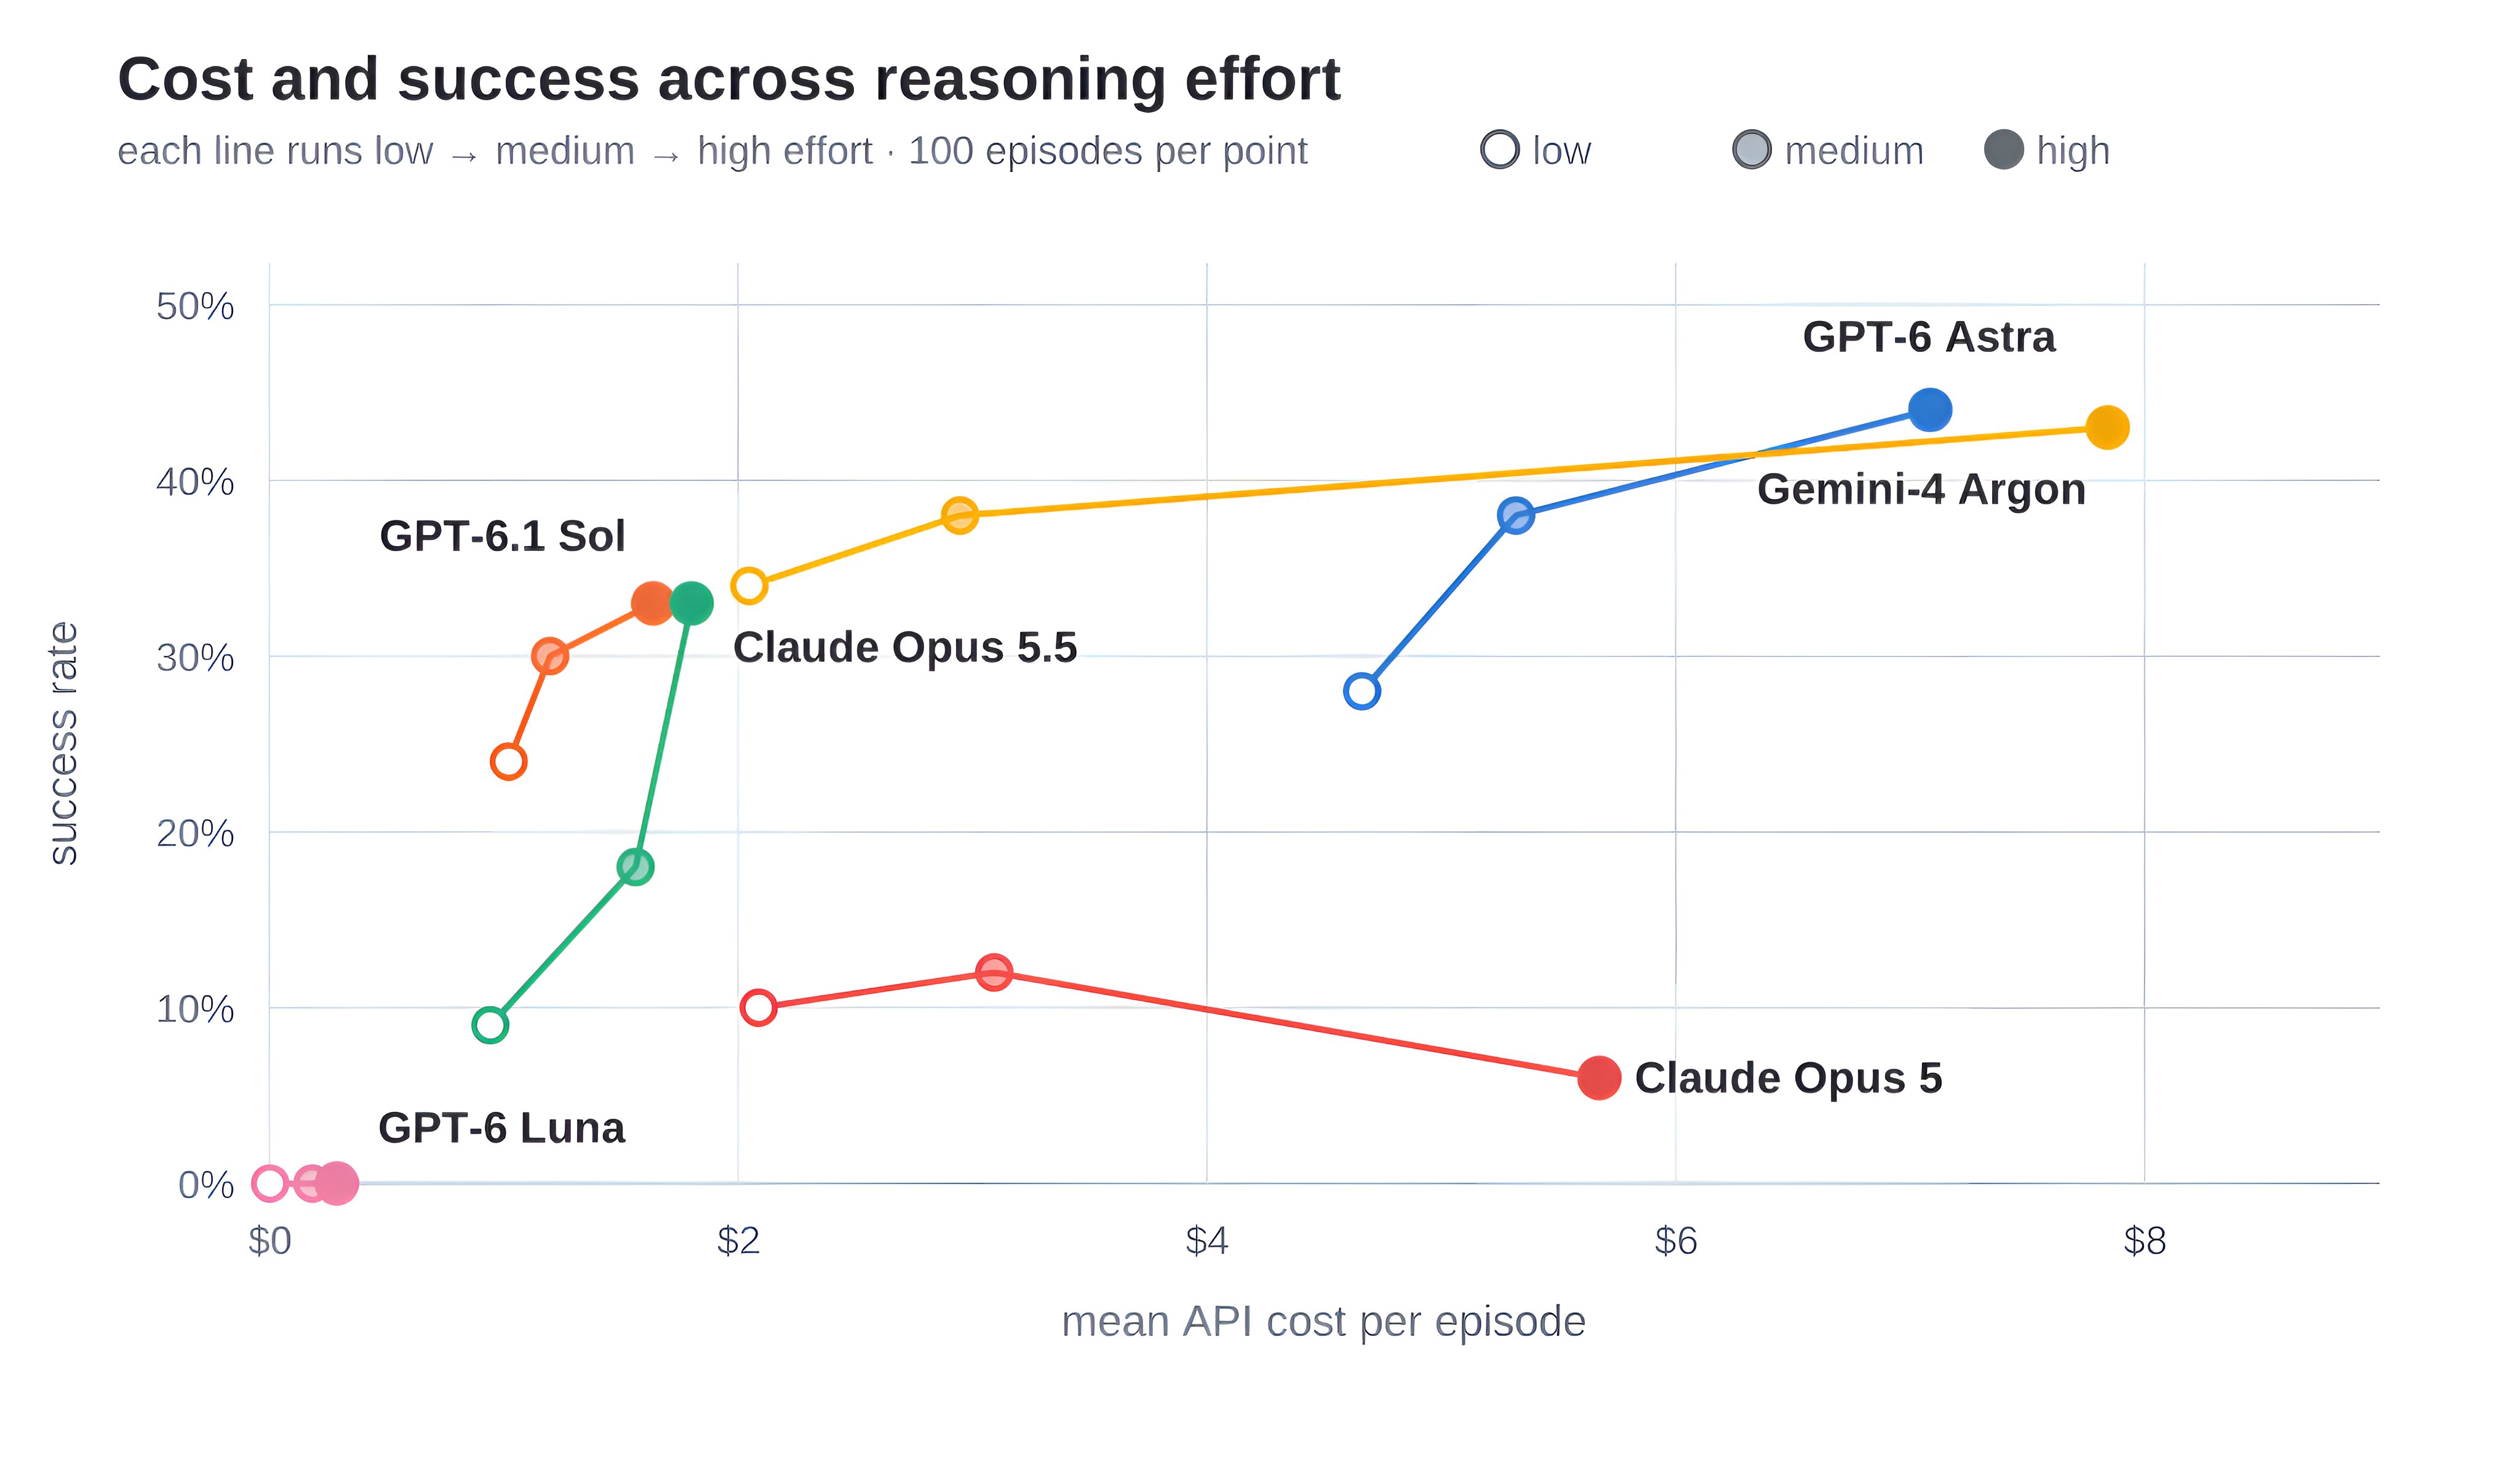
GPT-6 Astra has shown impressive robot manipulation capabilities in demo videos. But how well do frontier AI models perform on established robotics benchmarks? We evaluated 6 models from GPT, Claude, and Gemini on LIBERO-10 using the same control interface and evaluation protocol. 3 reasoning levels per model, 18 configurations, 1,800 episodes. All zero-shot, without task-specific training! The best success rate is 44%. More reasoning generally helps, but the cost varies significantly across models. Here's the success rate vs. API cost comparison! 👇 1/6 ➡️ (Links at the end)