Models with similar scores differ 7x in output tokens per task, Gemini 4 Argon at about 60K
Artificial Analysis data cited by Merge shows GPT-6 Astra scoring 52.7 on 27K output tokens while Claude Sonnet 5.5 scores 56.0 on 197K, with Gemini 4 Argon in the 60K-64K range.
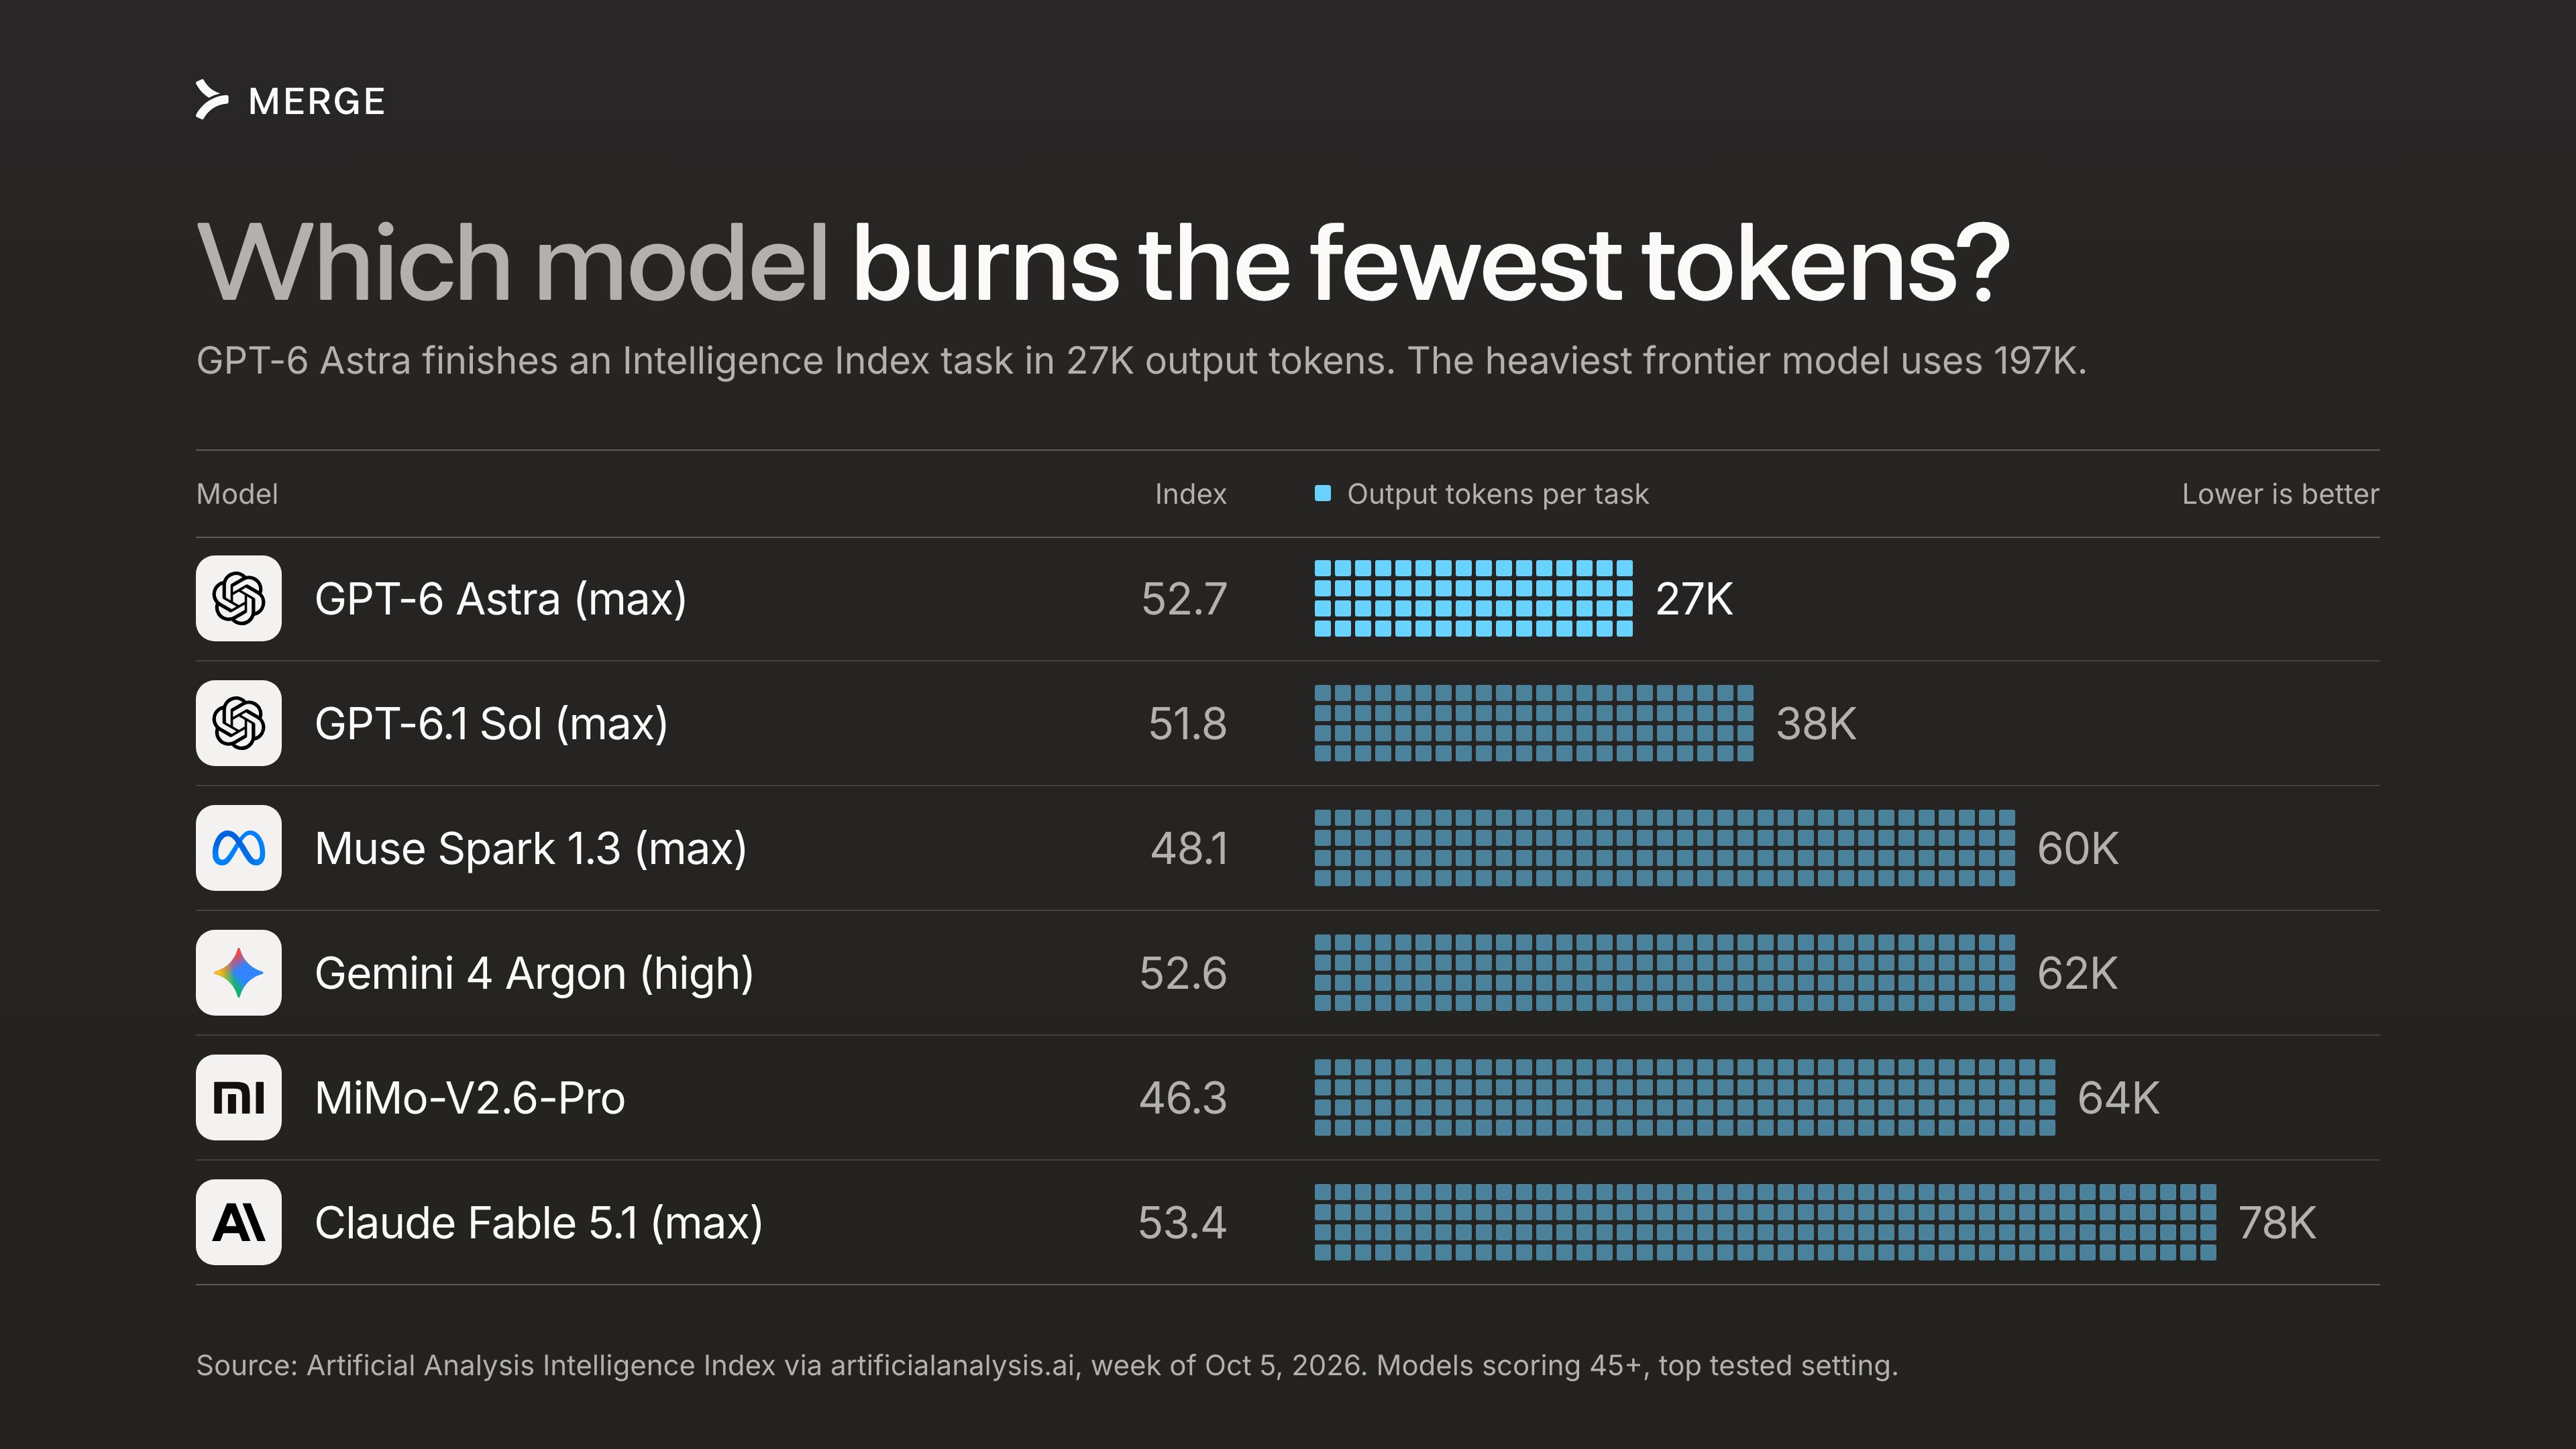
Two frontier models a few points apart on the Intelligence Index can differ 7x in the tokens they burn per task. GPT-6 Astra (@OpenAI) scores 52.7 and finishes an average Artificial Analysis Intelligence Index task in 27K output tokens. Claude Sonnet 5.5 scores 56.0 and uses 197K. GPT-6.1 Sol comes in at 38K, while Muse Spark 1.3, Gemini 4 Argon and MiMo-V2.6-Pro all land between 60K and 64K. Output tokens are what you pay for. Sending simple requests to a leaner model is one of the easiest ways to cut inference spend, and Merge Gateway routes them for you. Scores via http://artificialanalysis.ai, week of Oct 5.