Gemini 4 Argon early benchmarks: leads 13 of 19 tests
Rolled out to trusted testers through the Fairwind Program, Gemini 4 Argon scores 65.4% on the finance agent benchmark against GPT-6 Astra's 53.5%, but still trails on software and terminal tasks.
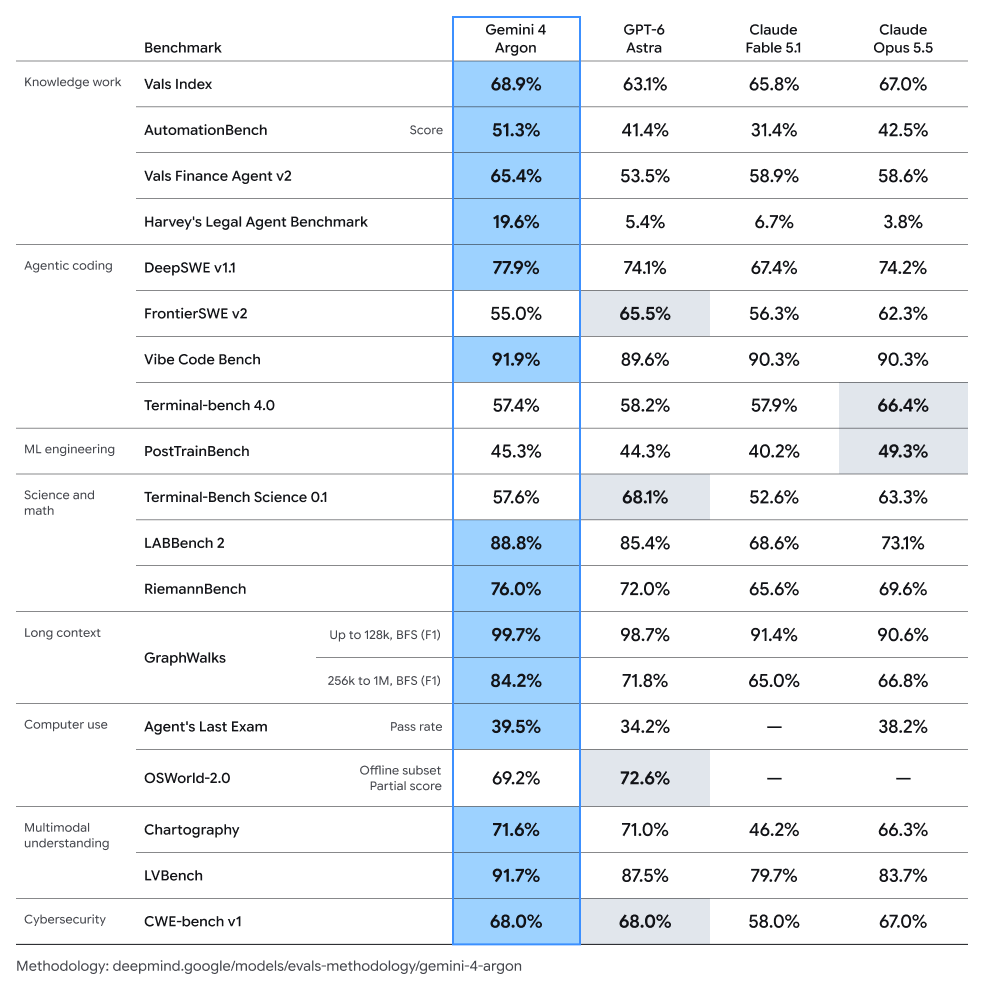
GOOGLE IS BACK IN THE AI RACE. Google DeepMind just introduced Gemini 4 Argon, a frontier model built for complex workflows across coding, enterprise knowledge work, science and cybersecurity. It is initially rolling out to trusted testers through Google’s Fairwind Program rather than launching broadly today but the early benchmarks look extremely strong. Argon leads outright on 13 of the 19 listed tests, ties for first on cybersecurity and trails on only five and some of its largest advantages are in areas businesses will actually pay for. It scores 65.4% on the finance agent benchmark versus 53.5% for GPT 6 Astra and it also scores 19.6% on Harvey’s legal agent benchmark, compared with 5.4% for GPT 6. Google does not win everything. GPT 6 leads several software, science and computer use benchmarks, while Claude Opus leads Terminal-Bench and PostTrainBench and Argon is not universally superior, but it appears unusually balanced across many workloads. That matters because the AI race is moving beyond chatbots toward agents that can complete real work. Google also has a distribution advantage that OpenAI and Anthropic cannot easily match because it can place Gemini across Search, Workspace, Android, YouTube and Google Cloud while using its own TPUs and data center infrastructure. If Argon’s real world performance matches these early results, Google could control the model, chips, cloud infrastructure and distribution inside one ecosystem.
This post quotes another post: “Pichai gives early look at Gemini 4 Argon and its benchmarks”