Ling-3.1-flash: open-weight 560B MoE agent model with 1M context
Ant's Ling-3.1-flash is released with open weights: a 560B MoE model activating about 25B parameters per token, supporting up to 1M context and aimed at long-running agents and tool calling.
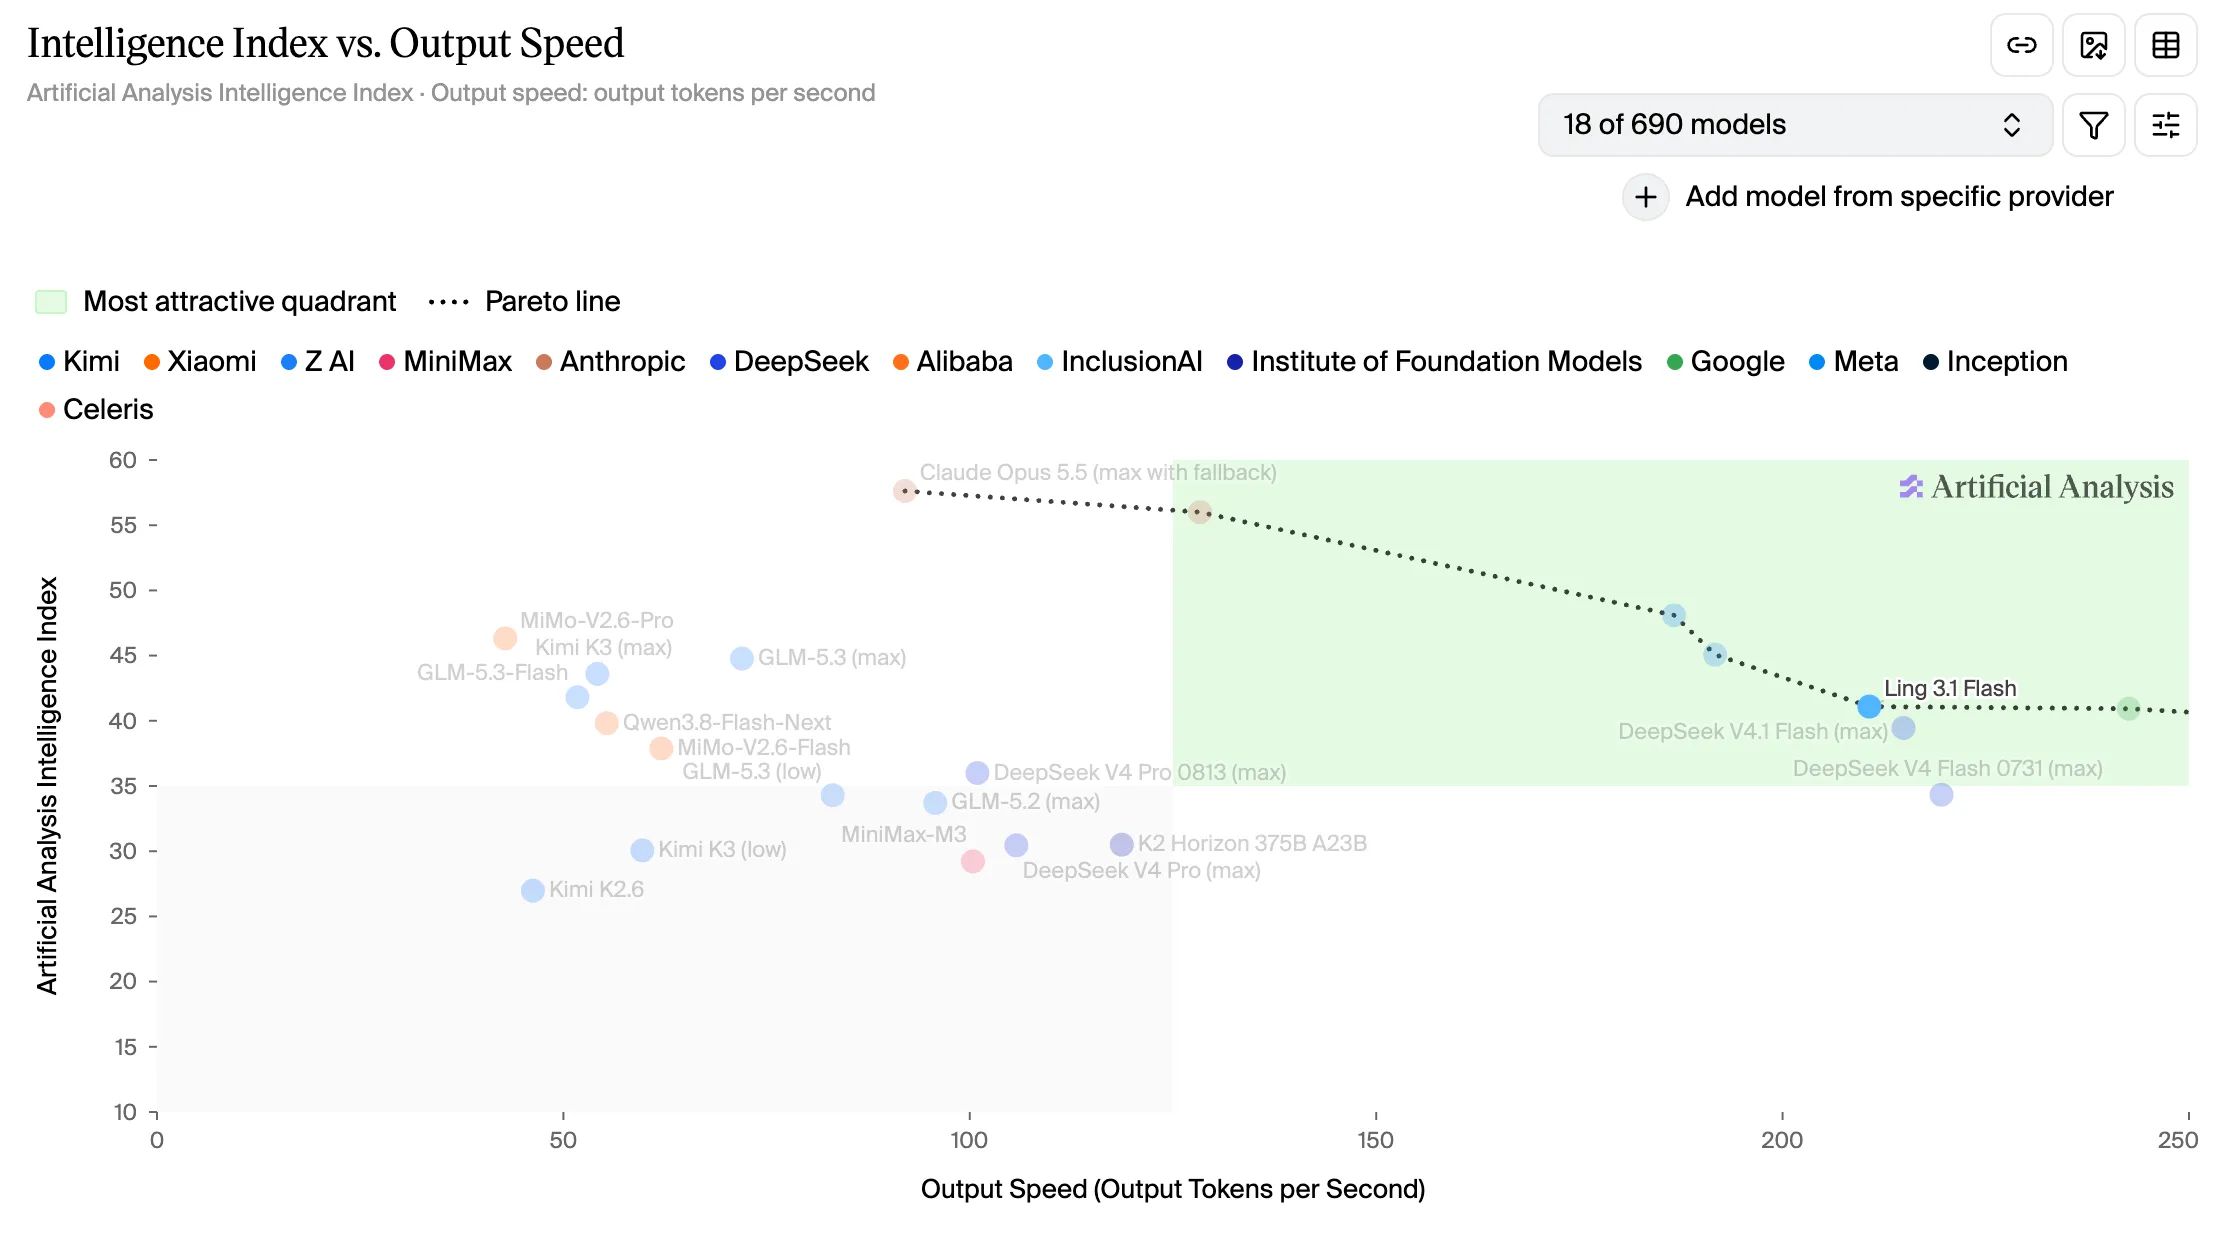
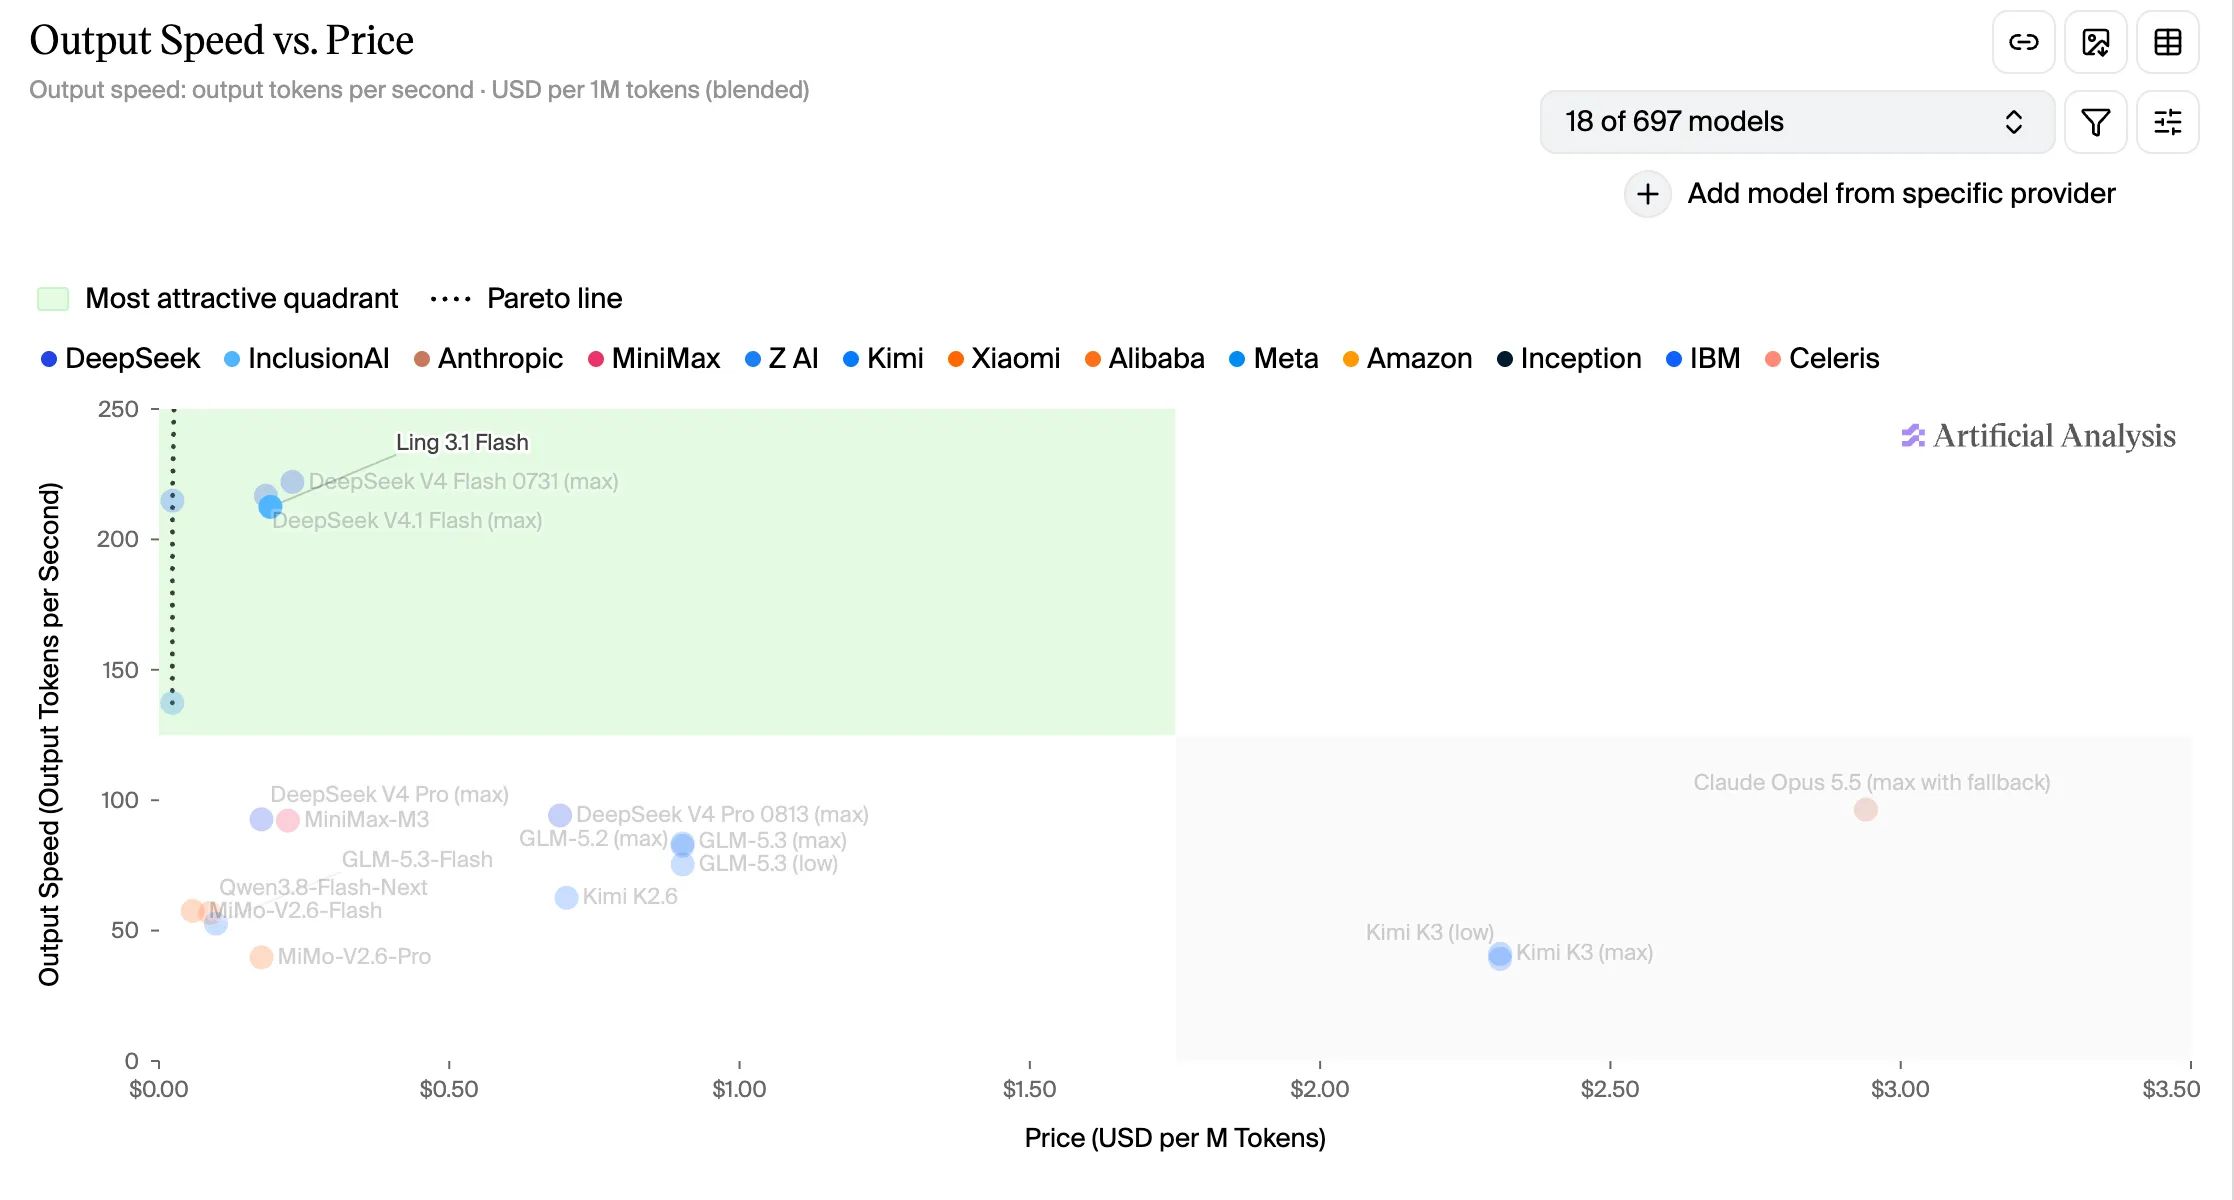
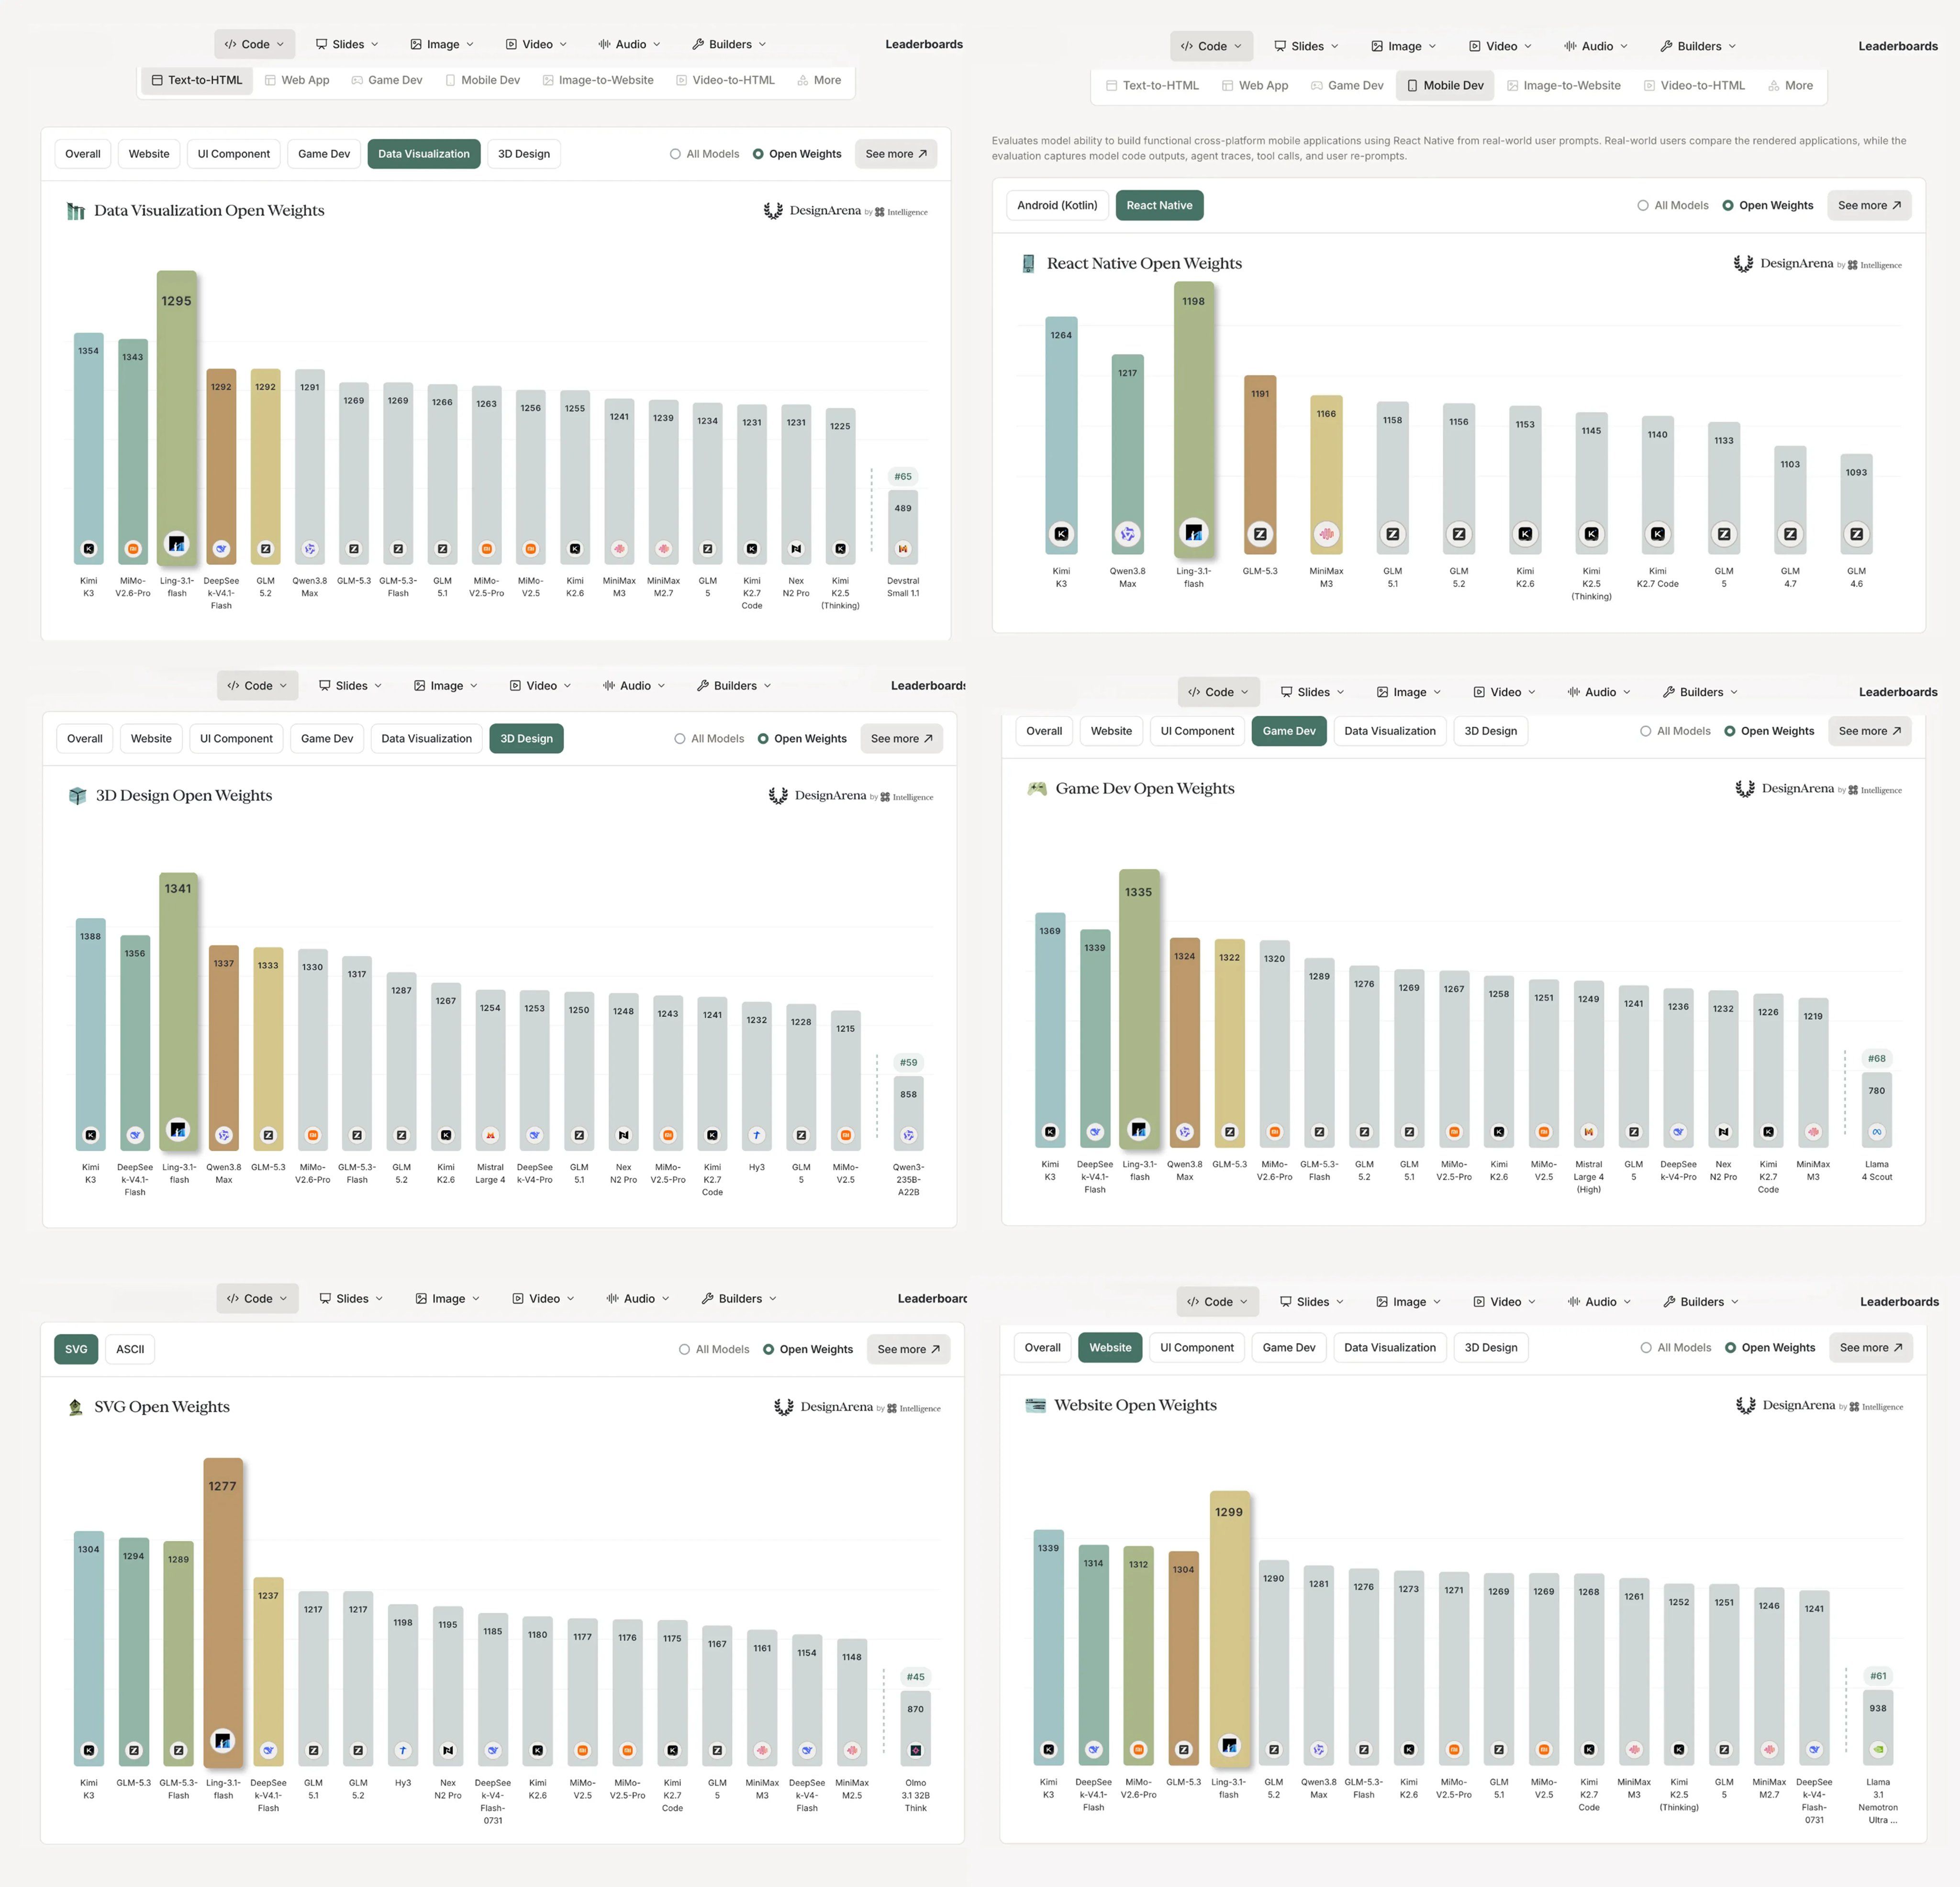
Ling-3.1-flash is now available with open weights: a 560B MoE agent model activating around 25B parameters per token, with support for up to 1M context. 🤖 https://modelscope.ai/models/inclusionAI/Ling-3.1-flash 🏆 Strong agent benchmarks: Leads the reported HealthBench Professional and FrontierSWE comparisons, and ranks second on GDPval-AA v2.1 among the models shown. ⚡ Fast and capable: Scores 41 on the Artificial Analysis Intelligence Index while generating around 210 tokens/s, placing it on the reported intelligence–speed Pareto frontier. 🎨 From prompts to working outputs: Ranks among the top open-weight models in Design Arena for data visualization, React Native, 3D, game development, SVG, and websites. 📦 Easier to deploy: MXFP4 mixed precision reduces the model footprint from around 534GB to 292GB and cuts the tested server setup from 8 accelerators to 4. 🧠 Built for long-running agents: Maintains goals, tool history, and intermediate results across hours-long workflows, with stronger JSON Schema tool calling for production integration. The hosted API currently supports 256K context; the open model supports configurations up to 1M.