VulcanBench results for five OpenAI models across all effort levels
The author finished running an engineering-task benchmark on five OpenAI models at every reasoning effort level, concluding that effort level does not affect code quality, Terra Max matches Astra at half the price, and GPT-5.5 is no longer necessary.
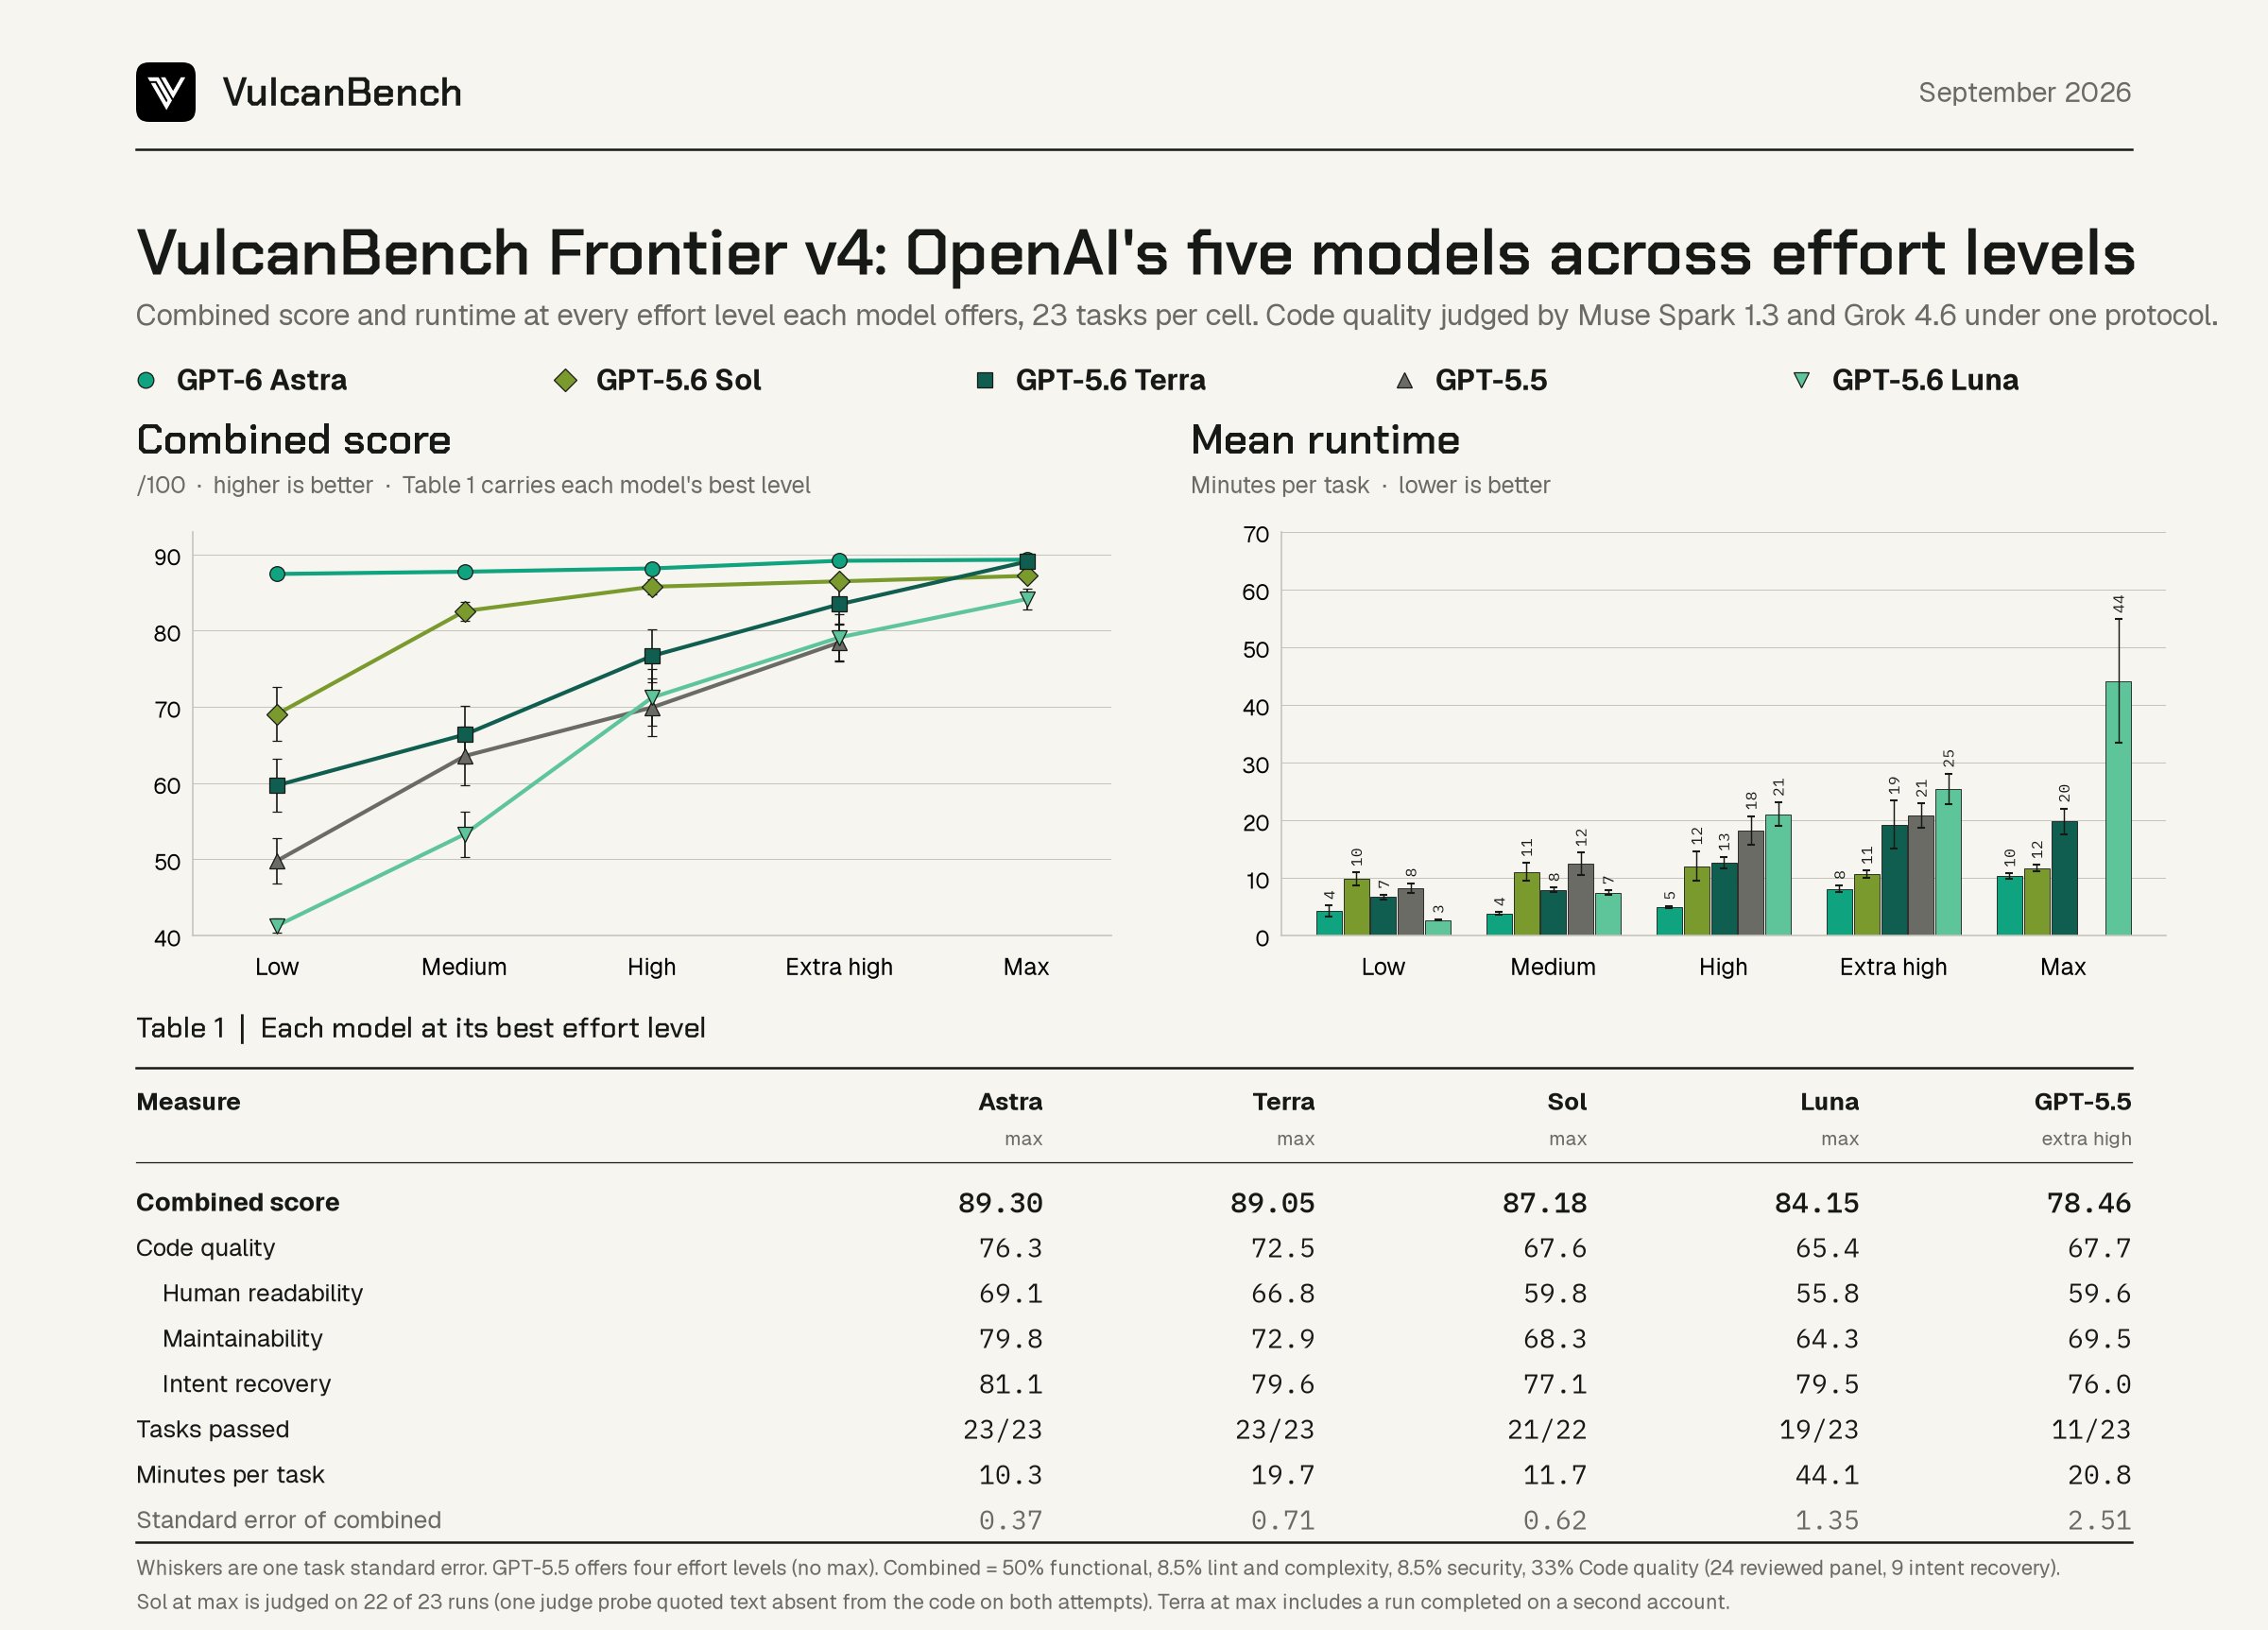
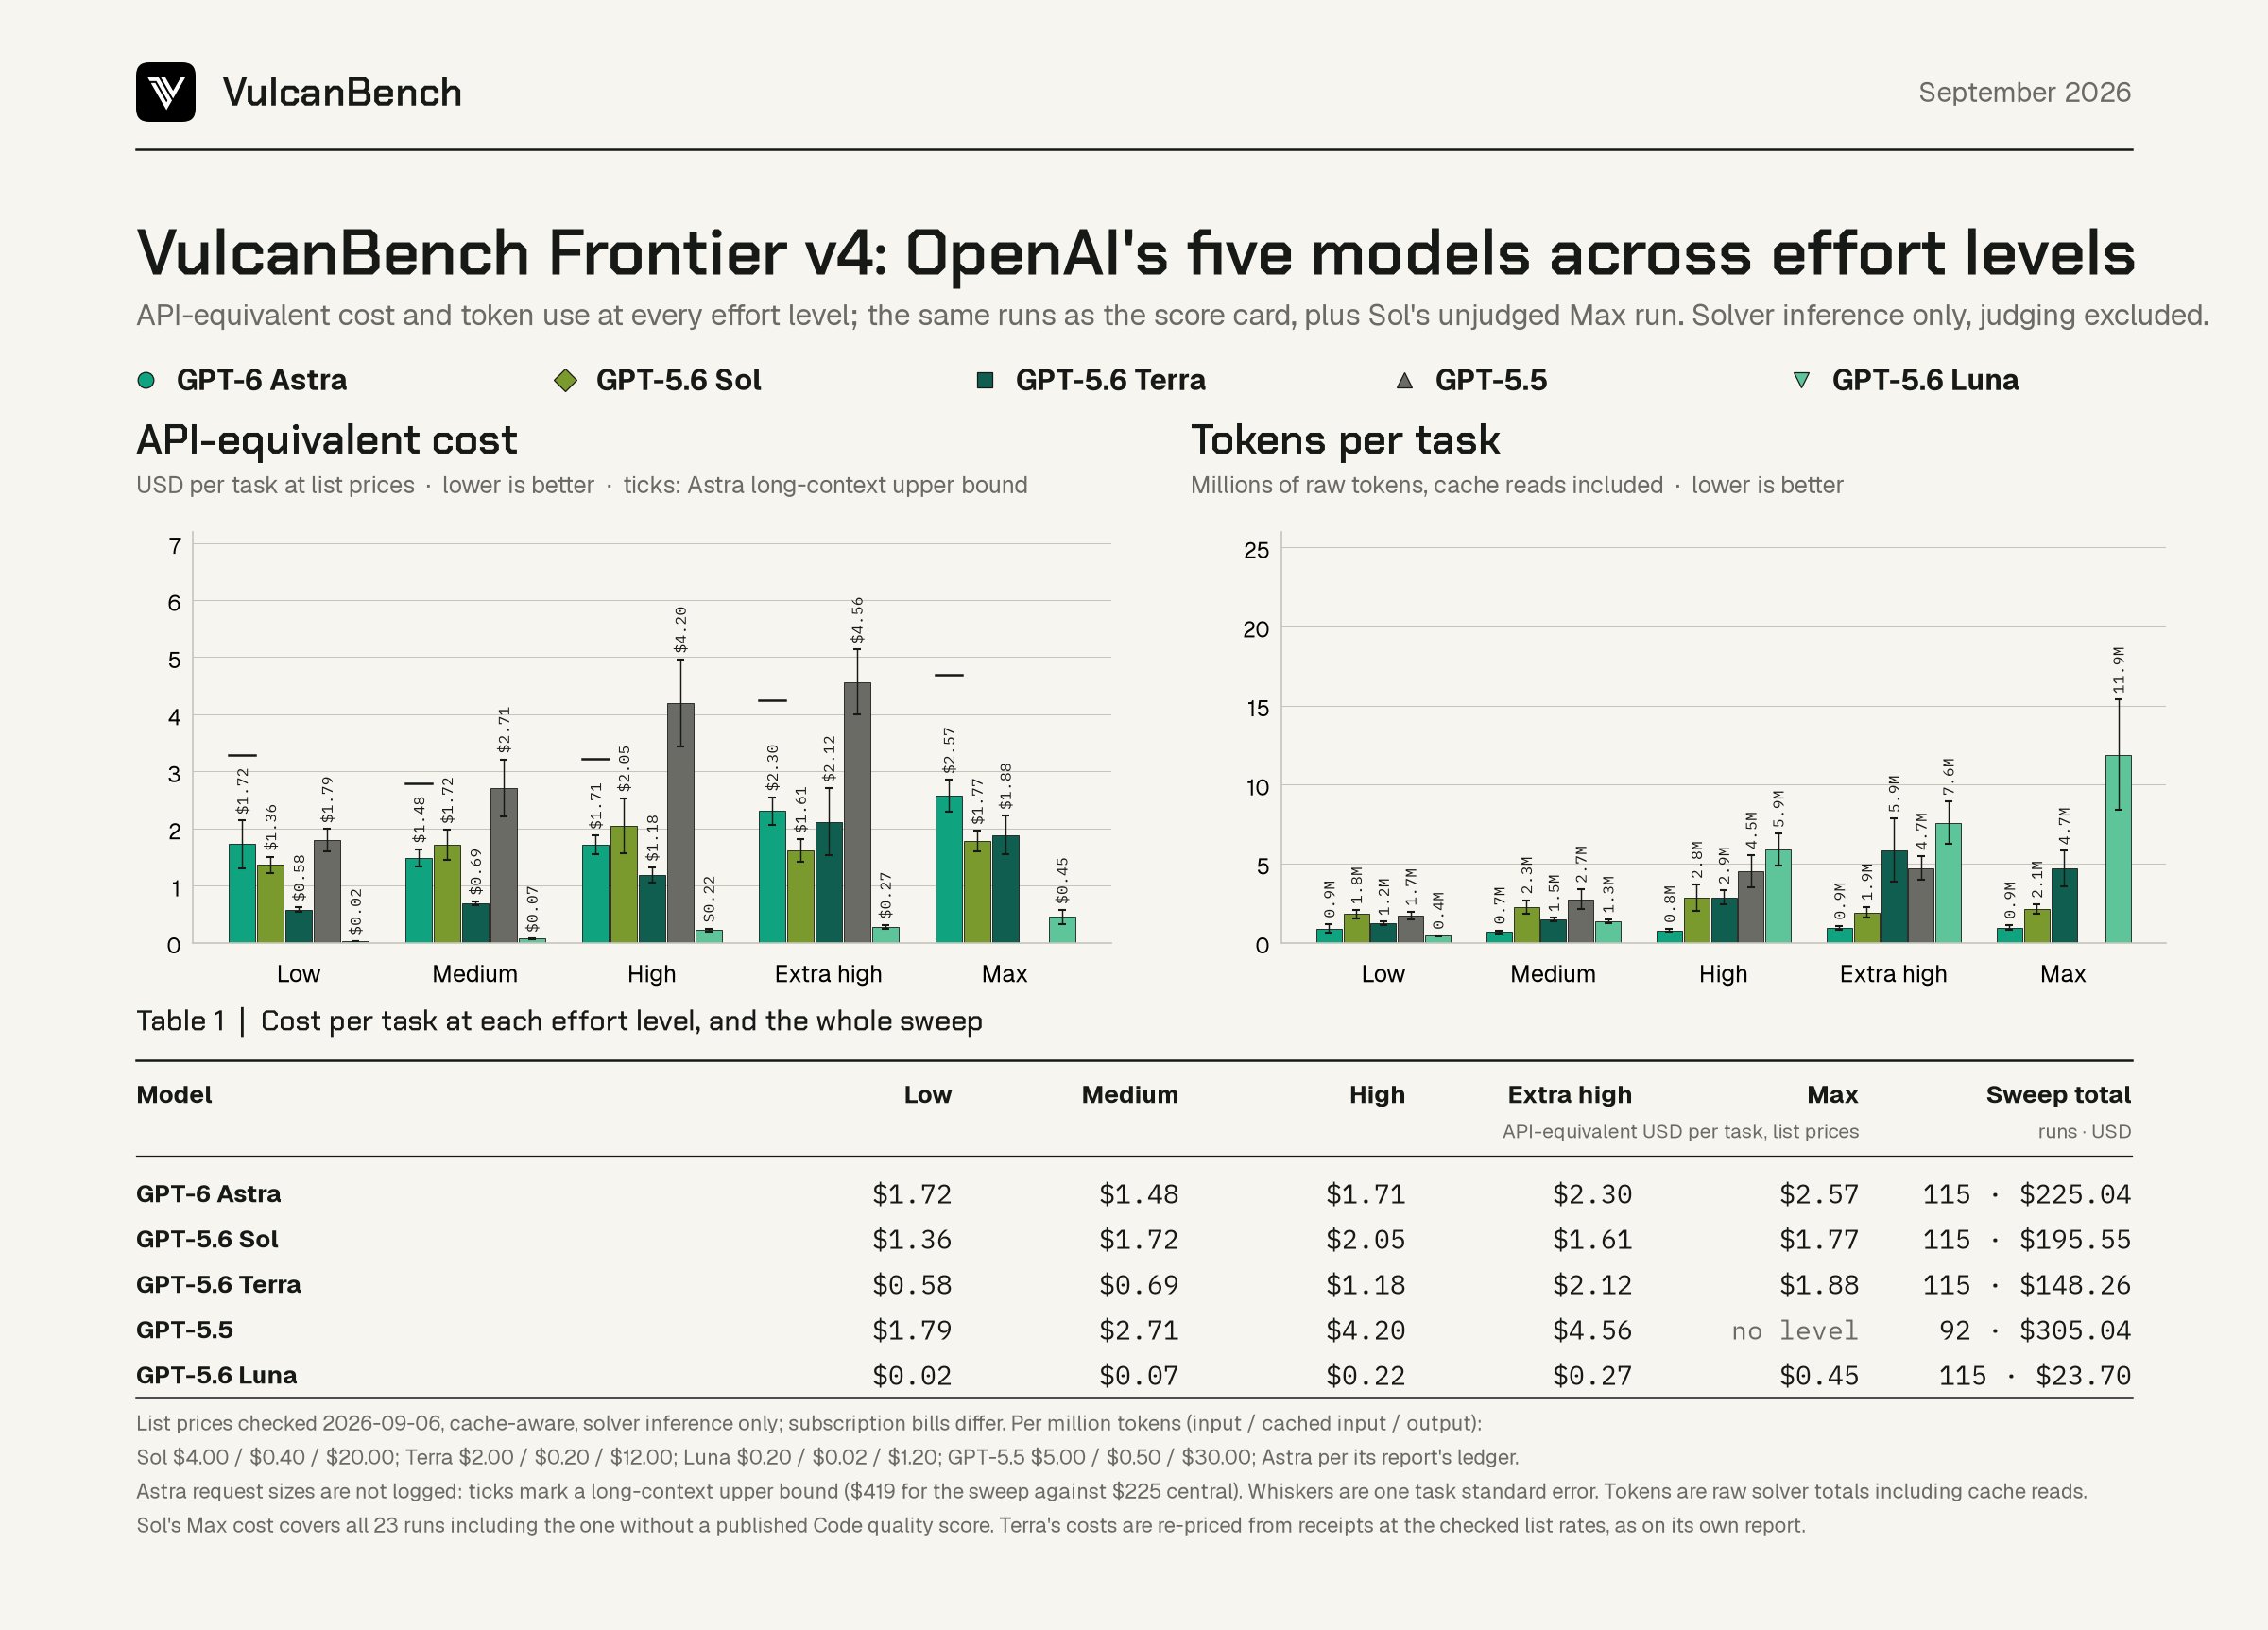
Okay, woke up this morning and my Sol benchmark was finished, so I have now completed my full run, on the five core OpenAI models available today, across all effort levels. Through this process as I shared a bit last week, I also decided to create a third eval suite, focused on routine engineering tasks. This current suite, which I'm now calling VulcanBench Frontier, is really, most likely, harder tasks that regular engineers on engineering teams are giving models on a normal day. What I'm testing with this eval suite is how these models do with hard stuff, things you might give a model, but not likely on a daily basis. Which means I would look at these results as providing signal for what model/effort to use for your hardest tasks. Also as a quick reminder, or heads up for those just joining me here. With this v4 eval suite I also included a code quality scoring system that uses both Muse and Grok to score the code quality and include this as 33% of the score. I think code quality output for models is going to matter more and more over time, not because models need to write good code for humans, but because models need to write code other agents can understand and work on too. As for key insights I got from this, here's three: 1. Increasing effort level does not seem to impact code quality. So anyone thinking Low effort writes crappy code and Max writes beautiful code, that doesn't seem to be the case. Low and Max in pretty much every OpenAI model writes the same quality code. 2. Terra Max matches Astra at half the price. I'll just leave that here 👀 3. You never need to use GPT 5.5, and if you are, in any workflows, stop, you're wasting money. Comparison model cards below, and if you want to see detailed reports on each specific model run, you can find those here: https://vulcanbench.com/benchmarks.html