Muse Wonder Full benchmark: much slower than GPT-6 Astra
Combined VulcanBench scores show Muse Wonder Full's medium effort as the sweet spot, but it runs far slower than Opus 5.5, GPT-6.1 Sol and GPT-6 Astra, so the poster prefers the latter two.
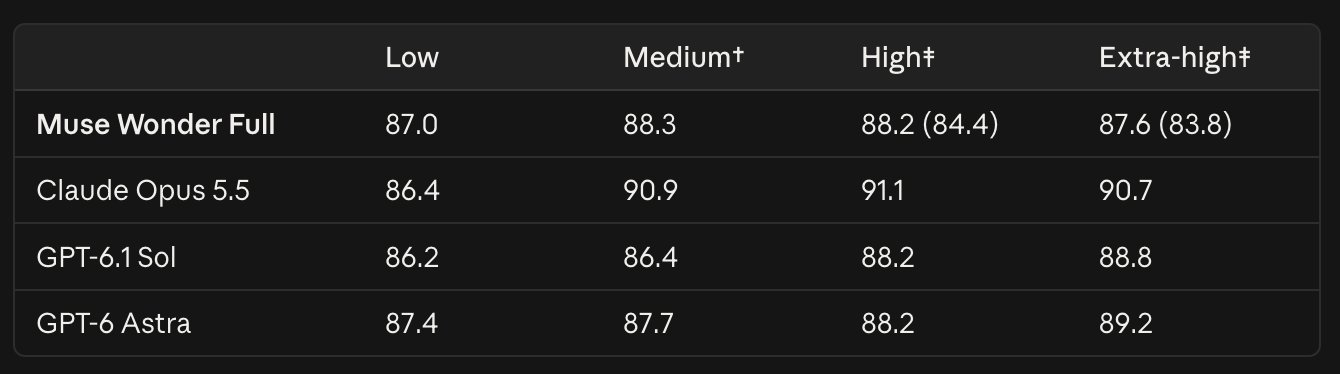
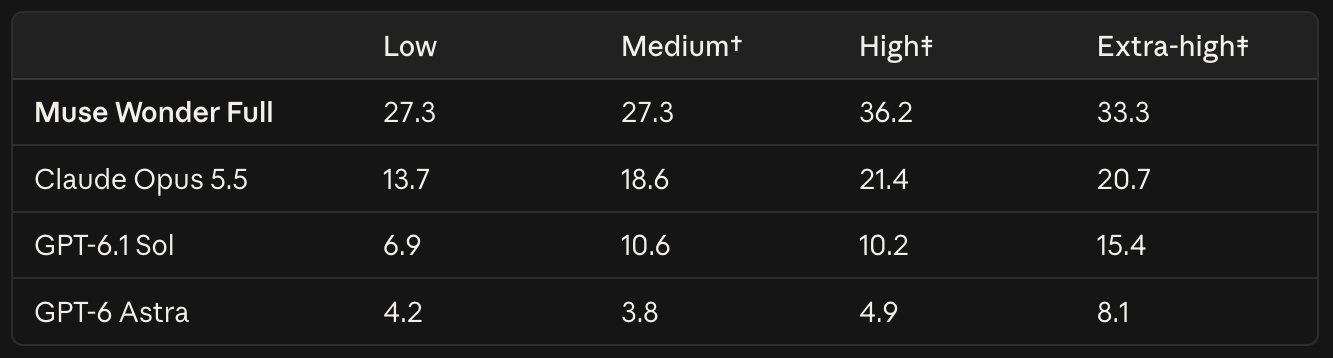
Okay my Muse Wonder Full benchmark is now complete with @VulcanBench - busy weekend so might not get to put all the data and model cards together until next week. But I wanted to share a quick peek at the combined score and how it compares to other models. The TL;DR is, with Muse Wonder Full, Medium effort seems to be the sweet spot, but, you need to take tokens-per-task and cost-per-task into account when deciding what model to use. In the two tables below, first is combined accuracy score, second is time per task. Right now Muse Wonder Full is quite a bit slower than Opus 5.5, much slower than GPT-6.1 Sol, and way slower than GPT-6 Astra. Overall, based on what I'm seeing, I would use Opus 5.5 or GPT-6.1 Sol over Muse Full at this point. You'll get the same or better accuracy faster and cheaper. More to come in model cards and deeper analysis on the site, but it's the weekend and I'm hanging with family more than doing benchmarks so might be a day or two. You should do the same! 🖖