Gemini 4 Argon vision test: bounding boxes plus HTML in one output
A developer tested Gemini 4 Argon for labeling image parts, getting bounding boxes and a viewing HTML in one output, and suggests pairing it with SAM3 in an agentic vision loop.
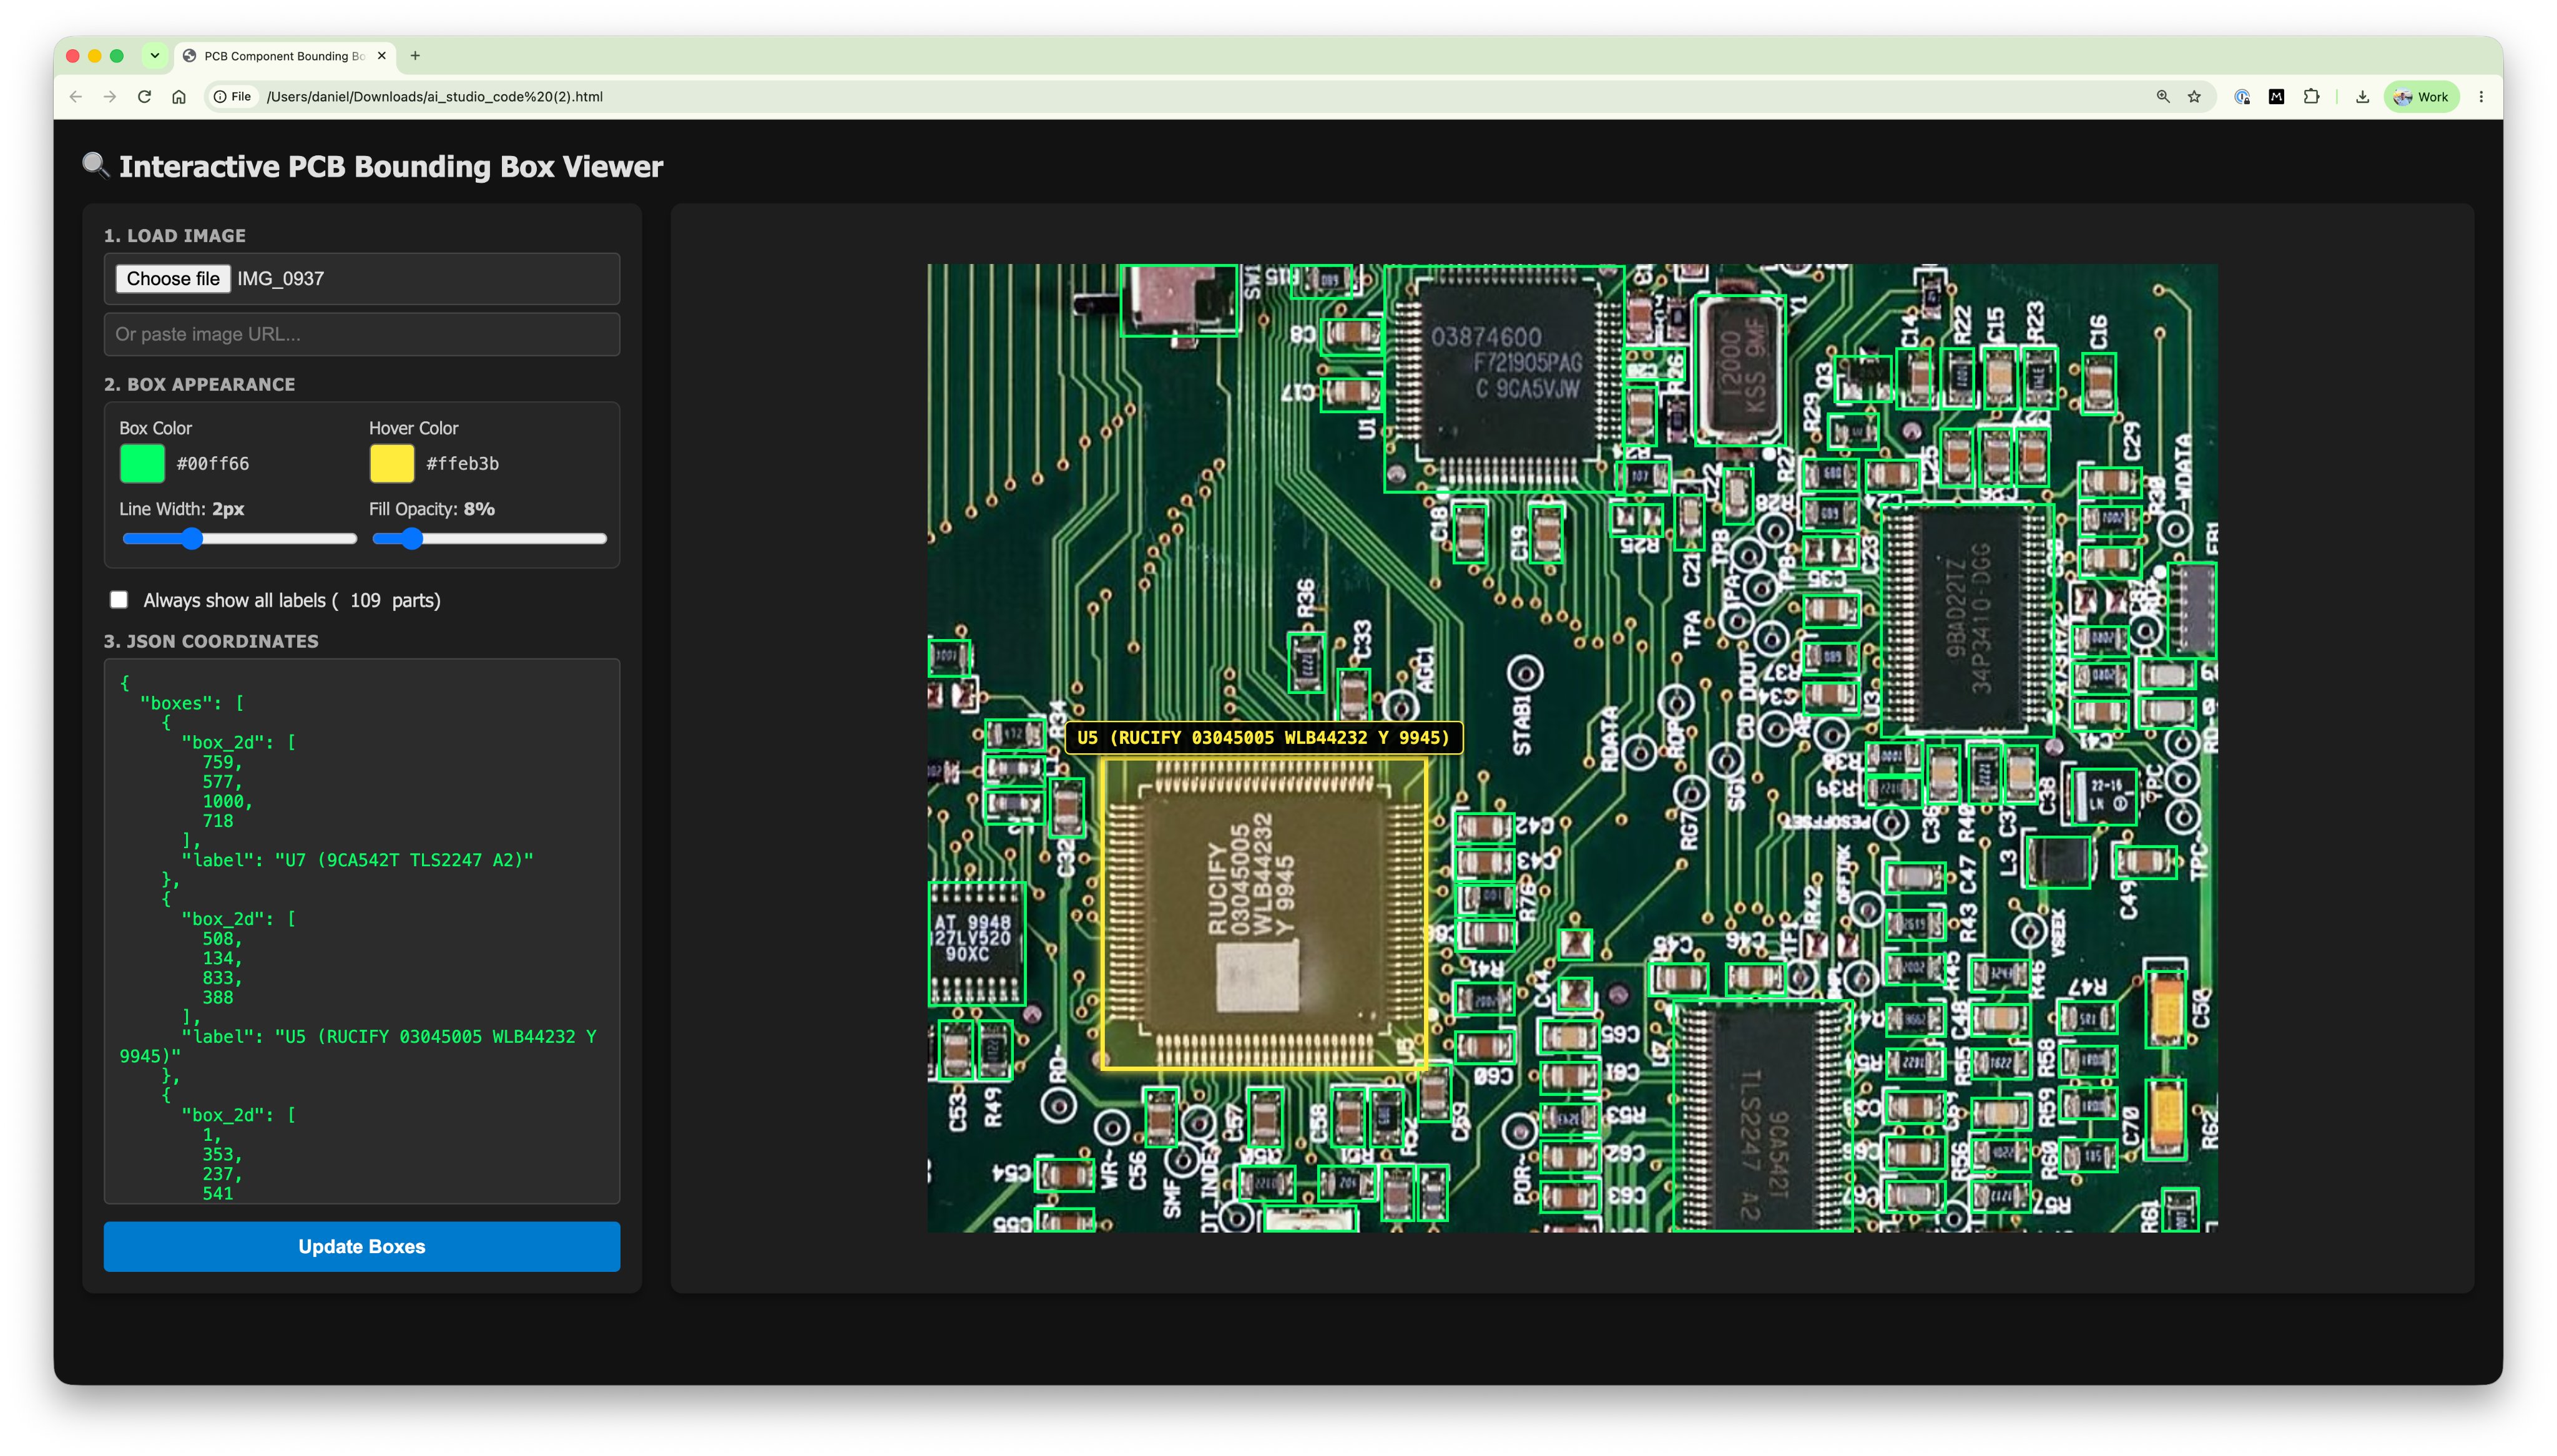
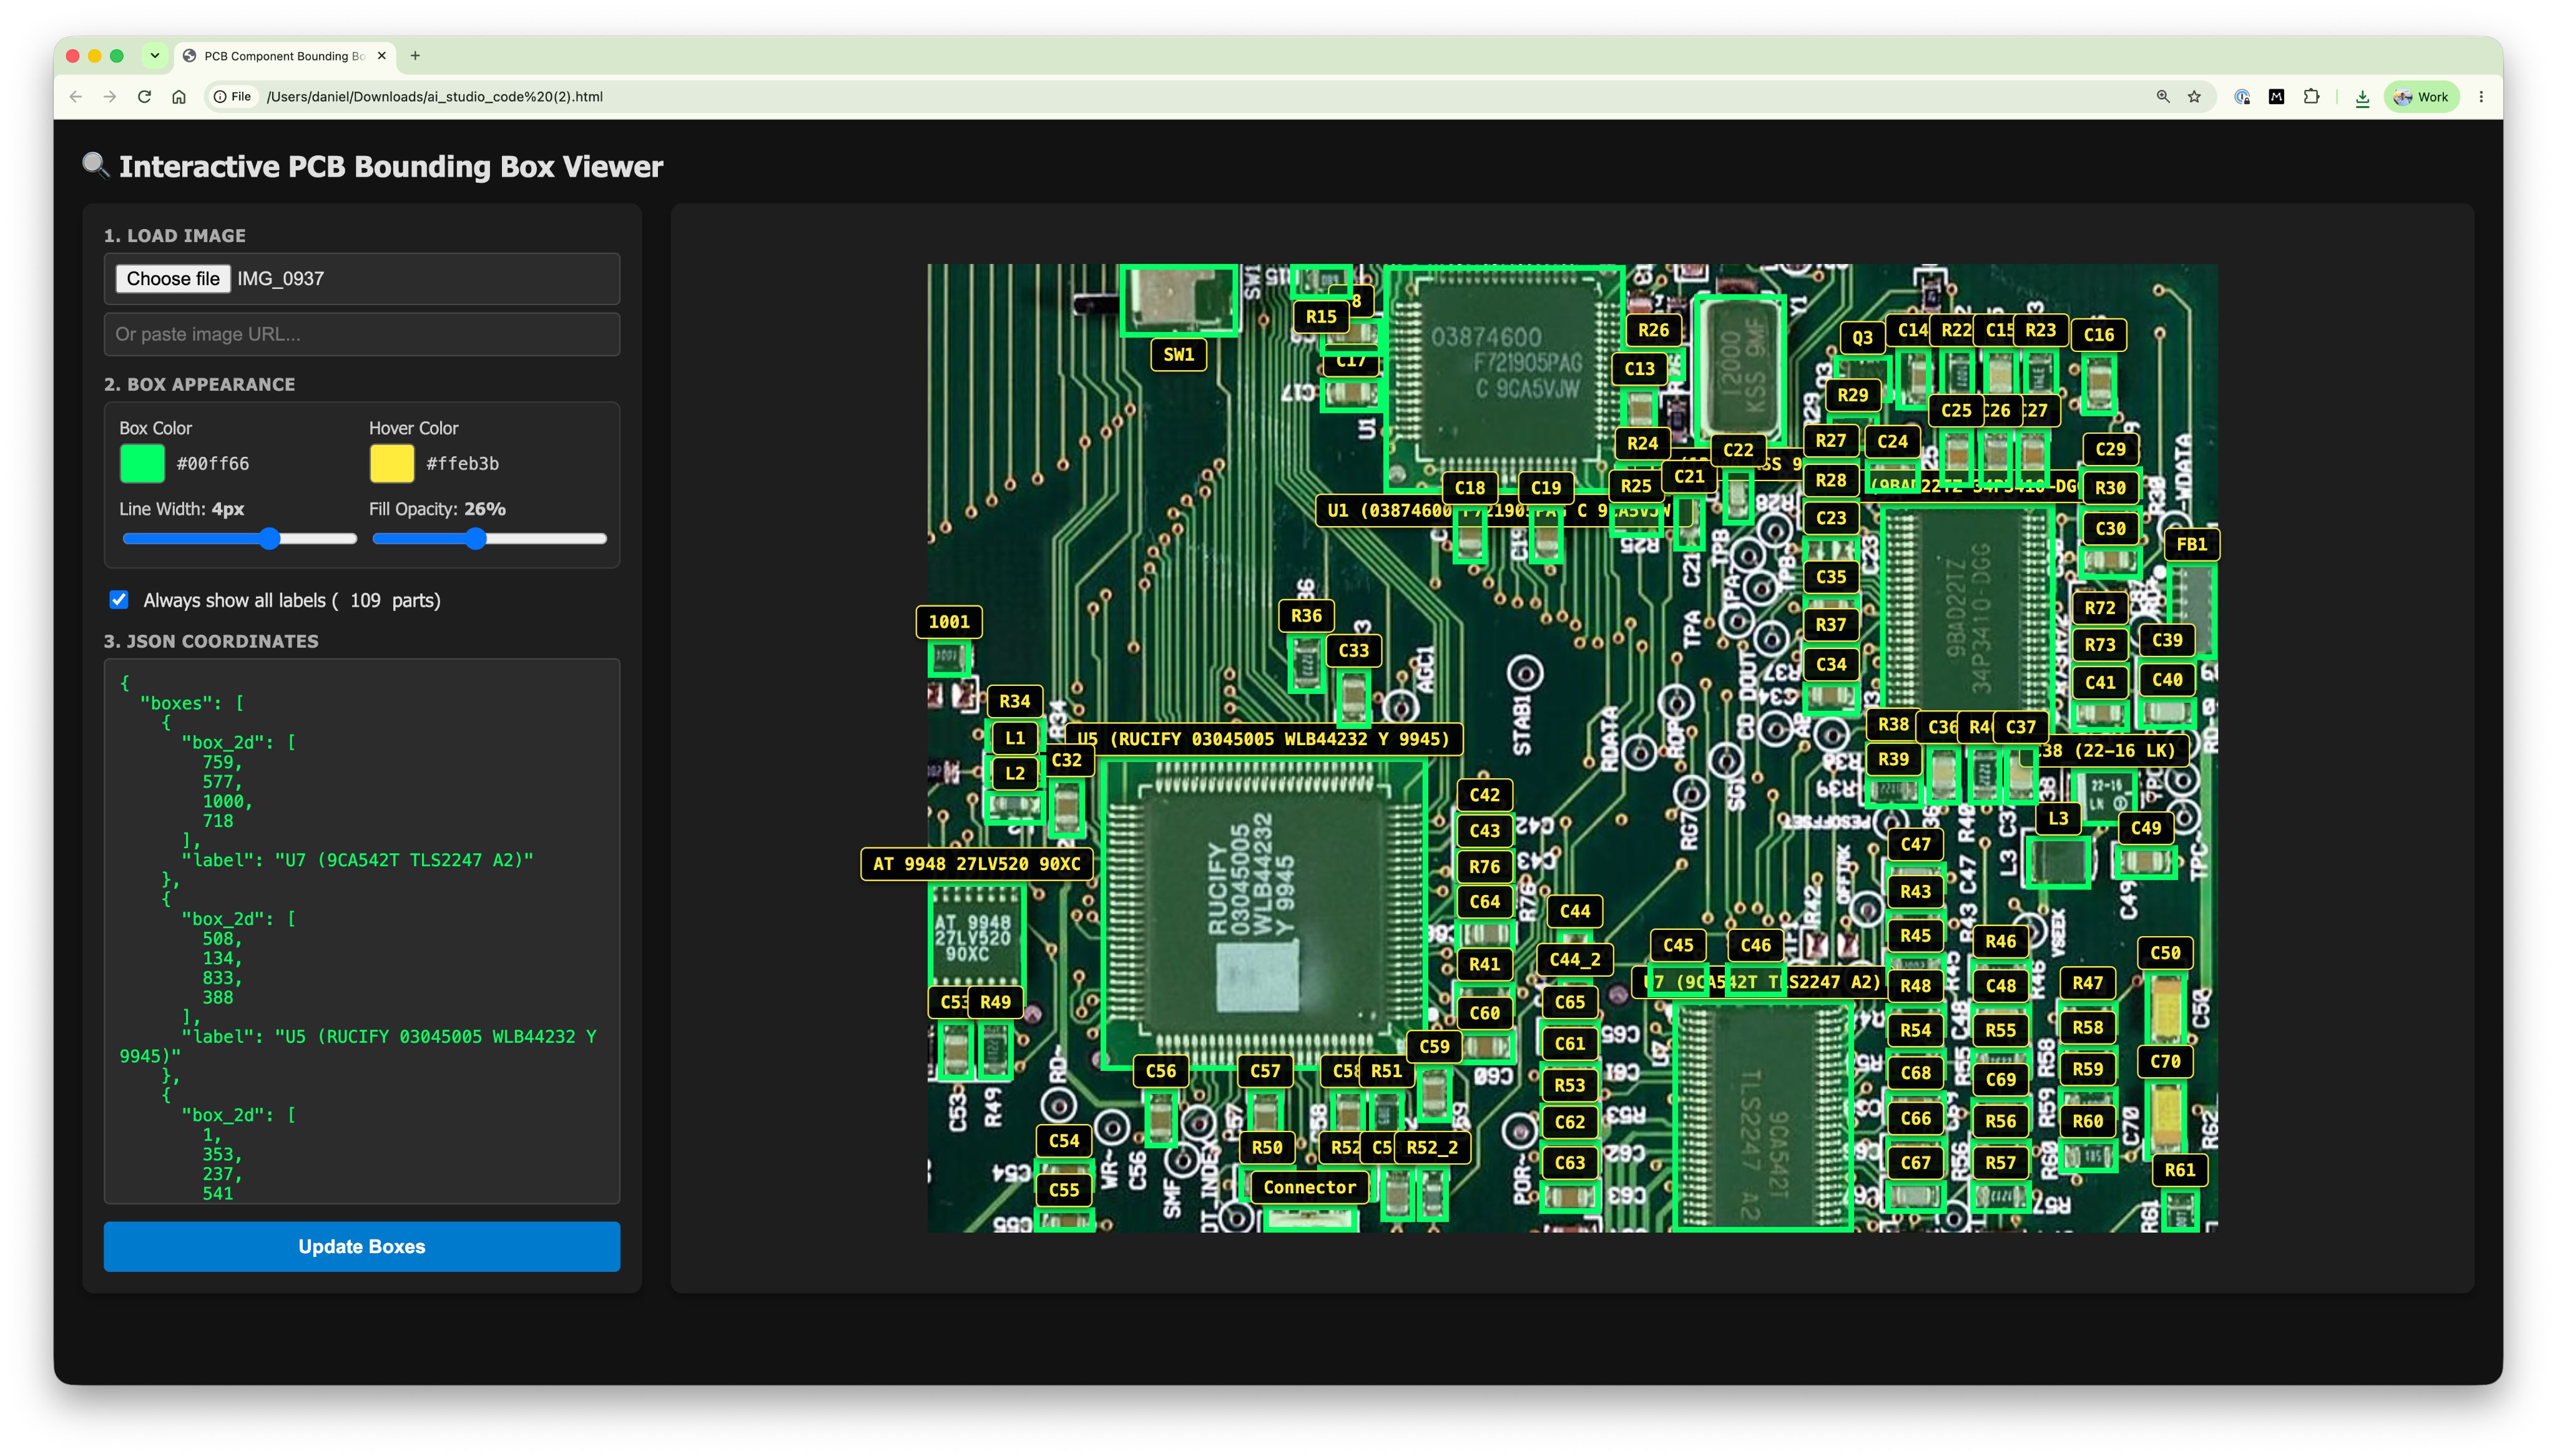
Gemini 4 Argon is cracked at vision Generated boxes + HTML to view the boxes in one output when asked basically "label all the parts raised on the board with bounding boxes" + a link to the Gemini API vision docs as a reference via @GoogleAIStudio If you've got any delicate vision tasks, I'd highly recommend trying to build a small agent loop which brings in Gemini 4 Argon + a tool like SAM3 (for high quality masks) The modern agentic vision loop: • Images at scale • Define a labelling rubric (e.g. "label all the X's and Y's") • Send seed data to Gemini in a loop to refine rubric / create golden samples (use Agentic Vision/Agentic Video for more token efficient labelling) • Bring in tools like SAM3 or Falcon Pecerption-HD for finesse • Repeat at scale • ... • Fine-tune a targeted model to repeat the task for even more labelling at scale • Get Gemini to review samples with high uncertainty • ... • Repeat N times until your smaller model is a beast at your target task