Developer builds a self-improving agent loop with Opus 5.5 and GPT-6 Astra
The author says that with Opus 5.5 and GPT-6 Astra, their test harness now writes evals, simulates calls, grades results, opens PRs and reviews them, with humans still handling merge and deploy.
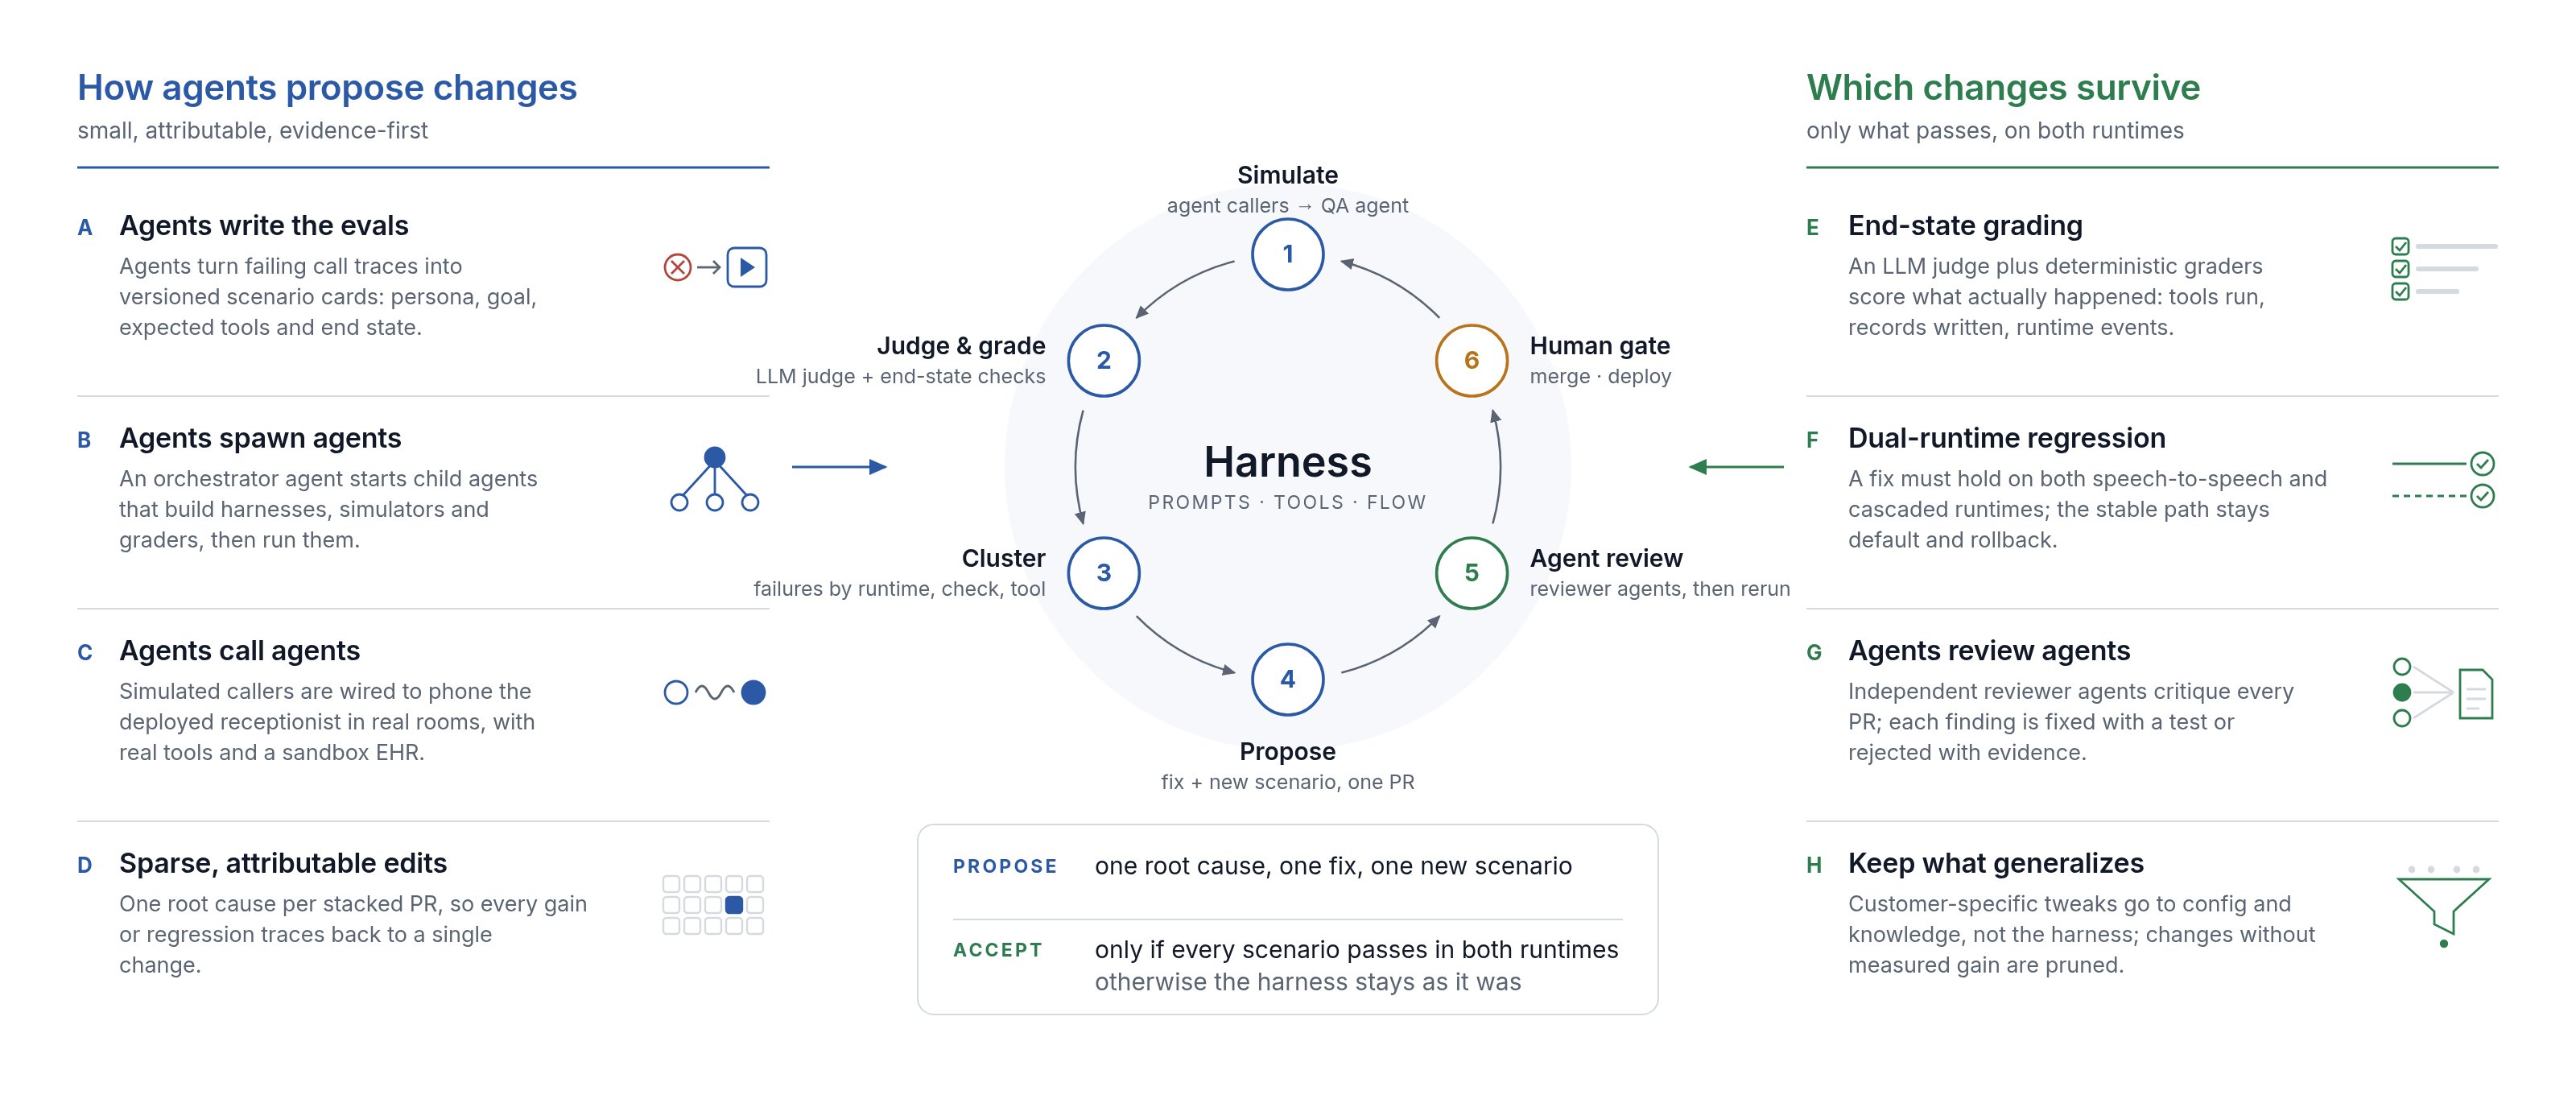
It's actually weird feeling to watch recursive self-improvement start working in your own harness, and to finally see the results. With Opus 5.5 and GPT-6 Astra, our harness now improves itself and agents do almost every step of it. 1. Agents write the evals. They turn failing call traces into versioned scenarios: caller persona, goal, the tools that should run, and the final state expected in the EHR. 2. Agents call agents. Simulated callers are wired to phone our deployed receptionist in real rooms, with real tools and a sandbox EHR, in text and audio, across both of our runtimes. 3. Agents grade agents. An LLM judge plus deterministic end-state checks score each call, and failures are clustered by runtime, tool and check. Agents then write one fix and one new scenario per root cause as a stacked PR. 4. Agents review agents. Reviewer agents critique every PR, findings get fixed with tests, and scenarios are rerun. A change proposed only if it passes on both runtimes. We still own merge and deploy, for now. We're early, but for the first time the loop is starting to close. I've never experienced a pace like this. It's getting faster so RAPIDLY.
This post quotes another post: x.com/anthropicai/status/2062568862479208923