Jev outperforms Voyage's dedicated reranker in a reranking test
The author benchmarked Jev against Voyage rerank-3 on a reranking eval and found Jev beat the domain-specific model, though the long rubric in every request makes Jev more expensive than Voyage rerank-3.
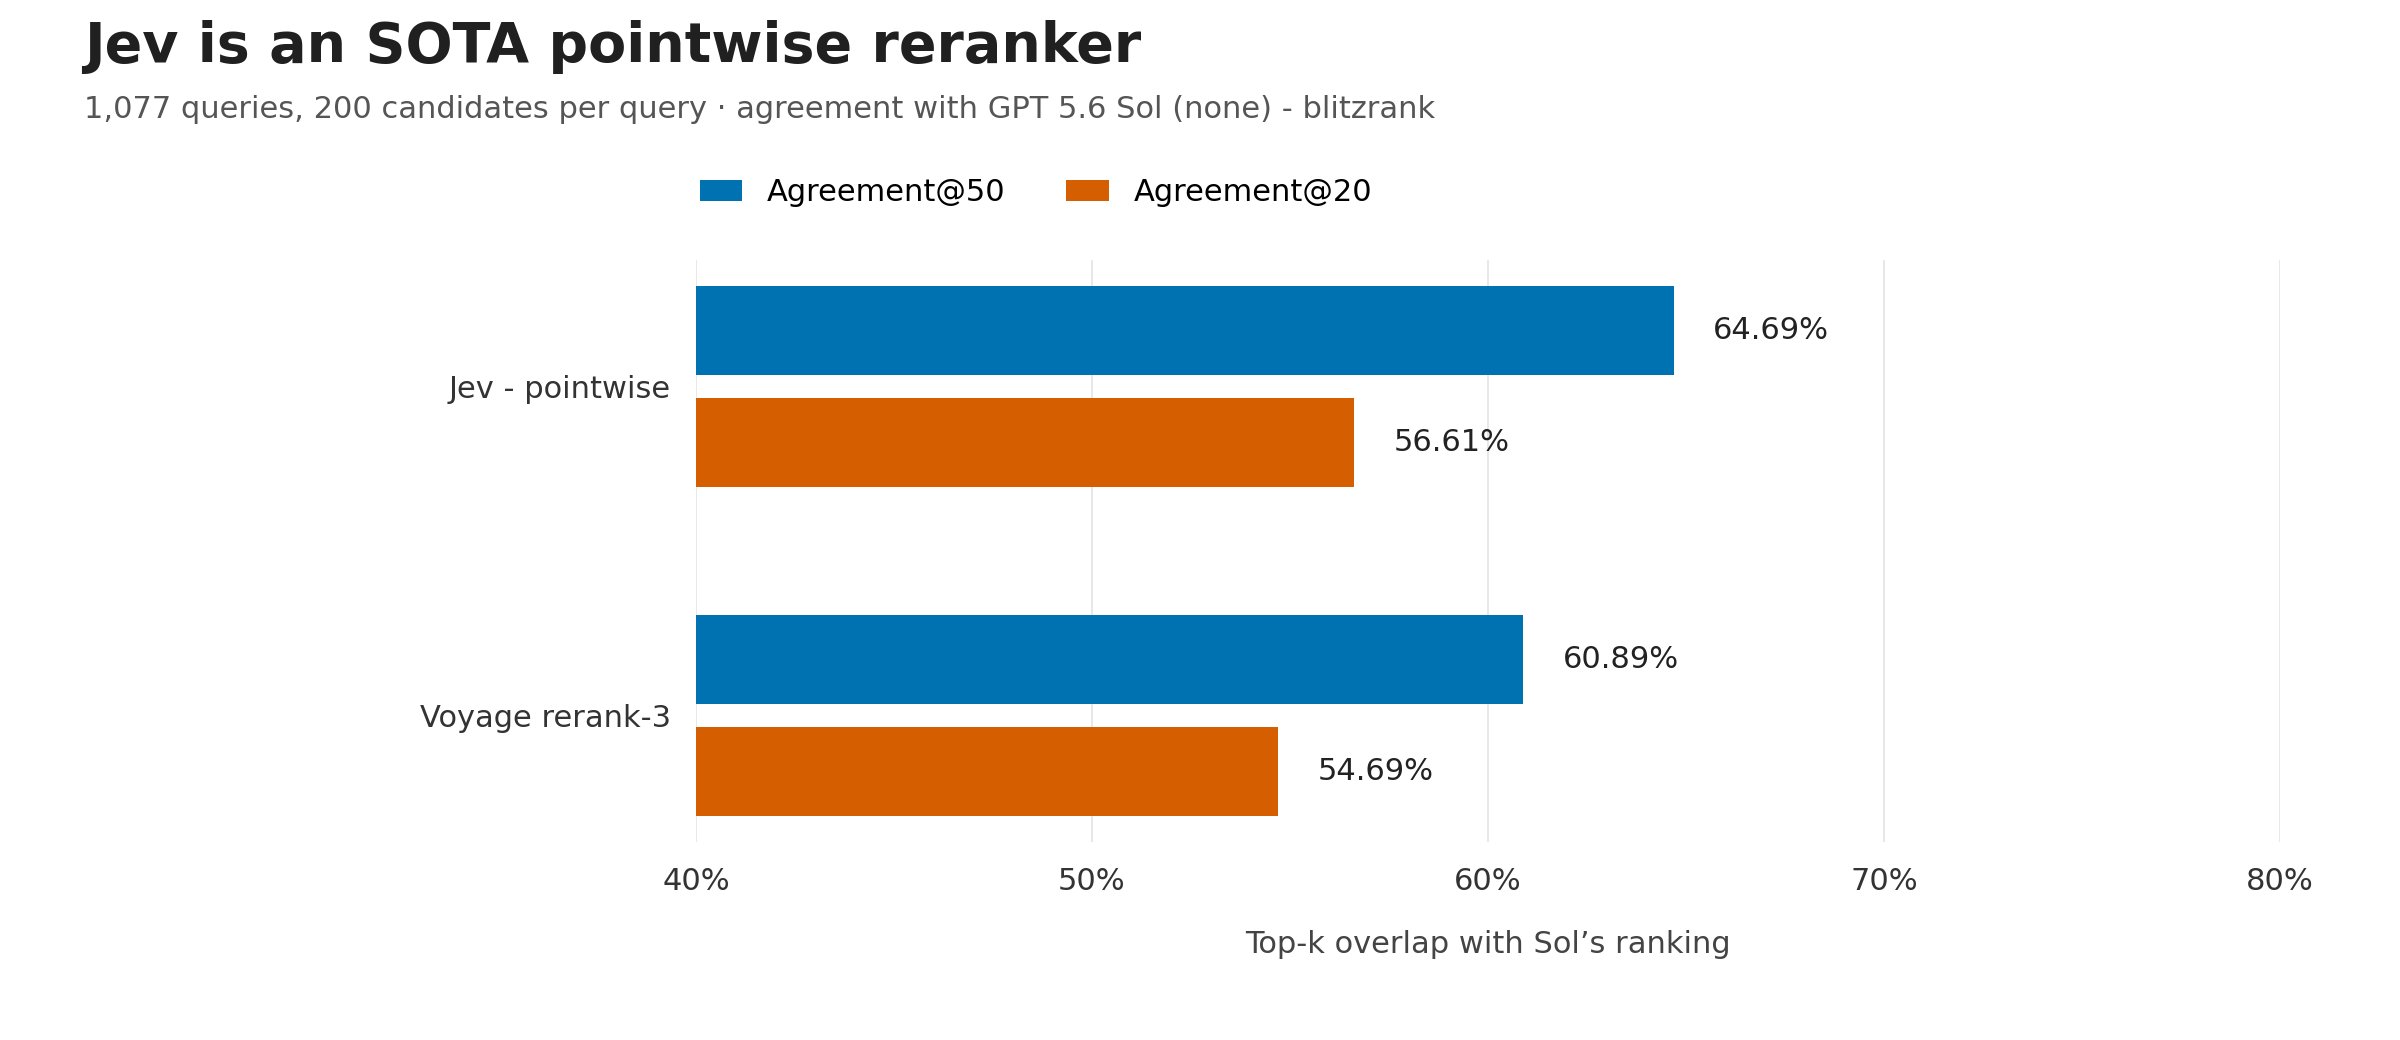
There's a fun mix of excitement and cope on my timeline re-Jev: - OMG I made Jev a year ago this is dumb - You can fine tune this encoder into a better, faster, local classifier, etc Re the "just train your own small classifier" crew - Voyage trains great, SOTA pointwise rerankers that are obviously specialized to the reranking task and have been at it for years, likely also using a strong synthetic data recipe... Exact setup in the response tweet. Do note that using Jev is definitely more expensive than using Voyage rerank-3 bc of the tokens in the lengthy rubric included in every request (though you could definitely optimize this further) Jev is interesting to me bc I didn't expect it to be able to outperform domain specific models like these rerankers. Every other OpenJev etc type model I've benchmarked gets ~15% agreement at 20 on this eval. It's almost like it would be tough to perfect the data recipe to train a general classifier 🤔