Science agent benchmark: GPT-6 Astra edges out Opus 5.5 across tiers
On Terminal-Bench-Science 0.1's 70 real research workflows, GPT-6 Astra max scores 63.3% while Opus 5.5 xhigh reaches 61.9%, beating its own max tier at lower cost.
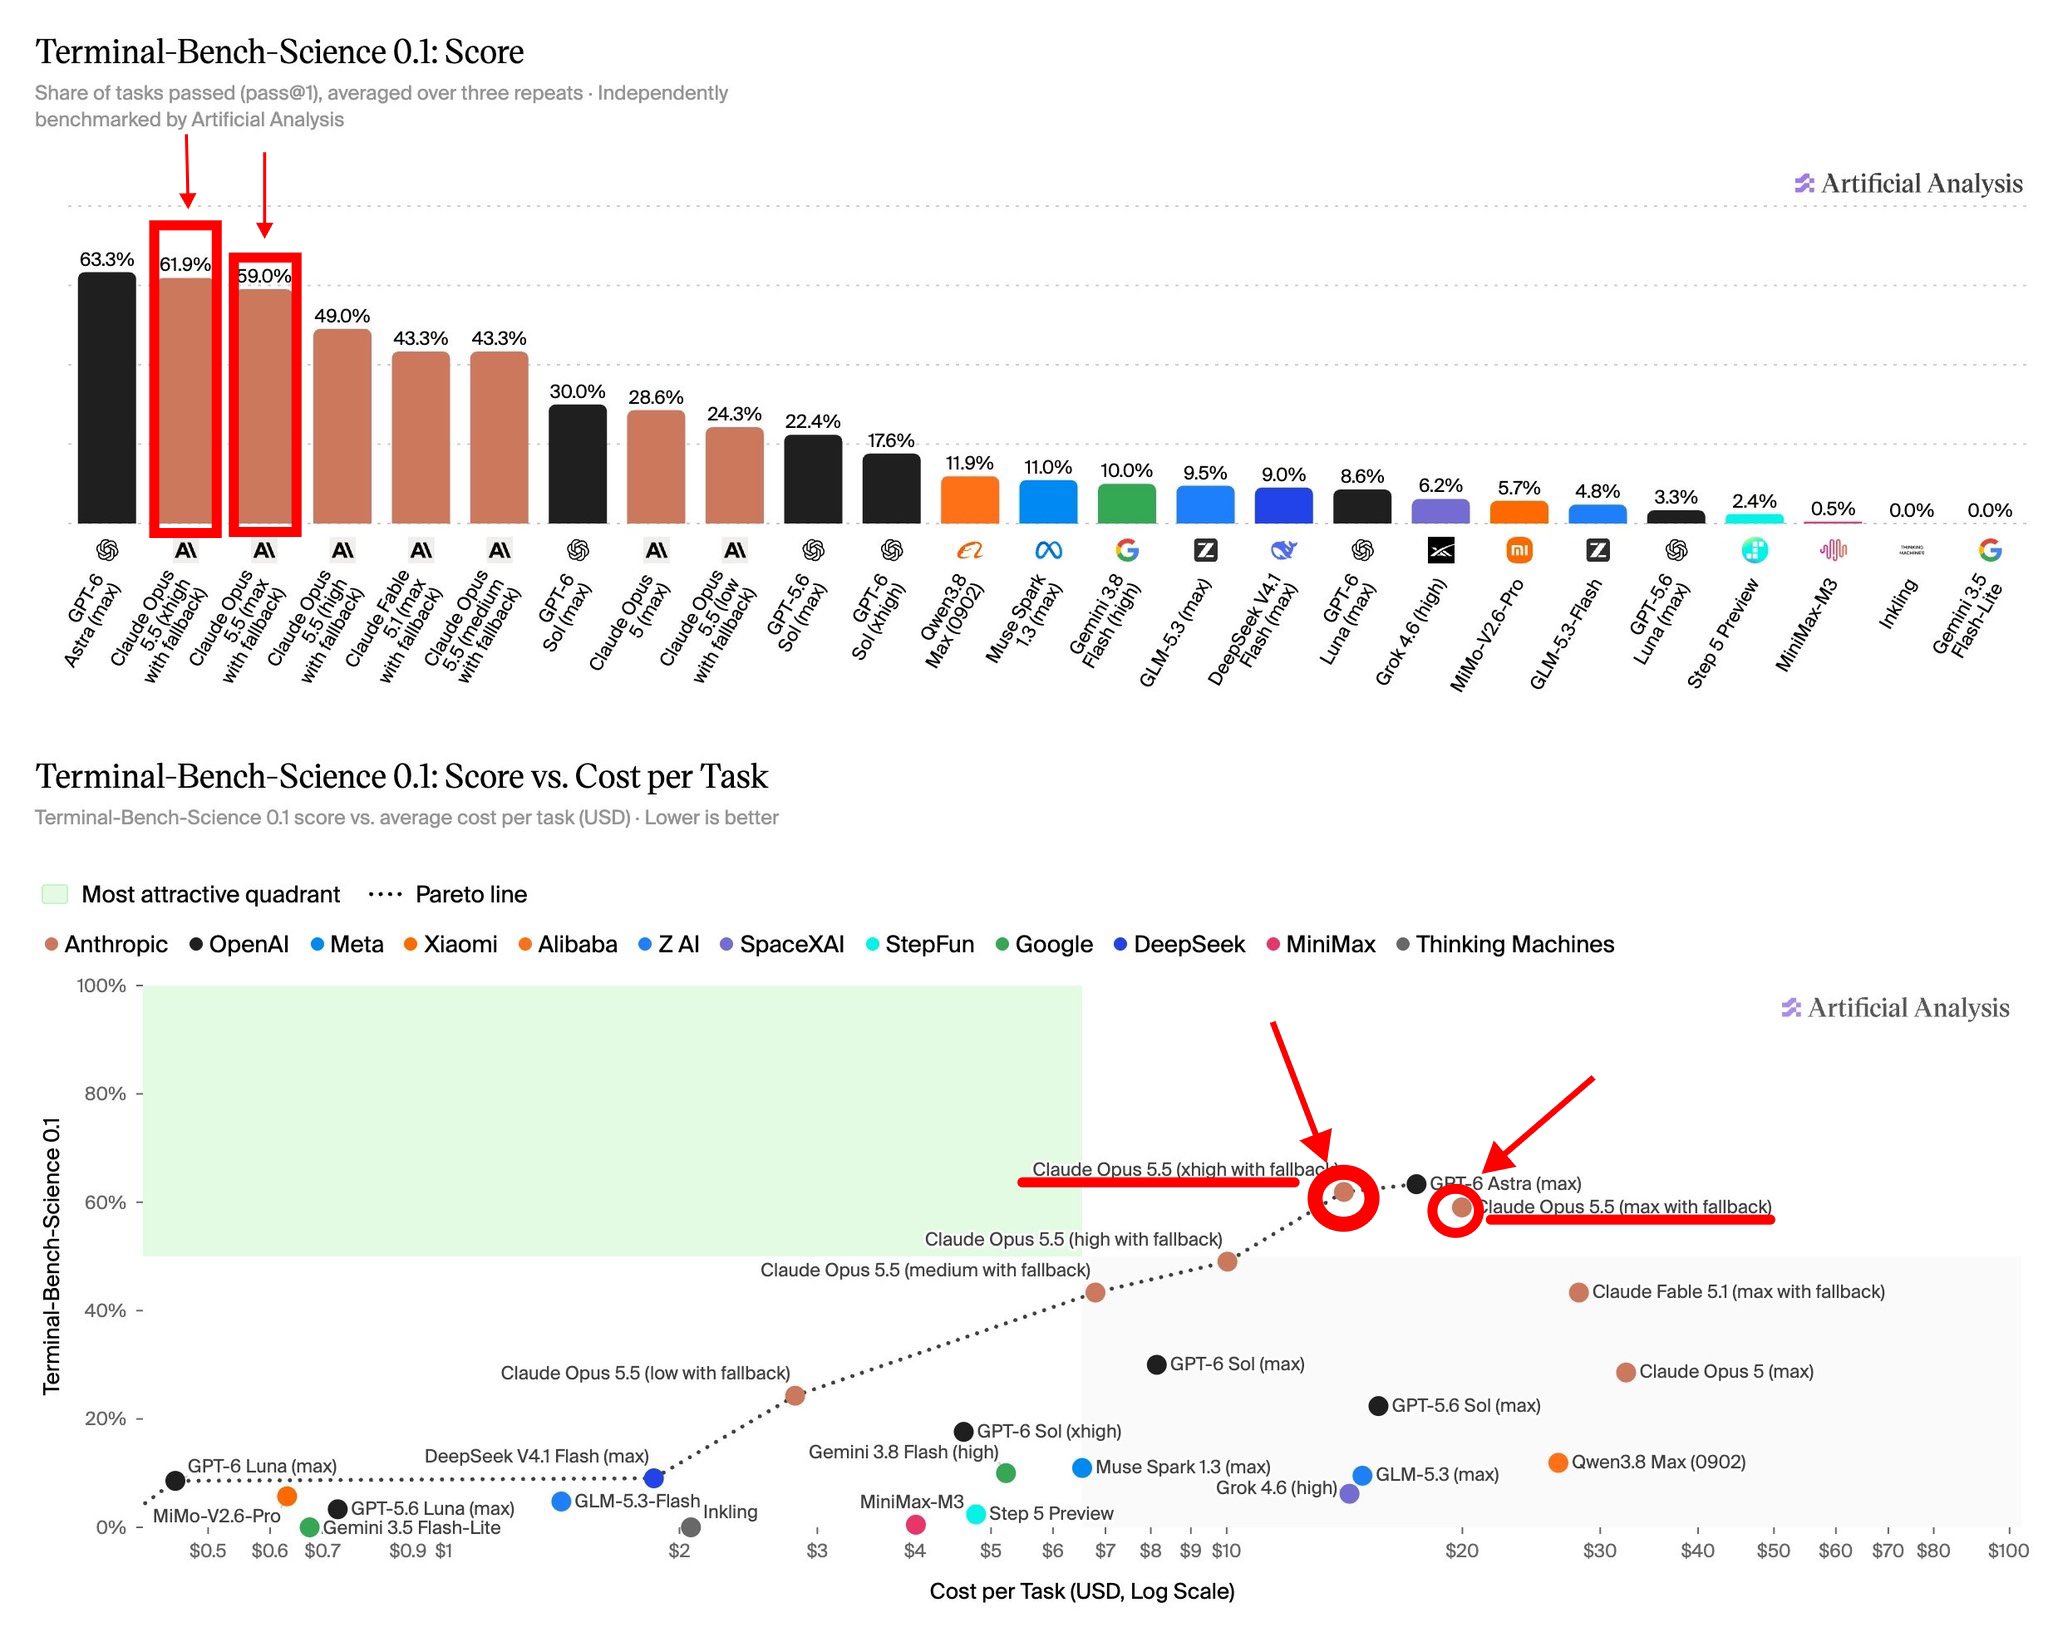
🔥注意了!Claude Opus 5.5 别再无脑开 Max 了,xhigh 才是科学代理任务的甜点档! Artificial Analysis 刚出的 Terminal-Bench-Science 0.1(70个真实科研工作流): 🔸GPT-6 Astra (max):63.3% 🔸Opus 5.5 xhigh + fallback:61.9% 🔸Opus 5.5 max + fallback:59.0% xhigh 直接反超 max 近 3 个百分点。 分点对比 Opus 5.5 两个推理档: 1️⃣科学任务通过率:xhigh 61.9% > max 59.0%(数学科学 xhigh 能到 71%,生命科学仍是短板) 2️⃣成本效率:通用 Intelligence Index 上 xhigh 约 $3.46/任务,max 要 $5.98,token 用量几乎翻倍 高推理档不是越高越好,Opus 5.5 的 xhigh 已经够顶,再往上开 Max 反而掉分还更贵。 科学代理想冲高分,先试 xhigh + fallback。 #ClaudeOpus55 #xhigh #Max推理 #TerminalBench #Anthropic #AI评测
This post quotes another post: “Opus 5.5 generates a drivable cyberpunk pixel city”