Strata runs a 125B MoE model on 12GB of VRAM
Open-source project Strata, which hit 20k GitHub stars in 17 days, fits the 125B Qwen3.8-Flash-Next MoE model into 12GB of consumer VRAM by scheduling experts on demand, and ships OpenAI/Anthropic-compatible endpoints.
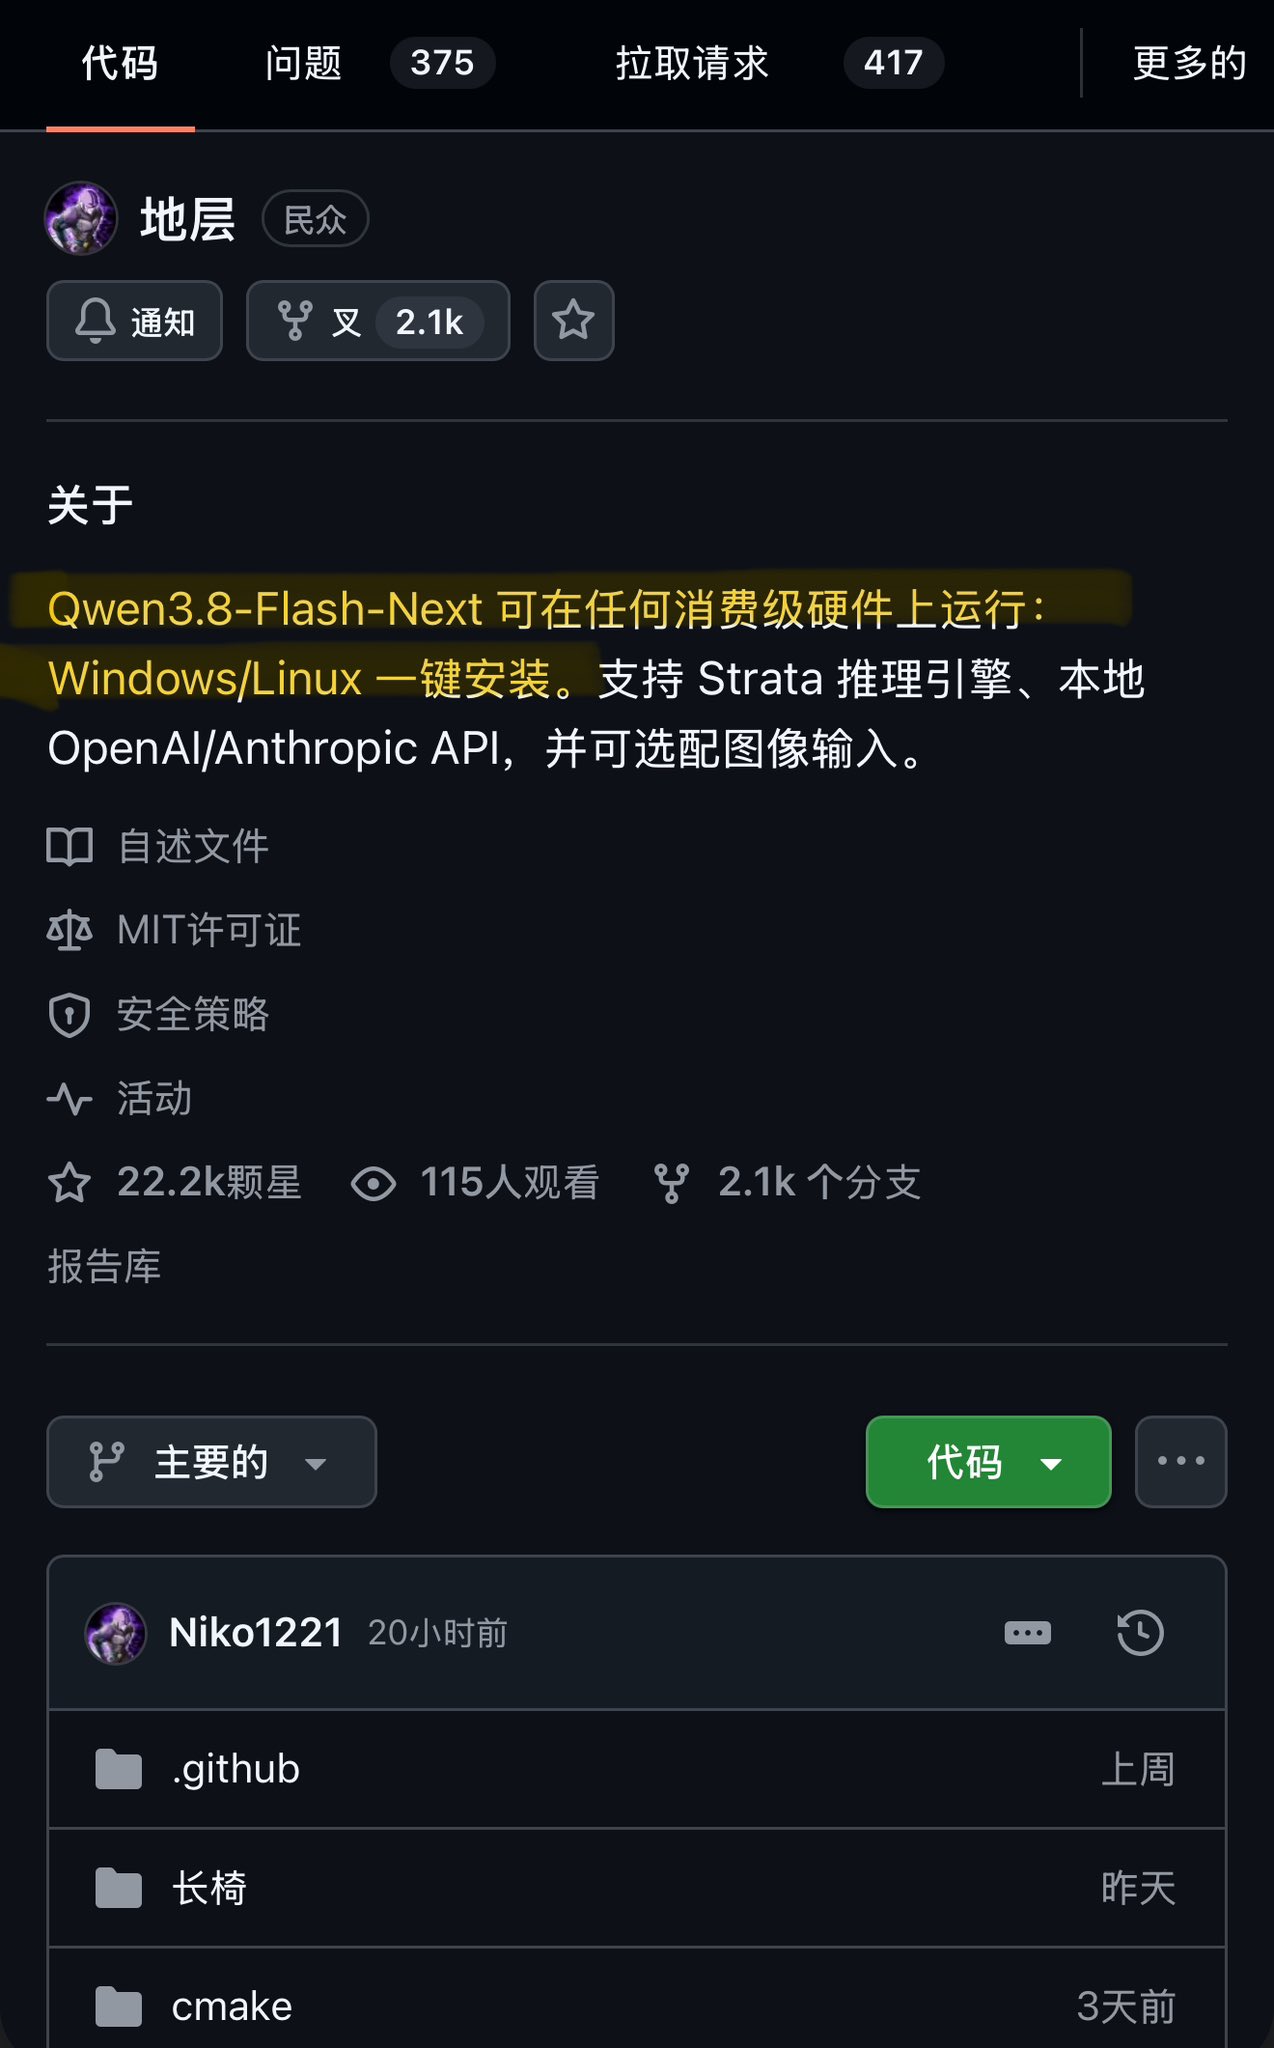
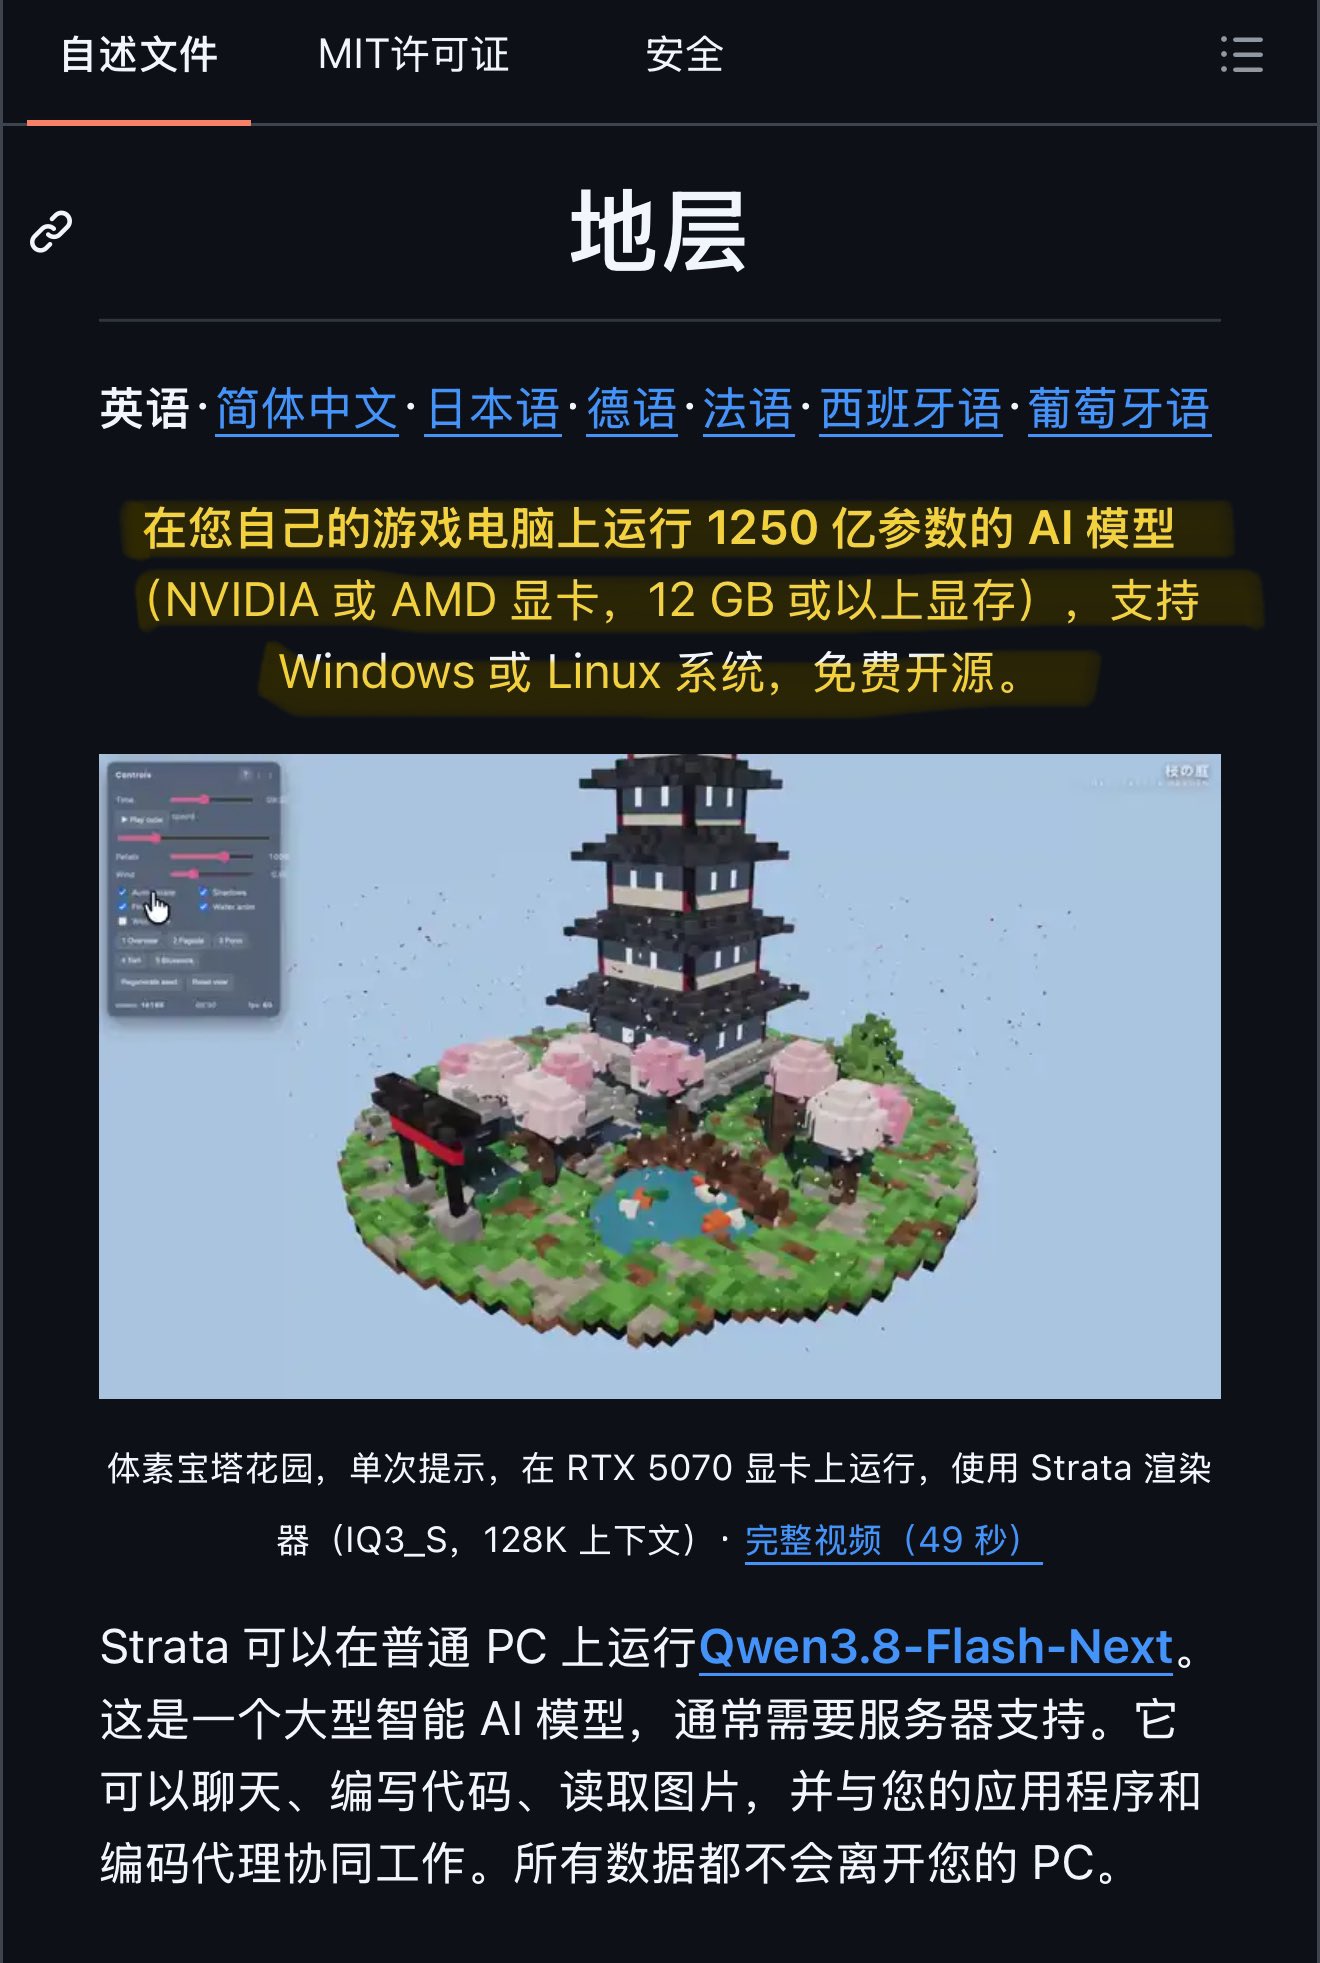
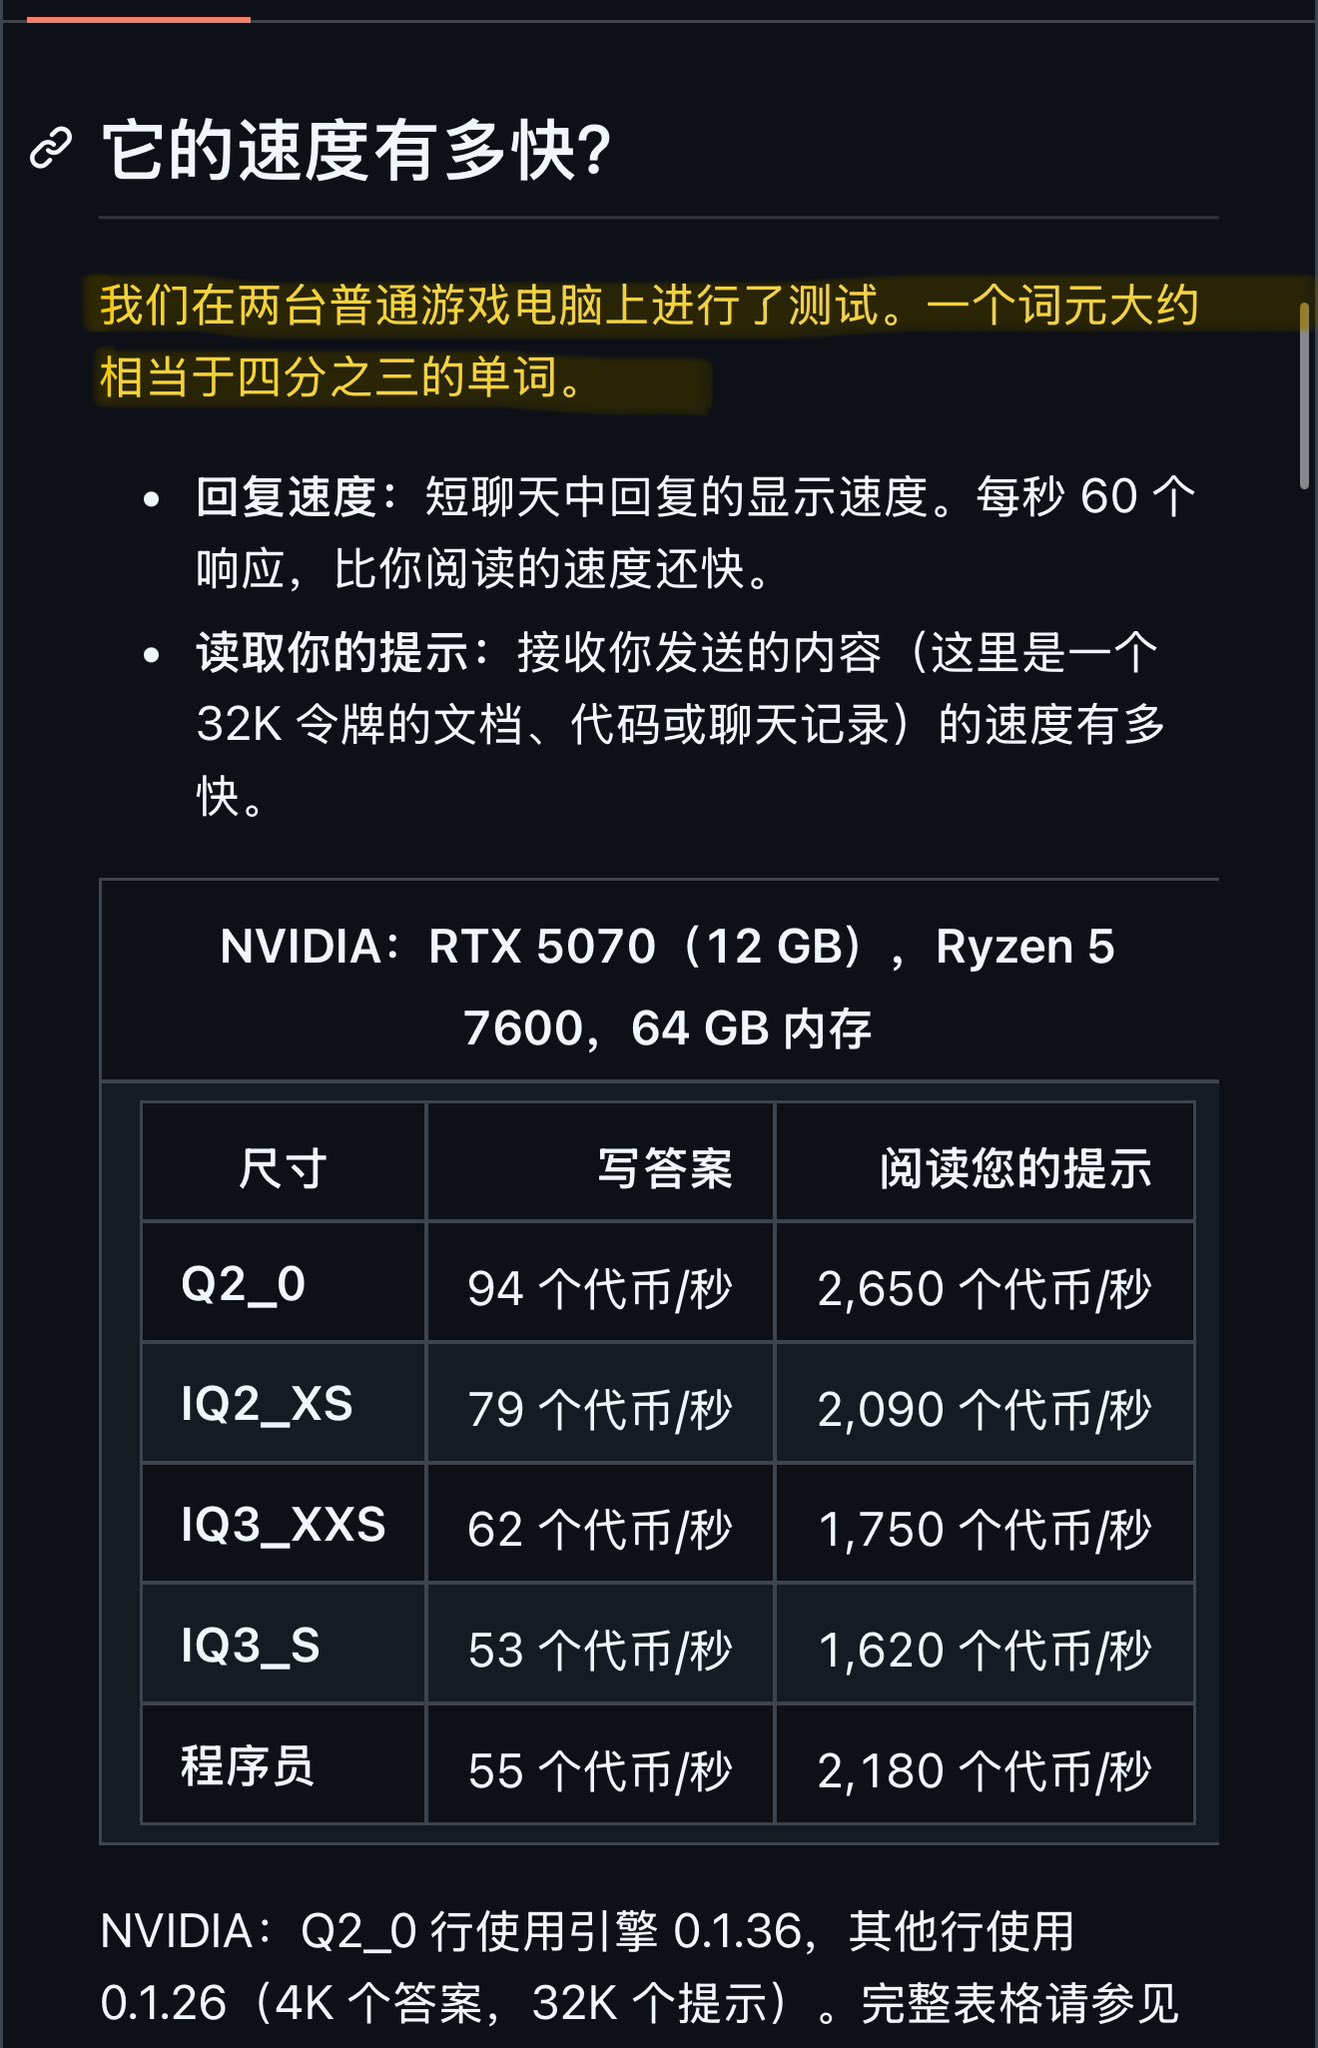
🔥简直逆天!Qwen3.8-Flash-Next 125B大模型,现在能直接跑在你 12G 显卡的游戏电脑上了! Strata 开源项目,上线仅17天,GitHub 已冲到20.8k Star,24h +1239,把这个 24576 专家的 MoE 模型塞进了普通消费级硬件。 核心亮点: 🔹仅需 12G 显存 + 32G 内存就能装(推荐 64G 跑满所有量化) 🔹RTX 5070 实测 Q2_0 达到 94 token/s(比阅读还快) 🔹24576 个专家按需调度:显卡只放常用热点,内存放全部,SSD 存查找表(原理像厨房,常用的放灶台边,其余存仓库按需取用) 🔹自带 OpenAI / Anthropic 兼容接口,Claude Code / Cursor 等直接连 localhost,数据完全本地 上手步骤: 1️⃣下载或 git clone https://github.com/Niko1221/Strata 2️⃣Windows 双击 START-HERE.bat,Linux 运行 ./setup.sh 3️⃣按提示选模型(32G 内存选 Coder,48G+ 推荐 IQ2_XS,64G 可上 IQ3_S) 4️⃣等待下载(约70GB)和首次加载(1-3分钟可能短暂卡顿,正常) 5️⃣浏览器打开 http://127.0.0.1:8080 直接用,或把 API 地址填进你的工具 GitHub:https://github.com/Niko1221/Strata #AI #LocalLLM #Strata #Qwen #开源 #本地大模型 #游戏电脑跑大模型 #MoE #阿里巴巴
This post quotes another post: x.com/nft_chen/status/2108346776881352833