DeepSeek V4.1 Flash on M5 Ultra via MLX: 102–112 tok/s at 3-bit
A single M5 Ultra 256GB runs 3-bit quantized DeepSeek-V4.1-Flash-1017 in mlx-serve at 102–112 tok/s (peak 136.7), 1770 tok/s prefill, ~9s to first token at 16k context, usable from Claude Code and Codex.
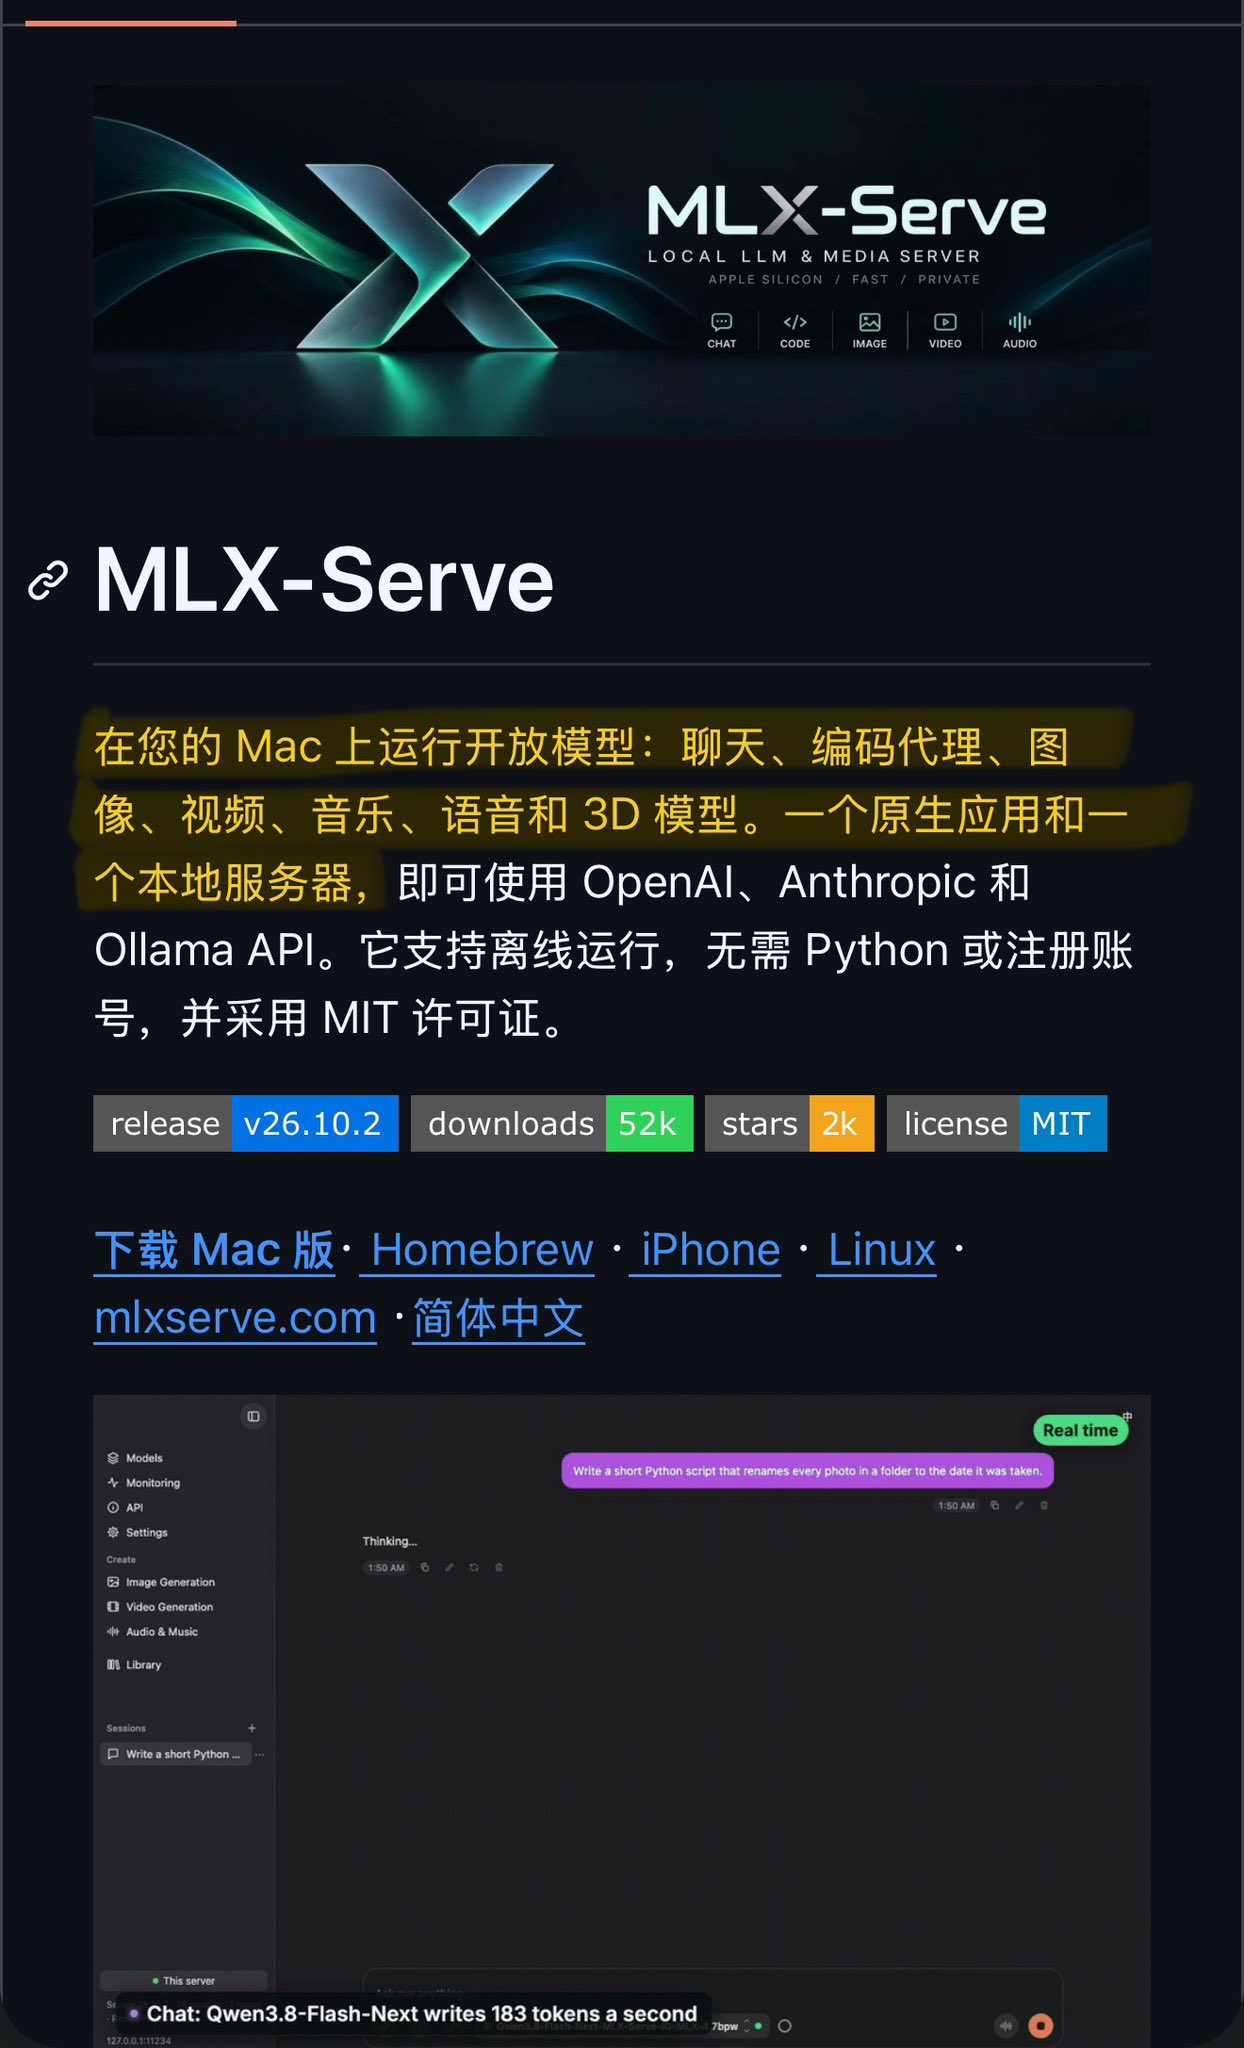
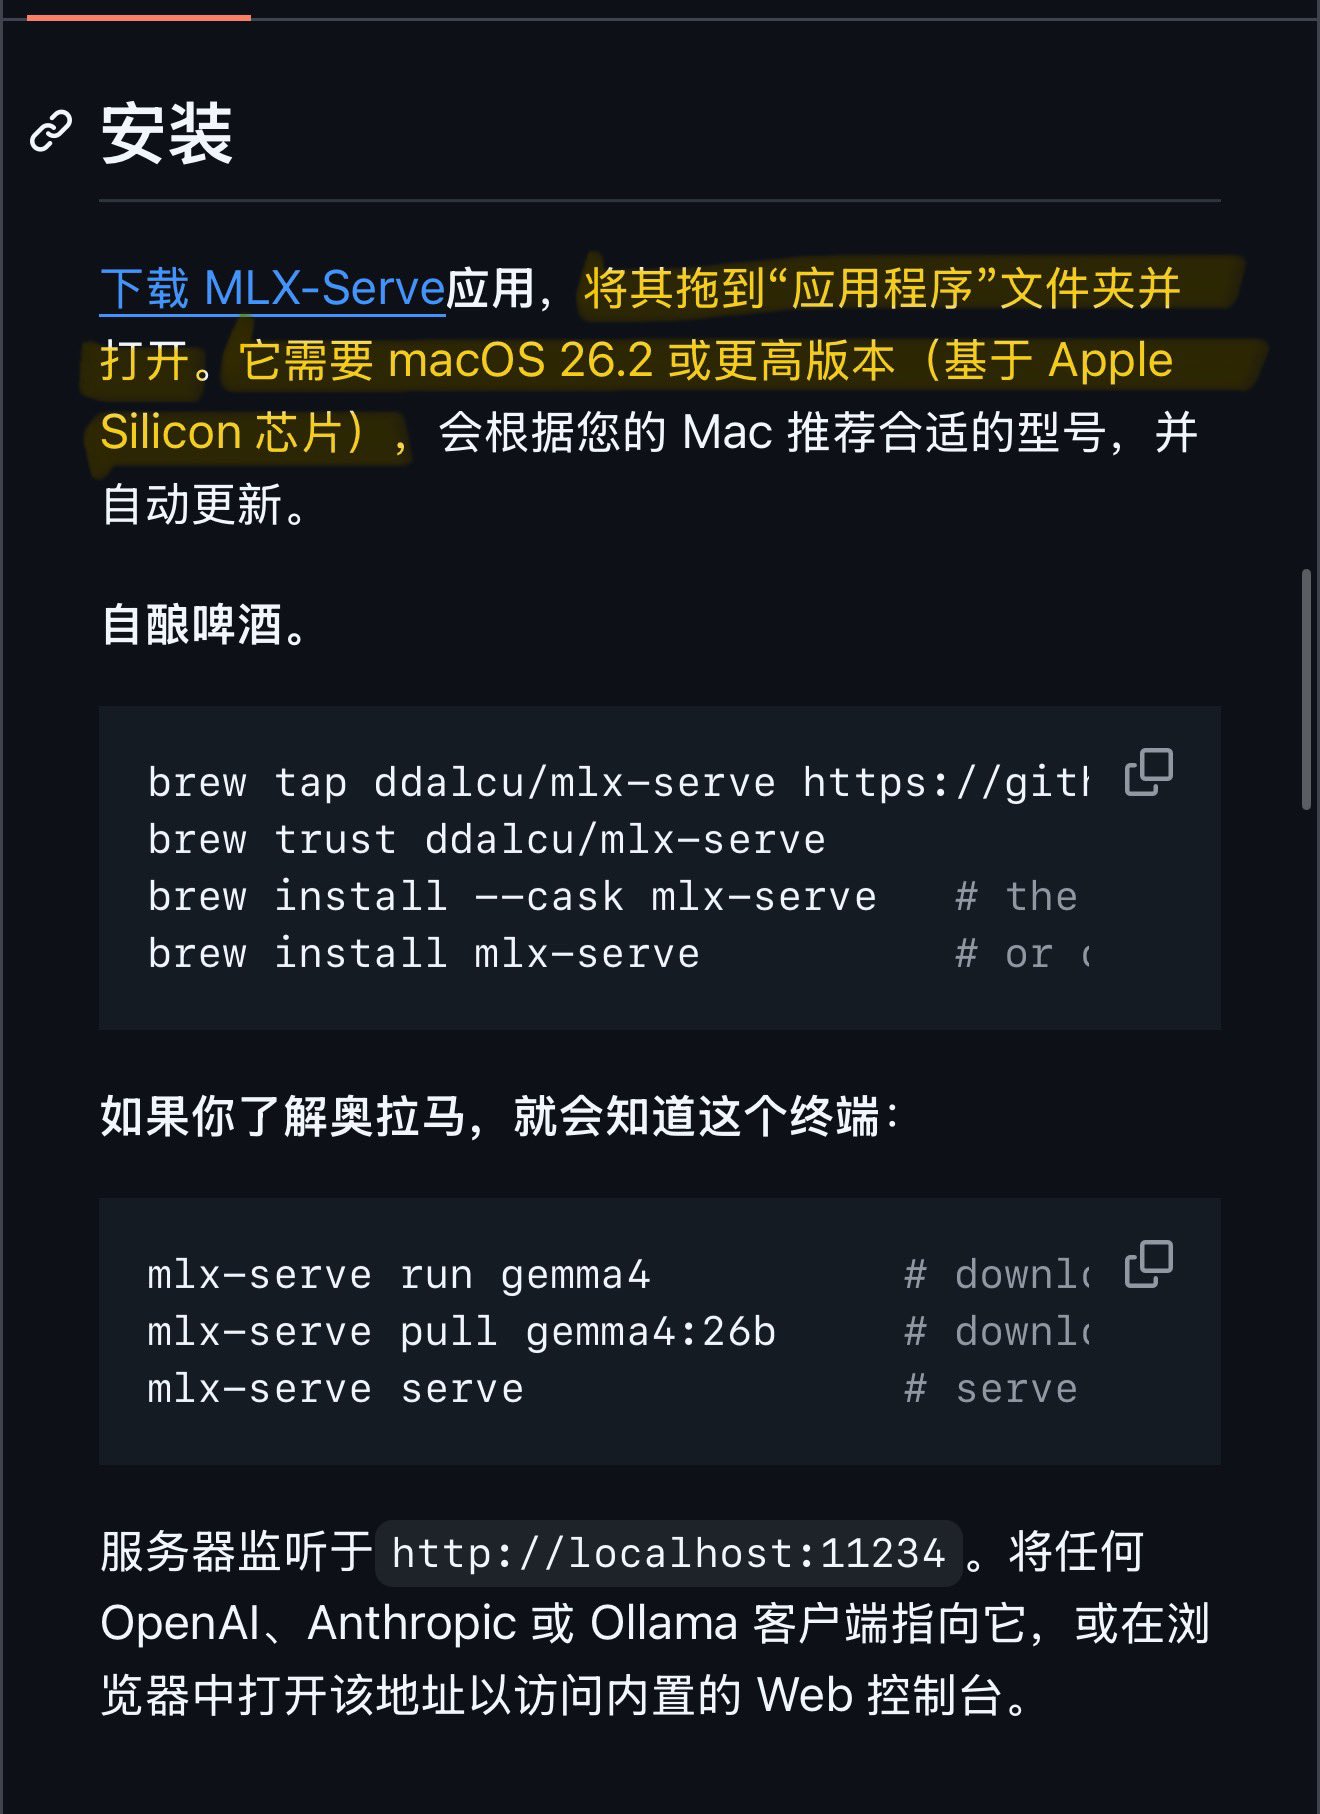
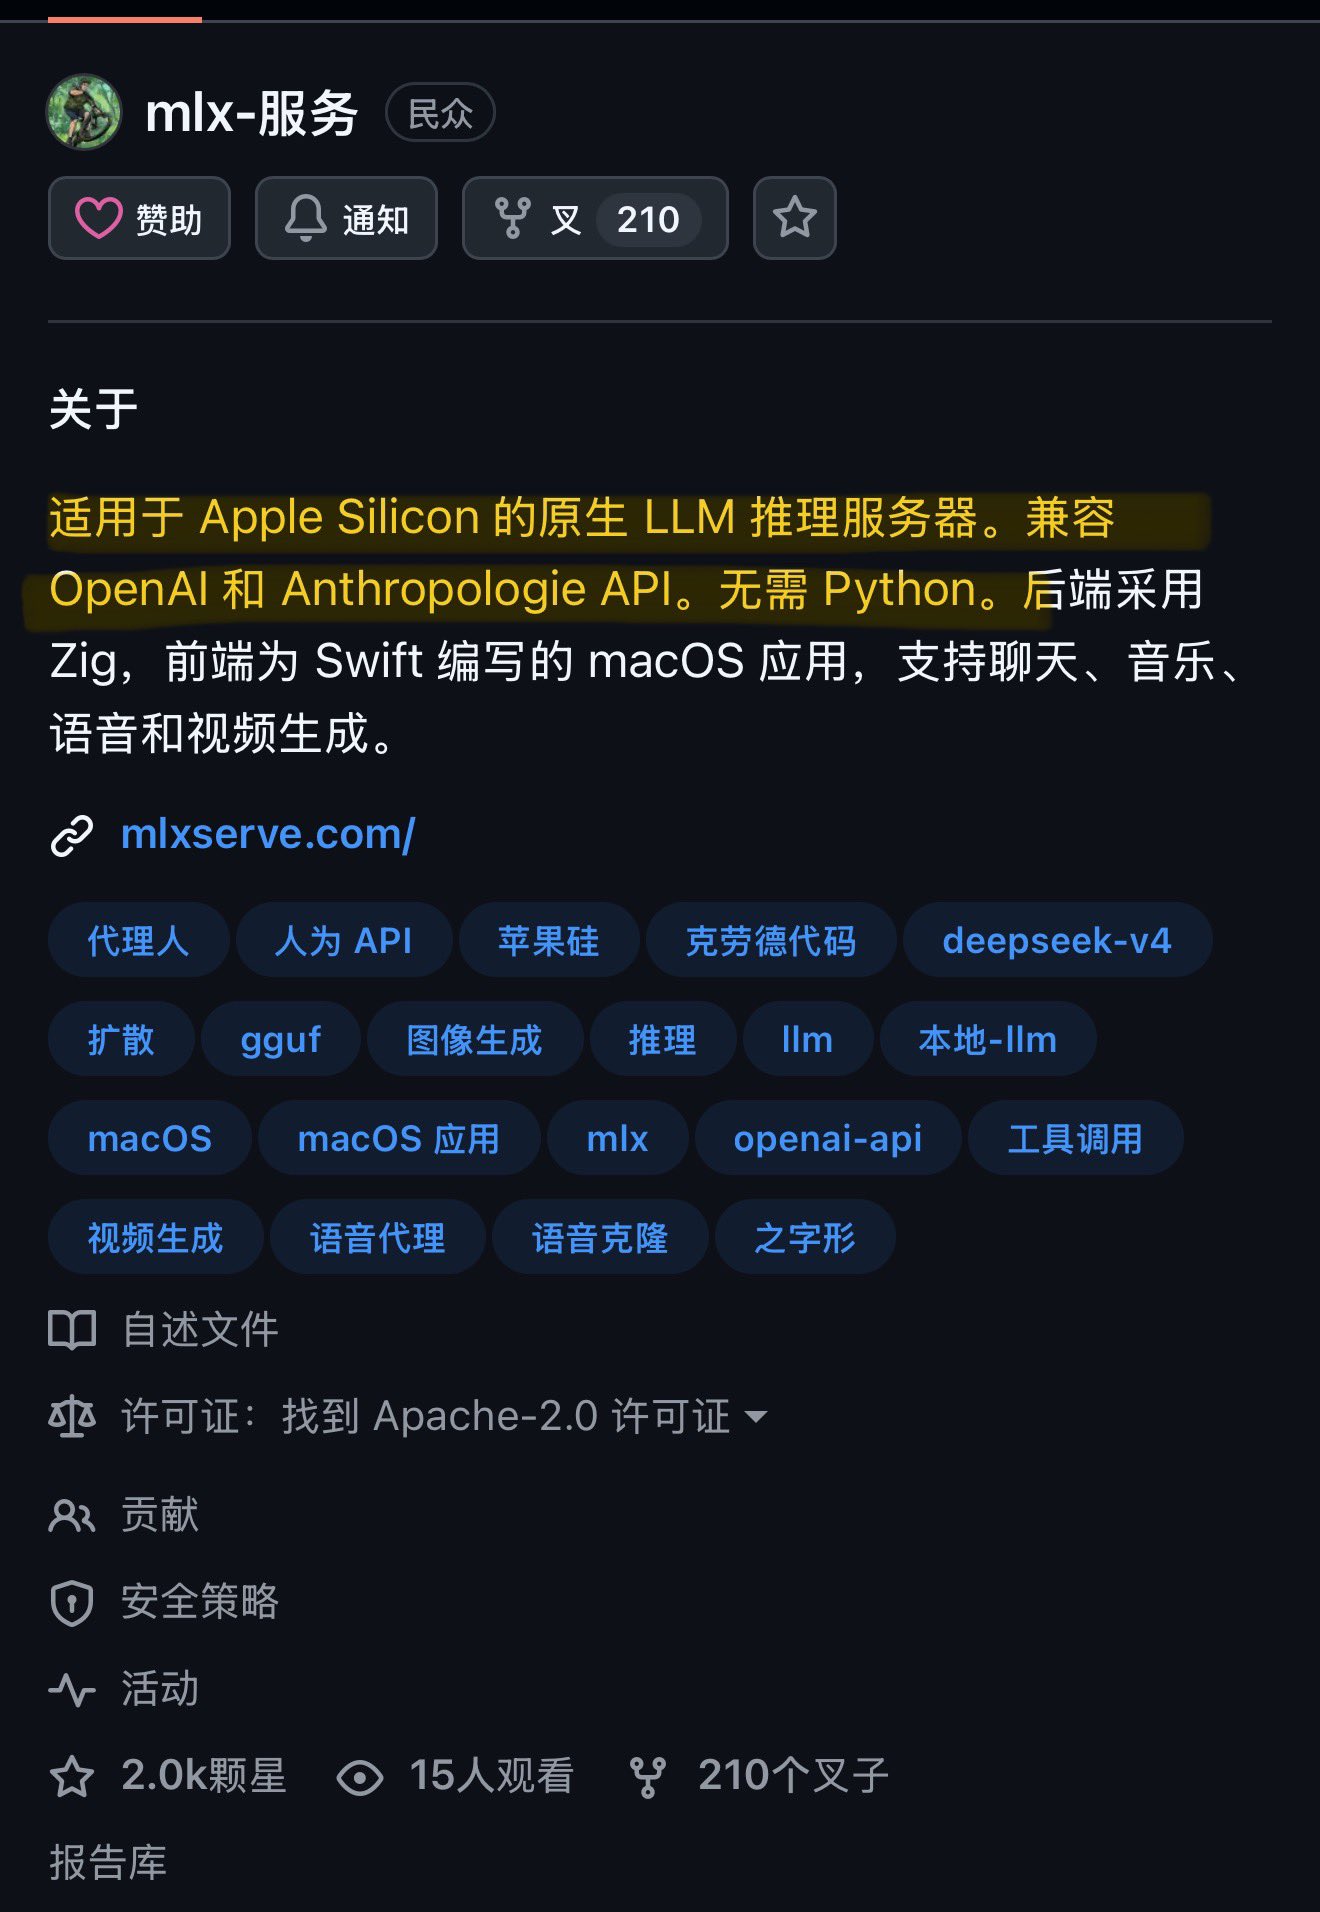
💥苹果党码住!只需一台Mac把 DeepSeek-V4.1-Flash 1017 直接干到每秒100+ token! 在单台M5 Ultra,80核GPU + 256GB上,用mlx-serve把刚发布的DeepSeek-V4.1-Flash-1017跑通 核心亮点: 🔹生成速度稳定102~112 tok/s,峰值冲到136.7 tok/s 🔹Prefill读prompt飙到1770 tok/s 🔹短问题首字约0.5秒,16k长上下文约9秒出字 🔹3-bit量化(iQ-MLX-3.0bpw),token匹配率89.8%,困惑度仅+3.6% 🔹自带DSpark草稿层 + prompt lookup加速,跑coding agent尤其猛 快速上手(256GB M5 Ultra用户最划算): 1️⃣升级到macOS 26.10.3预发布版 2️⃣下载MLX-Serve App(或brew安装) https://github.com/ddalcu/mlx-serve 3️⃣打开App,Model Browser搜索DeepSeek-V4.1-Flash下载对应quant 4️⃣直接聊天 / 用Claude Code、Codex等工具连本地端口(兼容OpenAI/Anthropic/Ollama) 完全本地、无需Python、MIT开源,写代码/跑agent神器。 #DeepSeekV41Flash1017 #Mac #LocalAI #MLX #AppleSilicon #M5Ultra #AI #开源 #本地部署 #苹果电脑
This post quotes another post: x.com/nft_chen/status/2113183059717885960