deepseek-v4.1THREAD
DeepSeek V4.1 Flash 1017 benchmark roundup: leads agent coding, trails Opus 5 on HLE
All 11 benchmarks improved, with DeepSWE 77.0 beating Opus 5's 74.0 and leads on Automation-Bench, Agents' Last Exam and Apex Bench, though Opus 5 still wins HLE and Terminal-Bench; pricing unchanged and MIT-licensed.
K-AI
@OGKAIMArchived 10 days agoOriginally posted 2026.10.17
THREAD
🐋 "鲸鱼回来了"——DeepSeek-V4.1-Flash-1017 说是"小更新",11 项评测全涨 📈 💻 Agent 编程赛道直接开香槟: DeepSWE 77.0,超过 Opus 5 的 74.0 Automation-Bench、Agents' Last Exam、Apex Bench 也都是第一 ⚠️ 但综合能力还得认:HLE、Terminal-Bench 这些还是 Opus 5 的天下 💰 价格不变、更快更短、MIT 开源 便宜大碗的干活模型,又进化了 💪
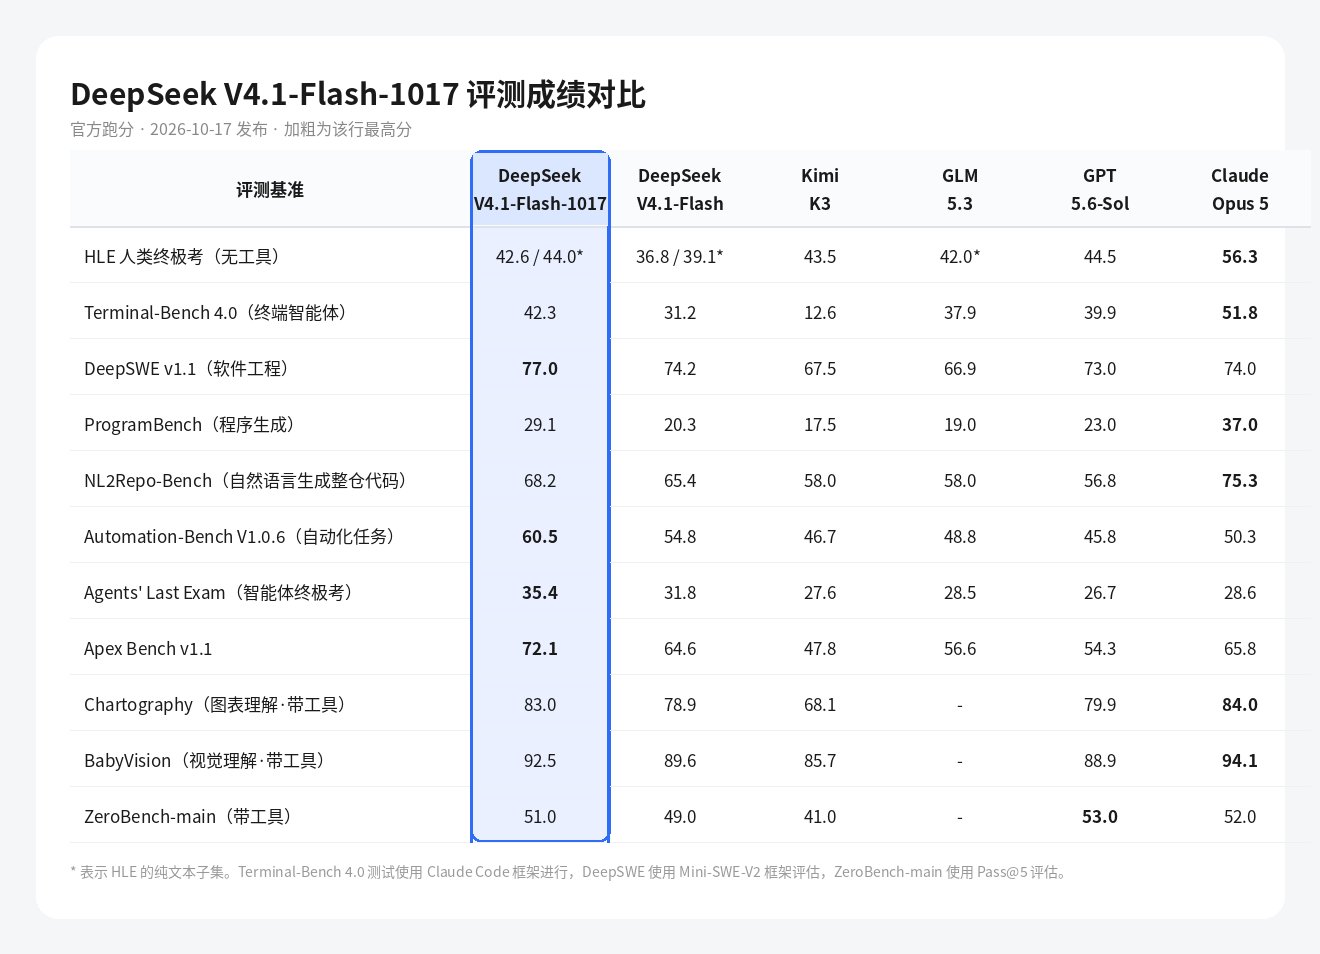
@liaiyuheping 分数表出自官方 HF 模型页:https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash-1017 模型更新见官方 10-17 的更新说明,网页端/App/API 已同步切换,API 名还是 deepseek-flash、价格没变。注脚里写了 Terminal-Bench 用 Claude Code 框架、DeepSWE 用 Mini-SWE-V2、ZeroBench 用 Pass@5 跑的,欢迎拿去复核
K-AI @OGKAIMOriginally posted 2026.10.17
x.com/ogkaim/status/2111388215726776540Archived 2026.10.18 16:43