Matching models to tasks: Astra reserved for complex debugging and architecture
The author suggests a tiered approach: GLM-5.3 for boilerplate code, GPT-5.6 Terra for planning and validation, and GPT-6 Astra only for deep reasoning tasks.
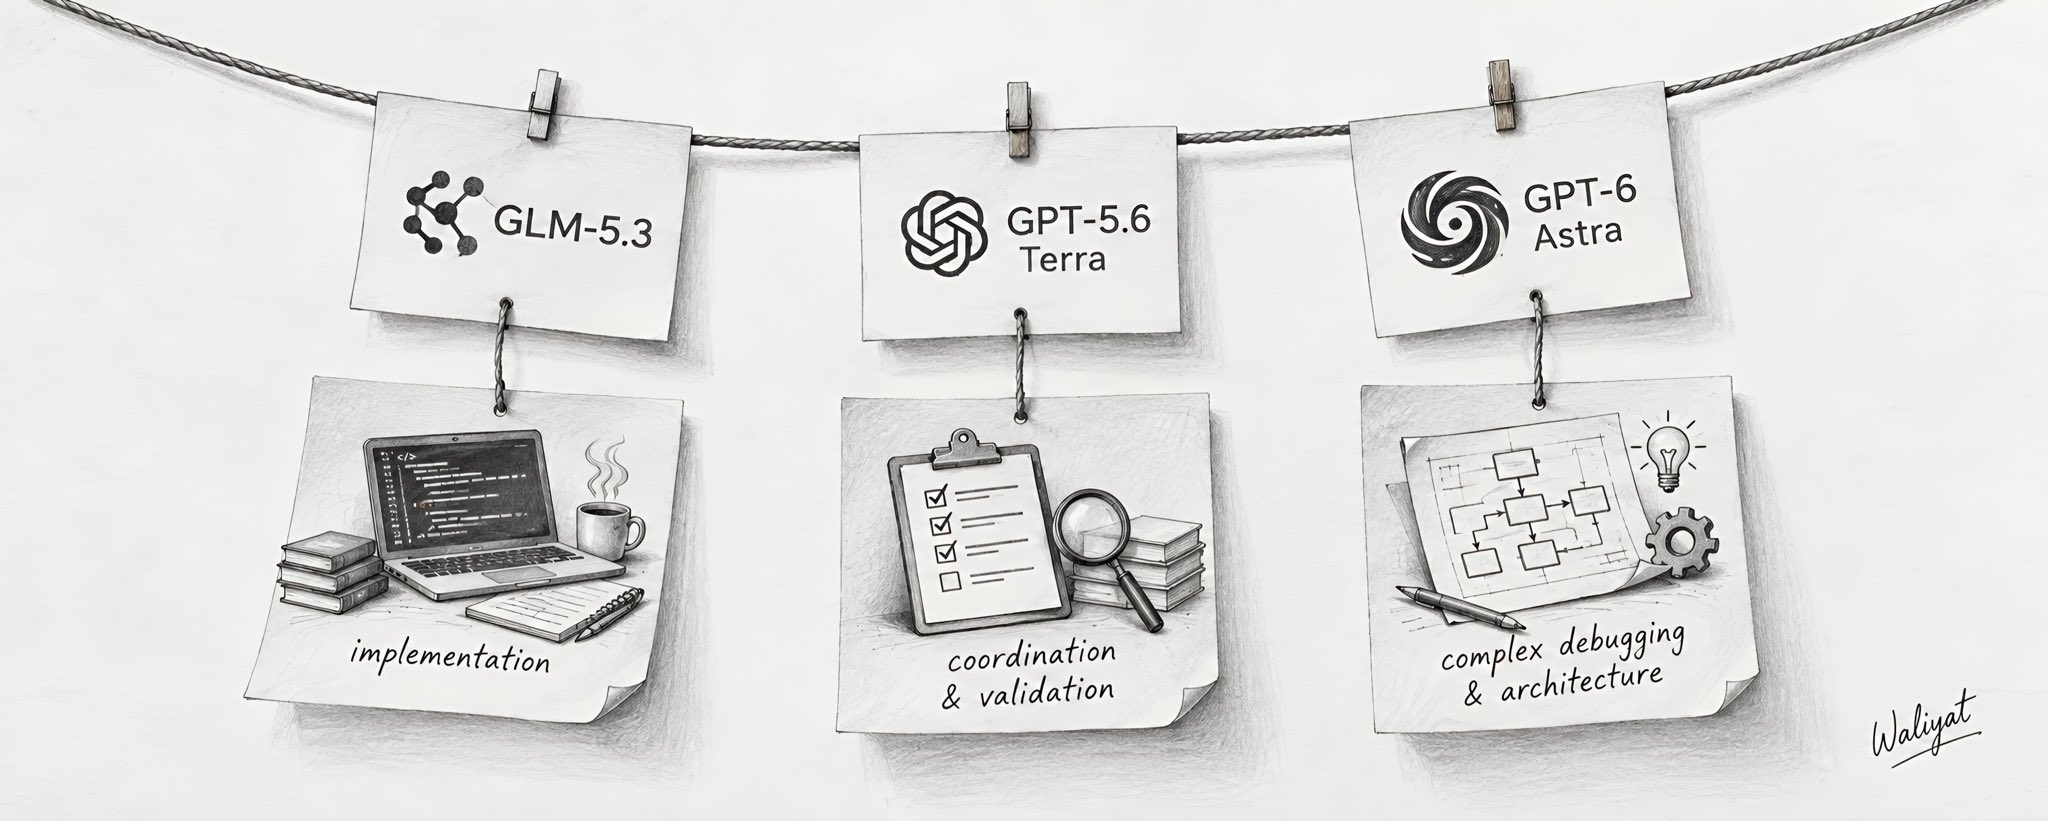
model selection gets more practical when you match the LLM to the workload • for routine implementation, something like GLM-5.3 can handle boilerplate, small features and straightforward code changes • for coordination and validation, GPT-5.6 Terra can handle planning, reviewing diffs, writing tests and checking outputs • for complex debugging or architecture, I’d move to GPT-6 Astra when the task needs deeper reasoning and a larger inference budget the same principle applies beyond coding: use smaller/cheaper models for high-volume tasks, and reserve expensive reasoning for problems where it actually adds value