ReFigBench: the same model scores differently inside Claude Code and Codex
GPT-5.5 ran the same 1,000 tasks in both Claude Code and Codex and its scores shifted with the harness; the benchmark asks agents to rebuild arXiv figures as editable PowerPoint slides, with perception still the main bottleneck.

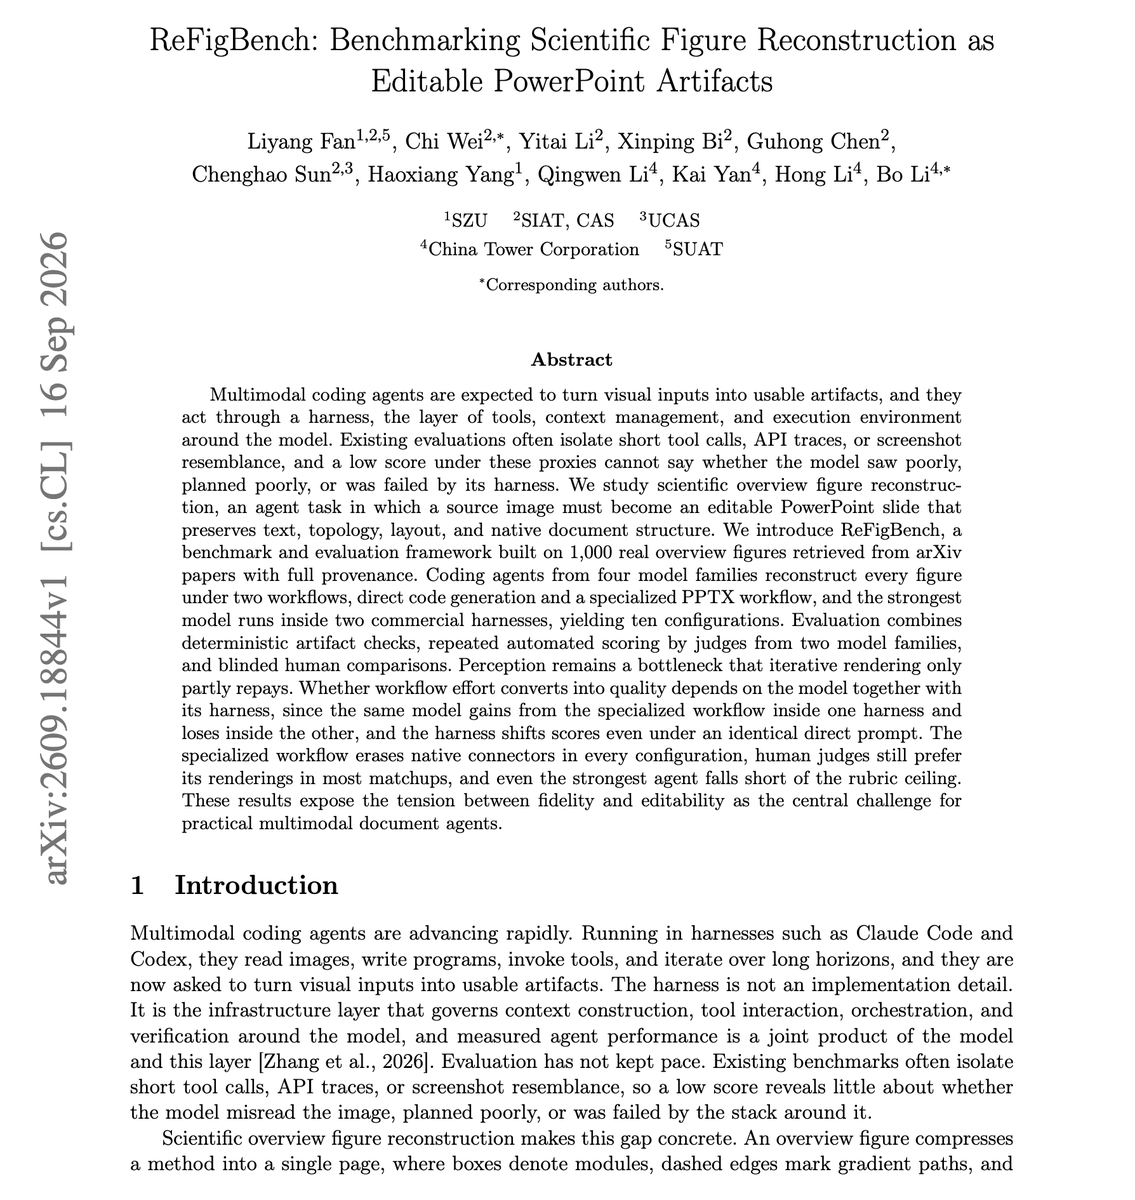
Impressive paper showing how much the harness changes a coding agent's results. Harnesses do play a huge role in what you are getting out of the models. GPT-5.5 was run inside both Claude Code and Codex on the same 1,000 tasks. With a specialized PowerPoint workflow, it improved inside one harness and got worse inside the other. The harness also changed scores when the prompt was identical. ReFigBench asks coding agents to rebuild real arXiv overview figures as editable PowerPoint slides that keep the text, layout and connections. It covers ten configurations across the GPT, Claude, MiMo and MiniMax families, scored by artifact checks, two families of LLM judges and blinded human comparisons. Perception is still the main bottleneck. The specialized workflow removed native connectors in every configuration, yet human judges still preferred its renderings in most matchups. Paper: https://t.co/5buGY1XGxM Chat with Paper: https://t.co/G16VcCG6Kf