Harness-Zero distills agent harness into the model
A new method from Google and others uses an optimized harness only during training, raising macro task success from 23.3% to 44.3% without a specialized harness at deployment.

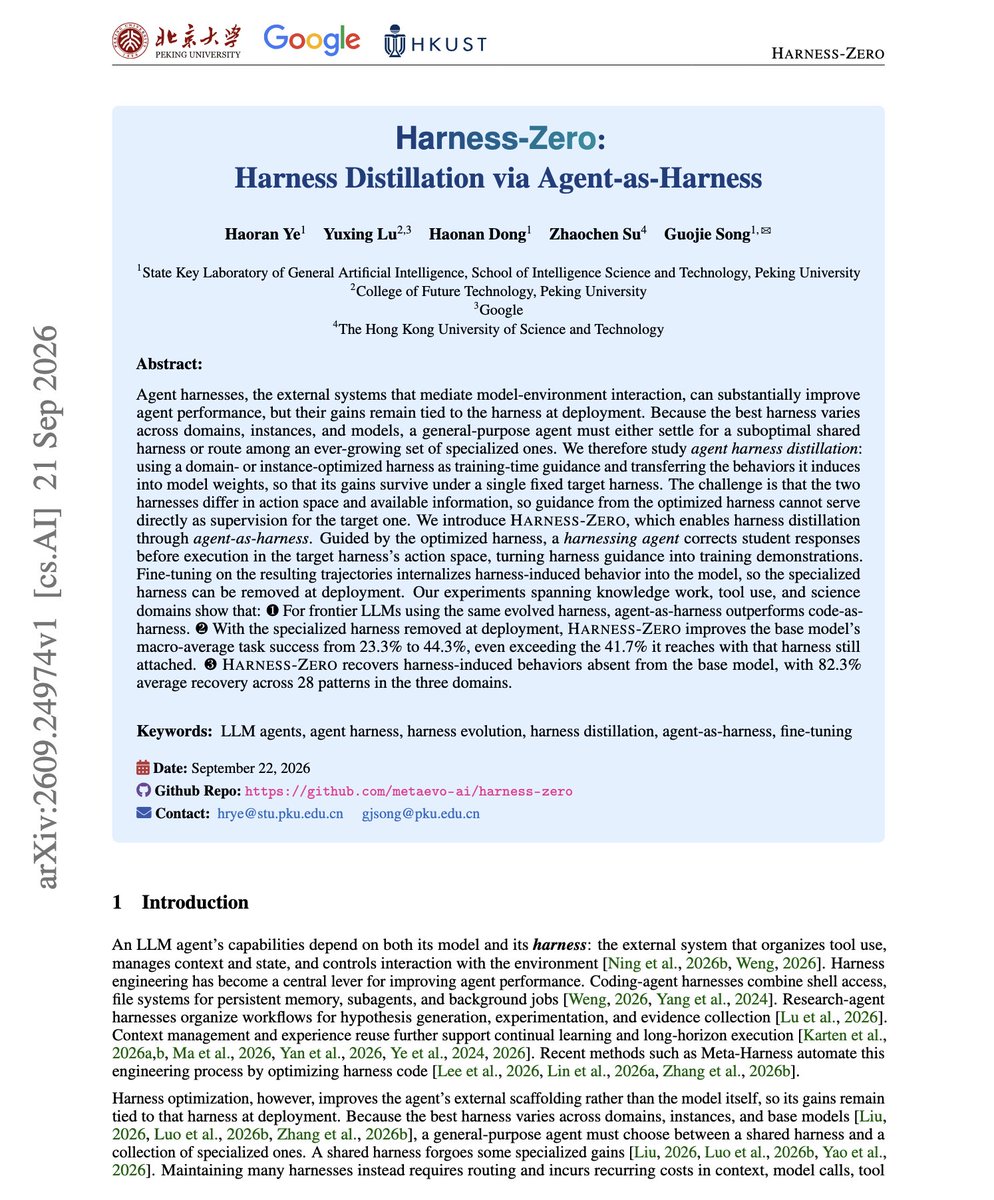
Super interesting paper from Google and colleagues. It studies where it's possible to distill an agent harness. With the specialized harness removed, macro task success goes from 23.3% to 44.3%. That is higher than the 41.7% the base model reaches with the harness attached. Harness-Zero uses the optimized harness only during training. The optimized harness and the deployment harness have different action spaces, so a harnessing agent guided by the optimized harness corrects the student's responses in the deployment action space before they run. Those corrected runs become the training demonstrations. Across 28 harness-induced behaviors in knowledge work, tool use and science, 82.3% are recovered on average. For frontier models using the same evolved harness, the agent-as-harness form also beats the code-as-harness form. It remains to be seen how robust the approach is, but it's very interesting to see potential in harness distillation. Paper: https://t.co/AiBm1p17Lp Chat with Paper: https://t.co/Nda4XsZgrh