Foreman: Codex does the work while Jev scores it from the sidelines
Someone placed Jev above Codex as a supervisor, producing 9 dimensions of calibrated probabilities in one parallel call, with a Python policy deciding whether to continue, stop, verify, or finish.
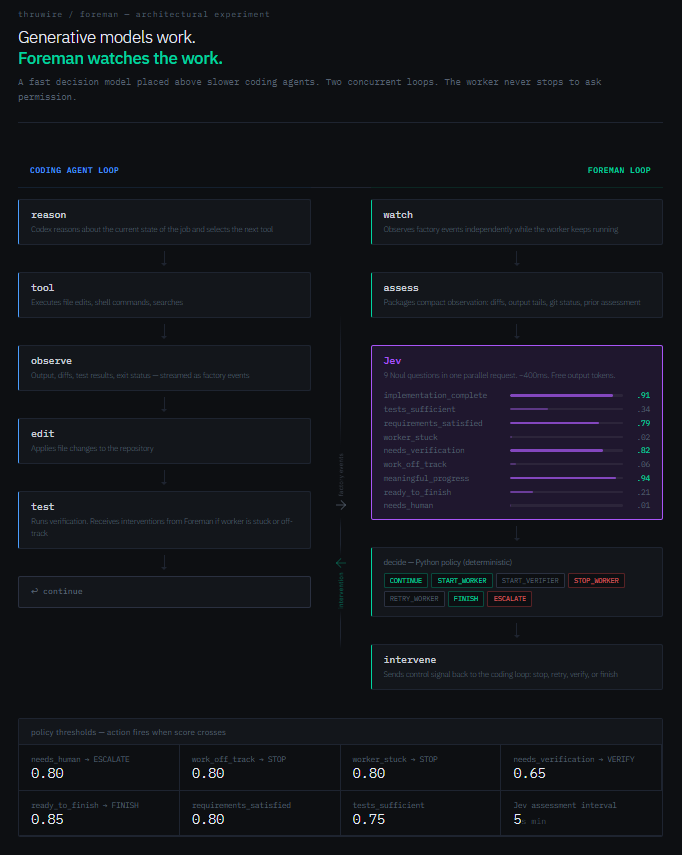
someone put Jev above Codex to watch it work. the problem with every coding agent today: the agent reasons, edits files, runs tests - and decides when it's done. that's the bug. a model that's stuck can't reliably tell you it's stuck. Foreman fixes this with two concurrent loops: Codex works. Jev watches. the worker never stops. Foreman independently scores 9 dimensions in one parallel Jev call: implementation_complete: .91 tests_sufficient: .34 worker_stuck: .02 needs_verification: .82 ready_to_finish: .21 9 calibrated probabilities. one request. 400ms. a deterministic Python policy reads those numbers and acts: CONTINUE / STOP_WORKER / VERIFY / FINISH / ESCALATE Jev assesses. Python decides. Codex executes. the thresholds that matter: worker_stuck hits 0.80 - worker terminated. needs_human hits 0.80 - autonomous work stops. ready_to_finish hits 0.85 - job complete. no frontier LLM judging if its own work is good enough. the builder is honest about it - this is an architectural experiment. false positives kill useful workers. Jev accuracy on this use case is unproven. but the architecture is the point.
This post quotes another post: x.com/p0lybender/status/2105657133702193458