Six hours with Jev: using its choice, score and noul question types
After six hours of using Jev, the author explains how its single API call answers choice, score and yes/no questions in parallel in about 200ms, and how to route by confidence to humans or larger models.
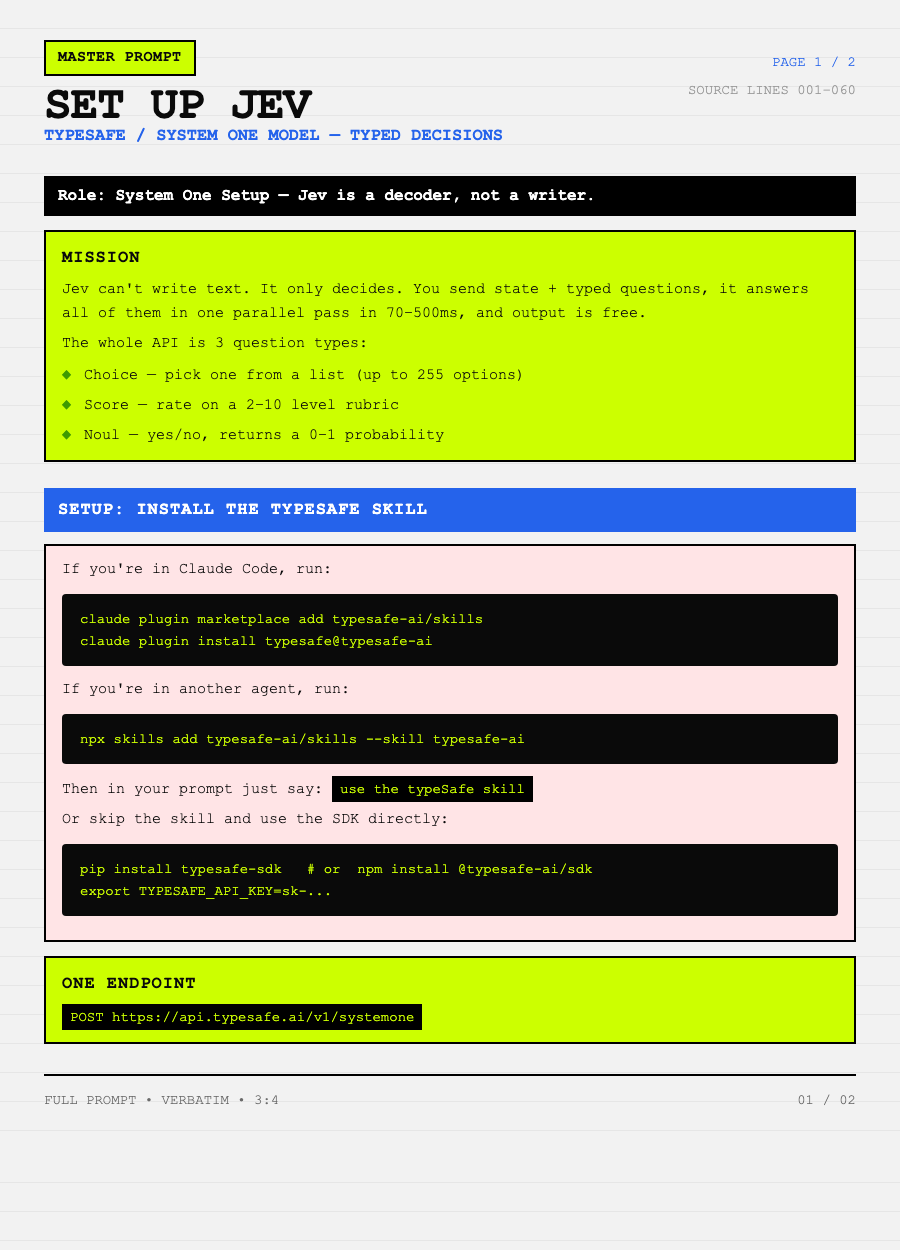
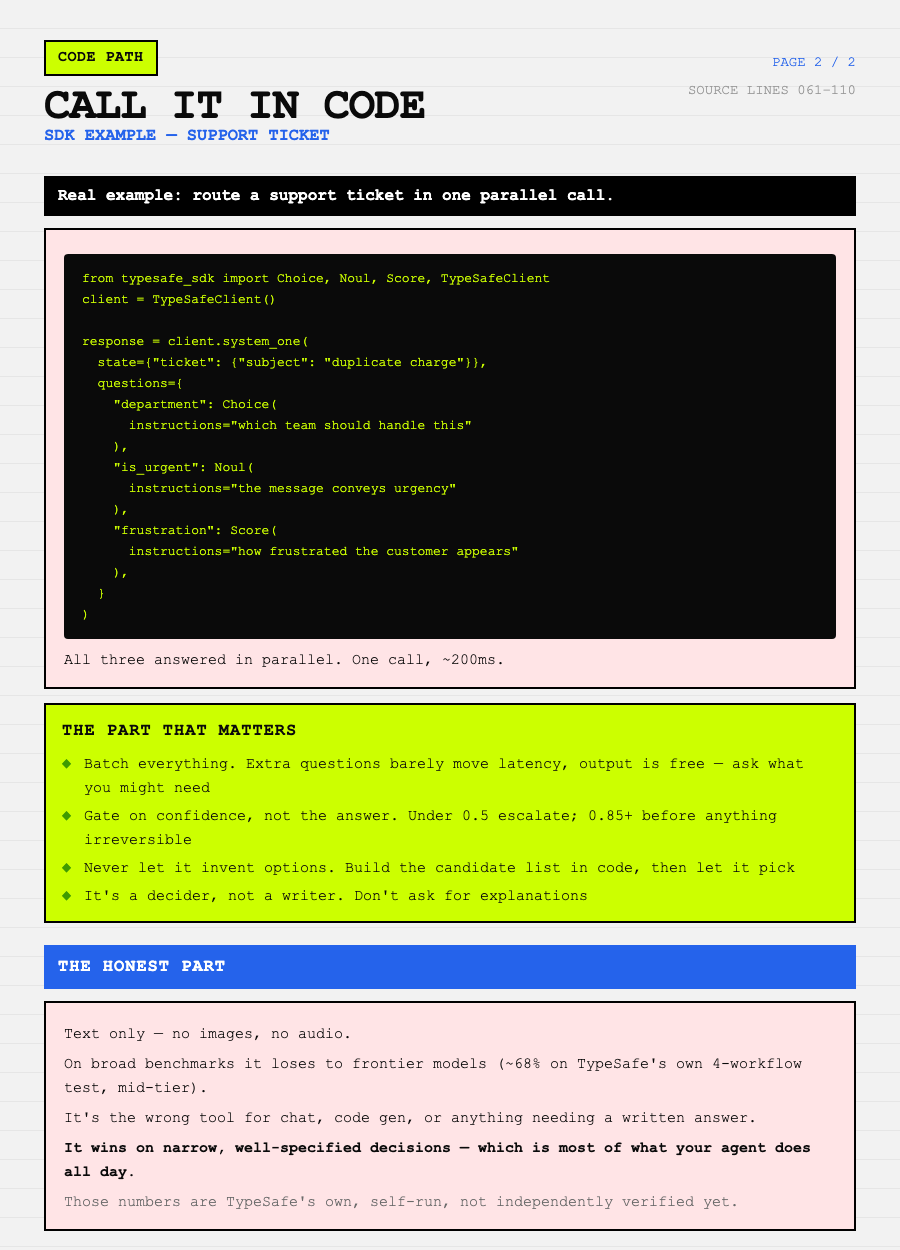
jev is insane!!😳 i've been using it for the past 6 hours and heres how i would recommend to use it to 100x your workflow. quick context: jev is a model that can't write text. it only decides. you send it state and questions, it answers all of them in one pass, 70-500ms, and output is free. here's how to actually use it. the whole api is 3 question types: 1. choice — pick one from a list (up to 255 options) 2. score — rate on a 2-10 level scale 3. noul — yes/no, returns a 0-1 probability one endpoint: POST https://api.typesafe.ai/v1/systemone setup: claude code → claude plugin marketplace add typesafe-ai/skills elsewhere → npx skills add typesafe-ai/skills --skill typesafe-ai then just tell your agent: "use the typesafe skill" (or skip it: pip install typesafe-sdk) a real example. support ticket: from typesafe_sdk import Choice, Noul, Score, TypeSafeClient client = TypeSafeClient() response = client.system_one( state={"ticket": {"subject": "duplicate charge", "messages": [...]}}, questions={ "department": Choice(instructions="which team should handle this", criteria={...}), "is_urgent": Noul(instructions="the message conveys urgency"), "frustration": Score(instructions="how frustrated the customer appears", criteria=[...]) } ) it answers all three in parallel. one call, ~200ms. the part that matters: batch everything. adding questions barely moves the latency, and output is free. ask every question you might need, even ones you'll throw away. gate on confidence, not the answer. under 0.5 escalate to a big model or a human. 0.85+ before anything irreversible. never let it invent options. build the candidate list in code, then let it pick. it's a decider, not a writer. don't ask for explanations. the honest part: text only. no images, no audio. on broad benchmarks it loses to frontier models — ~68% on TypeSafe's own 4-workflow test, about mid-tier. it's the wrong tool for chat, code gen, or anything that needs a written answer. it wins on narrow, well specified decisions. which is most of what your agent does all day. and those numbers are TypeSafe's own, self-run, not independently verified yet. early access is waitlisted. many people got in thesame day http://typesafe.ai
This post quotes another post: x.com/painn_x/status/2100703773131718763