Cognition releases SWE-2, still behind GPT-6 Astra on benchmarks
SWE-2 is post-trained on Kimi K3 and scores 50% on FrontierCode, beating Grok 4.6 and GPT-5.6 Sol but trailing Fable 5.1 and Astra, with costs up to 70% lower.
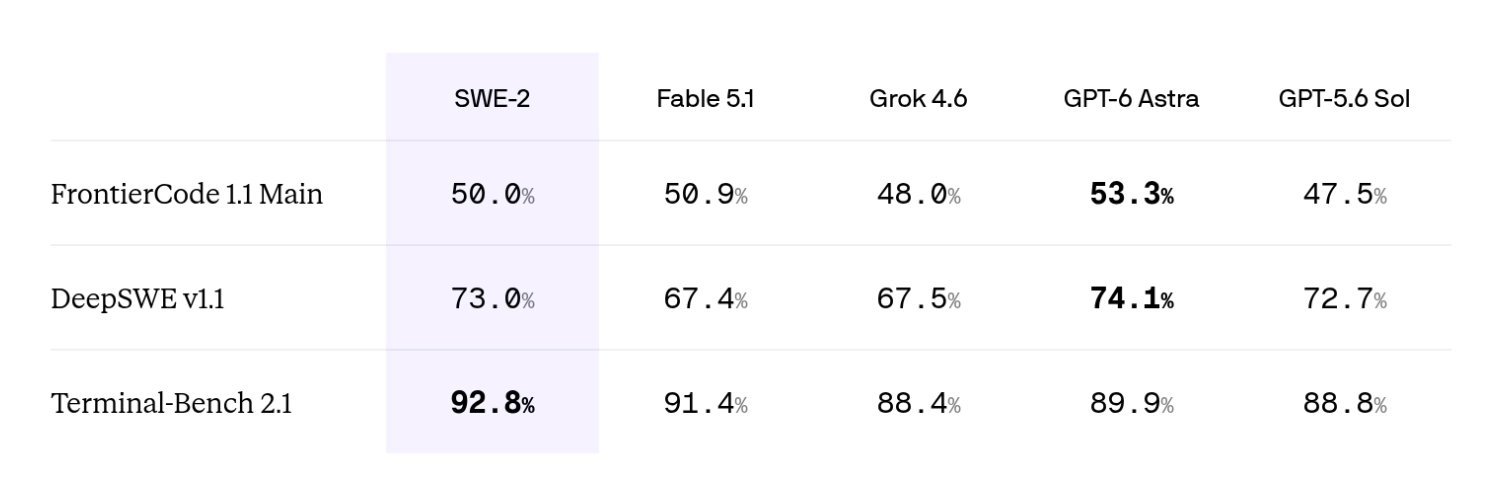
Cognition Has Announced SWE-2 - SWE-2 is post-trained on Kimi K3 and uses a new RL recipe scaled to trillions of parameters. - On FrontierCode, it scores 50.0%, beating SWE-1.7, Grok 4.6 and GPT-5.6 Sol, while staying behind Fable 5.1 and GPT-6 Astra. - The biggest advantage is cost: up to 70% lower than Fable 5.1 and Astra. - It looks pretty good to me, but benchmarks don't show everything and models can be benchmark-maxxed. - They're still using Terminal-Bench 2.1. Where is Terminal-Bench 4.0? It makes me think they showed the benchmarks where SWE-2 looks best.
This post quotes another post: x.com/cognition/status/2098069235733823965