Multi-model benchmark: Gemini 4 Argon scores 40.7, third behind Muse Wonder and Opus 5.5
Averaged over three runs, Muse Wonder leads at 42 and Opus 5.5 follows at 41.7, with Gemini 4 Argon (high) at 40.7 in third; DeepSeek V4.1 Flash varies widely.
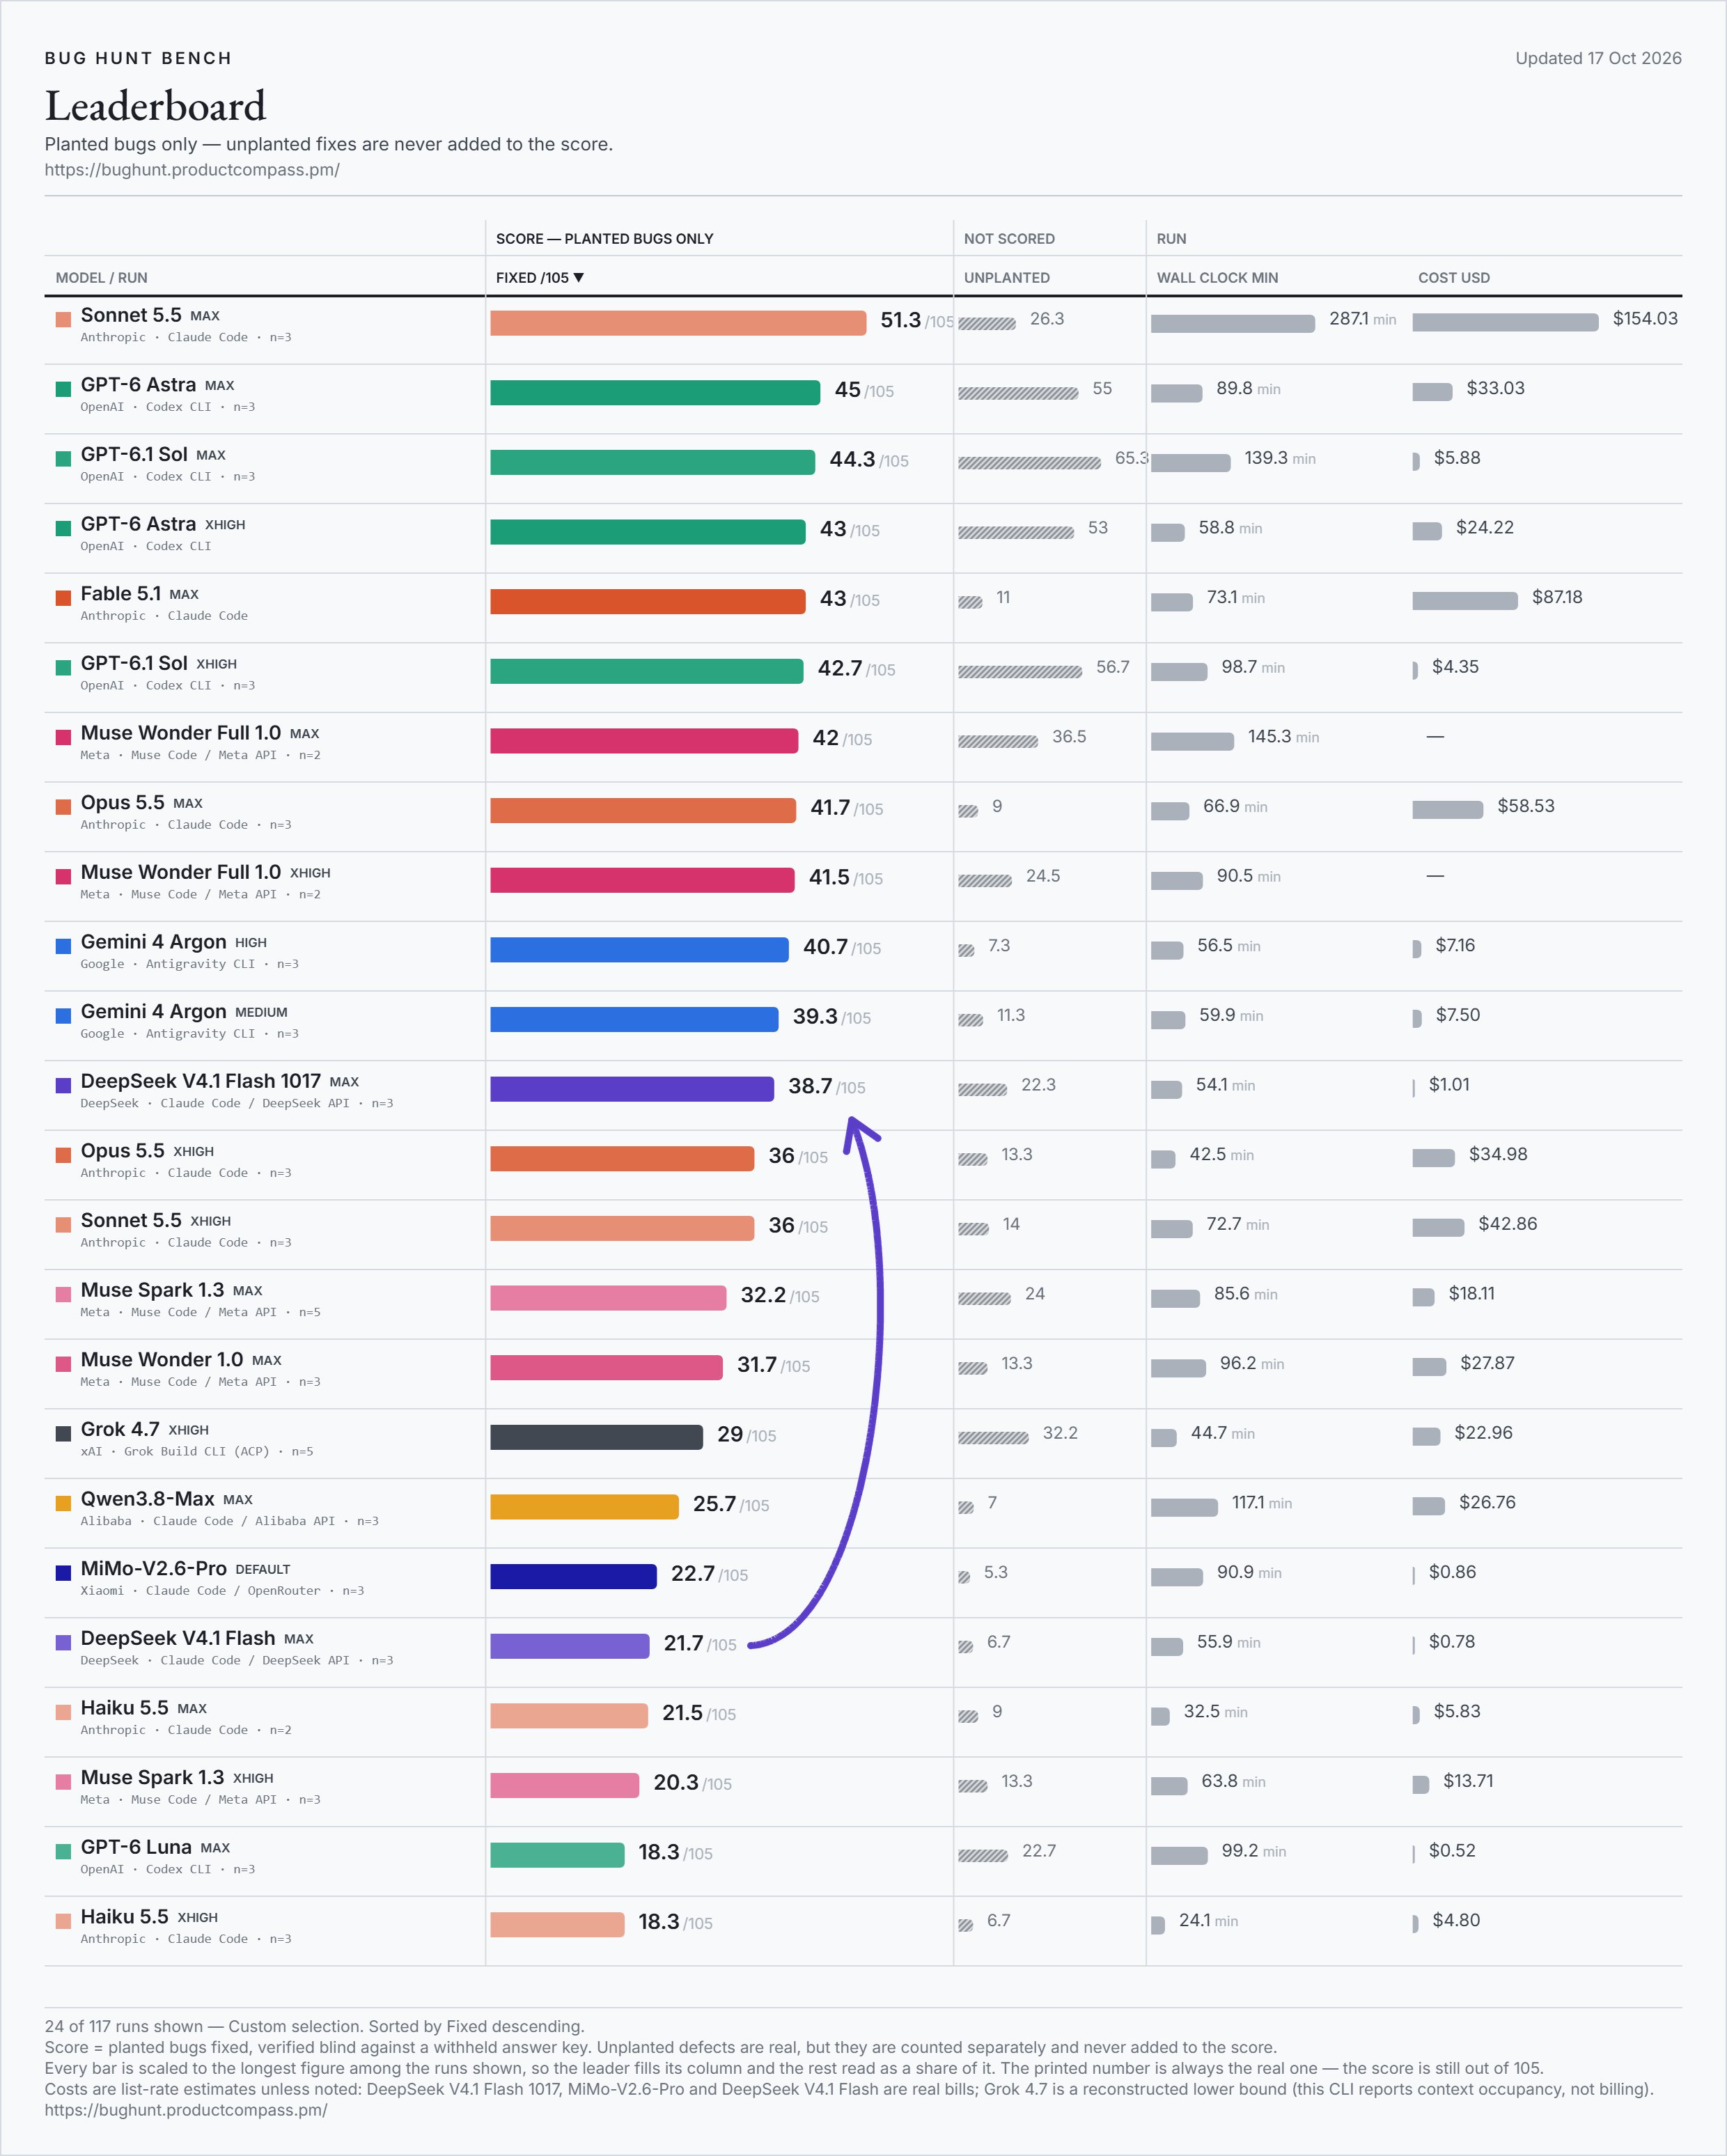
Oh wow. DeepSeek V4.1 Flash 1017 varies much more than usual. After three runs: Muse Wonder Full 1.0 (max): 42 Opus 5.5 (max): 41.7 Gemini 4 Argon (high): 40.7 DeepSeek V4.1 Flash 1017 (max): 38.7 🟣 Grok 4.7 (xhigh): 29 Qwen3.8-Max (max): 25.7 DeepSeek V4.1 Flash (max): 21.7 🟣 GLM-5.3 (max): 19 Individual scores: 34, 37, 45 Next: high effort level, n=3 Later: low effort level, n=3 Last: n=5 for max, just in case
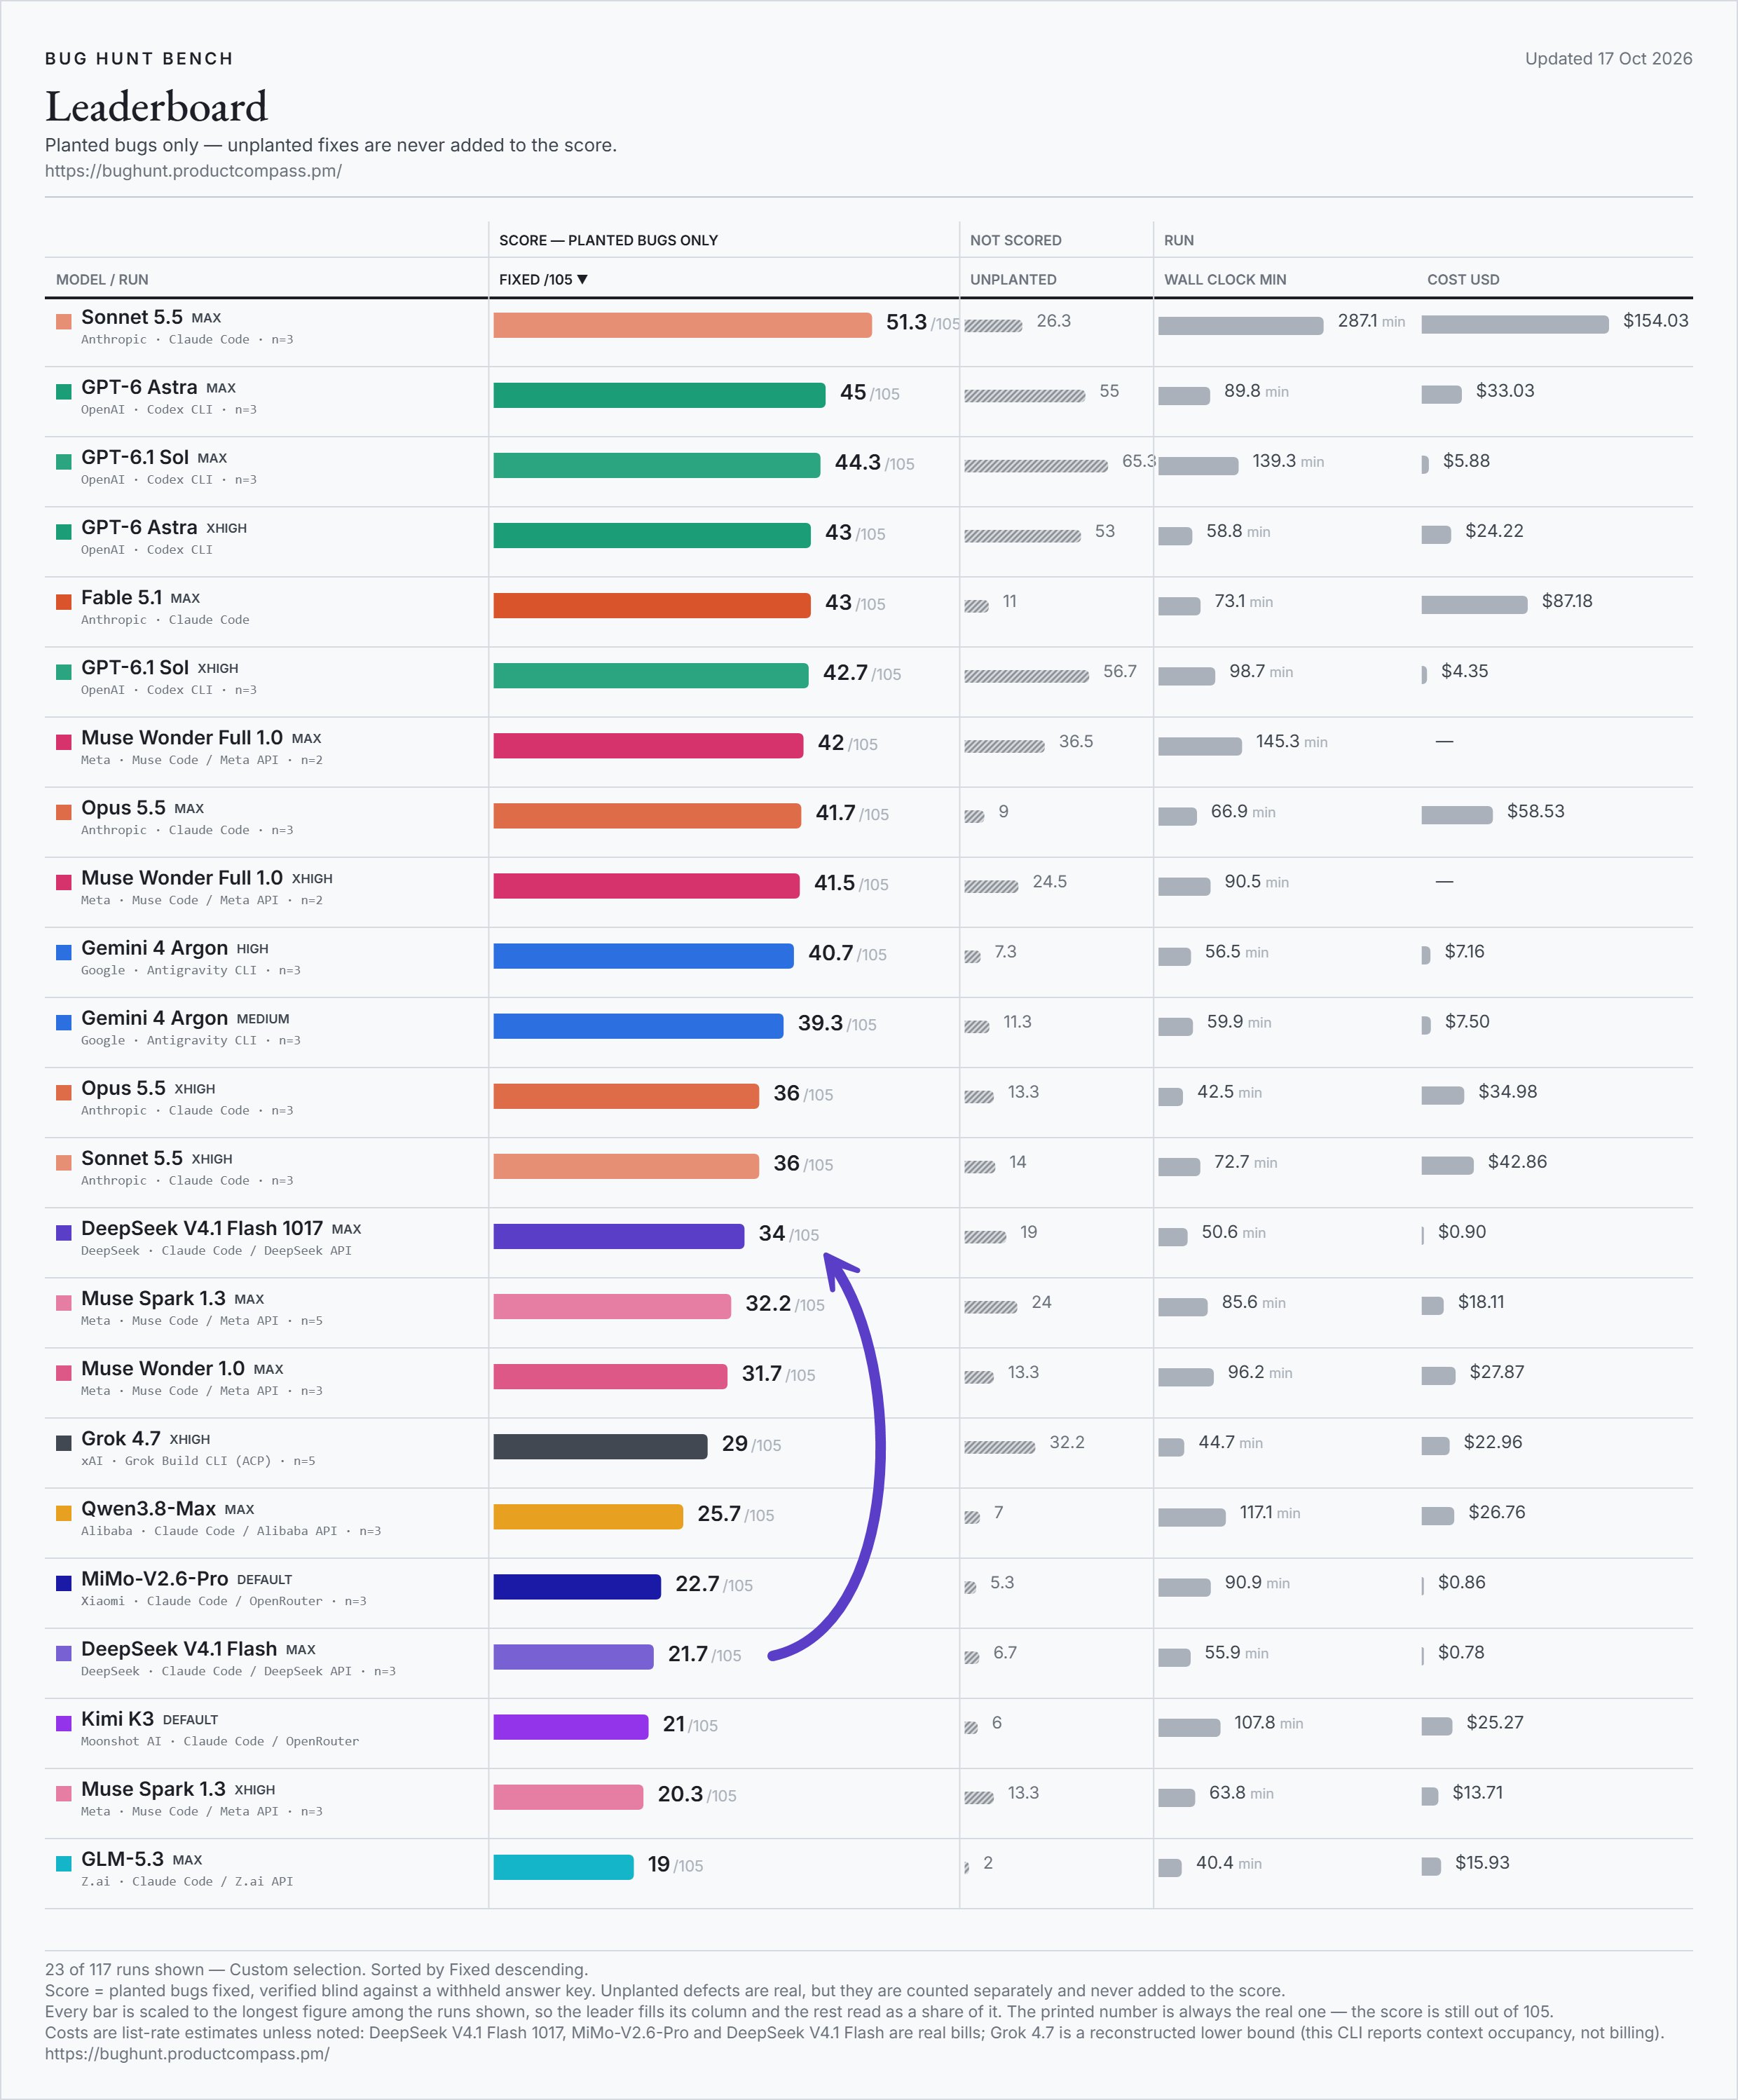
So I tested DeepSeek V4.1 Flash 1017 on real work. 2 repos. 105 hidden bugs. Find and fix what you can. The first results: Muse Wonder Full 1.0 (max): 42 Opus 5.5 (max): 41.7 Gemini 4 Argon (high): 40.7 DeepSeek V4.1 Flash 1017 (max): 34 🟣 Grok 4.7 (xhigh): 29 Qwen3.8-Max (max): 25.7 DeepSeek V4.1 Flash (max): 21.7 🟣 GLM-5.3 (max): 19 A great improvement. Strange that the model wasn't labeled V4.2. 763B params. The weights are already on Hugging Face. I expect the score to change by ~1.7 points after repeating the test 3 times. More data and results at different effort levels dropping in this thread very soon 🧵