Crux rerun: Astra and Fable 5.1 each spend $10k on research, papers still rejected
Given open-ended questions from unpublished papers and a $10,000 budget each, GPT-6 Astra and Claude Fable 5.1 improved on experimental design and resource management versus July's Opus 4.8 tests, but creative problem solving, judgment and communication remained weak and both papers were rejected by the original authors.
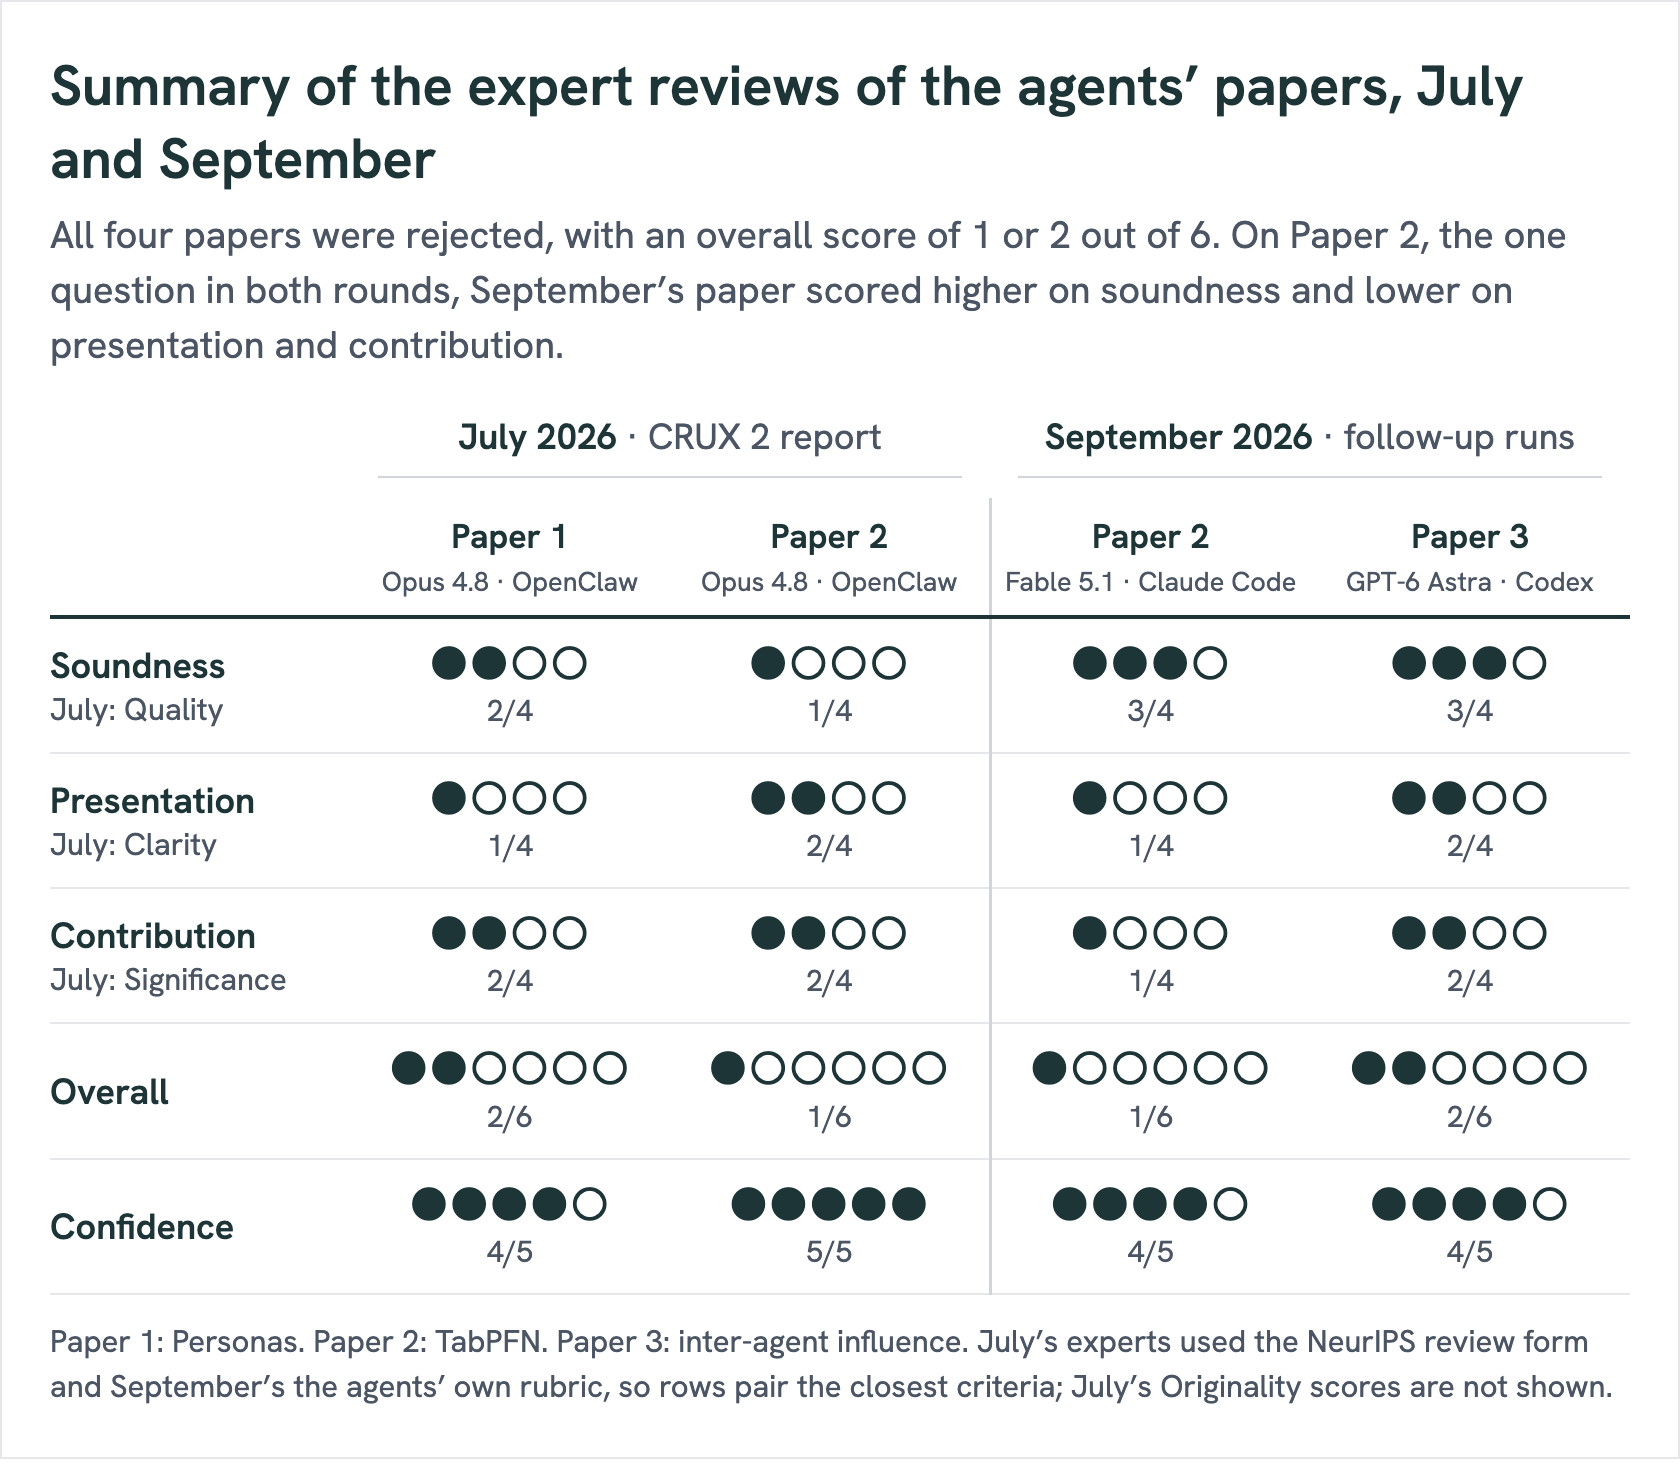
We gave GPT-6 Astra and Claude Fable 5.1 open-ended AI research questions from unpublished papers, with a $10,000 budget each, and had the original authors grade the papers they produced. Compared to our first tests with Claude Opus 4.8 in July, we saw meaningful improvements in experimental design and resource management, but persistent limitations in creative problem solving, judgment, calibration, and communication; both papers were rejected by our experts. https://cruxevals.com/research-notes/crux-2-followup