Running 11 open-weight models locally on a Mac mini for 19,019 Gettysburg rewrites
The author ran 11 open-weight models locally on a Mac mini; DeepSeek V4.1 Flash and GLM-5.3 Flash looked stable but drifted back toward Lincoln's original wording, suggesting memorization, while the largest models streamed from SSD and took ~36 of 45 hours.
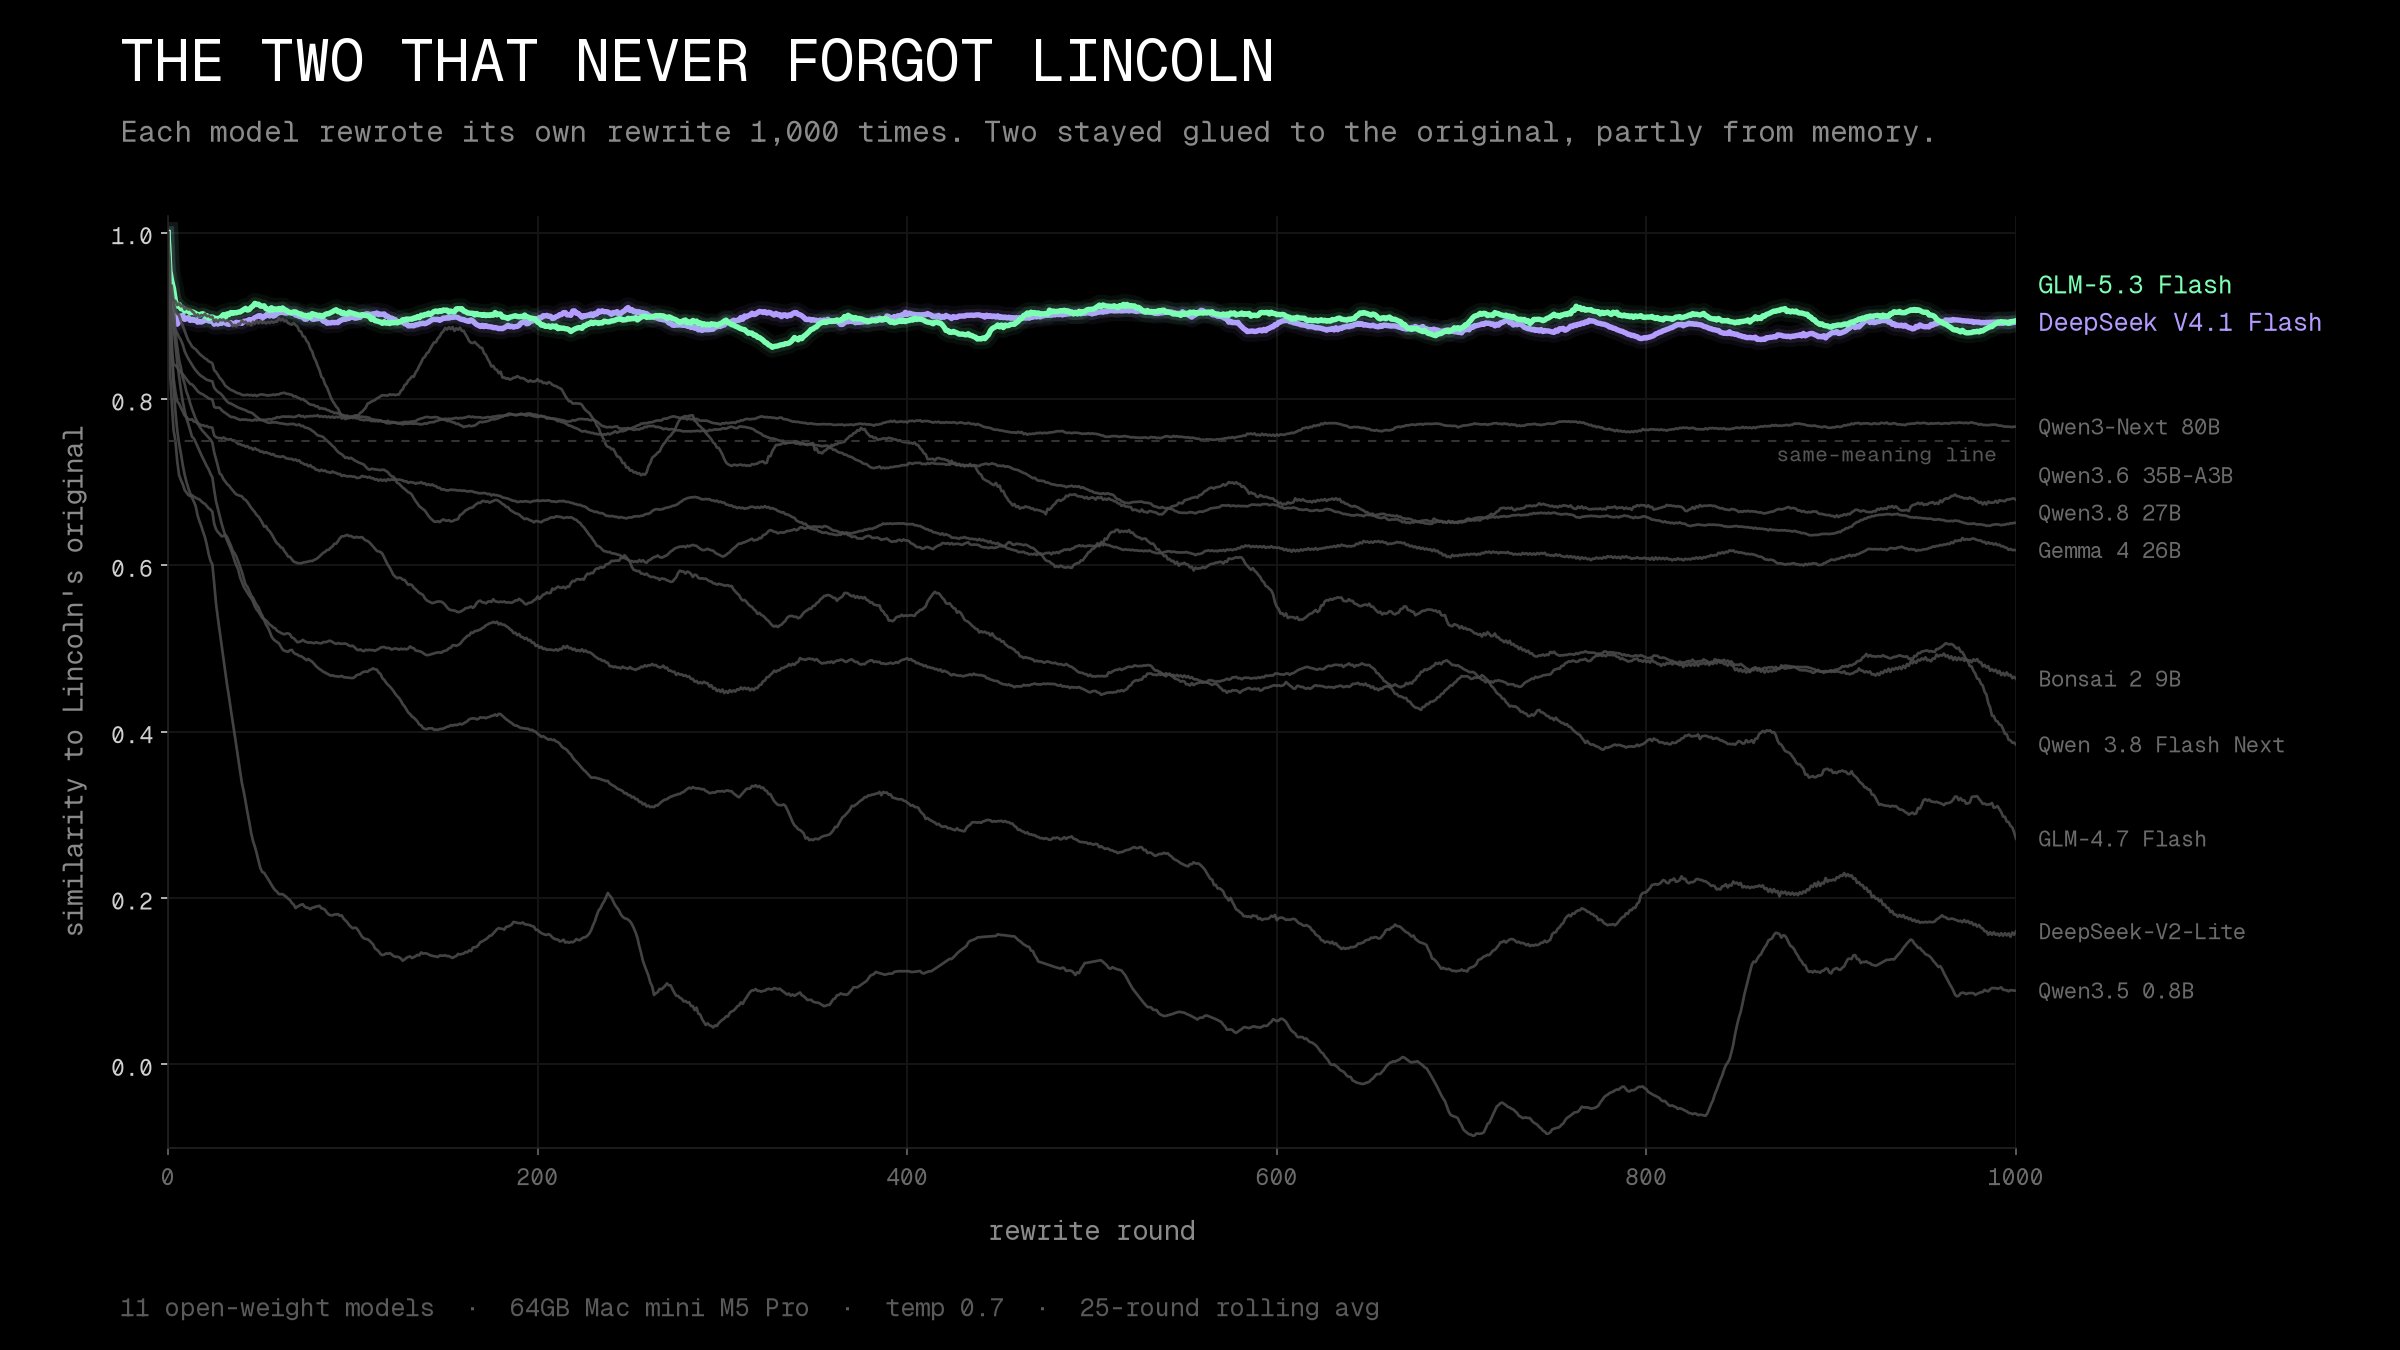
Last week I said I still want models open even though anyone can strip the safety training off. This weekend, running local AI on my Mac mini, 11 open-weight models rewrote the Gettysburg Address 19,019 times and the two biggest kept finding their way back to Lincoln. What I learned: 1) GLM-5.3 Flash from @Zai_org and DeepSeek V4.1 Flash from @deepseek_ai looked rock stable until I read the outputs. 86 of GLM's 1,000 rewrites open with "Four score", and by round 1,000 both were closer to Lincoln's original wording than at round 1. Part of what looked like stability was memory. 2) The small models had nothing to fall back on and drifted off. DeepSeek-V2-Lite turned the 278-word speech into 13 words about advancing your career, and Qwen3.5 0.8B ended up on project planning. I think it's the same pull the big models felt (each one slides toward whatever its training data made most familiar), it just landed on workplace topics instead of Lincoln. 3) A single score would have hidden all of this. I only caught it because I could open the files and read them. 4) Running locally meant the weights never changed mid-run and I paid nothing per rewrite. Anyone with a Mac can rerun it and check my numbers. 5) The two biggest models don't fit in 64GB, so they streamed off my SSD and ate about 36 of the 45 hours. They still ran. Most of the others finished 1,000 rewrites in under an hour. The smallest did 350 tok/s in under 1GB of memory, and Qwen3-Next 80B, an 80B mixture-of-experts, did 73 tok/s in 45GB. 6) Using a famous text baked memorization into the result. The next run adds a text no model could have seen, so I can separate stability from recall. The very reason why I want weights open. A benchmark score wouldn't have shown this and no API would let me run 19,019 rewrites for free. All of it is public, so you can check my work or find what I missed. If you've run long chained tests on your own machine, I'd love to hear what you found.
This post quotes another post: x.com/pratikg/status/2112217547366088851