Practitioners call Jev a classifier, benchmark trails bge-small
Industry practitioners say Jev is essentially a fixed-choice classifier, scoring 83.2% on banking77 versus 93.3% for bge-small plus logistic regression, and that its "can't hallucinate" claim only guarantees valid format.
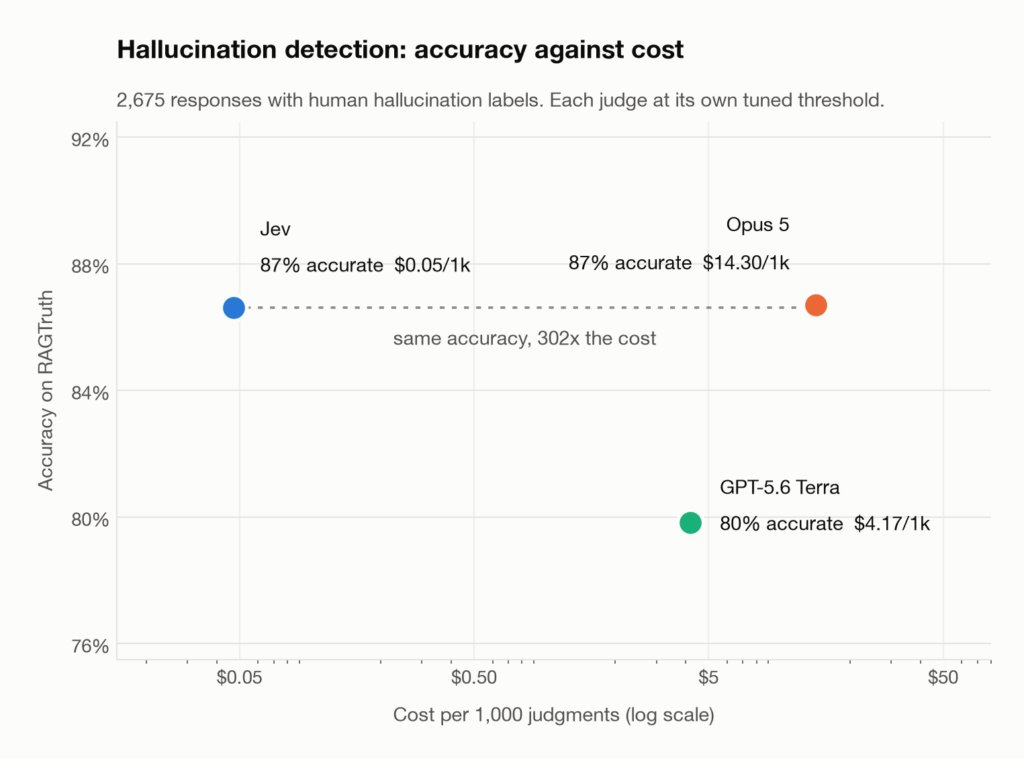
Jev is getting called out hard by people who actually work in this space the pushback boils down to this. jev isn't a new kind of ai. it's a classifier, returning probabilities over a fixed set of choices instead of generating text. zero-shot classifiers have existed since 2019, hugging face made this basically one line of code years ago the "can't hallucinate" claim is the part getting picked apart the most. typesafe's own docs admit that number isn't measured, what they actually guarantee is the output matches the allowed format. that stops an invalid answer, not a wrong one. those are very different guarantees someone ran an actual head to head on a real benchmark. a simple bge-small embedding model plus logistic regression scored 93.3% on banking77. jev scored 83.2%, and the simple setup ran locally in about 9 milliseconds but not everyone's dismissing it either. one data scientist said the speed and price point genuinely unlocks stuff that wasn't feasible before, like reranking search results in real time as a page loads, since running a full llm for that used to be too expensive and the fair counterpoint keeps coming up too. if this is really nothing new, why is there no open competitor matching it yet so maybe it's not a new category of ai. maybe it's just really good engineering wrapped in a name that makes it sound bigger than it is