rapid-mlx ships DeepSeek V4.1 Flash MLX quant for 256GB+ Macs
An MLX quantization for 256GB+ Macs claims 35–44% lower mean KL, 85.1% vs 79.3% top-1, zero experts pruned across all 40x384, with Engram tables streamed from SSD.
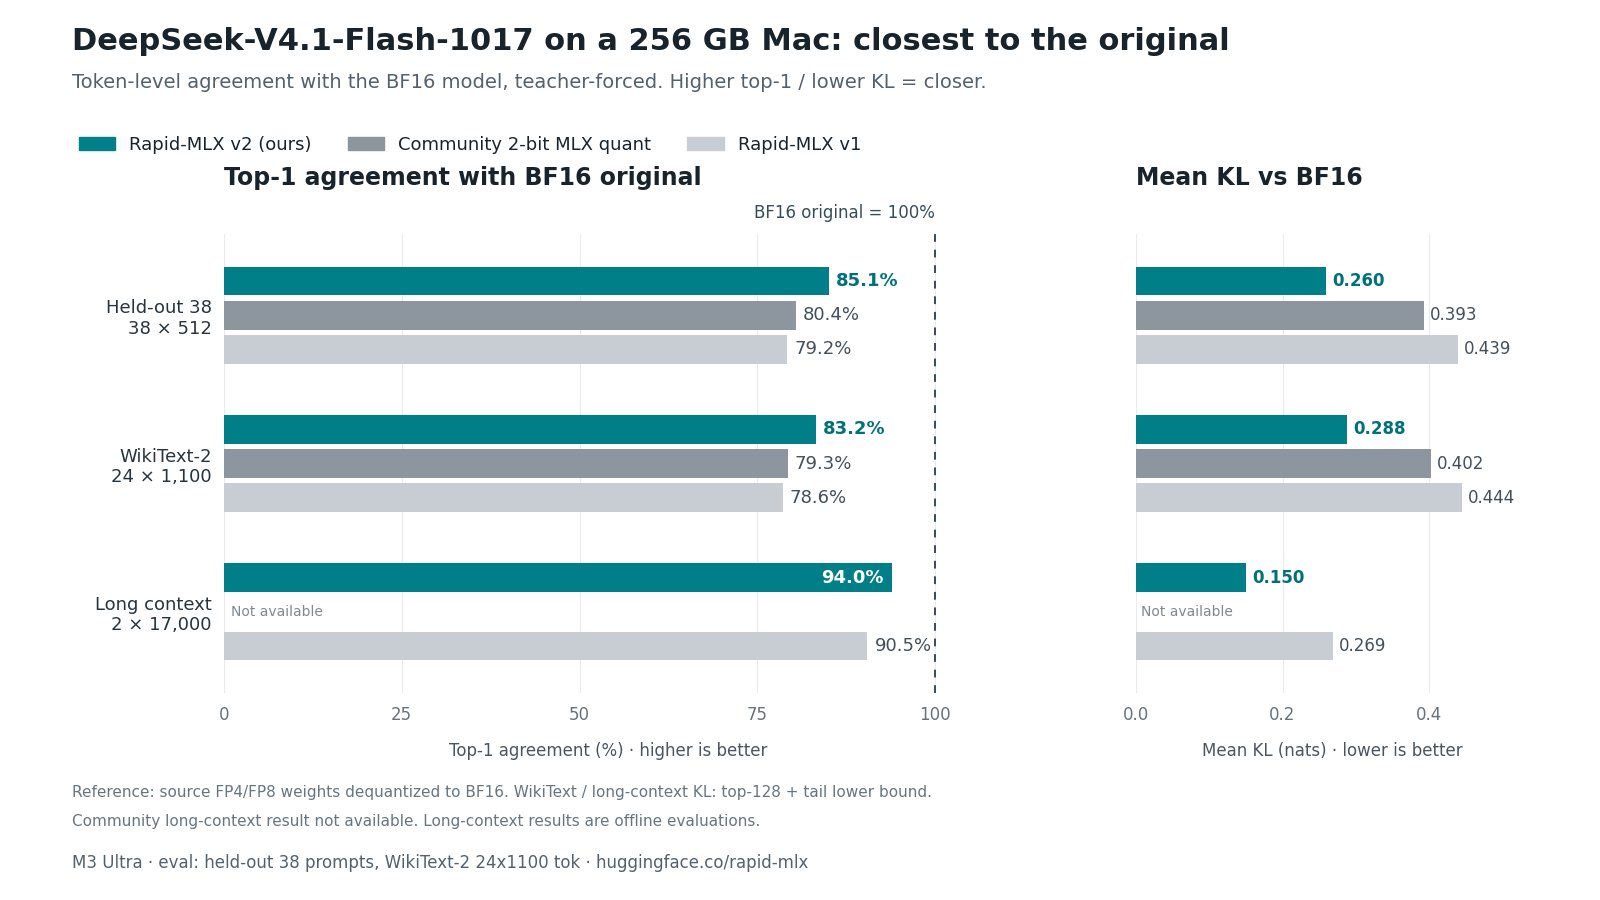
Running DeepSeek-V4.1-Flash locally shouldn't mean sacrificing quality. Meet the most faithful MLX quantization of DeepSeek-V4.1-Flash-1017. We built the ultimate version for 256GB+ Macs, maximizing both quality and speed. 👑 The New Standard for MLX: ✅ Highest Quality: 35–44% lower Mean KL. Crushes the leading 2-bit MLX quant (85.1% vs 79.3% top-1). ✅ No Compromises: ZERO experts pruned. All 40x384 kept. ✅ Advanced Tech: Sequential quantization, sensitivity-driven mixed precision, and Engram tables streamed from SSD. ✅ Fastest Path: A major high-speed inference release is imminent. The best local DeepSeek-V4.1-Flash-1017 on Mac is ready. 🔗 Weights & comparisons: https://huggingface.co/rapid-mlx/DeepSeek-V4.1-Flash-1017-MLX
This post quotes another post: x.com/artificialanlys/status/2112218661432000694