DeepSeek V4.1 Flash wins 4 of 11 self-reported benchmarks vs Opus 5, priced 17–20x lower
Official numbers show wins on four agentic benchmarks but losses on HLE, Terminal-Bench, ProgramBench, NL2Repo and vision; the real edge is MIT open weights at $0.30/$1.20 per million tokens.
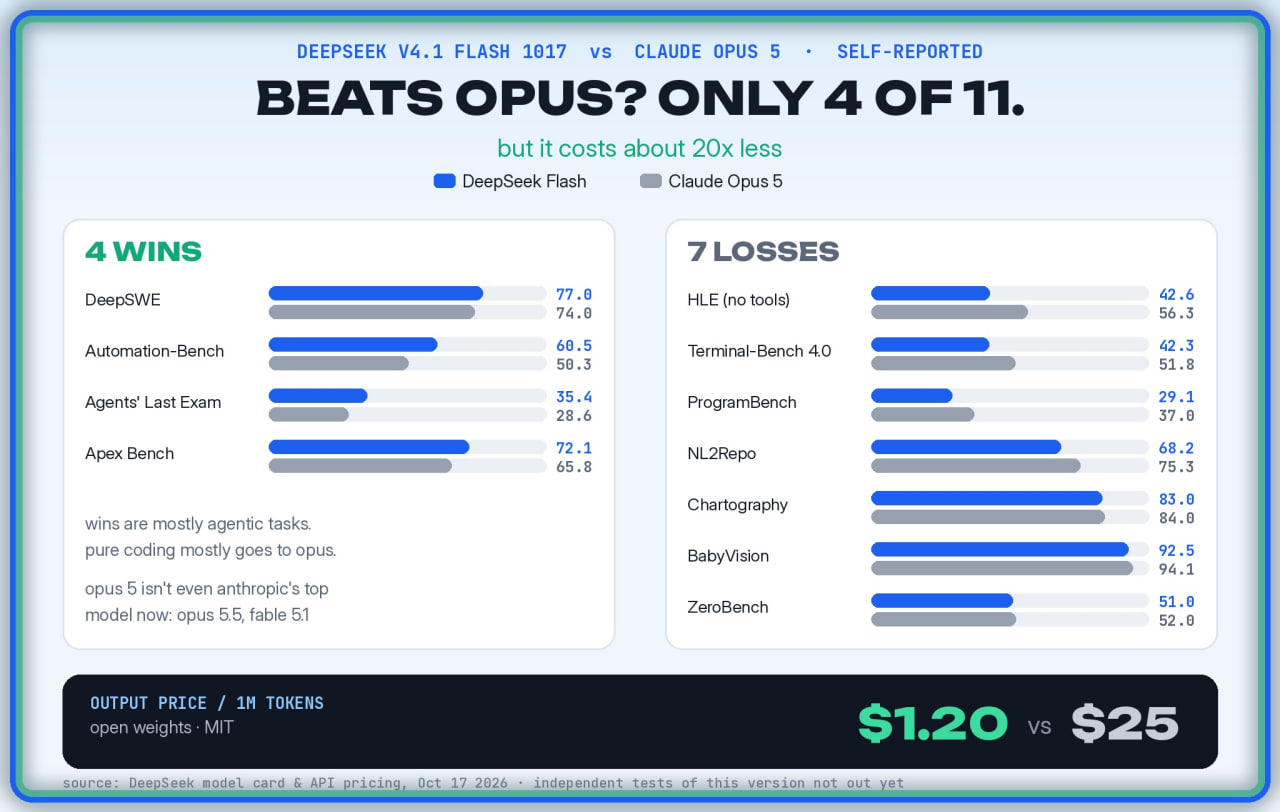
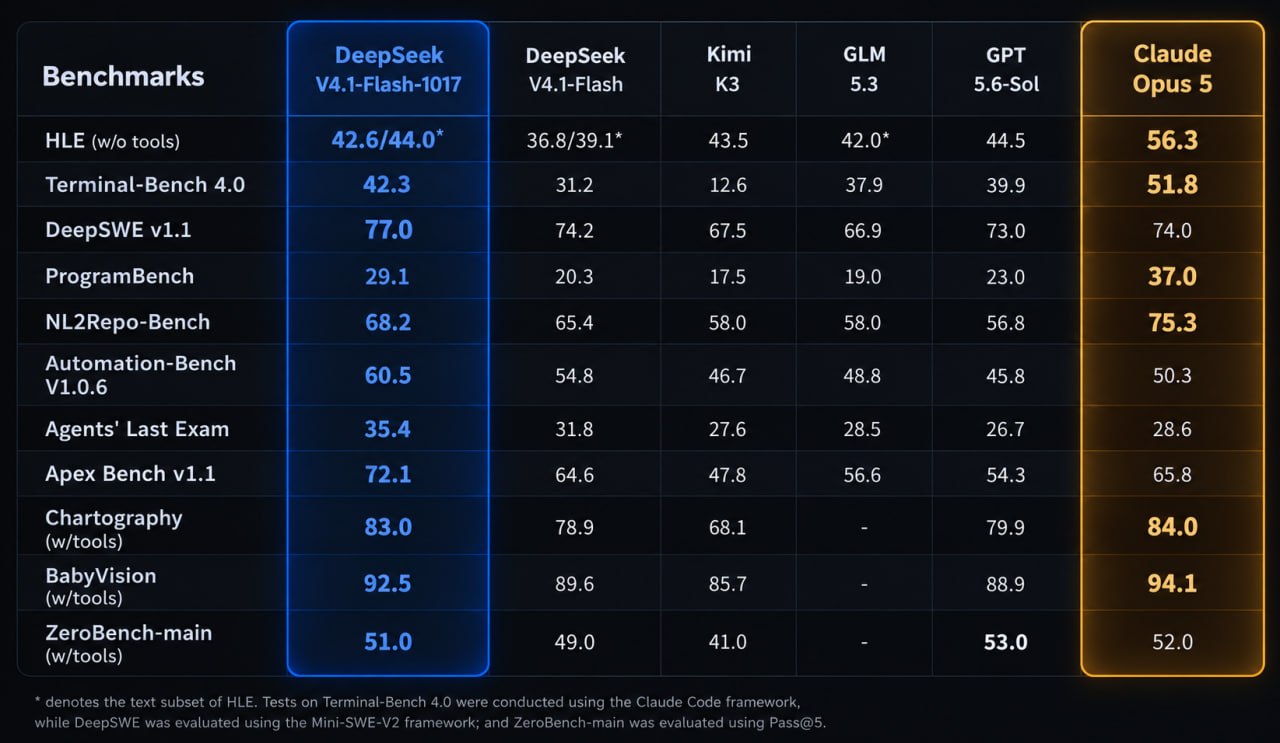
deepseek just dropped v4.1 flash 1017, and the headline everyone's sharing is "it beats claude opus 5." that's half true. in deepseek's own tests it wins 4 of 11 benchmarks against opus 5, mostly agentic ones: deepswe, automation-bench, agents' last exam and apex bench. it loses the other 7. hle, terminal-bench, programbench, nl2repo and the vision tests all go to opus. and opus 5 isn't even anthropic's top model anymore. opus 5.5 and fable 5.1 are already out. so the "flash beats the flagship" story doesn't hold. the real story is price. this is an open-weights model under mit. it costs $0.30 in and $1.20 out per million tokens. opus 5 costs $5 and $25. that's roughly 17-20x cheaper. on deepseek's own chart it solves a deepswe task for under $0.20. rivals land somewhere between $2 and $10+ per task. one catch: every number here is self-reported. independent tests of this version aren't out yet. if they hold up, the question stops being "is it smarter than claude." it becomes "why pay 20x more for the tasks where it's close enough."