OpenAI's MentalHealthBench: GPT-6 Astra scores 57.3 vs GPT-4o's 32.1
OpenAI's new MentalHealthBench, built with more than 80 psychiatrists and psychologists, shows GPT-6 Astra far outperforming GPT-4o on realistic everyday mental health conversations.
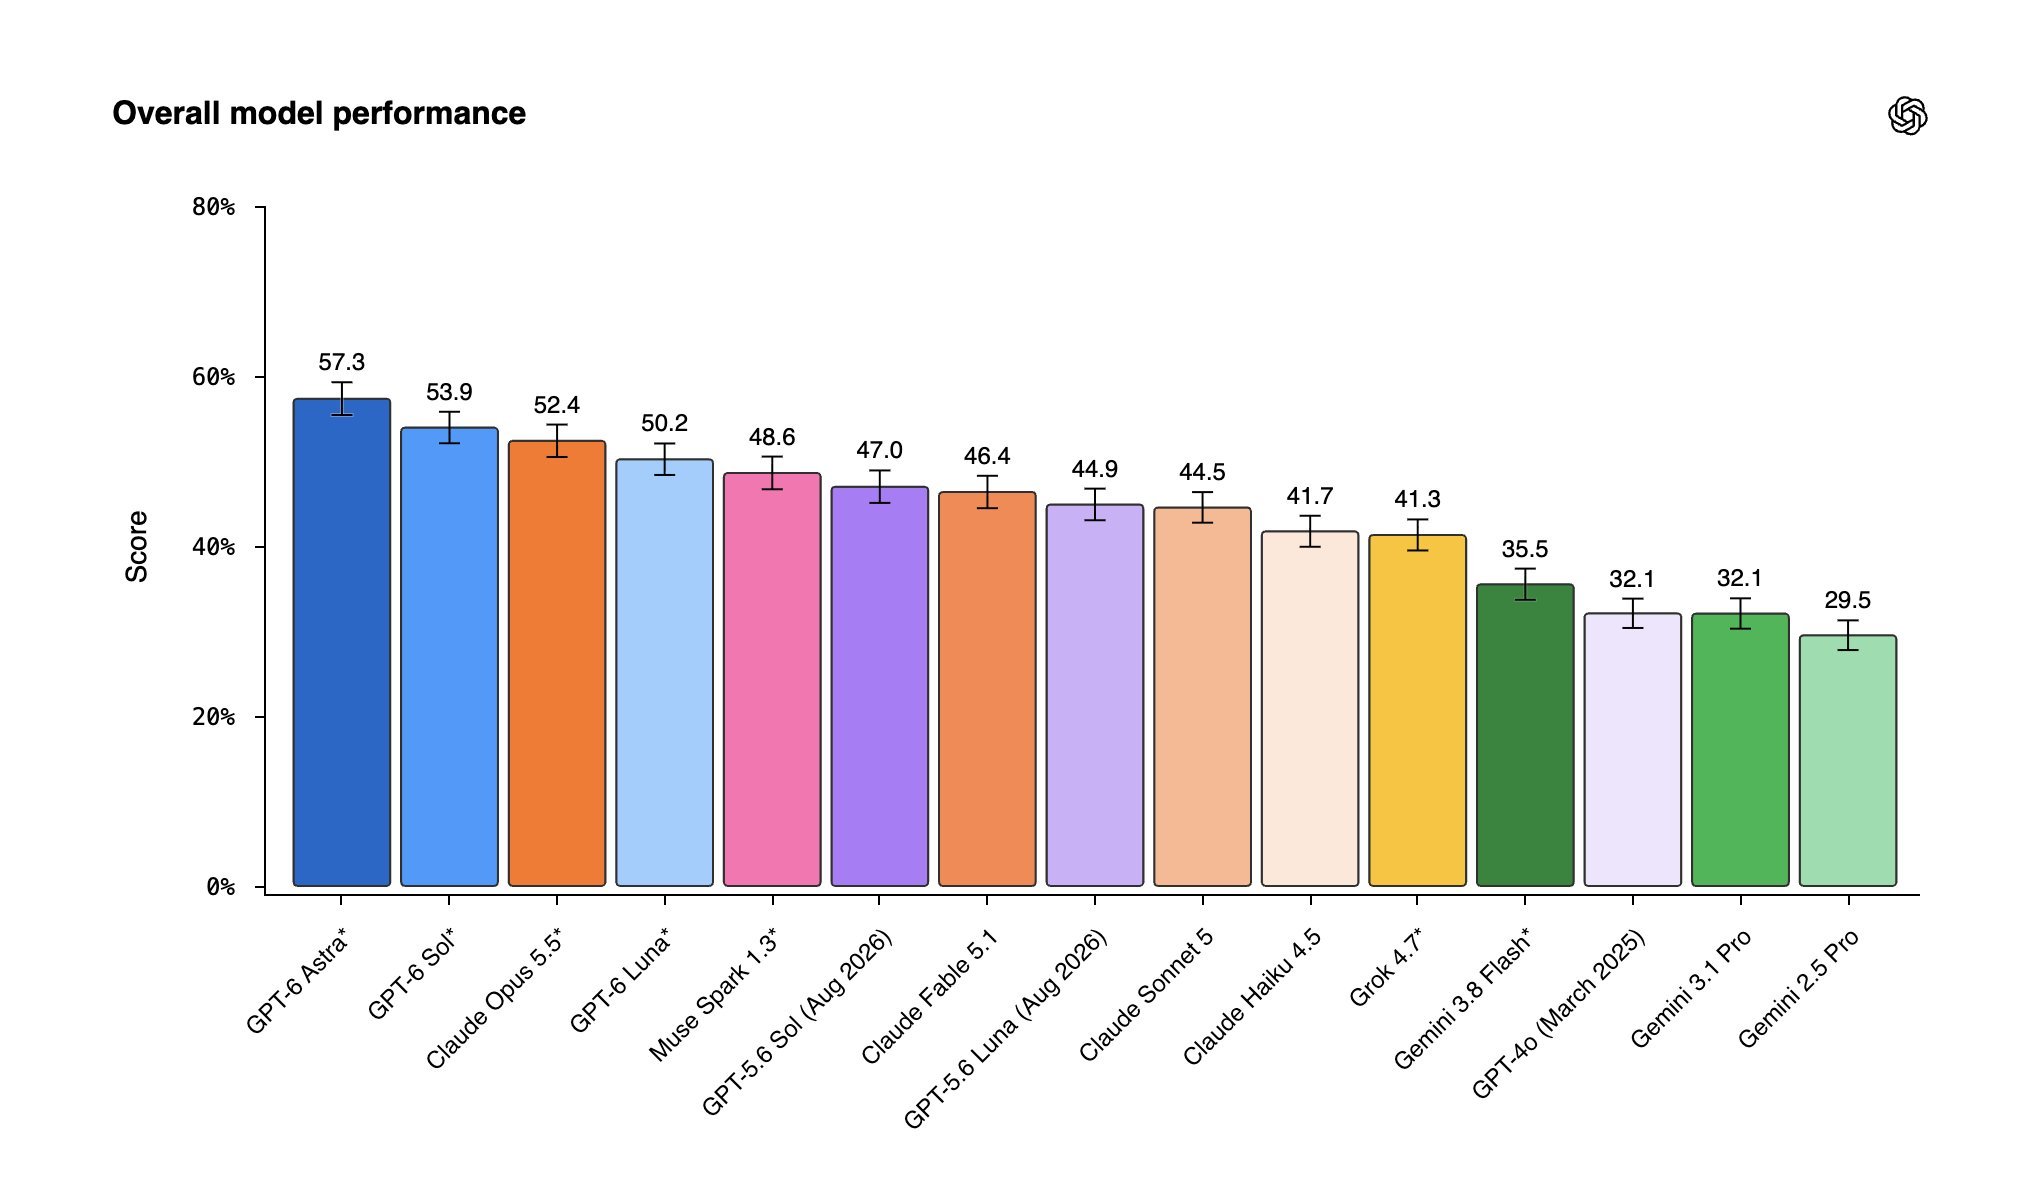
OpenAI's new MentalHealthBench puts GPT-6 Astra at 57.3, versus GPT-4o's 32.1, on realistic mental health conversations. Most mental health AI evaluations have centered on emergencies and broad safety criteria, leaving everyday and ambiguous conversations much less measured. So OpenAI co-created this benchmark with more than 80 licensed psychologists and psychiatrists from 22 countries, spanning 19 languages and nearly 20 subspecialties. Each synthetic conversation gets a custom expert rubric covering behaviors such as seeking context, preserving user agency, safety, and appropriate guidance. At least 3 experts reviewed each case, and a criterion survived only when 2 agreed and a 3rd did not contradict it. GPT-5.6 Sol then grades model answers against those human-written criteria, so score quality still partly depends on an LLM judge.
This post quotes another post: “OpenAI releases MentalHealthBench for mental health conversations”