Paper: Astra nears robot benchmark saturation but costs too much
A new paper testing GPT-6 Astra on 12 robot benchmarks finds near-saturation on LIBERO and 81.9% on RoboDojo, but one long episode costs ~9M tokens and nearly 2 hours.
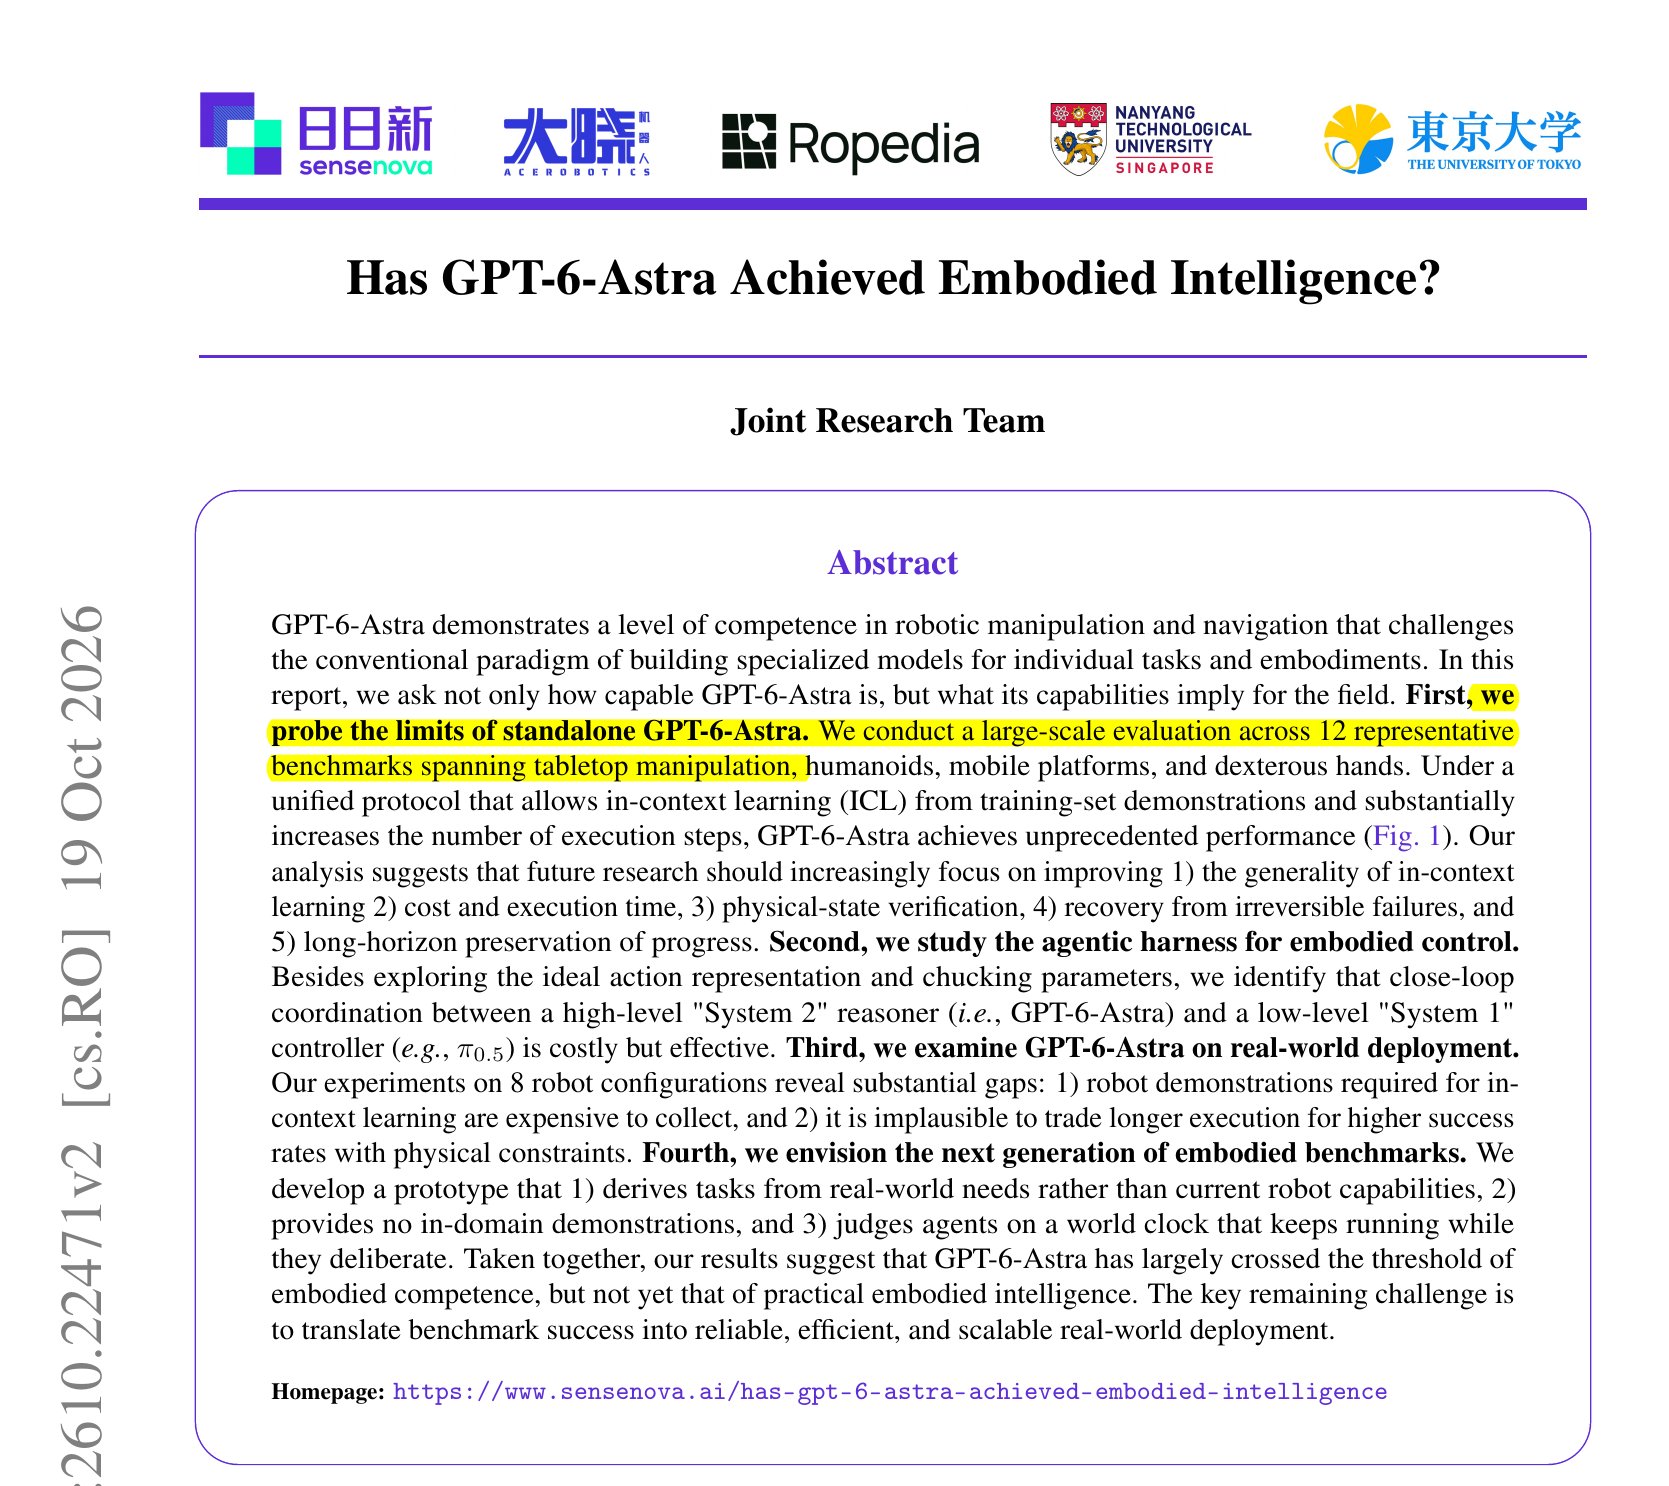
New paper finds that GPT-6-Astra nearly saturates easy robot benchmarks but still fails to verify physical success and recover from irreversible mistakes. And at a cost too high for real use. Robot manipulation and navigation have been dominated by task-specific models. The question was whether 1 general model could handle them all without weight updates. The authors tested GPT-6-Astra on 12 robot benchmarks. It studied training demos into a frozen knowledge package and got up to 10 times the usual action steps to recover. It neared saturation on the LIBERO suite and reached 81.9% on RoboDojo and 87.3% on DexJoCo. But a single LIBERO-Ultra-Long episode used about 9M tokens and nearly 2 hours, and on real robots it could not trade more steps for success. Treat general models as capable robot controllers for research, but expect task-specific demos, heavy compute, and physical limits to block deployment for now. – arxiv. org/abs/2610.22471 Title: "Has GPT-6-Astra Achieved Embodied Intelligence?"