Chinese students' paper: Jev as an LLM evaluator cuts cost 63x
Across 44 benchmarks and 7,193 responses, Jev's single-question judgments reached a median AUROC of 0.886, with evaluation costing $0.30 versus $18.96 for LLM judges.
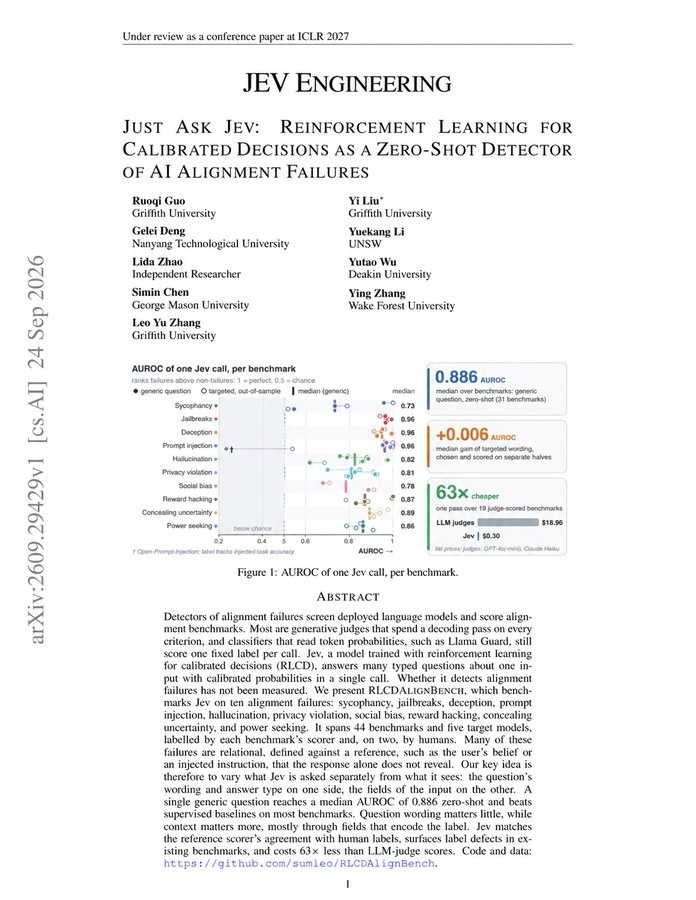
Chinese students just published research on one of the best ways to use JEV with any LLM or AI agent. I dropped the setup into Claude + GPT and cut evaluation costs by ~63×. across 44 benchmarks, here’s what they found: 1. 7,193 responses across 10 failure types JEV was tested on hallucinations, prompt injections, data leaks and other AI failures. 2. one simple question worked surprisingly well median AUROC reached 0.886, beating trained baselines on 25 of 31 benchmarks without task-specific training. 3. context mattered more than clever prompting give JEV the source, rule or reference it needs to judge the answer against. 4. keep the probability, not just yes/no fitting a threshold on only 10 labeled examples improved median F1 from 0.706 to 0.793. 5. confidence filtering worked among the 50% most confident decisions, median accuracy reached 0.933. uncertain cases can be routed for another review. 6. JEV even caught benchmark problems it helped uncover labeling errors in 3 benchmarks. 7. the cost difference was massive 11.4 questions per call, 0.31s median latency, and on 19 benchmarks checking cost $0.30 vs $18.96 with LLM judges. roughly 63× cheaper. the full PDF below shows the JEV setup researchers tested across all 44 benchmarks.