Astra vs Claude Fable 5.1: breaking down the real cost of a code review
On the same code review GPT-6 Astra came out 26.4% cheaper than Claude Fable 5.1, but 7,250 of its 9,832 output tokens were reasoning, and in another call over 90% of the cost came from cache reads and writes.
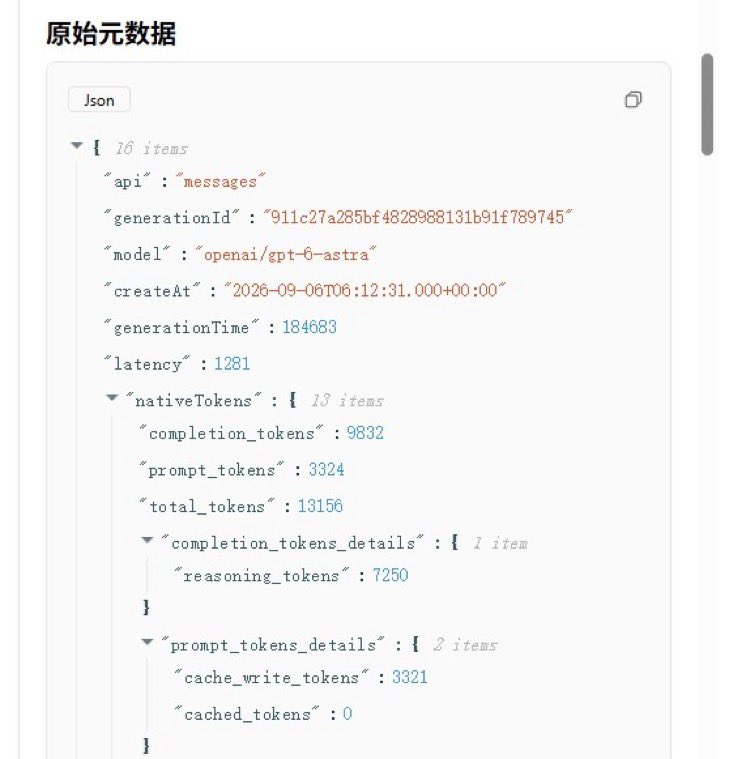
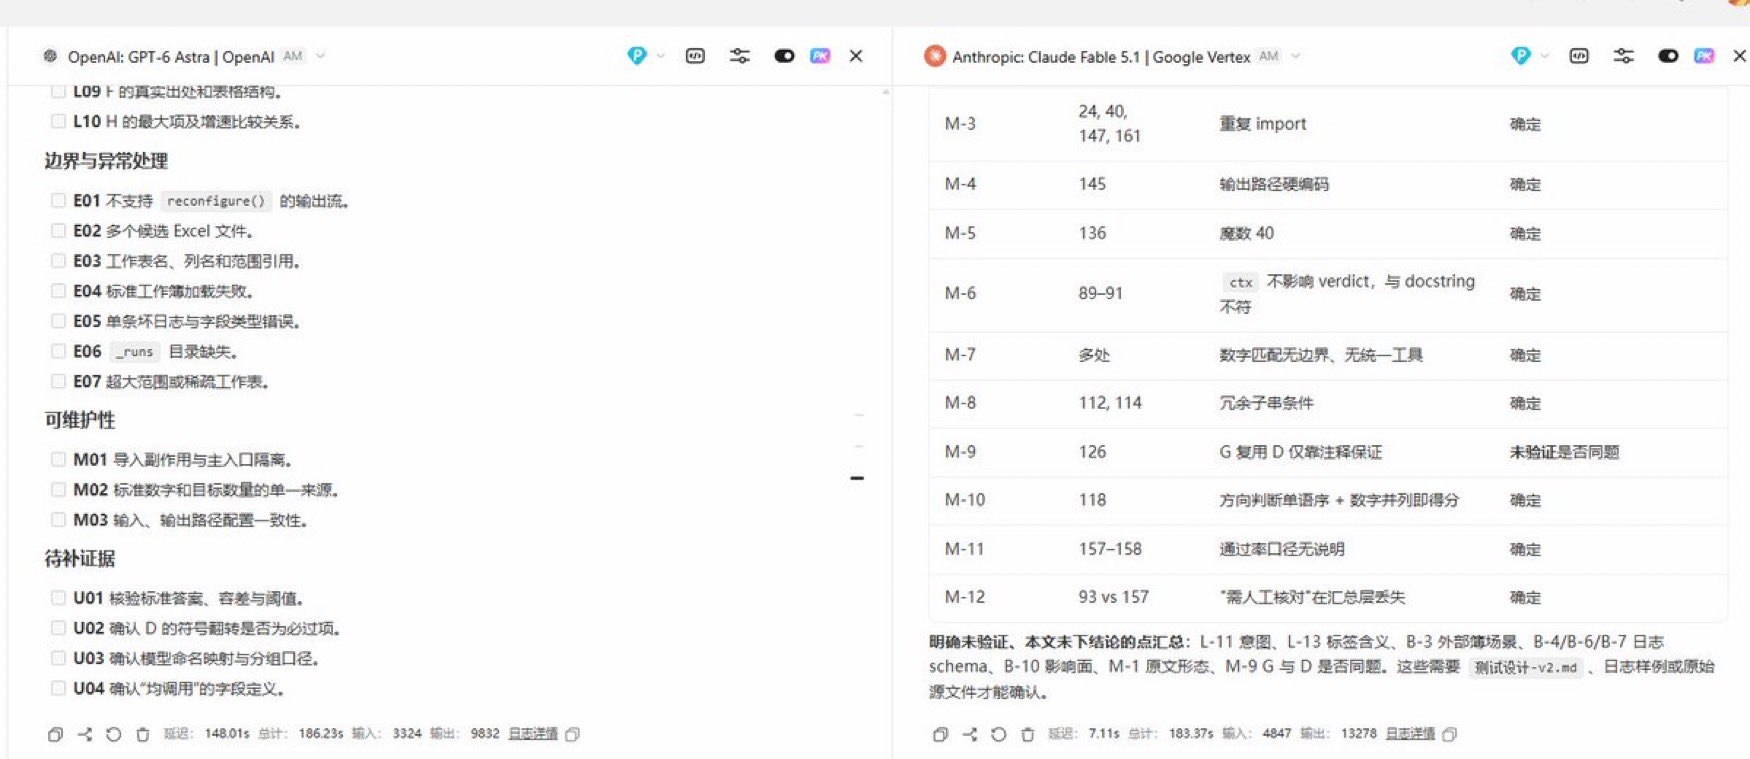
i thought the interesting part of this test was going to be which model was cheaper. turns out, the bill had more going on than that. GPT-6 Astra came out 26.4% cheaper than Claude Fable 5.1 on the same code review. but when the logs were opened up, Astra had 9,832 output tokens, and 7,250 of those were reasoning. so just looking at the total output count doesn’t really tell you much. then there was another call that made this even more interesting. a one-sentence question ended up costing $0.248, but only 8.3% of that was from the actual output. over 90% came from cache reads and writes. that’s the kind of thing you’d completely miss if you only looked at the final bill. using @zenmuxai made it easier to see all of this in one place because the call records break down the costs instead of giving you one number and calling it a day. imo, when you’re using AI agents heavily, the question isn’t just “which model is cheaper?” you also need to know what’s actually eating the budget.
This post quotes another post: x.com/zenmuxai/status/2096035457956286737