SGLang v0.5.22: DeepSeek V4.1 Flash gets up to 2.3x output throughput on Hopper
SGLang v0.5.22 ships 950 PRs, including up to 2.3x output token throughput for DeepSeek-V4.1-Flash on Hopper and up to 10x faster weight loading via InstantTensor.
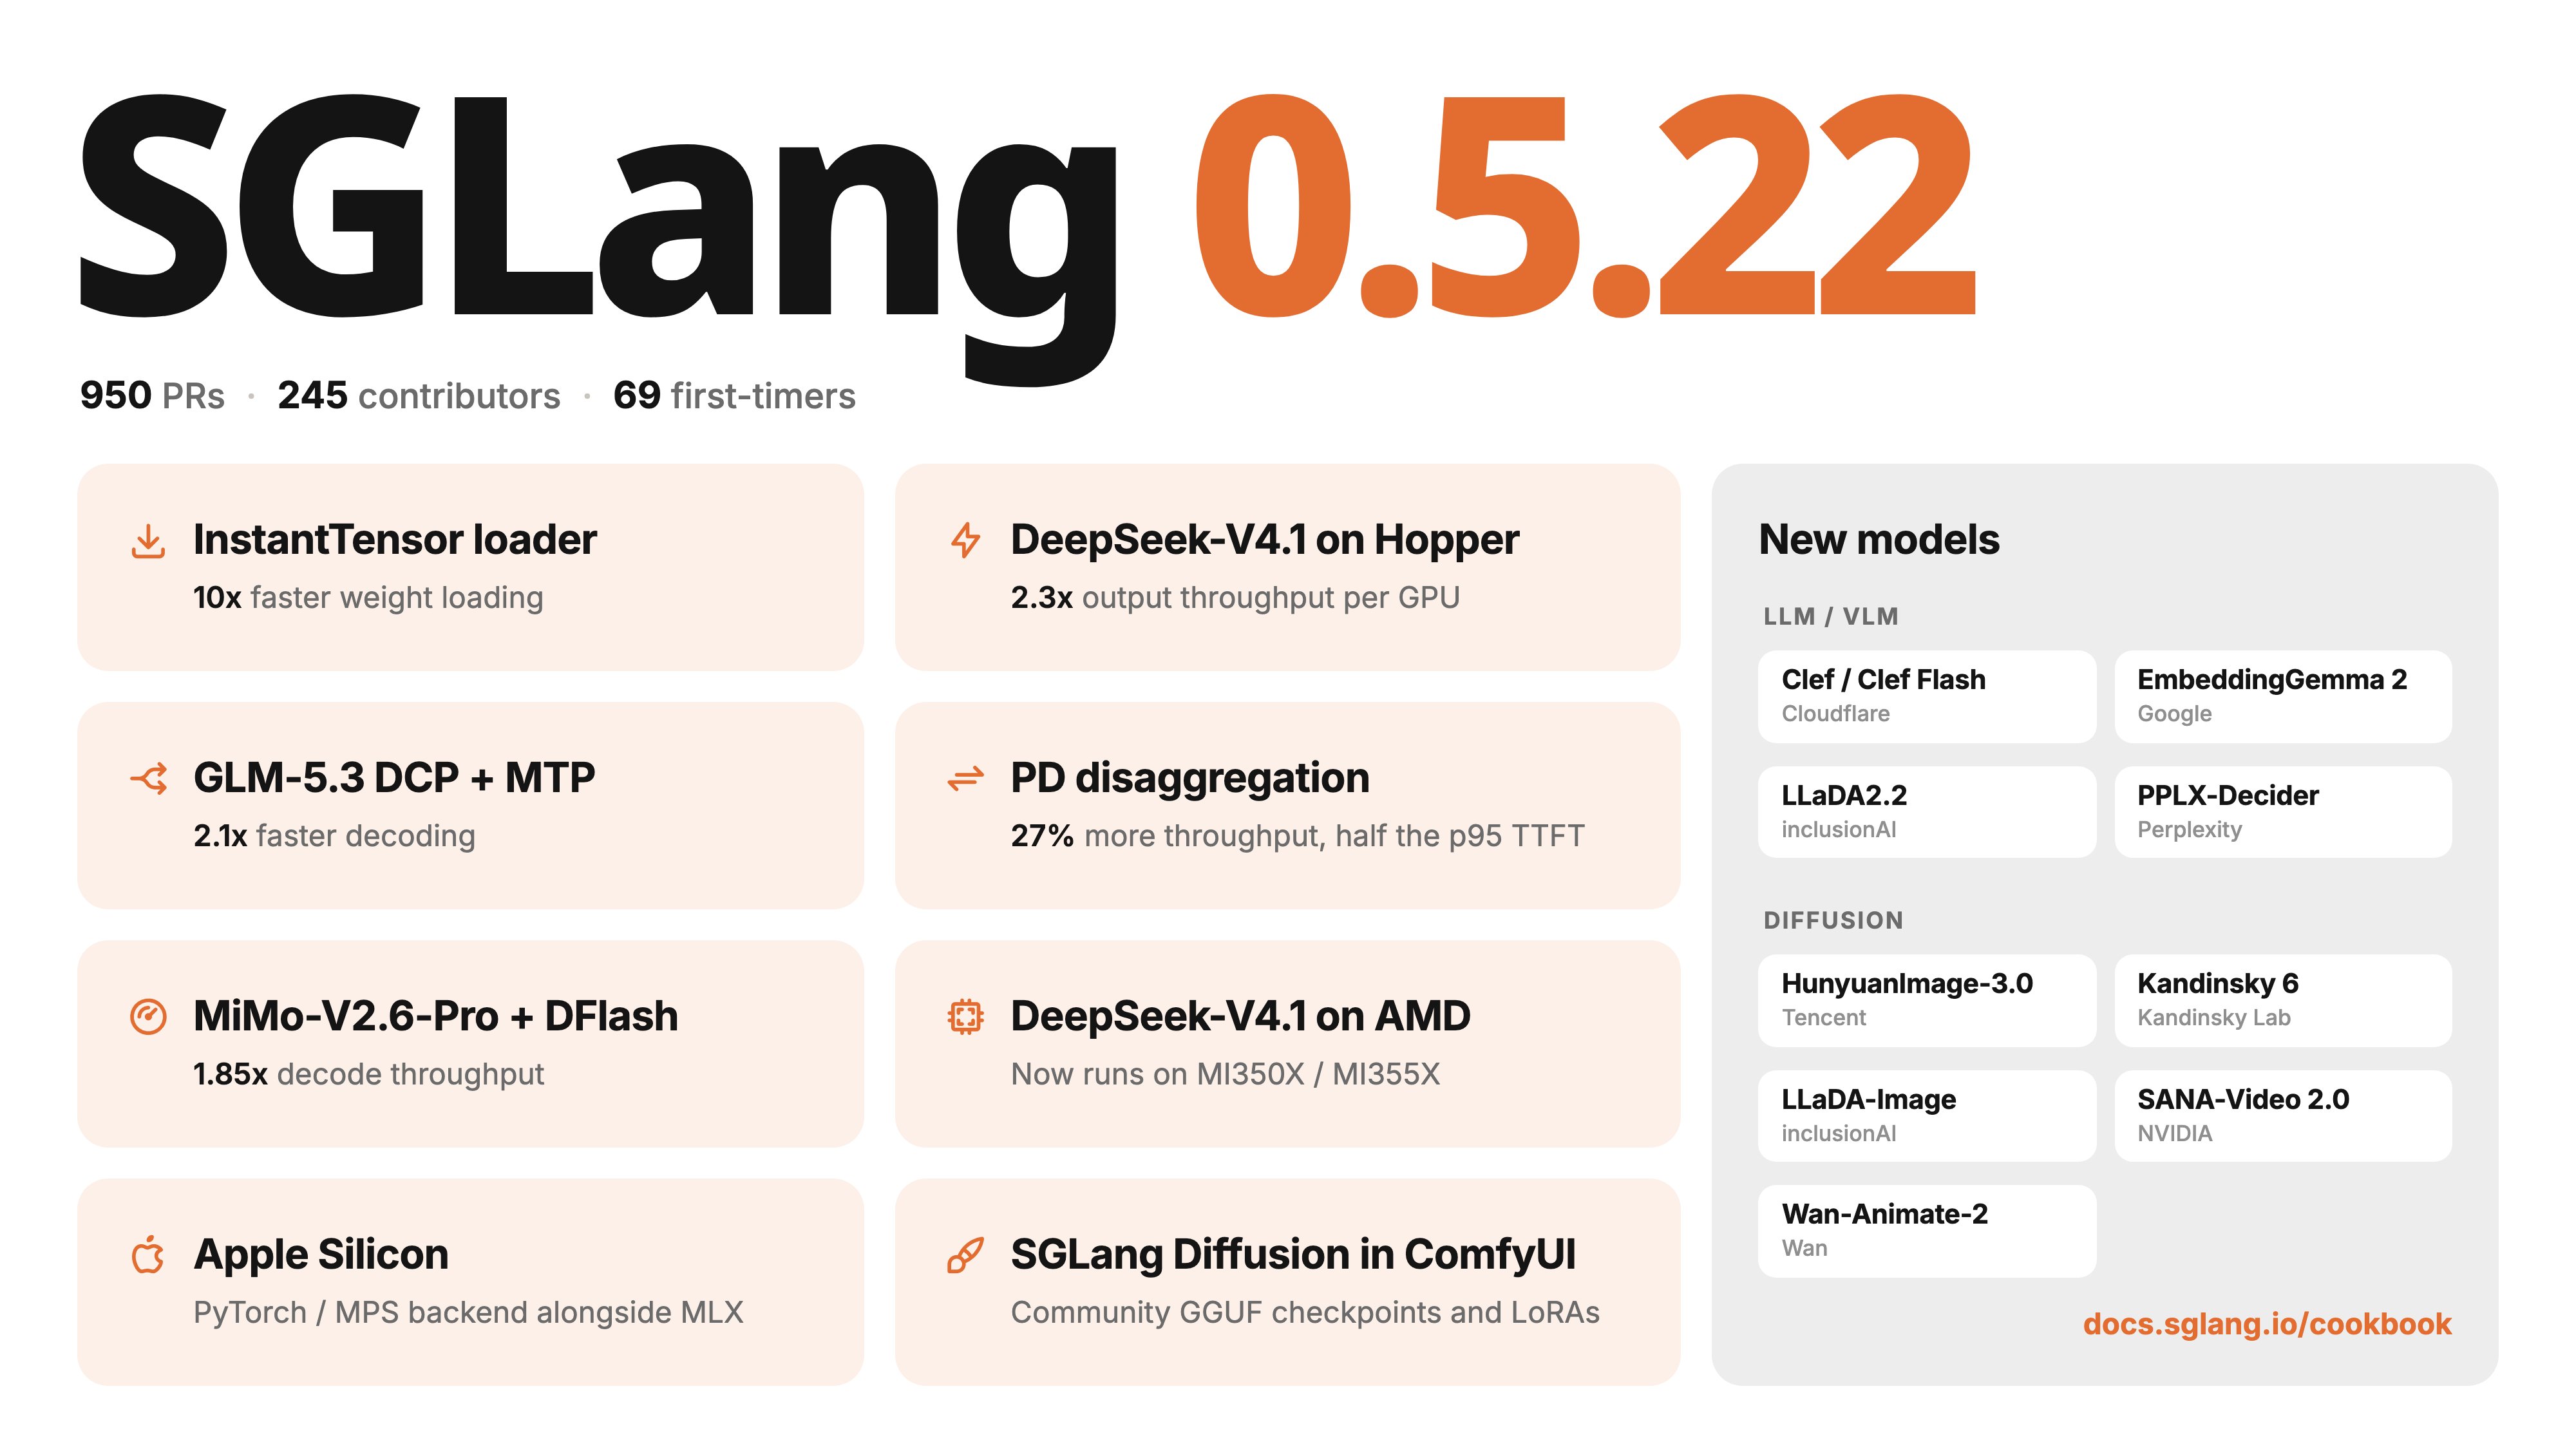
SGLang v0.5.22 is out! 950 PRs from 245 contributors, including 69 new contributors 🧡 Some of our favorite updates: - InstantTensor brings up to 10x faster weight loading - DeepSeek-V4.1-Flash gets up to 2.3x output token throughput on Hopper - Up to 2.1x faster decoding on GLM-5.3, with decode context parallelism with MTP - PD disaggregation gets up to 27% more throughput and half the p95 TTFT on agentic tasks - MiMo-V2.6-Pro gets 1.85x decode throughput with DFlash - Apple Silicon Macs can now use the standard PyTorch/MPS backend alongside MLX - SGLang Diffusion now supports community GGUF checkpoints and LoRAs on ComfyUI New models include Clef / Clef Flash, PPLX-Decider v1 / v1.1, EmbeddingGemma 2, LLaDA2.2, HunyuanImage-3.0-Instruct, Kandinsky 6, SANA-Video 2.0, and more. Full release notes: http://github.com/sgl-project/sglang/releases/tag/v0.5.22