DeepSeek V4.1 Flash vs GLM-5.3-Flash on 1M-token needle tests on one GB300
Across 125K–1M needle-in-a-haystack prompts on a single GB300, DeepSeek scored 4/6, 4/6, 5/6, 4/6 versus GLM's 6/6, 6/6, 6/6, 4/6; all misses were two-hop chains and 1M TTFT was ~49–51 s.
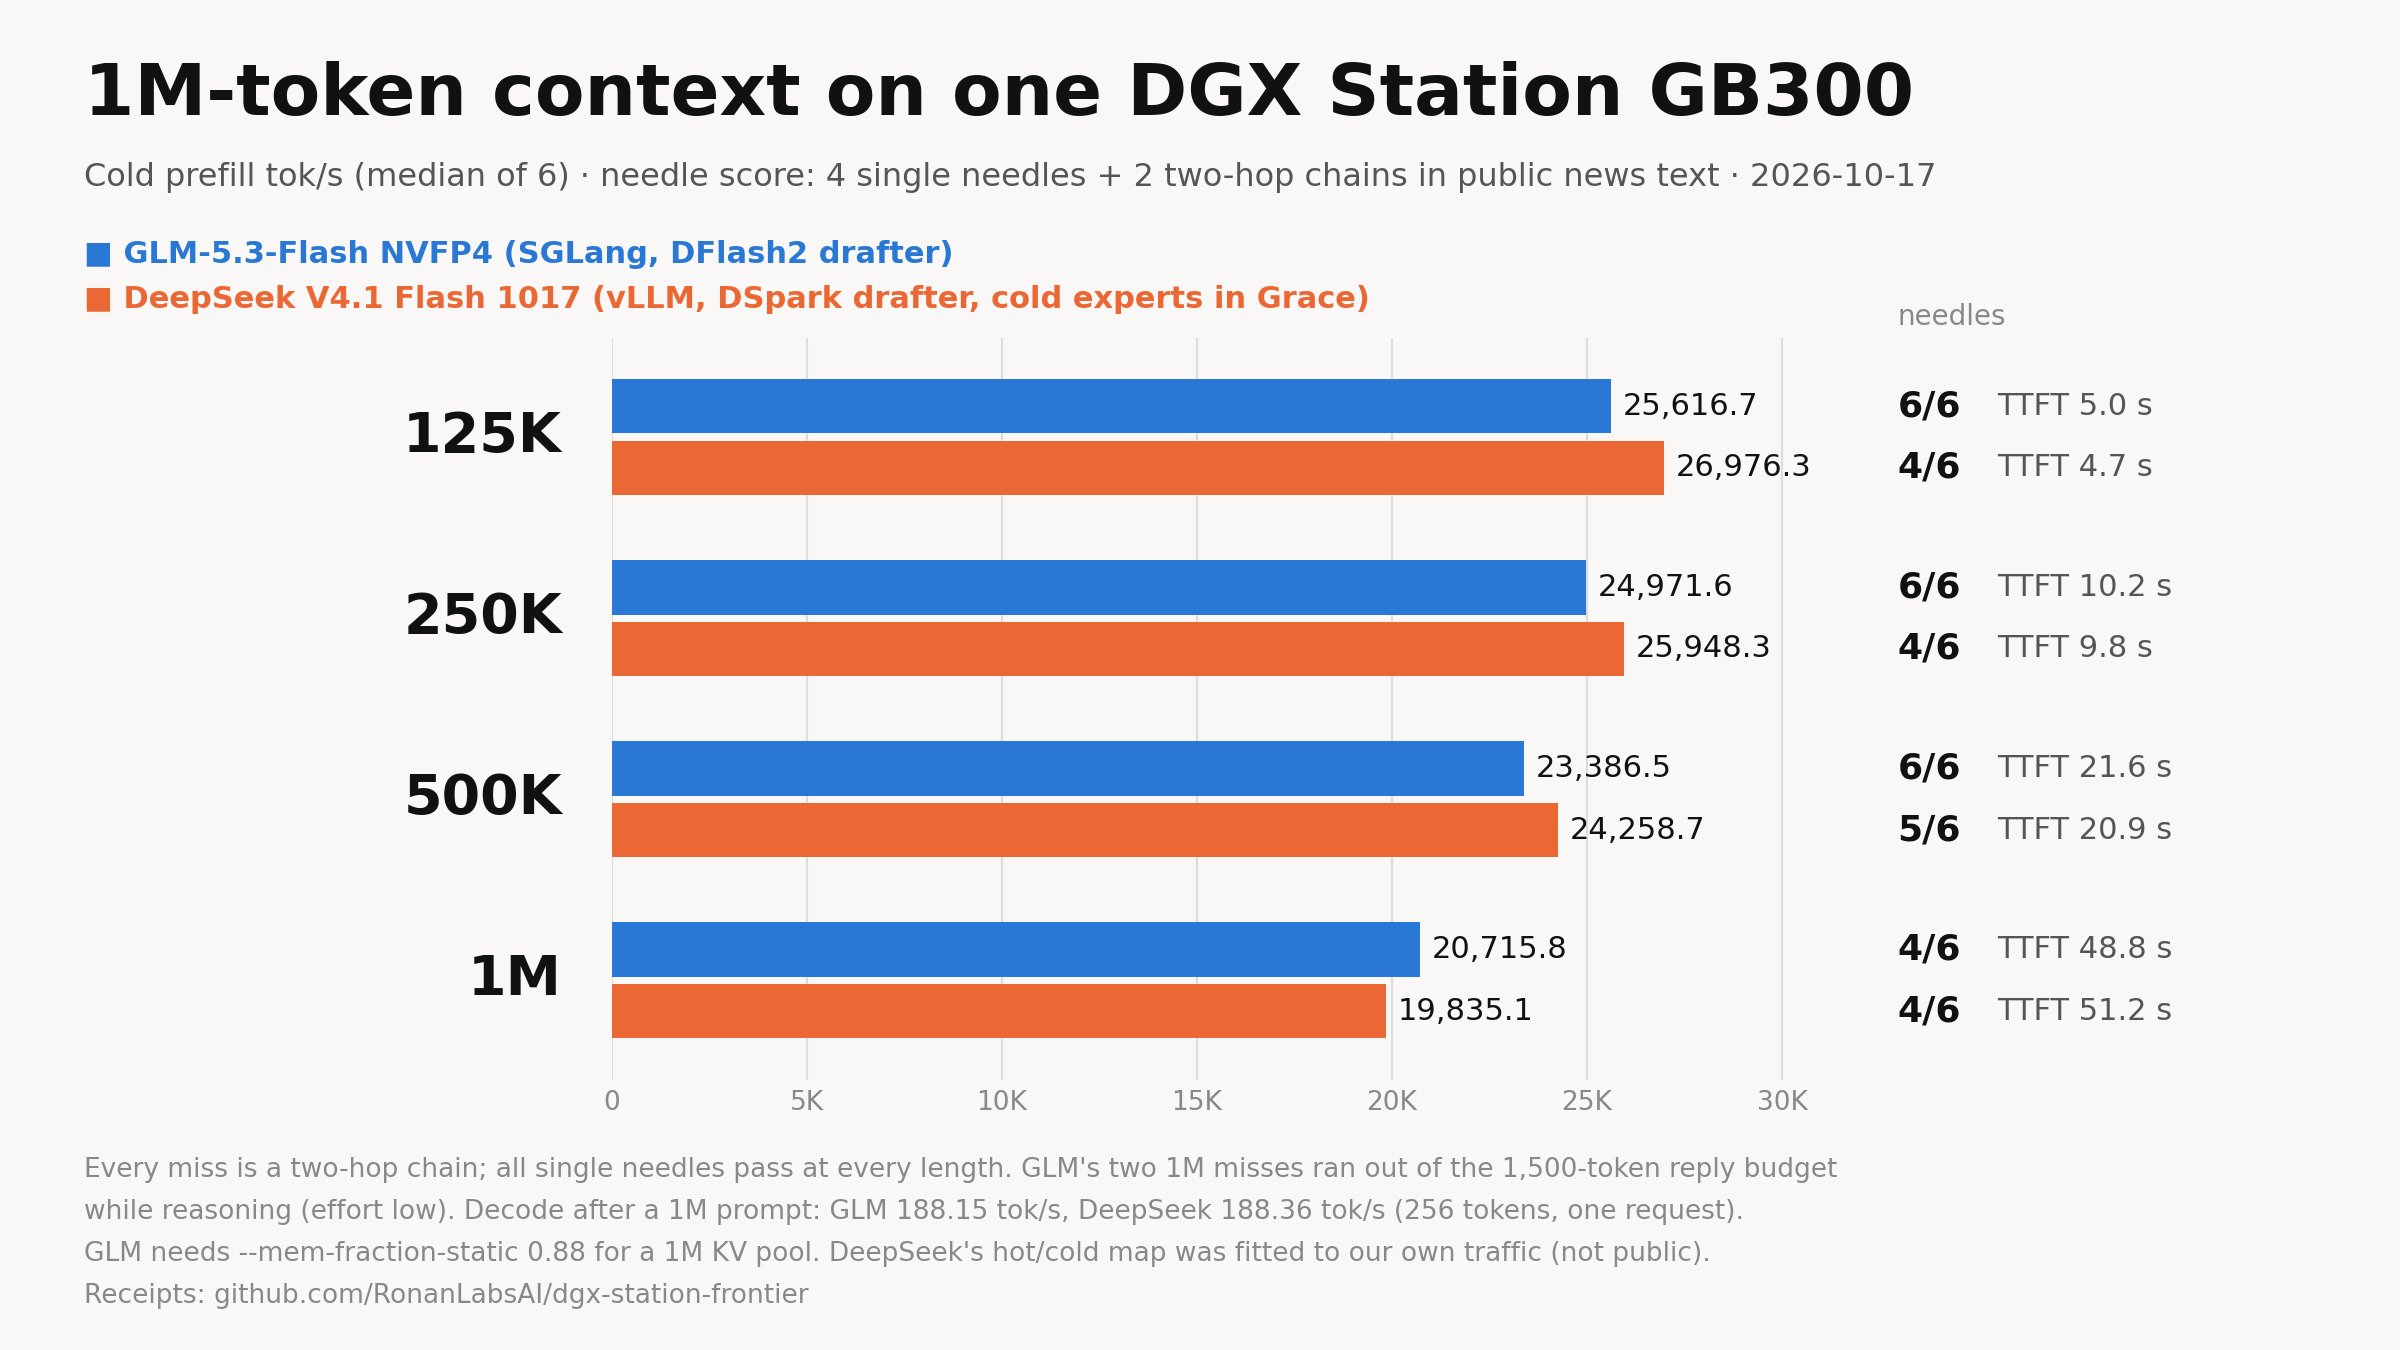
1M-token context on one DGX Station GB300: two models, measured. We gave GLM-5.3-Flash and DeepSeek V4.1 Flash 1017 needle-in-a-haystack prompts of 125K, 250K, 500K and 1M tokens, each on a single GB300. Every prompt was read cold (0% prefix-cache hits). Needles found (out of 6): GLM-5.3-Flash NVFP4: 6/6 at 125K, 6/6 at 250K, 6/6 at 500K, 4/6 at 1M DeepSeek V4.1 Flash 1017: 4/6, 4/6, 5/6, 4/6 Time to first token: GLM: 5.0 s, 10.2 s, 21.6 s, 48.8 s DeepSeek: 4.7 s, 9.8 s, 20.9 s, 51.2 s Prefill speed stays above 19.8K tok/s even at 1M (GLM 25.6K to 20.7K, DeepSeek 27.0K to 19.8K). Decoding after a 1M-token prompt: 188 tok/s on both. The test: each length has 6 items hidden in public news text. 4 are single needles at different depths, and 2 are two-hop chains: find which vault an agent uses, then find that vault's code. What the misses tell you: - Every miss on both models is a two-hop chain. Single needles never missed at any length. - GLM's two misses at 1M weren't wrong answers. Both spent the whole 1,500-token reply budget reasoning and never answered. A bigger budget might pass; we haven't tested that. - DeepSeek's older checkpoint misses the same items, so this isn't a regression in 1017. Setup: - GLM on SGLang with the DFlash2 drafter, all in GB300 memory. It needs --mem-fraction-static 0.88 to fit a 1M-token KV cache (1,147,584 tokens). - DeepSeek on vLLM with the DSpark drafter and cold experts in Grace memory. Caveat: 6 items per length is a small sample. Treat this as a capability check, not a benchmark. Full method, scripts and logs: http://github.com/RonanLabsAI/dgx-station-frontier/blob/main/results/long-context-1m.md @Zai_org, @deepseek_ai