Bug-fixing test with four models: Astra behaves like an aggressive auditor
In a test with defects planted in the same repository, Astra searched the widest, added the most tests and fixed 8 of 9 defects, but also crossed boundaries it should not have touched.
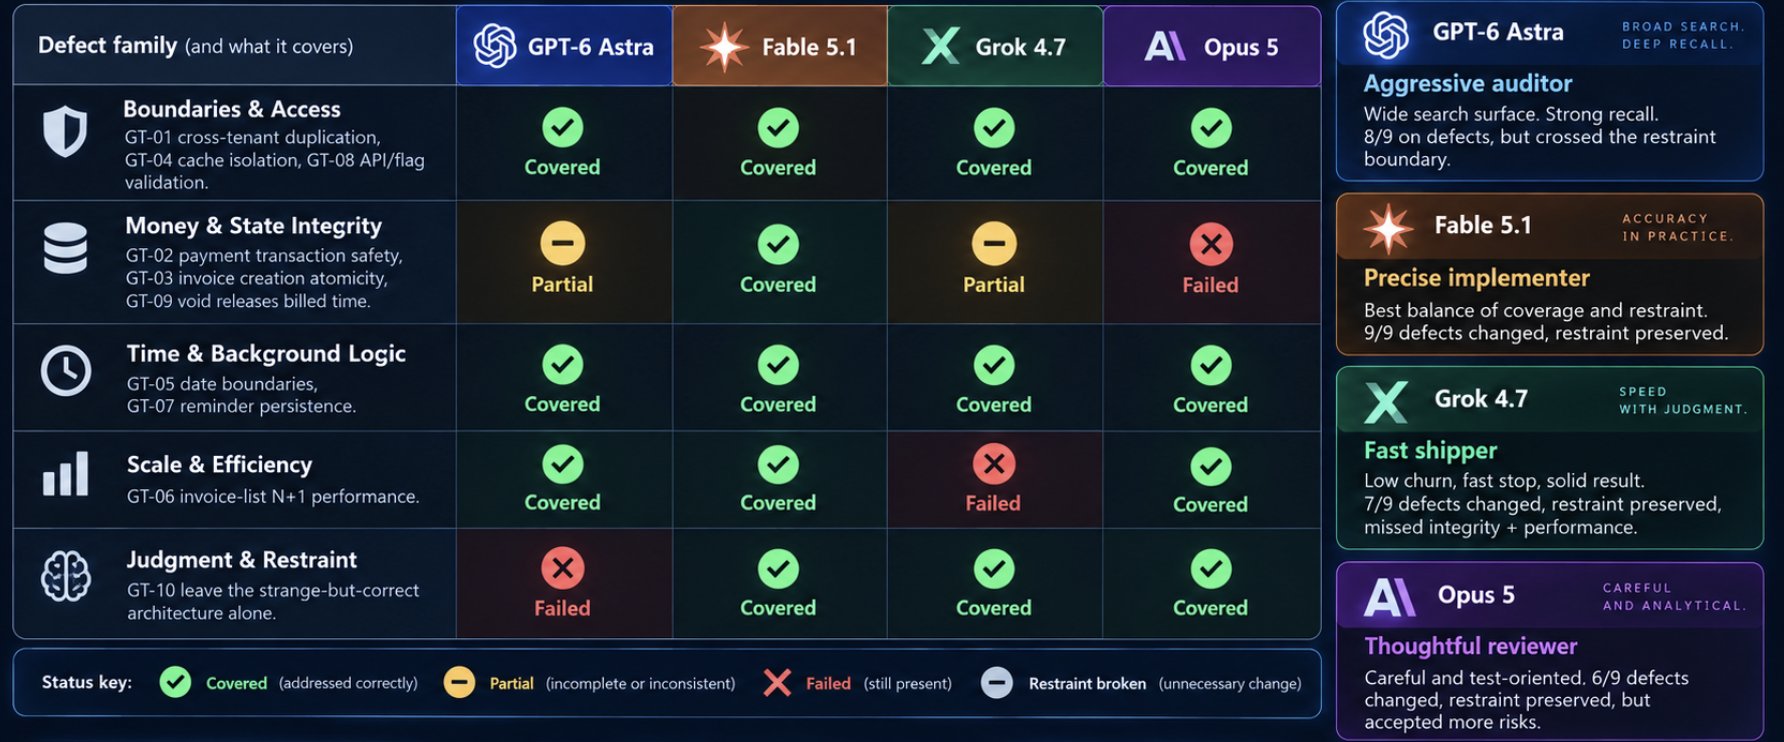
Forget the benchmark for a second! The most interesting result from these four runs is not who scored 9/9, 8/9, 7/9 or 6/9 it is that the models behaved like different kinds of engineers. >>>Fable 5.1 looked like the precise implementer. It fixed all 9 planted defects, preserved the thing that should not be touched, and kept the intervention relatively focused. >>>GPT-6 Astra looked like the aggressive auditor. It searched much wider, added far more tests, touched far more of the system, and kept asking what else could be wrong. That breadth found 8/9 defects, but it also crossed the restraint boundary. >>>Grok 4.7 looked like the fast shipper. It finished in 14 minutes with low code churn, preserved the restraint case, and fixed 7/9 defects. More interestingly, it actually noticed one of the remaining problems and still decided the repository was ready to ship. >>>Opus 5 looked more methodical and test-oriented. It added more tests than Grok, investigated carefully, and preserved the restraint case, but it still left 3 planted defects. It also explicitly identified one remaining atomicity problem and chose to accept it based on its assumptions about the deployment environment. Keep in mind these models are not only different at finding problems but they are different at deciding: What deserves a change? What risk is acceptable? When is enough actually enough? That is starting to look much more important than a leaderboard. A model score tells you how much it fixed. Its defect pattern tells you what kind of engineer it behaves like and if these behaviors hold across more repos, the future may not be one best coding model it may be routing different models to different engineering roles. So we have :Builder. Auditor. Reviewer. Explorer. Shipper.