Model routing with Jev: three tiers by task difficulty
The author uses Jev as a dispatcher to split queries into fast, standard and reasoning tiers, routing them to small, mid-size and strong models to cut latency and cost.
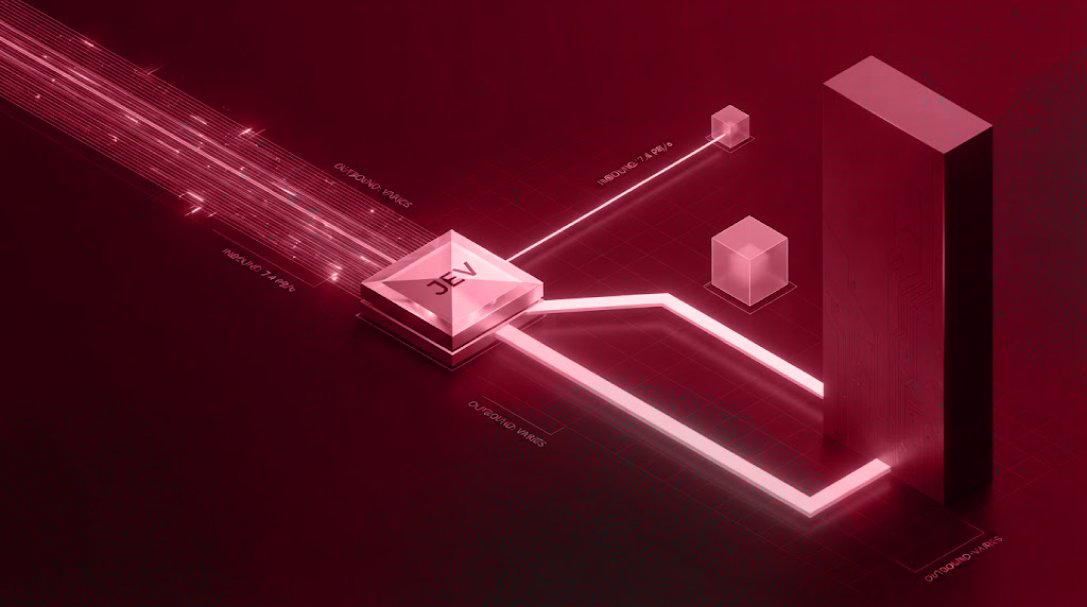
every task on your stack runs through the same model typo fixes and deep synthesis get the same compute bill that is the waste nobody notices until the bill does i am implementing a model router using jev as the dispatcher three buckets: - fast track: typos, json formatting, basic extraction → llama 3 8b or phi-3 - standard track: short posts, summarization, simple contradictions → mistral or mid-size models - reasoning track: deep synthesis, strategic planning, complex code → gemma 4 31b or claude 3.5 jev reads the query picks the bucket routes it latency drops load drops the real test is not the router it is whether output quality holds once the cheap models take the easy half
This post quotes another post: x.com/0xricker/status/2102396090012115030