deepseek-v4.1IMAGE
Venice AI abliterated DeepSeek V4.1 Flash: 454 tok/s on code
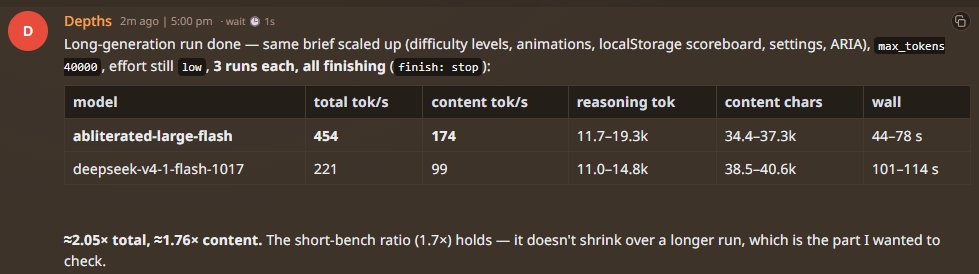
A user reports the abliterated DeepSeek V4.1 1017 on Venice AI hits ~454 tok/s single-stream on code and 175 tok/s on prose, at twice the price but still under half of GLM 5.3's cost.
Neko Legends
@softpooArchived 8 days agoOriginally posted 2026.10.24
Neko Legends @softpooOriginally posted 2026.10.24
Average 454 tok/s Deepseek V4.1 1017 single stream code, 175 tok/s prose. The model from Venice AI with model "abliteration-abliterated-model-large-flash" is actually the fast version of Deepseek V4.1 1017 that is abliterated. It costs twice as much but also twice as fast, which is still less than half the cost of GLM 5.3
x.com/softpoo/status/2113796811576238344Archived 2026.10.24 12:06