RoboQuest robot benchmark: Gemini 4 Argon and GPT-6 Astra tie for first
On the new RoboQuest robot agent benchmark, Gemini 4 Argon scores 23.8% success at $11.22 per episode, roughly level with GPT-6 Astra and well above Opus 5.5's 13.8%.
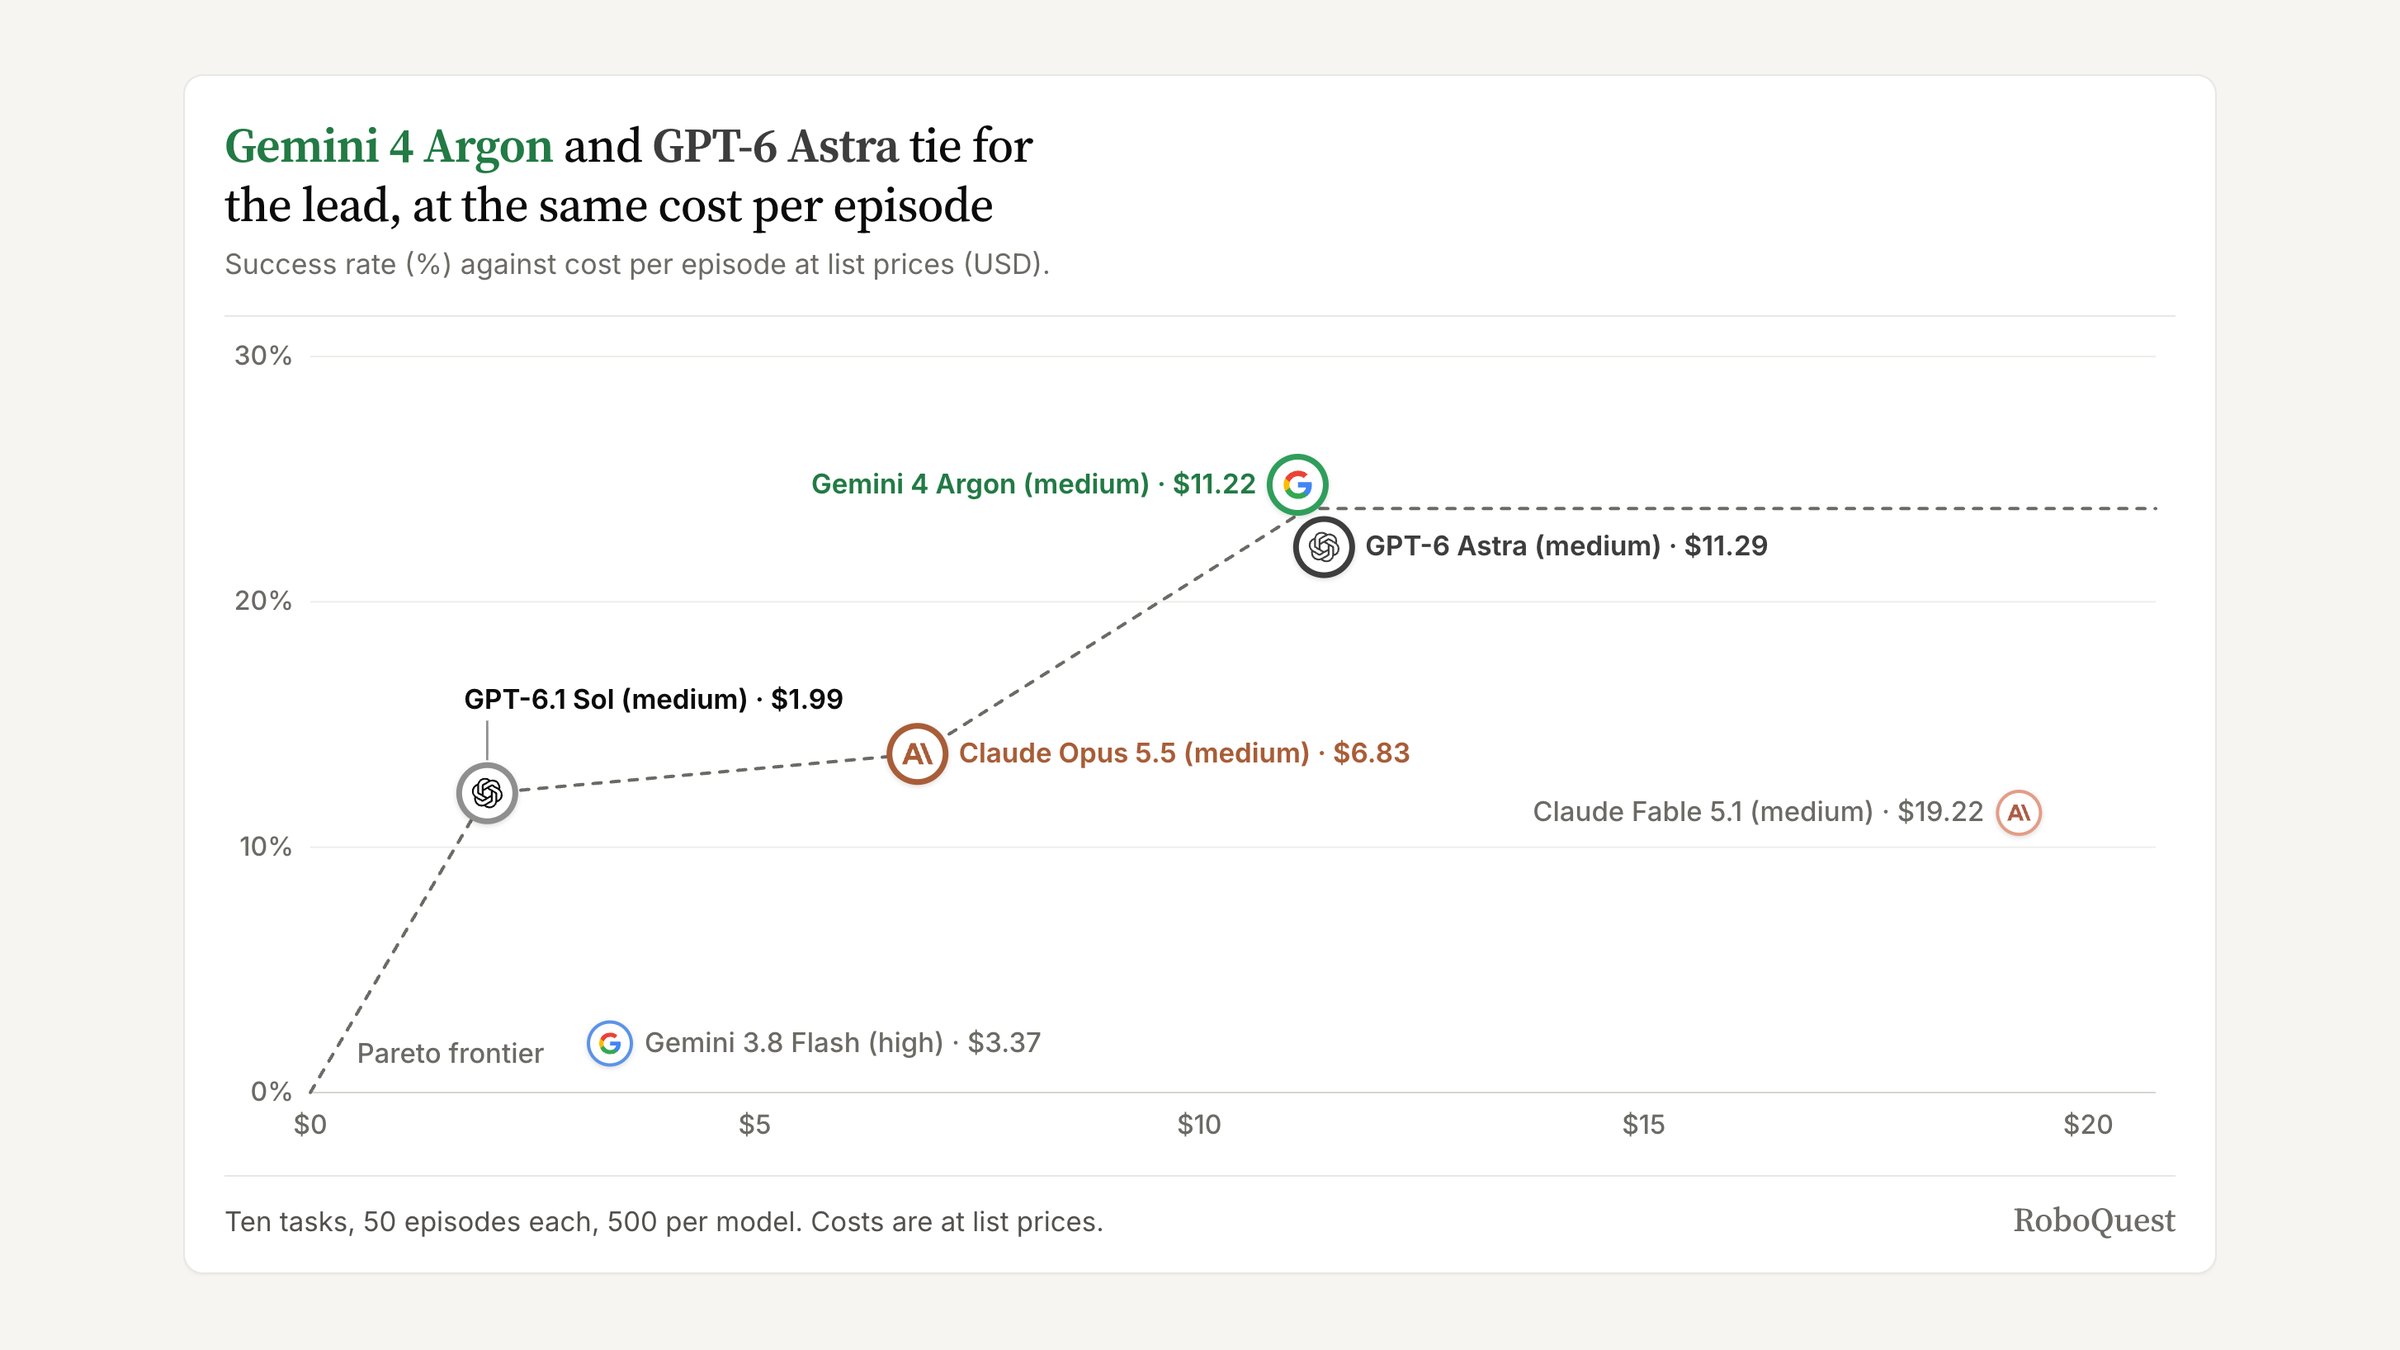
🤖 We're releasing RoboQuest, a long-horizon agentic benchmark for robots. 🏆 Gemini 4 Argon and GPT-6 Astra tie for the lead, with 23.8% and 23.2% success. They also cost about the same: $11.22 and $11.29 per episode. 🔍 We wanted to see how frontier AI agents hold up on physical tasks that require gathering evidence. In every RoboQuest task, the information needed to succeed is hidden at the start: where an object is, what is under a mug, or which bolt blocks which. The robot must search, inspect or test to find it. So success depends on control, and also on planning and interpreting what the robot sees. 🦾 How the model controls the robot: the robot is a Franka arm on a mobile base, simulated in MuJoCo with RoboCasa365 scenes. Each turn, the model sees 3 camera images and the robot's state. It replies with one tool call: move the gripper, drive the base, wait, or stop. The simulator runs the command and sends back new images, for up to 200 turns. There are no grasp or find-object helpers. To finish, the robot must press a red SUBMIT button in the scene. 📊 Success rate and cost per episode at list prices, 500 episodes per model, no fine-tuning: ▪️ Gemini 4 Argon: 23.8%, $11.22 ▪️ GPT-6 Astra: 23.2%, $11.29 ▪️ Claude Opus 5.5: 13.8%, $6.83 ▪️ GPT-6.1 Sol: 12.2%, $1.99 ▪️ Claude Fable 5.1: 11.4%, $19.22 ▪️ Gemini 3.8 Flash: 2.0%, $3.37 A π0.5 fine-tuned on our demos almost never succeeds. 🧠 The bottleneck is exploring and deciding, not motor control. Given the hidden information up front, GPT-6 Astra, Claude Opus 5.5 and GPT-6.1 Sol complete the individual skills in 72–81% of tries. Only 18–21% of their failures are execution errors. Most of their failures (66–74%) come from evidence the model never collected or did not use correctly. Often, a needed object sat in a drawer or box the model saw 5+ times but never opened. We also notice that models falsely believed they completed a task and pressed the submit button. 📄 Paper: https://arxiv.org/abs/2610.10388 🌐 Project: https://declare-lab.github.io/RoboQuest/ 💻 Code: https://github.com/declare-lab/RoboQuest 🗂️ Data: https://huggingface.co/datasets/declare-lab/RoboQuest
This post quotes another post: x.com/theturingpost/status/2109809600568655904