EAGLE-4: open-source speculative decoding stack
EAGLE-4 pairs EAGLE-Harness with an Efficient LM Head to hit 961.6 tokens/s per request and 4x vanilla decoding speed, with the implementation open-sourced on GitHub.
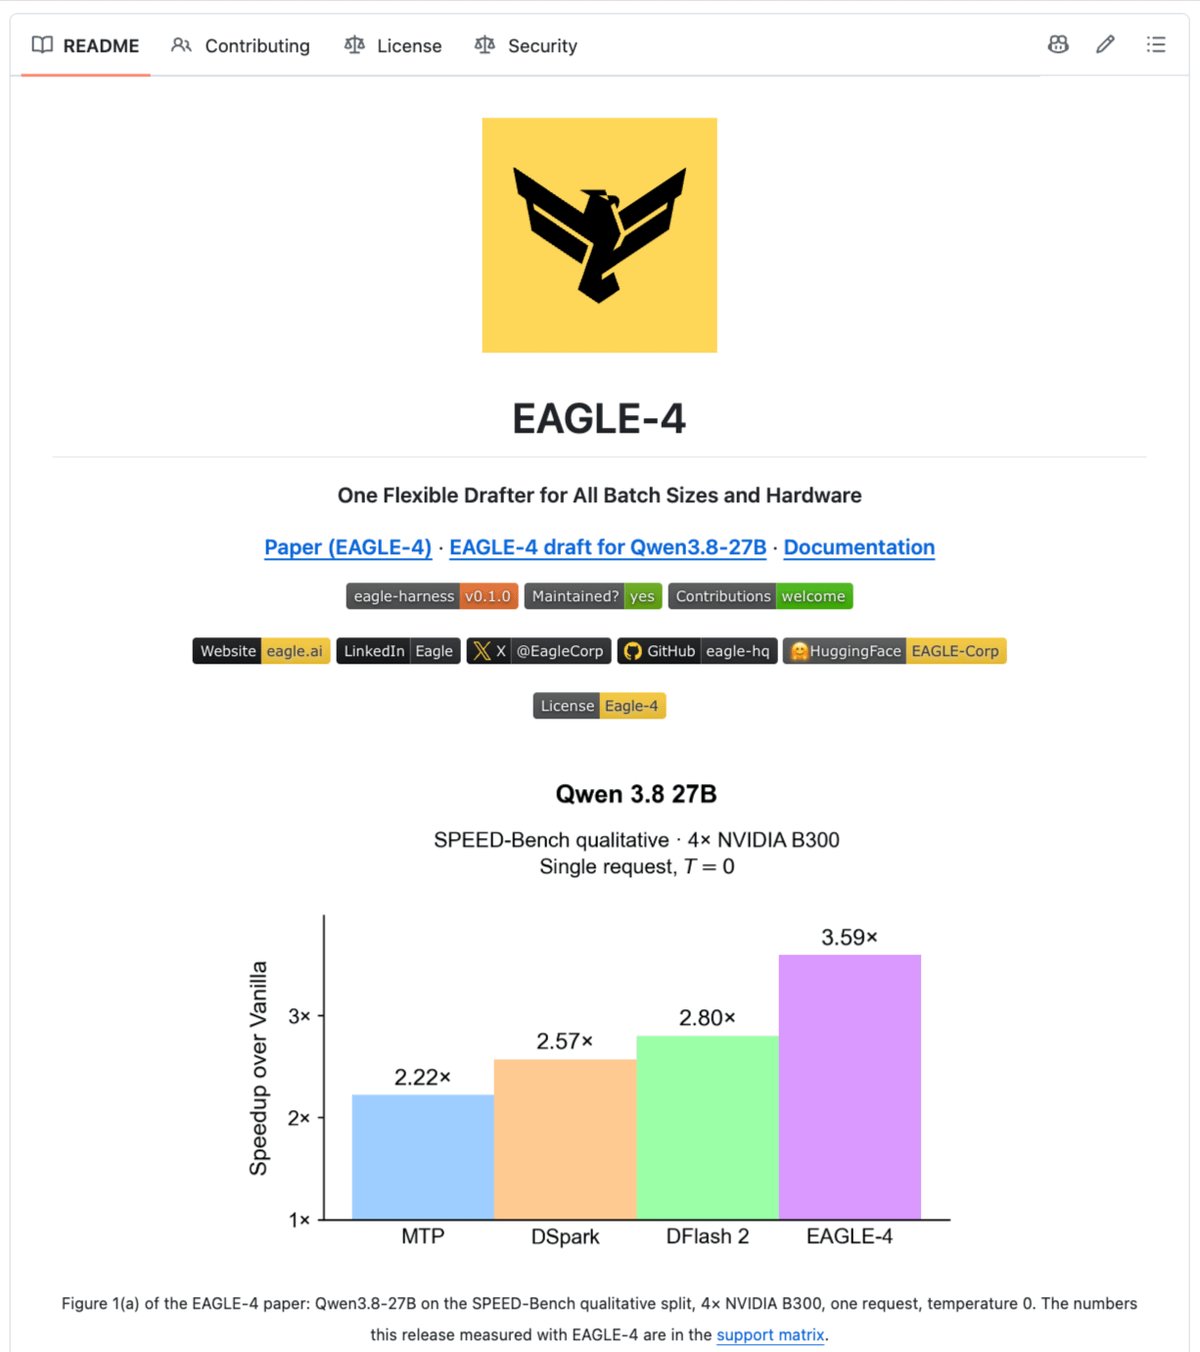
Faster inference isn't just about generating tokens faster. The architecture driving that acceleration matters just as much. EAGLE-4 combines EAGLE-Harness, which adapts draft structures to hardware and workload conditions, with an Efficient LM Head that cuts draft-model overhead by over 40%. The results are impressive: 961.6 tokens/s for a single request and 4× the speed of vanilla decoding. The launch paper also reports strong throughput performance against DFlash 2 and DSpark. Explore the implementation: https://github.com/eagle-hq/EAGLE-4
This post quotes another post: x.com/eaglecorp/status/2112660683670323531