Ternary-Bonsai 27B local model ships GGUF quantized bundles
A quantized package of a 27B local model for 8GB-and-up GPUs, with serve scripts per VRAM tier, about 50 tok/s on an RTX 3060, 262k context and agent tasks.
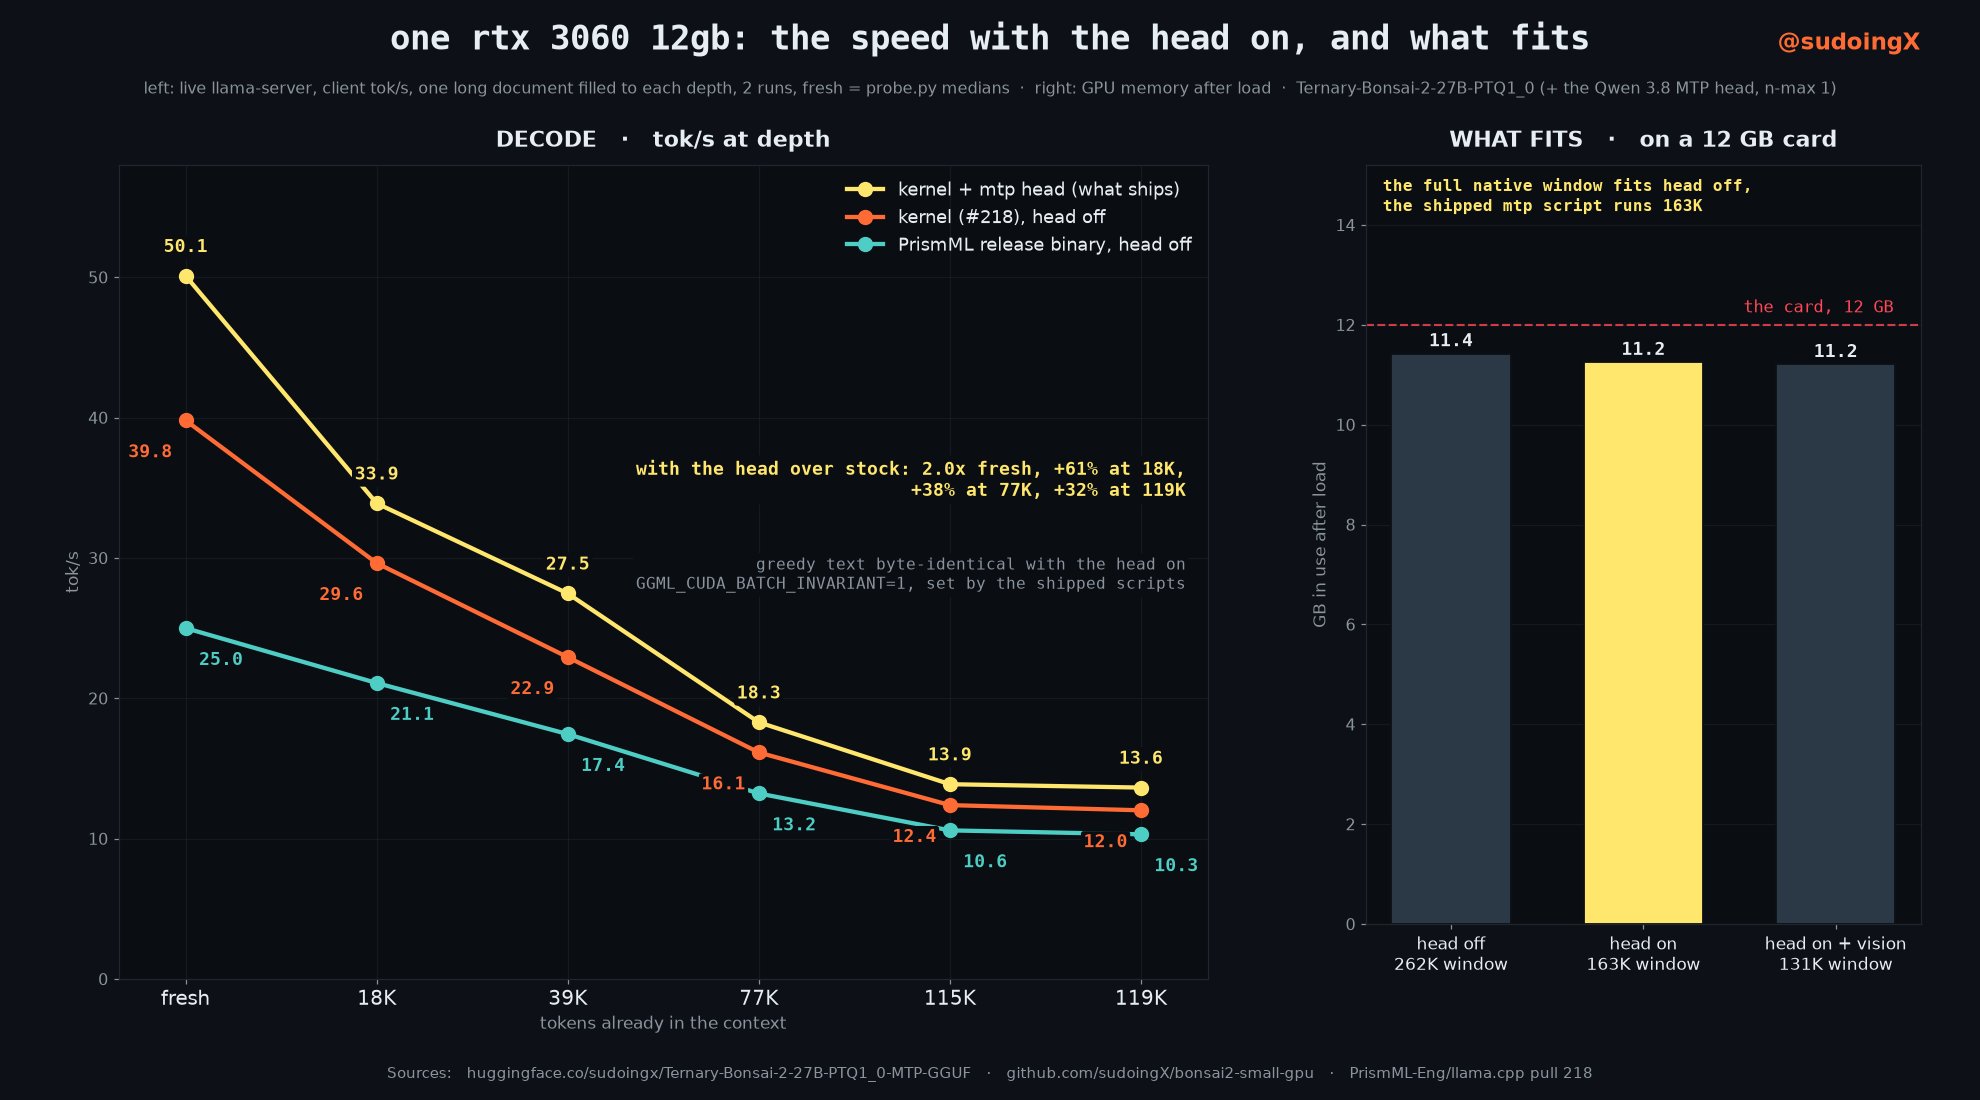
don't sleep on this model gamers, you already have the vram it needs, and you can taste the freedom of local ai on the card sitting in your pc right now. it runs a 27b model at 50 tok/s fresh on gpus like rtx 3060, way faster than you can read, with no account and nothing leaving your machine. and it doesn't just chat, it does agent work, you hand it a task and it opens files, writes the code, runs it, checks it and keeps going while you're away from the desk. this chart is the part people ask about most, context. with the mtp head on it starts at 50 tok/s and still does 18.3 tok/s with 77k tokens already in the window, faster than you read. the full 262k window fits on a 12gb card with the head off, and the shipped mtp script runs 163k, that's a whole codebase in one prompt. it slows as the window fills, and i'd rather show you the whole curve than crop it. the card you bought for games sits idle most of the day, give it a job. i packaged all of it for you, the model, a serve script for every vram tier and a prebuilt bundle, so you extract it and run. it got 10,756 downloads in 4 days already. 3060, 3070, 4060, anything with 8gb and up, pull it and tell me what your card does: http://huggingface.co/sudoingx/Ternary-Bonsai-2-27B-PTQ1_0-MTP-GGUF
This post quotes another post: x.com/sudoingx/status/2102021327729397963